Introducing Microsoft SQL Server 2008 R2


Contents at a Glance


Introduction xvii


PART I DATABASE ADMINISTRATION


CHAPTER 1 SQL Server 2008 R2 Editions and Enhancements 3


CHAPTER 2 Multi-Server Administration 21


CHAPTER 3 Data-Tier Applications 41


CHAPTER 4 High Availability and Virtualization Enhancements 63


CHAPTER 5 Consolidation and Monitoring 85


PART II BUSINESS INTELLIGENCE DEVELOPMENT


CHAPTER 6 Scalable Data Warehousing 109


CHAPTER 7 Master Data Services 125


CHAPTER 8 Complex Event Processing with StreamInsight 145


CHAPTER 9 Reporting Services Enhancements 165


CHAPTER 10 Self-Service Analysis with PowerPivot 189


What do you think of this book? We want to hear from you!


Microsoft is interested in hearing your feedback so we can continually improve our

books and learning resources for you. To participate in a brief online survey, please visit:


microsoft.com/learning/booksurvey


vii


Contents


Introduction xvii


PART I DATABASE ADMINISTRATION


CHAPTER 1 SQL Server 2008 R2 Editions and Enhancements 3


SQL Server 2008 R2 Enhancements for DBAs. 3


Application and Multi-Server Administration Enhancements 4


Additional SQL Server 2008 R2 Enhancements for DBAs 8


Advantages of Using Windows Server 2008 R2 . 10


SQL Server 2008 R2 Editions. 11


Premium Editions 12


Core Editions 12


Specialized Editions 13


Hardware and Software Requirements. 14


Installation, Upgrade, and Migration Strategies. 16


The In-Place Upgrade 16


Side-by-Side Migration 18


CHAPTER 2 Multi-Server Administration 21


The SQL Server Utility. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 21


SQL Server Utility Key Concepts 23


UCP Prerequisites 25


UCP Sizing and Maximum Capacity Specifications 25


viii Contents


Creating a UCP . 26


Creating a UCP by Using SSMS 26


Creating a UCP by Using Windows PowerShell 28


UCP Post-Installation Steps 29


Enrolling SQL Server Instances. 29


Managed Instance Enrollment Prerequisites 30


Enrolling SQL Server Instances by Using SSMS 30


Enrolling SQL Server Instances by Using Windows PowerShell 32


The Managed Instances Dashboard 32


Managing Utility Administration Settings . 33


Connecting to a UCP 33


The Policy Tab 34


The Security Tab 37


The Data Warehouse Tab 39


CHAPTER 3 Data-Tier Applications 41


Introduction to Data-Tier Applications. 41


The Data-Tier Application Life Cycle 42


Common Uses for Data-Tier Applications 43


Supported SQL Server Objects 44


Visual Studio 2010 and Data-Tier Application Projects. 45


Launching a Data-Tier Application

Project Template in Visual Studio 2010 45


Importing an Existing Data-Tier

Application Project into Visual Studio 2010 47


Extracting a Data-Tier Application with

SQL Server Management Studio. 49


Installing a New DAC Instance with the

Deploy Data-Tier Application Wizard. 52


Registering a Data-Tier Application. 55


Deleting a Data-Tier Application. 56


Upgrading a Data-Tier Application. 59


Contents ix


CHAPTER 4 High Availability and Virtualization Enhancements 63


Enhancements to High Availability with Windows Server 2008 R2. 63


Failover Clustering with Windows Server 2008 R2. 64


Traditional Failover Clustering 65


Guest Failover Clustering 67


Enhancements to the Validate A Configuration Wizard 68


The Windows Server 2008 R2 Best Practices Analyzer 71


SQL Server 2008 R2 Virtualization and Hyper-V. 72


Live Migration Support Through CSV 72


Windows Server 2008 R2 Hyper-V System Requirements 73


Practical Uses for Hyper-V and SQL Server 2008 R2 74


Implementing Live Migration for SQL Server 2008 R2. 75


Enabling CSV 76


Creating a SQL Server VM with Hyper-V 76


Configuring a SQL Server VM for Live Migration 79


Initiating a Live Migration of a SQL Server VM 83


CHAPTER 5 Consolidation and Monitoring 85


SQL Server Consolidation Strategies. 85


Consolidating Databases and Instances 86


Consolidating SQL Server Through Virtualization 87


Using the SQL Server Utility for Consolidation and Monitoring . 89


Using the SQL Server Utility Dashboard. 90


Using the Managed Instances Viewpoint . 95


The Managed Instances List View Columns 96


The Managed Instances Detail Tabs 97


Using the Data-Tier Application Viewpoint . 100


The Data-Tier Application List View 102


The Data-Tier Application Tabs 102


PART II BUSINESS INTELLIGENCE DEVELOPMENT


CHAPTER 6 Scalable Data Warehousing 109


Parallel Data Warehouse Architecture . 109


Data Warehouse Appliances 109


Processing Architecture 110


The Multi-Rack System 110


Hub-and-Spoke Architecture 115


Data Management. 115


Shared Nothing Architecture 115


Data Types 120


Query Processing 121


Data Load Processing 121


Monitoring and Management. 122


Business Intelligence Integration. 123


Integration Services 123


Reporting Services 123


Analysis Services and PowerPivot 123


CHAPTER 7 Master Data Services 125


Master Data Management . 125


Master Data Challenges 125


Key Features of Master Data Services 126


Master Data Services Components. 127


Master Data Services Configuration Manager 128


The Master Data Services Database 128


Master Data Manager 128


Data Stewardship . 129


Model Objects 129


Master Data Maintenance 131


Business Rules 132


Transaction Logging 134


Integration. 135


Importing Master Data 135


Exporting Master Data 136


Administration. 137


Versions 137


Security 138


Model Deployment 142


Programmability. 142


The Class Library 142


Master Data Services Web Service 143


Matching Functions 143


CHAPTER 8 Complex Event Processing with StreamInsight 145


Complex Event Processing. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . .145


Complex Event Processing Applications 145


StreamInsight Highlights 146


StreamInsight Architecture. 146


Data Structures 147


The CEP Server 147


Deployment Models 149


Application Development. 150


Event Types 150


Adapters 151


Query Templates 154


Queries 155


Query Template Binding 162


The Query Object 163


The Management Interface. 163


Diagnostic Views 163


Windows PowerShell Diagnostics 164


CHAPTER 9 Reporting Services Enhancements 165


New Data Sources. 165


Expression Language Improvements. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . .165


Combining Data from More Than One Dataset 166


Aggregation 168


Conditional Rendering Expressions 169


Page Numbering 170


Read/Write Report Variable 170


Layout Control. 171


Pagination Properties 172


Data Synchronization 173


Text Box Orientation 174


Data Visualization. 175


Data Bars 175


Sparklines 176


Indicators 176


Maps 177


Reusability. 178


Shared Datasets 179


Cache Refresh 179


Report Parts 180


Atom Data Feed 182


Report Builder 3.0. 183


Edit Sessions 183


The Report Part Gallery 183


Report Access and Management. 184


Report Manager Improvements 184


Report Viewer Improvements 186


Improved Browser Support 186


RDL Sandboxing 186


SharePoint Integration. 187


Improved Installation and Configuration 187


RS Utility Scripting 187


SharePoint Lists as Data Sources 187


SharePoint Unified Logging Service 188


CHAPTER 10 Self-Service Analysis with PowerPivot 189


PowerPivot for Excel. 190


The PowerPivot Add-in for Excel 190


Data Sources 191


Data Preparation 193


PowerPivot Reports 196


Data Analysis Expressions 199


PowerPivot for SharePoint. 201


Architecture 201


Content Management 204


Data Refresh 205


Linked Documents 205


The PowerPivot Web Service 205


The PowerPivot Management Dashboard. 206


Index 207

About the Authors 215


What do you think of this book? We want to hear from you!


Microsoft is interested in hearing your feedback so we can continually improve our

books and learning resources for you. To participate in a brief online survey, please visit:


microsoft.com/learning/booksurvey


xv


Acknowledgments


I would like to first acknowledge Shirmattie Seenarine for assisting me on this

title. I couldn’t have written this book without your assistance in such a short

timeframe with everything else going on in my life. Your hard work, contributions,

edits, and perseverance are much appreciated.


Thank you to fellow SQL Server MVP Kevin Kline for introducing me to the

former SQL Server product group manager Matt Hollingsworth, who started the

chain of events that led up to this book. In addition, I would like recognize Ken

Jones, former product planner at Microsoft Press, for taking on this project. I

would also like to thank my coauthor, Stacia Misner, for doing a wonderful job

in writing the second portion of this book, which focuses on business intelligence

(BI). I appreciate your support and talent in the creation of this title.


I would also like to recognize the folks at Microsoft Press for providing me with

this opportunity and for putting the book together in a timely manner. Special

thanks goes to Maria Gargiulo, project editor, and Karen Szall, developmental editor,

for driving the project and bringing me up to speed on the “Microsoft Press”

way. Maria, your attention to detail and organizational skills during the multiple

rounds of edits and reviews is much appreciated. Also, thanks to all the folks on

the production team at Online Training Solutions, Inc. (OTSI): Jean Trenary, project

manager; Kathy Krause, copy editor; Rozanne Whalen, technical reviewer; and

Kathleen Atkins, proofreader.


This book would not have been possible without the support and assistance

of numerous individuals working for the SQL Server, High Availability, Failover

Clustering, and Virtualization product groups at Microsoft. To my colleagues on

the product team, thanks for your assistance in responding to my questions and

providing chapter reviews:


¦ SQL Server Manageability Dan Jones, Principal Group Program

Manager; Omri Bahat, Senior Program Manager; Morgan Oslake, Senior

Program Manager; Alan Brewer, Senior Programming Writer; and Tai Yee,

Program Manager II


¦ Clustering, High Availability, Virtualization, and Consolidation

Symon Perriman, Program Manager II; Ahmed Bisht, Senior Program

Manager; Max Verun, Senior Program Manager; Tai Yee, Program Manager;

Justin Erickson, Program Manager II; Zhen-Yu Zhao, SDET II; Madhan

Arumugam, Program Manager Lead II; and Steven Ekren, Senior Program

Manager


¦ General Overview and Enhancements Sabrena McBride, Senior Product

Manager


xvii


Introduction


Our purpose in Introducing Microsoft SQL Server 2008 R2 is to point out both

the new and the improved in the latest version of SQL Server. Because this

version is Release 2 (R2) of SQL Server 2008, you might think the changes are

relatively minor—more than a service pack, but not enough to justify an entirely

new version. However, as you read this book, we think you will find that there are a

lot of exciting enhancements and new capabilities engineered into SQL Server 2008 R2

that will have a positive impact on your applications, ranging from improvements

in operation to those in management. It is definitely not a minor release!


Who Is This Book For?


This book is for anyone who has an interest in SQL Server 2008 R2 and wants to

understand its capabilities. In a book of this size, we cannot cover every feature

that distinguishes SQL Server from other databases, and consequently we assume

that you have some familiarity with SQL Server already. You might be a database

administrator (DBA), an application developer, a power user, or a technical

decision maker. Regardless of your role, we hope that you can use this book to

discover the features in SQL Server 2008 R2 that are most beneficial to you.


How Is This Book Organized?


SQL Server 2008 R2, like its predecessors, is more than a database engine. It is a

collection of components that you can implement either separately or as a group

to form a scalable data platform. In broad terms, this data platform consists of

two types of components—those that help you manage data and those that help

you deliver business intelligence (BI). Accordingly, we have divided this book into

two parts to focus on the new capabilities for each of these areas.


Part I, “Database Administration,” is written with the DBA in mind and introduces

readers to the numerous innovations in SQL Server 2008 R2. Chapter 1, “SQL

Server 2008 R2 Editions and Enhancements,” discusses the key enhancements,

what’s new in the different editions of SQL Server 2008 R2, and the benefits of

running SQL Server 2008 R2 on Windows Server 2008 R2. In Chapter 2, “Multi-

Server Administration,” readers learn how centralized management capabilities


xviii Introduction


are improved with the introduction of the SQL Server Utility Control Point. Stepby-

step instructions show DBAs how to quickly designate a SQL Server instance as

a Utility Control Point and enroll instances for centralized multi-server management.

Chapter 3, “Data-Tier Applications,” focuses on how to streamline deployment

and manage and upgrade database applications with the new data-tier application

feature. Chapter 4, “High Availability and Virtualization Enhancements,”

covers high availability enhancements and includes step-by-step implementations

for ensuring business continuity with SQL Server 2008 R2, Windows Server 2008

R2, and Hyper-V Live Migration. Finally, in Chapter 5, “Consolidation and Monitoring,”

a discussion on consolidation strategies teaches readers how to improve

resource optimization. This chapter also explains how to use the new dashboard

and viewpoints to gain insight into application and database utilization, and it also

covers how to use capacity policy violations to help identify consolidation opportunities,

maximize investments, and ultimately maintain healthier systems.


In Part II, “Business Intelligence Development,” readers discover components

new to the SQL Server data platform, as well as significant enhancements to the

reporting component. Chapter 6, “Scalable Data Warehousing,” introduces the

data warehouse appliance known as SQL Server 2008 R2 Parallel Data Warehouse

by explaining its architecture, reviewing data layout strategies for optimal query

performance, and describing the integration points with SQL Server BI components.

In Chapter 7, “Master Data Services,” readers learn about master data

management concepts and the new Master Data Services component. Chapter 8,

“Complex Event Processing with StreamInsight,” describes scenarios that benefit

from complex event analysis, and it illustrates how to develop applications that

use the SQL Server StreamInsight engine for complex event processing. Chapter

9, “Reporting Services Enhancements,” reviews all the new features available in

SQL Server 2008 R2 Reporting Services that support self-service reporting and

address common report design problems. Last, Chapter 10, “Self-Service Analysis

with PowerPivot,” continues the theme of self-service by explaining how users can

integrate disparate data for analysis by using SQL Server PowerPivot for Excel, and

how to centralize and share the results of this analysis by using SQL Server PowerPivot

for SharePoint.


Pre-Release Software


To help you get familiar with SQL Server 2008 R2 as early as possible after its

release, we wrote this book using examples that work with the Release Candidate

0 (RC0) version of the product. Consequently, the final version might include new

features, and features we discuss might change or disappear. Refer to the “What’s


Introduction xix


New” topic in SQL Server Books Online at http://msdn.microsoft.com/en-us

/library/bb500435(SQL.105).aspx for the most up-to-date list of changes to the

product. Be aware that you might also notice some minor differences between the

RTM version of the product and the descriptions and screen shots that we provide.


Support for This Book


Every effort has been made to ensure the accuracy of this book. As corrections or

changes are collected, they will be added to a Microsoft Knowledge Base article

accessible via the Microsoft Help and Support site. Microsoft Press provides support

for books, including instructions for finding Knowledge Base articles, at the

following Web site:


http://www.microsoft.com/learning/support/books/


If you have questions regarding the book that are not answered by visiting this

site or viewing a Knowledge Base article, send them to Microsoft Press via e-mail

to mspinput@microsoft.com.


Please note that Microsoft software product support is not offered through

these addresses.


We Want to Hear from You


We welcome your feedback about this book. Please share your comments and

ideas via the following short survey:


http://www.microsoft.com/learning/booksurvey


Your participation will help Microsoft Press create books that better meet your

needs and your standards.


NOTE We hope that you will give us detailed feedback via our survey.

If you have questions about our publishing program, upcoming titles, or

Microsoft Press in general, we encourage you to interact with us via Twitter

at http://twitter.com/MicrosoftPress. For support issues, use only the e-mail

address shown above.


3


C H A P T E R 1


SQL Server 2008 R2 Editions

and Enhancements


Microsoft SQL Server 2008 R2 is the most advanced, trusted, and scalable data

platform released to date. Building on the success of the original SQL Server 2008

release, SQL Server 2008 R2 has made an impact on organizations worldwide with its

groundbreaking capabilities, empowering end users through self-service business intelligence

(BI), bolstering efficiency and collaboration between database administrators (DBAs) and application

developers, and scaling to accommodate the most demanding data workloads.


This chapter introduces the new SQL Server 2008 R2 features, capabilities, and editions

from a DBA’s perspective. It also discusses why Windows Server 2008 R2 is recommended

as the underlying operating system for deploying SQL Server 2008 R2. Last, SQL

Server 2008 R2 hardware and software requirements and installation strategies are also

identified.


SQL Server 2008 R2 Enhancements for DBAs


Now more than ever, organizations require a trusted, cost-effective, and scalable database

platform that offers efficiency and managed self-service BI. These organizations

face ever-changing business conditions in the global economy, IT budget constraints,

and the need to stay competitive by obtaining and utilizing the right information at the

right time.


With SQL Server 2008 R2, they can meet the pressures head on to achieve these

demanding goals. This release delivers an award-winning enterprise-class database platform

with robust capabilities that improve efficiency through better resource utilization,

end-user empowerment, and scaling out at lower costs. Enhancements to scalability and

performance, high availability, enterprise security, enterprise manageability, data warehousing,

reporting, self-service BI, collaboration, and tight integration with Microsoft

Visual Studio 2010, Microsoft SharePoint 2010, and SQL Server PowerPivot for SharePoint

make it the best database platform available.


SQL Server 2008 R2 is considered to be a minor version upgrade of SQL Server 2008.

However, for a minor upgrade it offers a tremendous amount of new, breakthrough

capabilities that DBAs can take advantage of.


4 CHAPTER 1 SQL Server 2008 R2 Editions and Enhancements


Microsoft has made major investments in the SQL Server product as a whole; however,

the new features and breakthrough capabilities that should interest DBAs the most are the

advancements in application and multi-server administration. This section introduces some of

the new features and capabilities.


Application and Multi-Server Administration Enhancements


The SQL Server product group has made sizeable investments in improving application and

multi-server management capabilities. Some of the main application and multi-server administration

enhancements that allow organizations to better manage their SQL Server environments

include


¦ The SQL Server Utility This is a new manageability feature used to centrally

monitor and manage database applications and SQL Server instances from a single

management interface known as a Utility Control Point (UCP). Instances of SQL Server,

data-tier applications, database files, and volumes are managed and viewed within the

SQL Server Utility.


¦ The Utility Control Point (UCP) As the central reasoning point for the SQL Server

Utility, the Utility Control Point collects configuration and performance information

from managed instances of SQL Server every 15 minutes. After data has been collected

from the managed instances, the SQL Server Utility dashboard and viewpoints in SQL

Server Management Studio (SSMS) provide DBAs with a health summary of SQL Server

resources through policy evaluation and historical analysis. For more information on

the SQL Server Utility, Utility Control Points, and managing instances of SQL Server, see

Chapter 2, “Multi-Server Administration.”


¦ Data-tier applications A data-tier application (DAC) is a single unit of deployment

containing all of the database’s schema, dependant objects, and deployment requirements

used by an application. A DAC can be deployed in one of two ways: it can be

authored by using the SQL Server data-tier application project in Visual Studio 2010,

or it can be created by extracting a DAC definition from an existing database with the

Extract Data-Tier Application Wizard in SSMS. Through the use of DACs, the deployment

of data applications and the collaboration between data-tier developers and

DBAs is significantly improved. For more information on authoring, deploying, and

managing data-tier applications, see Chapter 3, “Data-Tier Applications.”


¦ Utility Explorer dashboards The dashboards in the SQL Server Utility offer DBAs

tremendous insight into resource utilization and health state for managed instances of

SQL Server and deployed data-tier applications across the enterprise. Before the introduction

of the SQL Server Utility, DBAs did not have a powerful tool included with SQL

Server to assist them in monitoring resource utilization and health state. Most organizations

purchased third-party tools, which resulted in additional costs associated with


SQL Server 2008 R2 Enhancements for DBAs CHAPTER 1 5


the total cost of ownership of their database environment. The new SQL Server Utility

dashboards also assist with consolidation efforts. Figure 1-1 illustrates SQL Server Utility

dashboard and viewpoints for providing superior insight into resource utilization and

policy violations.


FIGURE 1-1 Monitoring resource utilization with the SQL Server Utility dashboard and viewpoints


¦ Consolidation management Organizations can maximize their investments by

consolidating SQL Server resources onto fewer systems. DBAs, in turn, can bolster their

consolidation efforts through their use of SQL Server Utility dashboards and viewpoints,

which easily identify underutilized and overutilized SQL Server resources across

the SQL Server Utility. As illustrated in Figure 1-2, dashboards and viewpoints make it

simple for DBAs to realize consolidation opportunities, start the process toward eliminating

underutilization, and resolve overutilization issues to create healthier, pristine

environments.


FIGURE 1-2 Identifying consolidation opportunities with the SQL Server Utility dashboard and

viewpoints


¦ Customization of utilization thresholds and policies DBAs can customize the

utilization threshold and policies for managed instances of SQL Server and deployed

data-tier applications to suit the needs of their environments. For example, DBAs can

specify the CPU utilization policies, file space utilization policies, computer CPU utilization

policies, and storage volume utilization policies for all managed instances of SQL Server.

Furthermore, they can customize the global utilization policies for data-tier applications.

For example, a DBA can specify the CPU utilization policies and file space utilization policies

for all data-tier applications. The default policy setting for overutilization is 70 percent,

whereas underutilization is set to 0 percent. By customizing the utilization threshold

policies, DBAs can maintain higher service levels for their SQL Server environments.


Figure 1-3 illustrates the SQL Server Utility. In this figure, a Utility Control Point has been

deployed and is collecting health state and resource utilization data from managed instances of

SQL Server and deployed data-tier applications. A DBA is making use of the SQL Server Utility

dashboards and viewpoints included in SSMS to proactively and efficiently manage the database


environment. This can be done at scale, with information on resource utilization throughout the

managed database environment, as a result of centralized visibility. In addition, a data-tier developer

is building a data-tier application with Visual Studio 2010; the newly created DAC package

will be deployed to a managed instance of SQL Server through the Utility Control Point.


Utility dashboard to

monitor health state

Uplo

ad dcaotlale csetion

t

Managed instance

Managed instance

Utility Control Point

UMDW msdb

Upload collection

data set

Uplo

ad collection data se t

Managed instance

DBA

SSMS

D e l i v e

r

y

D A

C p

a c k a g e o n t o

managed instance

Developer

Visual Studio

2010

DAC


FIGURE 1-3 The SQL Server Utility, including a UPC, managed instances, and a DAC


In the example in Figure 1-4, a DBA has optimized hardware resources within the environment

by modifying the global utilization policies to meet the needs of the organization. For

example, the global CPU overutilization policies of a managed instance of SQL Server and

computer have been configured to be overutilized when the utilization is greater than 85

percent. In addition, the global file space and storage volume overutilization policies for all

managed instances of SQL Server have been changed to 65 percent.


FIGURE 1-4 Configuring overutilization and underutilization global policies for managed instances


For more information on consolidation, monitoring, using the SQL Server Utility dashboards,

and modifying policies, see Chapter 5, “Consolidation and Monitoring.”


Additional SQL Server 2008 R2 Enhancements for DBAs


This section focuses on the SQL Server 2008 R2 enhancements that go above and beyond

application and multi-server administration. DBAs should be aware of the following new

capabilities:


¦ Parallel Data Warehouse Parallel Data Warehouse is a highly scalable appliance

for enterprise data warehousing. It consists of both software and hardware designed to

meet the needs of the largest data warehouses. This solution has the ability to massively

scale to hundreds of terabytes with the use of new technology, referred to as massively

parallel processing (MPP), and through inexpensive hardware configured in a hub-and-


spoke (control node and compute nodes) architecture. Performance improvements can

be attained with Parallel Data Warehouse’s design approach because it partitions large

tables over several physical nodes, resulting in each node having its own CPU, memory,

storage, and SQL Server instance. This design directly eliminates issues with speed and

provides scale because a control node evenly distributes data to all compute nodes.

The control node is also responsible for gathering data from all compute nodes when

returning queries to applications. There isn’t much a DBA needs to do from an implementation

perspective—the deployment and maintenance is simplified because the

solution comes preassembled from certified hardware vendors.


¦ Integration with Microsoft SQL Azure The client tools included with SQL Server

2008 R2 allow DBAs to connect to SQL Azure, a cloud-based service. SQL Azure is

part of the Windows Azure platform and offers a flexible and fully relational database

solution in the cloud. The hosted database is built on SQL Server technologies and is

completely managed. Therefore, organizations do not have to install, configure, or deal

with the day-to-day operations of managing a SQL Server infrastructure to support

their database needs. Other key benefits offered by SQL Azure include simplification

of the provisioning process, support for Transact-SQL, and transparent failover. Yet another

enhancement affiliated with SQL Azure is the Generate And Publish Scripts Wizard,

which now includes SQL Azure as both a source and a destination for publishing

scripts. SQL Azure has something for businesses of all sizes. For example, startups and

medium-sized businesses can use this service to create scalable, custom applications,

and larger businesses can use SQL Azure to build corporate departmental applications.


¦ Installation of SQL Server with Sysprep Organizations have been using the

System Preparation tool (Sysprep) for many years now to automate the deployment

of operating systems. SQL Server 2008 R2 introduces this technology to SQL Server.

Installing SQL Server with Sysprep involves a two-step procedure that is typically conducted

by using wizards on the Advanced page of the Installation Center. In the first

step, a stand-alone instance of SQL Server is prepared. This step prepares the image;

however, it stops the installation process after the binaries of SQL Server are installed.

To initiate this step, select the Image Preparation Of A Stand-Alone Instance For SysPrep

Deployment option on the Advanced page of the Installation Center. The second

step completes the configuration of a prepared instance of SQL Server by providing

the machine, network, and account-specific information for the SQL Server instance.

This task can be carried out by selecting the Image Completion Of A Prepared Stand-

Alone Instance step on the Advanced page of the Installation Center. SQL Server 2008

R2 Sysprep is recommended for DBAs seeking to automate the deployment of SQL

Server while investing the least amount of their time.


¦ Analysis Services integration with SharePoint SQL Server 2008 R2 introduces

a new option to individually select which feature components to install. SQL Server

PowerPivot for SharePoint is a new role-based installation option in which PowerPivot

for SharePoint will be installed on a new or existing SharePoint 2010 server to support


PowerPivot data access in the farm. This new approach promises better integration

with SharePoint while also enhancing SharePoint’s support of PowerPivot workbooks

published to SharePoint. Chapter 10, “Self-Service Analysis with PowerPivot,” discusses

PowerPivot for SharePoint.


NOTE In order to use this new installation feature option, SharePoint 2010 must be

installed but not configured prior to installing SQL Server 2008 R2.


¦ Premium Editions SQL Server 2008 R2 introduces two new premium editions to

meet the needs of large-scale data centers and data warehouses. The new editions,

Datacenter and Parallel Data Warehouse, will be discussed in the “SQL Server 2008 R2

Editions” section later in this chapter.


¦ Unicode Compression SQL Server 2008 R2 supports compression for Unicode

data types. The data types that support compression are the unicode compression and

the fixed-length nchar(n) and nvarchar(n) data types. Unfortunately, values stored off

row or in nvarchar(max) columns are not compressed. Compression rates of up to 50

percent in storage space can be achieved.


¦ Extended Protection SQL Server 2008 R2 introduces support for connecting to the

Database Engine by using Extended Protection for Authentication. Authentication is

achieved by using channel binding and service binding for operating systems that support

Extended Protection.


Advantages of Using Windows Server 2008 R2


The database platform is intimately related to the operating system. Because of this relationship,

Microsoft has designed Windows Server 2008 R2 to provide a solid IT foundation for

business-critical applications such as SQL Server 2008 R2. The combination of the two products

produces an impressive package. With these two products, an organization can achieve

maximum performance, scalability, reliability, and availability, while at the same time reducing

the total cost of ownership associated with its database platform.


It is a best practice to leverage Windows Server 2008 R2 as the underlying operating

system when deploying SQL Server 2008 R2 because the new and enhanced capabilities of

Windows Server 2008 R2 can enrich an organization’s experience with SQL Server 2008 R2.

The new capabilities that have direct impact on SQL Server 2008 R2 include


¦ Maximum scalability Windows Server 2008 R2 is capable of achieving unprecedented

workload size, dynamic scalability, and across-the-board availability and reliability.

For instance, Windows Server 2008 R2 supports up to 256 logical processors

and 2 terabytes of memory in a single operating system instance. When SQL Server

2008 R2 runs on Windows Server 2008 R2, the two products together can support

more intensive database and BI workloads than ever before.


¦ Hyper-V improvements Building on the approval and success of the original

Hyper-V release, Windows Server 2008 R2 delivers several new capabilities to the

Hyper-V platform to further improve the SQL Server virtualization experience. First,

availability can be stepped up with the introduction of Live Migration, which makes it

possible to move SQL Server virtual machines (VMs) between Hyper-V hosts without

service interruption. Second, Hyper-V can make use of up to 64 logical processors in

the host processor pool, which allows for consolidation of a greater number of SQL

Server VMs on a single Hyper-V host. Third, Dynamic Virtual Machine Storage, a new

feature, allows for the addition of virtual or physical disks to an existing VM without

requiring the VM to be restarted.


¦ Windows Server 2008 R2 Server Manager Server Manager has been optimized

in Windows Server 2008 R2. It is usually used to centrally manage and secure multiple

server roles across SQL Server instances running Windows Server 2008 R2. Remote

management of connections to remote computers is achievable with Server Manager.

Server Manager also includes a new Best Practices Analyzer tool to report best practice

violations.


¦ Best Practices Analyzer (BPA) Although there are only a few roles on Windows

Server 2008 R2 that the BPA can collect data for, this tool is still a good investment

because it helps reduce best practice violations, which ultimately helps fix and prevent

deterioration in performance, scalability, and downtime.


¦ Windows PowerShell 2.0 Windows Server 2008 R2 ships with Windows PowerShell

2.0. In addition to allowing DBAs to run Windows PowerShell commands against

remote computers and run commands as asynchronous background jobs, Windows

PowerShell 2.0 features include new and improved Windows Management Instrumentation

(WMI) cmdlets, a script debugging feature, and a graphical environment

for creating scripts. DBAs can improve their productivity with Windows PowerShell by

simplifying, automating, and consolidating repetitive tasks and server management

processes across a distributed SQL Server environment.


SQL Server 2008 R2 Editions


SQL Server 2008 R2 is available in nine different editions. The editions were designed to meet

the needs of almost any customer and are broken down into the following three categories:


¦ Premium editions


¦ Core editions


¦ Specialized editions


Premium Editions


The premium editions of SQL Server 2008 R2 are meant to meet the highest demands of

large-scale datacenters and data warehouse solutions. The two editions are


¦ Datacenter For the first time in the history of SQL Server, a datacenter edition is offered.

SQL Server 2008 R2 Datacenter provides the highest levels of security, reliability,

and scalability when compared to any other edition. SQL Server 2008 R2 Datacenter delivers

an enterprise-class data platform that provides maximum levels of scalability for

organizations looking to run very large database workloads. In addition, this edition offers

the best platform for the most demanding virtualization and consolidation efforts.

It offers the same features and functionality as the Enterprise edition; however, it differs

by supporting up to 256 logical processors, more than 25 managed instances of SQL

Server enrolled into a single Utility Control Point, unlimited virtualization, multi-instance

dashboard views and drilldowns, policy-based resource utilization evaluation, high-scale

complex event processing with Microsoft SQL Server StreamInsight, and the potential to

sustain up to the maximum amount of memory the operating system will support.


¦ Parallel Data Warehouse New to the family of SQL Server editions is SQL Server

2008 R2 Parallel Data Warehouse. It is a highly scalable appliance for enterprise data

warehousing. SQL Server 2008 R2 Parallel Data Warehouse uses massively parallel

processing (MPP) technology and hub-and-spoke architecture to support the largest

data warehouse and BI workloads, from tens or hundreds of terabytes to more than 1

petabyte, in a single solution. SQL Server 2008 R2 Parallel Data Warehouse appliances

are pre-built from leading hardware venders and include both the SQL Server software

and appropriate licenses.


Core Editions


The traditional Enterprise and Standard editions of SQL Server are considered to be core edition

offerings in SQL Server 2008 R2. The following section outlines the features associated

with both SQL Server 2008 R2 Enterprise and Standard:


¦ Enterprise SQL Server 2008 R2 Enterprise delivers a comprehensive, trusted data

platform for demanding, mission-critical applications, BI solutions, and reporting.

Some of the new features included in this edition include support for up to eight processors,

enrollment of up to 25 managed instances of SQL Server into a single Utility

Control Point, PowerPivot for SharePoint, data compression support for UCS-2 Unicode,

Master Data Services, support for up to four virtual machines, and the potential to

sustain up to 2 terabytes of RAM. It still provides high levels of availability, scalability, and

security, and includes classic SQL Server 2008 features such as data and backup compression,

Resource Governor, Transparent Data Encryption (TDE), advanced data mining

algorithms, mirrored backups, and Oracle publishing.


¦ Standard SQL Server 2008 R2 Standard is a complete data management and BI

platform that provides medium-class solutions for smaller organizations. It does not

include all the bells and whistles included in Datacenter and Enterprise; however, it

continues to offer best-in-class ease of use and manageability. Backup compression,

which was an enterprise feature with SQL Server 2008, is now a feature included with

the SQL Server 2008 R2 Standard. Compared to Datacenter and Enterprise, Standard

supports only up to four processors, up to 64 GB of RAM, one virtual machine, and two

failover clustering nodes.


Specialized Editions


SQL Server 2008 R2 continues to deliver specialized editions for organizations that have

unique sets of requirements.


¦ Developer Developer includes all of the features and functionality found in Datacenter;

however, it is strictly meant to be used for development, testing, and demonstration

purposes only. It is worth noting that it is possible to transition a SQL Server

Developer installation that is used for testing or development purposes directly into

production by upgrading it to SQL Server 2008 Enterprise without reinstallation.


¦ Web At a much more affordable price compared to Datacenter, Enterprise, and Standard,

SQL Server 2008 R2 Web is focused on service providers hosting Internet-facing

Web serving environments. Unlike Workgroup and Express, this edition doesn’t have

a small database size restriction, and it supports four processors and up to 64 GB of

memory. SQL Server 2008 R2 Web does not offer the same premium features found in

Datacenter, Enterprise, and Standard; however, it is still the ideal platform for hosting Web

sites and Web applications.


¦ Workgroup Workgroup is the next SQL Server 2008 R2 edition and is one step below

the Web edition in price and functionality. It is a cost-effective, secure, and reliable

database and reporting platform meant for running smaller workloads than Standard.

For example, this edition is ideal for branch office solutions such as branch data

storage, branch reporting, and remote synchronization. Similar to Web, it supports a

maximum database size of 524 terabytes; however, it supports only two processors

and up to 4 GB of RAM. It is worth noting that it is possible to upgrade Workgroup to

Standard or Enterprise.


¦ Express This free edition is the best entry-level alternative for independent software

vendors, nonprofessional developers, and hobbyists building client applications. This

edition is integrated with Visual Studio and is great for individuals learning about databases

and how to build client applications. Express is limited to one processor, 1 GB of

memory, and a maximum database size of 10 GB.


¦ Compact SQL Server 2008 R2 Compact is typically used to develop mobile and small

desktop applications. It is free to use and is commonly redistributed with embedded

and mobile independent software vendor (ISV) applications.


NOTE Review “Features Supported by the Editions of SQL Server 2008 R2” at

http://msdn.microsoft.com/en-us/library/cc645993(SQL.105).aspx for a complete comparison

of the key capabilities of the different editions of SQL Server 2008 R2.


Hardware and Software Requirements


The recommended hardware and software requirements for SQL Server 2008 R2 vary

depending on the component you want to install, the load anticipated on the servers, and

the type of processor class that you will use. Tables 1-1 and 1-2 describe the hardware and

software requirements for SQL Server 2008 R2.


Because SQL Server 2008 R2 supports many processor types and operating systems, Table

1-1 strictly covers the hardware requirements for a typical SQL Server 2008 R2 installation.

Typical installations include SQL Server 2008 R2 Standard and Enterprise running on Windows

Server operating systems. If you need information for Itanium-based systems or compatible

desktop operating systems, see “Hardware and Software Requirements for Installing SQL

Server 2008 R2″ at http://msdn.microsoft.com/en-us/library/ms143506(SQL.105).aspx.


TABLE 1-1 Hardware Requirements


HARDWARE COMPONENT


REQUIREMENTS


Processor


Processor type: (64-bit) x64


¦ Minimum: AMD Opteron, AMD Athlon 64, Intel Xeon

with Intel EM64T support, Intel Pentium IV with EM64T

support


¦ Processor speed: minimum 1.4 GHz; 2.0 GHz or faster

recommended


Processor type: (32-bit)


¦ Intel Pentium III-compatible processor or faster


¦ Processor speed: minimum 1.0 GHz; 2.0 GHz or faster

recommended


Memory (RAM)


Minimum: 1 GB


Recommended: 4 GB or more


Maximum: Operating system maximum


HARDWARE COMPONENT


REQUIREMENTS


Disk Space


Database Engine: 280 MB


Analysis Services: 90 MB


Reporting Services: 120 MB


Integration Services: 120 MB


Client components: 850 MB


SQL Server Books Online: 240 MB


TABLE 1-2 Software Requirements


SOFTWARE COMPONENT


REQUIREMENTS


Operating system


Windows Server 2003 SP2 x64 Datacenter, Enterprise, or Standard

edition


or


The 64-bit editions of Windows Server 2008 SP2 Datacenter,

Datacenter without Hyper-V, Enterprise, Enterprise without

Hyper-V, Standard, Standard without Hyper-V, or Windows

Web Server 2008


or


Windows Server 2008 R2 Datacenter, Enterprise, Standard, or

Windows Web Server


.NET Framework


Minimum: Microsoft .NET Framework 3.5 SP1


SQL Server support tools

and software


SQL Server 2008 R2 – SQL Server Native Client


SQL Server 2008 R2 – SQL Server Setup Support Files


Minimum: Windows Installer 4.5


Internet Explorer


Minimum: Windows Internet Explorer 6 SP1


Virtualization


Windows Server 2008 R2


or


Windows Server 2008


or


Microsoft Hyper-V Server 2008


or


Microsoft Hyper-V Server 2008 R2


NOTE Server hardware has offered both 32-bit and 64-bit processors for several years,

however, Windows Server 2008 R2 is 64-bit only. Please take this into consideration when

planning SQL Server 2008 R2 deployments on Windows Server 2008 R2.


Installation, Upgrade, and Migration Strategies


Like its predecessors, SQL Server 2008 R2 is available in both 32-bit and 64-bit editions, both

of which can be installed either with the SQL Server Installation Wizard or through a command

prompt. As was briefly mentioned earlier in this chapter, it is now also possible to use

Sysprep in conjunction with SQL Server for automated deployments with minimal administrator

intervention.


Last, DBAs also have the option to upgrade an existing installation of SQL Server or

conduct a side-by-side migration when installing SQL Server 2008 R2. The following sections

elaborate on the different strategies.


The In-Place Upgrade


An in-place upgrade is the upgrade of an existing SQL Server installation to SQL Server 2008

R2. When an in-place upgrade is conducted, the SQL Server 2008 R2 setup program replaces

the previous SQL Server binaries with the new SQL Server 2008 R2 binaries on the same

machine. SQL Server data is automatically converted from the previous version to SQL Server

2008 R2. This means that data does not have to be copied or migrated. In the example in

Figure 1-5, a DBA is conducting an in-place upgrade on a SQL Server 2005 instance running

on Server 1. When the upgrade is complete, Server 1 still exists, but the SQL Server 2005

instance, including all of its data, is now upgraded to SQL Server 2008 R2.


Upgrade

Pre-migration Post-migration

Server 1

SQL Server 2005

Server 1

SQL Server 2008 R2


FIGURE 1-5 An in-place upgrade from SQL Server 2005 to SQL Server 2008 R2


NOTE SQL Server 2000, SQL Server 2005, and SQL Server 2008 are all supported for an

in-place upgrade to SQL Server 2008 R2. Unfortunately, earlier editions, such as SQL Server

7.0 and SQL Server 6.5, cannot be upgraded to SQL Server 2008 R2.


Side-by-Side Migration


The term side-by-side migration describes the deployment of a brand-new SQL Server 2008

R2 instance alongside a legacy SQL Server instance. When the SQL Server 2008 R2 installation

is complete, a DBA migrates data from the legacy SQL Server database platform to the new

SQL Server 2008 R2 database platform. Side-by-side migration is depicted in Figure 1-6.


NOTE It is possible to conduct a side-by-side migration to SQL Server 2008 R2 by using

the same server. You can also use the side-by-side method to upgrade to SQL Server 2008

on a single server.


Data is migrated

from

SQL Server 2005

on Server 1

to

SQL Server 2008 R2

on Server 2

Migration

Pre-migration

Post-migration

Server 1

SQL Server 2005

Server 1

SQL Server 2005

Server 2

SQL Server 2008 R2


FIGURE 1-6 Side-by-side migration from SQL Server 2005 to SQL Server 2008 R2


Side-by-Side Migration Pros and Cons


The biggest benefit of a side-by-side migration over an in-place upgrade is the opportunity

to build out a new database infrastructure on SQL Server 2008 R2 and avoid potential migration

issues with an in-place upgrade. The side-by-side migration also provides more granular

control over the upgrade process because it is possible to migrate databases and components

independent of one another. The legacy instance remains online during the migration process.

All of these advantages result in a more powerful server. Moreover, when two instances

are running in parallel, additional testing and verification can be conducted, and rollback is

easy if a problem arises during the migration.


However, there are disadvantages to the side-by-side strategy. Additional hardware might

need to be purchased. Applications might also need to be directed to the new SQL Server

2008 R2 instance, and it might not be a best practice for very large databases because of the

duplicate amount of storage that is required during the migration process.


SQL Server 2008 R2 High-Level Side-by-Side Strategy


The high-level side-by-side migration strategy for upgrading to SQL Server 2008 R2 consists

of the following steps:


1. Ensure that the instance of SQL Server you plan to migrate to meets the hardware and

software requirements for SQL Server 2008 R2.


2. Review the deprecated and discontinued features in SQL Server 2008 R2 by referring

to “SQL Server Backward Compatibility” at http://msdn.microsoft.com/en-us/library

/cc707787(SQL.105).aspx.


3. Although you will not upgrade a legacy instance to SQL Server 2008 R2, it is still beneficial

to run the SQL Server 2008 R2 Upgrade Advisor to ensure that the data being

migrated to the new SQL Server 2008 R2 is supported and that there is nothing suggesting

that a break will occur after migration.


4. Procure hardware and install the operating system of your choice. Windows Server

2008 R2 is recommended.


5. Install the SQL Server 2008 R2 prerequisites and desired components.


6. Migrate objects from the legacy SQL Server to the new SQL Server 2008 R2 database

platform.


7. Point applications to the new SQL Server 2008 R2 database platform.


8. Decommission legacy servers after the migration is complete.


21


C H A P T E R 2


Multi-Server Administration


Over the years, an increasing number of organizations have turned to Microsoft SQL

Server because it embodies the Microsoft Data Platform vision to help organizations

manage any data, at any place, and at any time. The biggest challenges organizations

face with this increase of SQL Server installations have been in management.


With the release of Microsoft SQL Server 2008 came two new manageability features,

Policy-Based Management and the Data Collector, which drastically changed how database

administrators managed SQL Server instances. With Policy-Based Management,

database administrators can centrally create and enforce polices on targets such as SQL

Server instances, databases, and tables. The Data Collector helps integrate the collection,

analysis, troubleshooting, and persistence of SQL Server diagnostic information. When

introduced, both manageability features were a great enhancement to SQL Server 2008.

However, database administrators and organizations still lacked manageability tools to

help effectively manage a multi-server environment, understand resource utilization, and

enhance collaboration between development and IT departments.


SQL Server 2008 R2 addresses concerns about multi-server management with the

introduction of a new manageability feature, the SQL Server Utility. The SQL Server Utility

enhances the multi-server administration experience by helping database administrators

proactively manage database environments efficiently at scale, through centralized

visibility into resource utilization. The utility also provides improved capabilities to help

organizations maximize the value of consolidation efforts and ensure the streamlined

development and deployment of data-driven applications.


The SQL Server Utility


The SQL Server Utility is a breakthrough manageability feature included with SQL Server

2008 R2 that allows database administrators to centrally monitor and manage database

applications and SQL Server instances, all from a single management interface. This

interface, known as a Utility Control Point (UCP), is the central reasoning point in the


22 CHAPTER 2 Multi-Server Administration


SQL Server Utility. It forms a collection of managed instances with a repository for performance

data and management policies. After data is collected from managed instances, Utility

Explorer and SQL Server Utility dashboard and viewpoints in SQL Server Management Studio

(SSMS) provide administrators with a view of SQL Server resource health through policy

evaluation and analysis of trending instances and applications throughout the enterprise.

The following entities can be viewed in the SQL Server Utility:


¦ Instances of SQL Server


¦ Data-tier applications


¦ Database files


¦ Volumes


Figure 2-1 shows one possible configuration using the SQL Server Utility, which includes a

UCP, many managed instances, and a workstation running SSMS for managing the utility and

viewing the dashboard and viewpoints. The UCP stores configuration and collection information

in both the UMDW and msdb databases.


SQL Server

Management Studio

Uplo

ad dcaotlale csetion

t

Managed instance

Managed instance

Utility Control Point

UMDW msdb

Upload collection

data set

Uplo

ad collection data se t

Managed instance


FIGURE 2-1 A SQL Server Utility Control Point (UCP) and managed instances


The SQL Server Utility CHAPTER 2 23


REAL WORLD


Many organizations that participate in the Microsoft SQL Server early adopter

program are currently either evaluating SQL Server 2008 R2 or already using

it in their production infrastructure. The consensus is that organizations should

design a SQL Server Utility solution that factors in a SQL Server Utility with every

deployment. The SQL Server Utility allows you to increase visibility and control,

optimize resources, and improve overall efficiencies within your SQL Server infrastructure.


SQL Server Utility Key Concepts


Although many database administrators may be eager to implement a UCP and start proactively

monitoring their SQL Server environment, it is beneficial to take a few minutes and become

familiar with the new terminology and components that make up the SQL Server Utility.


¦ The SQL Server Utility This represents an organization’s SQL Server-related entities

in a unified view. The SQL Server Utility supports actions such as specifying resource

utilization policies that track the utilization requirements of an organization. Leveraging

Utility Explorer and SQL Server Utility viewpoints in SSMS can give you a holistic

view of SQL Server resource health.


¦ The Utility Control Point (UCP) The UCP provides the central reasoning point

for the SQL Server Utility by using SSMS to organize and monitor SQL Server resource

health. The UCP collects configuration and performance information from managed

instances of SQL Server every 15 minutes. Information is stored in the Utility Management

Data Warehouse (UMDW) on the UCP. SQL Server performance data is then compared

to policies to help identify resource bottlenecks and consolidation opportunities.


¦ The Utility Management Data Warehouse (UMDW) The UMDW is a relational

database used to store data collected by managed instances of SQL Server. The UMDW

database is automatically created on a SQL Server instance when the UCP is created.

Its name is sysutility_mdw, and it utilizes the Simple Recovery model. By default, the

collection upload frequency is set to every 15 minutes, and the data retention period is

set to 1 year.


¦ The Utility Explorer user interface A component of SSMS, this interface provides

a hierarchical tree view for managing and controlling the SQL Server Utility. Its uses

include connecting to a utility, creating a UCP, enrolling instances, deploying data-tier

applications, and viewing utilization reports affiliated with managed instances and

data-tier applications. You launch Utility Explorer from SSMS by selecting View and

then choosing Utility Explorer.


¦ The Utility Explorer dashboard and list views These provide a summary and

detailed presentations of resource health and configuration details for managed

instances of SQL Server, deployed data-tier applications, and host resources such as

CPU utilization, file space utilization, and volume space utilization. This allows superior

insight into resource utilization and policy violations and helps identify consolidation

opportunities, maximizes the value of hardware investments, and maintains healthy

systems. The utility dashboard is depicted in Figure 2-2.


FIGURE 2-2 The SQL Server Utility dashboard


UCP Prerequisites


As with other SQL Server components and features, the deployment of a SQL Server UCP

must meet the following specific prerequisites and requirements:


¦ The SQL Server version running the UCP must be SQL Server 2008 R2 or higher. (SQL

Server 2008 R2 is also referred to as version 10.5.)


¦ The SQL Server 2008 R2 edition must be Datacenter, Enterprise, Evaluation, or

Developer.


¦ The SQL Server system running the UCP must reside within a Windows Active Directory

domain.


¦ The underlying operating system must be Windows Server 2003, Windows Server

2008, or Windows Server 2008 R2. If Windows Server 2003 is used, the SQL Server

Agent service account must be a member of the Performance Monitor User group.


¦ It is recommended that the collation settings affiliated with the Database Engine instance

hosting the UCP be case-insensitive.


NOTE The Database Engine instance is the only component that can be managed

by a UCP. Other components, such as Analysis Services and Reporting Services, are not

supported.


After all these prerequisites are met, you can deploy the UCP. However, before installing

the UCP, it is beneficial to size the UMDW accordingly and understand the maximum capacity

specifications associated with a UCP.


UCP Sizing and Maximum Capacity Specifications


The wealth of information captured during capacity planning sessions can help an organization

better understand its environment and make informed decisions when designing the

UCP implementation. In the case of the SQL Server Utility, it is helpful to know that each

SQL Server UCP can manage and monitor up to 100 computers and up to 200 SQL Server

Database Engine instances. Both computers and instances can be either physical or virtual.

Additional UCPs should be provisioned if there is a need to monitor more computers and

instances.


Disk space consumption is another area you should look at in capacity planning. For

instance, the disk space consumed within the UMDW is approximately 2 GB of data per year

for each managed instance of SQL Server , whereas the disk space used by the msdb database

on the UCP instance is approximately 20 MB per managed instance of SQL Server. Last, a SQL

Server UCP can support up to a total of 1,000 user databases.


Creating a UCP


The UCP is relatively easy to set up and configure. You can deploy it either by using the

Create Utility Control Point Wizard in SSMS or by leveraging Windows PowerShell scripts.

The high-level steps for creating a UCP include specifying the instance of SQL Server in which

the UCP will be created, choosing the account to run the utility control set, ensuring that the

instance is validated and passes the conditions test, reviewing the selections made, and finalizing

the UCP deployment.


Although the setup is fairly straightforward, the following conditions must be met to successfully

deploy a UCP:


¦ You must have administrator privileges on the instance of SQL Server.


¦ The instance of SQL Server must be SQL Server 2008 R2 or higher.


¦ The SQL Server edition must support UCP creation.


¦ The instance of SQL Server cannot be enrolled with any other UCP.


¦ The instance of SQL Server cannot already be a UCP.


¦ There cannot be a database named sysutility_mdw on the specified instance of SQL

Server.


¦ The collection sets on the specified instance of SQL Server must be stopped.


¦ The SQL Server Agent service on the specified instance must be started and configured

to start automatically.


¦ The SQL Server Agent proxy account cannot be a built-in account such as Network

Service.


¦ The SQL Server Agent proxy account must be a valid Windows domain account on the

specified instance.


Creating a UCP by Using SSMS


It is important to understand how to effectively use the Create Utility Control Point Wizard in

SSMS to create a SQL Server UCP. Follow these steps when using SSMS:


1. In SSMS, connect to the SQL Server 2008 R2 Database Engine instance in which the

UCP will be created.


2. Launch the Utility Explorer by selecting View and then selecting Utility Explorer.


3. On the Getting Started tab, click the Create A Utility Control Point (UCP) link or click

the Create Utility Control Point icon on the Utility Explorer toolbar.


4. The Create Utility Control Point Wizard is now invoked. Review the introduction message,

and then click Next to begin the UCP creation process. If you want, you can

select the Do Not Show This Page Again check box.


5. On the Specify The Instance Of SQL Server page, click the Connect button to specify

the instance of SQL Server in which the new UCP will be created, and then click Connect

in the Connect To Server dialog box.


6. Specify a name for the UCP, as illustrated in Figure 2-3, and then click Next to continue.


FIGURE 2-3 The Specify The Instance Of SQL Server page


NOTE Using a meaningful name is beneficial and easier to remember, especially when

you plan on implementing more than one UCP within your SQL Server infrastructure.

For example, to easily distinguish between multiple UCPs you might name the UCP that

manages the production servers “Production Utility” and the UCP for Test Servers “Test

Utility.” When connected to the UCP, users will be able to distinguish between the different

control points in Utility Explorer.


7. On the Utility Collection Set Account page, there are two options available for identifying

the account that will run the utility collection set. The first option is a Windows

domain account, and the second option is the SQL Server Agent service account. Note

that the SQL Server Agent service account can only be used if the SQL Server Agent

service account is leveraging a Windows domain account. For security purposes, it is

recommended that you use a Windows domain account with low privileges. Indicate

that the Windows domain account will be used as the SQL Server Agent proxy account

for the utility collection set, and then click Next to continue.


8. On the next page, the SQL Server instance is compared against a series of prerequisites

before the UCP is created. Failed conditions are displayed in a validation report. Correct

all issues, and then click the Rerun Validation button to verify the changes against

the validation rules. To save a copy of the validation report for future reference, click

Save Report, and then specify a location for the file. To continue, click Next.


NOTE As mentioned in the prerequisite steps before these instructions, SQL Server

Agent is, by default, not configured to start automatically during the installation of SQL

Server 2008 R2. Use the SQL Server Configuration Manager tool to configure the SQL

Server Agent service to start automatically on the specified instance.


9. Review the options and settings selected on the Summary Of UCP Creation page, and

click Next to begin the installation.


10. The Utility Control Point Creation page communicates the steps and report status affiliated

with the creation of a UCP. The steps involve preparing the SQL Server instance

for UCP creation, creating the UMDW, initializing the UMDW, and configuring the SQL

Server Utility collection set. Review each step for success and completeness. If you wish,

save a report on the creation of the UCP operation. Next, click Save Report and choose

a location for the file. Click Finish to close the Create Utility Control Point Wizard.


Creating a UCP by Using Windows PowerShell


Windows PowerShell can be used instead of SSMS to create a UCP. The following syntax

(available in the article “How To: Enroll an Instance of SQL Server (SQL Server Utility),” online

at http://msdn.microsoft.com/en-us/library/ee210563(SQL.105).aspx), illustrates how to create

a UCP with Windows PowerShell. You will need to change the elements inside the quotes to

reflect your own desired arguments.


NOTE When working with Windows Server 2008 R2, you can launch Windows PowerShell

by clicking the Windows PowerShell icon on the Start Menu taskbar. For more information

on SQL Server and Windows PowerShell, see “SQL Server PowerShell Overview” at

http://msdn.microsoft.com/en-us/library/cc281954.aspx.


$UtilityInstance = new-object –Type Microsoft.SqlServer.Management.Smo.Server

“ComputerName\UCP-Name”;

$SqlStoreConnection = new-object –Type

Microsoft.SqlServer.Management.Sdk.Sfc.SqlStoreConnection

$UtilityInstance.ConnectionContext.SqlConnectionObject;

$Utility =

[Microsoft.SqlServer.Management.Utility.Utility]::CreateUtility(“Utility”,

$SqlStoreConnection, “ProxyAccount”, “ProxyAccountPassword”);


UCP Post-Installation Steps


When the Create Utility Control Point Wizard is closed, the Utility Explorer is invoked, and

you are automatically connected to the newly created UCP. The UCP is automatically enrolled

as a managed instance. The data collection process also commences immediately. The

dashboards, status icons, and utilization graphs associated with the SQL Server Utility display

meaningful information after the data is successfully uploaded.


NOTE Do not become alarmed if no data is displayed in the dashboard and viewpoints in

the Utility Explorer Content pane; it can take up to 45 minutes for data to appear at first.

All subsequent uploads generally occur every 15 minutes.


A beneficial post-installation task is to confirm the successful creation of the UMDW. This

can be done by using Object Explorer to verify that the sysutility_mdw database exists on the

SQL Server instance. At this point, you can modify database settings.such as the initial size

of the database, autogrowth settings, and file placement.based on the capacity planning

exercises discussed in the “UCP Sizing and Maximum Capacity Specifications” section earlier

in this chapter.


Enrolling SQL Server Instances


After you have established a UCP, the next task is to enroll an instance or instances of SQL

Server into a SQL Server Control Point. Similar to deploying a Utility Control Point, this task is

accomplished by using the Enroll Instance Wizard in SSMS or by leveraging Windows PowerShell.

The high-level steps affiliated with enrolling instances into the SQL Server UCP include

choosing the UCP to utilize, specifying the instance of SQL Server to enroll, selecting the account

to run the utility collection set, reviewing prerequisite validation results, and reviewing

your selections. The enrollment process then begins by preparing the instance for enrollment.

The cache directory is created for the collected data, and then the instance is enrolled into

the designated UCP.


IMPORTANT A UCP created on SQL Server 2008 R2 Enterprise can have a maximum of

25 managed instances of SQL Server. If more than 25 managed instances are required, then

you must utilize SQL Server 2008 R2 Datacenter.


Managed Instance Enrollment Prerequisites


As with many of the other tasks in this chapter, certain conditions must be satisfied to successfully

enroll an instance:


¦ You must have administrator privileges on the instance of SQL Server.


¦ The instance of SQL Server must be SQL Server 2008 R2 or higher.


¦ The SQL Server edition must support instance enrollment.


¦ The instance of SQL Server cannot be enrolled with any other UCP.


¦ The instance of SQL Server cannot already be a UCP.


¦ The instance of SQL Server must have the utility collection set installed.


¦ The collection sets on the specified instance of SQL Server must be stopped.


¦ The SQL Server Agent service on the specified instance must be started and configured

to start automatically.


¦ The SQL Server Agent proxy account cannot be a built-in account such as Network

Service.


¦ The SQL Server Agent proxy account must be a valid Windows domain account on the

specified instance.


Enrolling SQL Server Instances by Using SSMS


The following steps should be followed when enrolling a SQL Server instance via SSMS:


1. In Utility Explorer, connect to the desired SQL Server Utility (for example, Production

Utility), expand the UCP, and then select Managed Instances.


2. Right-click the Managed Instances node, and select Enroll Instance.


3. The Enroll Instance Wizard is launched. Review the introduction message, and then

click Next to begin the enrollment process. If you want, you can select the Do Not

Show This Page Again check box.


4. On the Specify The Instance Of SQL Server page, click the Connect button to specify

the instance of SQL Server to enroll in the UCP.


5. Supply the SQL Server instance name, and then click Connect in the Connect To Server

dialog box.


6. Click Next to proceed. The Utility Collection Set Account page is invoked.


7. There are two options available for specifying an account to run the utility collection

set. The first option is a Windows domain account, and the second option is the SQL

Server Agent service account. You can use the SQL Server Agent service account only if

the SQL Server Agent service account is leveraging a Windows domain account. For security

purposes, it is recommended that you use a Windows domain account with low

privileges. Specify the Windows domain account to be used as the SQL Server Agent

proxy account for the utility collection set, and then click Next to continue.


8. As shown in Figure 2-4, a series of conditions will be evaluated against the SQL Server

instance to ensure that it passes all of the prerequisites before the instance is enrolled.

If there are any failures preventing the enrollment of the SQL Server instance, correct

them and then click Rerun Validation. To save the validation report, click Save Report

and specify a location for the file. Click Next to continue.


FIGURE 2-4 The SQL Server Instance Validation screen


9. Review the Summary Of Instance Enrollment page, and then click Next to enroll your

instance of SQL Server.


10. The following actions will be automatically completed on the Enrollment Of SQL Server

Instance page: the instance will be prepared for enrollment, the cache directory for the

collected data will be created, and the instance will be enrolled. Review the results, and

click Finish to finalize the enrollment process.


11. Repeat the steps to enroll additional instances.


Enrolling SQL Server Instances by Using

Windows PowerShell


Windows PowerShell can also be used to enroll instances. In fact, scripting may be the way

to go if there is a need to enroll a large number of instances into a SQL Server UCP. Let’s say

you need to enroll 200 instances, for example. Using the Enroll Instance Wizard in SSMS can

be very time consuming, because the wizard is a manual process in which you can enroll only

one instance at a time. In contrast, you can enroll 200 instances with a single script by using

Windows PowerShell. The following syntax illustrates how to create a UCP by using Windows

PowerShell. Change the elements in the quotes to match your environment.


$UtilityInstance = new-object -Type Microsoft.SqlServer.Management.Smo.Server

“ComputerName\UCP-Name”;

$SqlStoreConnection = new-object –Type

Microsoft.SqlServer.Management.Sdk.Sfc.SqlStoreConnection

$UtilityInstance.ConnectionContext.SqlConnectionObject;

$Utility =

[Microsoft.SqlServer.Management.Utility.Utility]::Connect($SqlStoreConnection);

$Instance = new-object -Type Microsoft.SqlServer.Management.Smo.Server

“ComputerName\ManagedInstanceName”;

$InstanceConnection = new-object –Type

Microsoft.SqlServer.Management.Sdk.Sfc.SqlStoreConnection

$Instance.ConnectionContext.SqlConnectionObject;

$ManagedInstance = $Utility.EnrollInstance($InstanceConnection, “ProxyAccount”,

“ProxyPassword”);


The Managed Instances Dashboard


After you have enrolled all of your instances associated with a UCP, you can review the Managed

Instances dashboard, as illustrated in Figure 2-5, to gain quick insight into the health

and utilization of all of your managed instances. The Managed Instances dashboard is covered

in Chapter 5, “Consolidation and Monitoring.”


FIGURE 2-5 The Managed Instances dashboard


Managing Utility Administration Settings


After you are connected to a UCP, use the Utility Administration node in the Utility Explorer

navigation pane to view and configure global policy settings, security settings, and data

warehouse settings across the SQL Server Utility. The configuration tabs affiliated with the

Utility Administration node are the Policy, Security, and Data Warehouse tabs. The following

sections explore the Utility Administration settings available within each tab. You must first

connect to a SQL Server UCP before modifying settings.


Connecting to a UCP


Before managing or configuring UCP settings, a database administrator must connect to a

UCP by means of Utility Explorer in SSMS. Use the following procedure to connect to a UCP:


1. Launch SSMS and connect to an instance of SQL Server.


2. Select View and then Utility Explorer.


3. On the Utility Explorer toolbar, click the Connect To Utility icon.


4. In the Connect To Server dialog box, specify a UCP instance, and then click Connect.


5. After you are connected, you can deploy data-tier applications, manage instances, and

configure global settings.


NOTE It is not possible to connect to more than one UCP at the same time. Therefore,

before attempting to connect to an additional UCP, click the Disconnect From Utility icon

on the Utility Explorer toolbar to disconnect from the currently connected UCP.


The Policy Tab


You use the Policy tab to view or modify global monitoring settings. Changes on this tab are

effective across the SQL Server Utility. You can view the Policy tab by connecting to a UCP

through Utility Explorer and then selecting Utility Administration. Select the Policy tab in the

Utility Explorer Content pane. Policies are broken down into three sections: Global Policies For

Data-Tier Applications, Global Policies For Managed Instances, and Volatile Resource Policy

Evaluation. To expand the list of values for these options, click the arrow next to the policy

name or click the policy title.


Global Policies For Data-Tier Applications


Use the first section on the Policy tab, Global Polices For Data-Tier Applications, to view or

configure global utilization policies for data-tier applications. You can set underutilization or

overutilization policy thresholds for data-tier applications by specifying a percentage in the

controls on the right side of each policy description. For example, it is possible to configure

underutilized and overutilized settings for CPU utilization and file space utilization for data

files and logs. Click the Apply button to save changes, or click the Discard or Restore Default

buttons as needed. By default, the overutilized threshold is 70 percent, and the underutilized

threshold is 0 percent.


Global Policies For Managed Instances


Global Policies For Managed Instances is the next section on the Policy tab. Here you can set

global SQL Server managed instance application monitoring policies for the SQL Server Utility.

As illustrated in Figure 2-6, you can set underutilization and overutilization thresholds to

manage numerous issues, including processor capacity, file space, and storage volume space.


FIGURE 2-6 Modifying global policies for managed instances


Volatile Resource Policy Evaluation


The final section on the Policy tab is Volatile Resource Policy Evaluation. This section, displayed

in Figure 2-7, provides strategies to minimize unnecessary reporting noise and unwanted

violation reporting in the SQL Server Utility. You can choose how frequently the CPU

utilization policies can be in violation before reporting the CPU as overutilized. The default

evaluation period for processor overutilization is 1 hour; 6 hours, 12 hours, 1 day, and 1

week can also be selected. The default percentage of data points that must be in violation

before a CPU is reported as being overutilized is 20 percent. The options range from 0 percent

to 100 percent.


FIGURE 2-7 Volatile resource policy evaluation


The next set of configurable elements allows you to determine how frequently CPU utilization

polices should be in violation before the CPU is reported as being underutilized. The default

evaluation period for processor underutilization is 1 week. Options range from 1 day to 1

month. The default percentage of data points that must be in violation before a CPU is reported

as being underutilized is 90 percent. You can choose between 0 percent and 100 percent.


To change policies, use the slider controls to the right of the policy descriptions, and then

click Apply. You can also restore default values or discard changes by clicking the buttons at

the bottom of the display pane.


REAL WORLD


Let’s say you configure the CPU overutilization polices by setting the Evaluate SQL

Server Utility Polices Over This Moving Time Window setting to 12 hours and the

Percent Of SQL Server Utility Polices In Violation During The Time Window Before

CPU Is Reported As Overutilized setting to 30 percent. Over 12 hours, there will

be 48 policy evaluations . Fourteen of these must be in violation before the CPU is

marked as overutilized.


The Security Tab


From a security and authorization perspective, there are two security roles associated with a

UCP. The first role is the Utility Administrator, and the second role is the Utility Reader. The

Utility Administrator is ultimately the “superuser” who has the ability to manage any setting

or view any dashboard or viewpoint associated with the UCP. For example, a Utility Administrator

can enroll instances, manage settings in the Utility Administration node, and much

more. The second security role is the Utility Reader, which has rights to connect to the SQL

Server Utility, observe all viewpoints in Utility Explorer, and view settings on the Utility Administration

node in Utility Explorer.


You can use the Security tab in the Utility Administration node of Utility Explorer to view

and provide Utility Reader privileges to a SQL Server login. By default, logins that have

sysadmin privileges on the instance running the UCP automatically have full administrative

privileges over the UCP. A database administrator must use a combination of both Object Explorer

and the Security Tab in Utility Administration to add or modify login settings affiliated

with the UCP.


For example, the following steps grant a new user the Utility Administrator role by creating

a new SQL Server login that uses Windows Authentication:


1. Open Object Explorer in SSMS, and expand the folder of the server instance that is

running the UCP in which you want to create the new login.


2. Right-click the Security folder, point to New, and then select Login.


3. On the General page of the Login dialog box, enter the name of a Windows user in the

Login Name box.


4. Select Windows Authentication.


5. On the Server Roles page, select the check box for the sysadmin role.


6. Click OK.


By default, this user is now a Utility Administrator, because he or she has been granted the

sysadmin role.


The next example will grant a standard SQL Server user the Utility Reader read-only privileges

for the SQL Server Utility dashboard and viewpoints.


1. Open Object Explorer in SSMS, and expand the folder of the server instance that

is running the UCP in which you want to create the new login. For this example,

SQL2K8R2-01\test2 will be used.


MORE INFO Review the article “CREATE LOGIN (Transact-SQL)” at the following link

for a refresher on how to create a login in SQL Server: http://technet.microsoft.com

/en-us/library/ms189751.aspx.


2. Right-click the Security folder, point to New, and then select Login.


3. On the General page, enter the name of a Windows user in the Login Name box.


4. Select Windows Authentication.


5. Click OK.


NOTE Unlike in the previous example, do not assign this user the sysadmin role on the

Server Role page. If you do, the user will automatically become a Utility Administrator

and not a Utility Reader on the UCP.


6. In Utility Explorer, connect to the UCP instance in which you created the login

(SQL2K8R2-01\Test2).


7. Select the Utility Administration node, and then select the Security tab in the Utility

Explorer Content pane.


8. Next to the newly created user (SQL2K8R2-01\Test2), as shown in Figure 2-8, grant the

Utility Reader privilege, and then click Apply.


FIGURE 2-8 Configuring read-only privileges for the SQL Server Utility


REAL WORLD


Many organizations have large teams managing their SQL Server infrastructures

because they have hundreds of SQL Server instances within their environment.

Let’s say you wanted to grant 50 users the read-only privilege for the SQL

Server Utility dashboard and viewpoints. It would be very impractical to grant every

single database administrator the read-only privilege. Therefore, if you have many

database administrators and you want to grant them the read-only role for the SQL

Server Utility within your environment, you can take advantage of a Role Based Access

model to streamline the process.


For example, you can create a security group within your Active Directory domain

called Utility Readers and then add all the desired database administrators and Windows

administrator accounts into this group. Then in SSMS, you create a new login

and select the Active Directory security group called Utility Readers. The final step

involves adding the Utility Reader role to the Utility Reader security group on the

Security tab in the Utility Administration node within Utility Explorer. By following

these steps, you provide access to all of your database administrators in a fraction

of the time. In addition, the use of RBA makes it quite easier to manage the ongoing

maintenance of security of the SQL Server Utility.


The Data Warehouse Tab


You view and modify the data retention period for utilization information collected for managed

instances of SQL Server on the Data Warehouse tab in the Utility Administration node in

Utility Explorer. In addition, the UMDW Database Name and Collection Set Upload Frequency

elements can be viewed; however, they cannot be modified in this version of SQL Server 2008

R2. There are plans to allow these settings to be modified in future versions of SQL Server.

The following steps illustrate how to modify the data retention period for the UMDW:


1. Launch SSMS and connect to a UCP through Utility Explorer.


2. Select the Utility Administration node in Utility Explorer.


3. Click the Data Warehouse tab in the Utility Explorer Content pane.


4. In the Utility Explorer Content pane, select the desired data retention period for

the UMDW, as displayed in Figure 2-9. The options are 1 month, 3 months, 6 months,

1 year, or 2 years.


FIGURE 2-9 Configuring the data retention period


5. Click the Apply button to save the changes. Alternatively, click the Discard Changes or

Restore Defaults buttons as needed.


41


C H A P T E R 3


Data-Tier Applications


Ask application developers or database administrators what it was like to work with

data-driven applications in the past, and most probably do not use adjectives such

as “easy,” “enjoyable,” or “wonderful” when they describe their experience. Indeed, the

development, deployment, and even the management of data-driven applications in the

past were a struggle. This was partly because Microsoft SQL Server and Microsoft Visual

Studio were not really outfitted to handle the development of data-driven applications,

the ability to create deployment policies did not exist, and application developers

couldn’t effortlessly hand off a single package to database administrators for deployment.

After a data-driven application was deployed, developers and administrations

found making changes to be a tedious process. Much later in the life cycle of data-driven

applications, they came to the stark realization that there was no tool available to centrally

manage a deployed environment. Obviously, many challenges existed throughout

the life cycle of a data-driven application.


Introduction to Data-Tier Applications


With the release of Microsoft SQL Server 2008 R2, the SQL Server Manageability team

addressed these struggles by introducing support for data-tier applications to help

streamline the deployment, management, and upgrade of database applications. A datatier

application, also referred to as a DAC, is a single unit of deployment that contains all

the elements used by an application, such as the database application schema, instancelevel

objects, associated database objects, files and scripts, and even a manifest defining

the organization’s deployment requirements.


The DAC improves collaboration between data-tier developers and database administrators

throughout the application life cycle and allows organizations to develop, deploy,

and manage data-tier applications in a much more efficient and effective manner than

ever before, mainly because the DAC file functions as a single unit. Database administrators

can now also centrally manage, monitor, deploy, and upgrade data-tier applications

with SQL Server Management Studio and view DAC resource utilization across the SQL

Server infrastructure in Utility Explorer at scale.


42 CHAPTER 3 Data-Tier Applications


The Data-Tier Application Life Cycle


There are two common methods for generating a DAC. One is to author and build a DAC

using a SQL Server data-tier application project in Microsoft Visual Studio 2010. In the second

method, you can extract a DAC from an existing database by using the Extract Data-Tier Application

Wizard in SQL Server Management Studio. Alternatively, a DAC can be generated

with Windows PowerShell commands.


Figure 3-1 illustrates the data-tier application generation and deployment life cycle for

both a new data-tier application project in Visual Studio 2010 and an extracted DAC created

with the Extract Data-Tier Application Wizard in SQL Server Management Studio (SSMS). In

the illustration, the DAC package is deployed to the same instance of SQL Server 2008 R2 in

both methodologies.


.dacpac

Visual Studio

Data-tier

developer

Build

Deploy

SQL Server

.dacpac

Extract

Deploy

Managed instances

SQL Server 2008 R2

Upload collection

data set

DBA

Utility Control Point

SQL Server

Management

Studio


FIGURE 3-1 The data-tier application life cycle


Introduction to Data-Tier Applications CHAPTER 3 43


Data-tier developers using a data-tier application project template in Visual Studio 2010

first build a DAC and then deploy the DAC package to an instance of SQL Server 2008 R2.

In contrast, database administrators using the Extract Data-Tier Application Wizard in SQL

Server Management Studio generate a DAC from an existing database. The DAC package is

then deployed to a SQL Server 2008 R2 instance. In both methods, the deployment creates a

DAC definition that is stored in the msdb system database and a user database that stores the

objects identified in the DAC definition. Finally, the applications connect to the database associated

with the DAC. Database administrators use the Utility Control Point and Utility Explorer in

SQL Server Management Studio to centrally manage and monitor data-tier applications at scale.


Common Uses for Data-Tier Applications


Data-tier applications are used in a multitude of ways to serve many different needs. For

example, organizations may use data-tier applications when they need to


¦ Deploy a data-tier application for test, staging, and production instances of the Database

Engine.


¦ Create DAC packages to tighten integration handoffs between data-tier developers

and database administrators.


¦ Move changes from development to production.


¦ Upgrade an existing DAC instance to a newer version of the DAC by using the Upgrade

Data-Tier Wizard.


¦ Compare database schemas between two data-tier applications.


¦ Upgrade database schemas from older versions of SQL Server to SQL Server 2008 R2—

for example, to extract a data-tier application from SQL Server 2000 and then deploy

the package on SQL Server 2008 R2.


¦ Consider next generation development, which is achieved by importing an existing

version of a DAC into Visual Studio and then modifying the schema, objects, or deployment

strategies.


¦ Author database objects by using source code control systems such as Team

Foundation Server.


¦ Integrate data-tier applications with Microsoft SQL Azure. Currently, it is possible to

deploy, register, and delete. Upgrading of data-tier applications with SQL Azure is

likely to be supported in future releases.


Real World


Organizations looking to accelerate and standardize deployment of database

applications within their database environments should leverage data-tier

applications included in SQL Server 2008 R2. By utilizing data-tier applications, an

organization captures intent and produces a single deployment package, providing

a more reliable and consistent deployment experience than ever before. In addition,

data-tier applications facilitate streamlined collaboration between development

and database administrator teams, which improves efficiency.


Supported SQL Server Objects


Every DAC contains objects used by the application, including schemas, tables, and views.

However, some objects are not supported in data-tier applications. The following list can help

you become acquainted with some of the SQL Server objects that are supported.


¦ Database role


¦ Function: Inline Table-valued


¦ Function: Multistatement Table-valued


¦ Function: Scalar


¦ Index: Clustered


¦ Index: Non-clustered


¦ Index: Unique


¦ Login


¦ Schema


¦ Stored Procedure: Transact-SQL


¦ Table: Check Constraint


¦ Table: Collation


¦ Table: Column, including computed columns


¦ Table: Constraint, Default


¦ Table: Constraint, Foreign Key


¦ Table: Constraint, Index


¦ Table: Constraint, Primary Key


¦ Table: Constraint, Unique


¦ Trigger: DML


¦ Type: User-defined Data Type


¦ Type: User-defined Table Type


¦ User


¦ View


Database administrators do not have to worry about looking for unsupported objects. This

laborious task is accomplished with the Extract Data-Tier Application Wizard. Unsupported

objects such as DDL triggers, service broker objects, and full-text catalog objects are identified

and reported by the wizard. Unsupported objects are identified with a red icon that represents

an invalid entry. Database administrators must also pay close attention to objects with a yellow

icon, because this communicates a warning. A yellow icon usually warns database administrators

that although an object is supported, it is linked to and quite reliant on an unsupported

object. Database administrators need to review and address all objects with red and yellow

icons. The wizard does not create a DAC package until unsupported objects are removed. For

a list of some common supported objects, review the topic “SQL Server Objects Supported in

Data-tier Applications” at http://msdn.microsoft.com/en-us/library/ee210549(SQL.105).aspx.


Visual Studio 2010 and Data-Tier Application Projects


By leveraging the new project DAC template in Visual Studio 2010, data-tier developers

can create new data-tier applications from scratch or edit existing data-tier applications by

importing them directly into a project. Data-tier developers then add database objects such

as tables, views, and stored procedures to the data-tier application project. Data-tier developers

can also define specific deployment requirements for the data-tier application. When

the data-tier application project is complete, the data-tier developer creates a single unit of

deployment, known as a DAC file package, from within Visual Studio 2010. This package is

delivered to a database administrator, who deploys it to one or more SQL Server 2008 R2

instances. Alternatively, database administrators can use the DAC package to upgrade an

existing data-tier application that has already been deployed.


Launching a Data-Tier Application Project Template in

Visual Studio 2010


The following steps describe how to launch a data-tier application project template in Visual

Studio 2010:


1. Launch Visual Studio 2010.


2. In Visual Studio 2010, select File, and then select New Project.


3. In the Installed Templates list, expand the Database node, and then select SQL Server.


4. In the Project Template pane, select Data-Tier Application.


5. Specify the name, location, and solution name for the data-tier application, as shown

in Figure 3-2, and click OK.


FIGURE 3-2 Selecting the Data-Tier Application project template in Visual Studio 2010


6. Select Project, and then click Add New Item to add and create a database object based

on the Data-Tier Application project template. Some of the database objects included

in the template are scalar-valued function, schema, table, index, login, stored procedure,

user, user-defined table type, view, table-valued function, trigger, user-defined

data type, database role, data generation plan, and inline function.


Figure 3-3 illustrates the syntax for creating a sample Employees table schema for a

data-tier application in Visual Studio 2010. The Solution Explorer pane also includes the

other schema objects—specifically the tables associated with the data-tier application.


FIGURE 3-3 The Create Table schema and the Solution Explorer pane in a Visual Studio 2010

DAC project


Importing an Existing Data-Tier Application Project into

Visual Studio 2010


Instead of creating a DAC from the ground up in Visual Studio 2010, a data-tier developer can

choose to import an existing data-tier application into Visual Studio 2010 and then either edit

the DAC or completely reverse-engineer it. The following steps enable you to import objects

from a data-tier application package to a data-tier application project in Visual Studio 2010:


1. Create a new data-tier application project in Visual Studio.


2. In the Visual Studio Solution Explorer pane, navigate to the node for the desired datatier

application project.


3. Right-click the node for the desired data-tier application project, and then select the

Import Data-Tier Application Wizard.


4. Review the information on the Welcome page, and then click Next.


5. On the Specify Import Options page, select the option that allows you to import from

a data-tier application package.


6. Click the Browse button, and navigate to the folder in which you placed the .dacpac to

import. Select the file, and then click Open. Click Next to continue.


7. Review the report that shows the status of the import actions, as illustrated in Figure

3-4, and then click Finish.


FIGURE 3-4 Reviewing the results when importing an existing DAC into Visual Studio 2010


8. In Schema View, navigate to the dbo schema, navigate to the Tables, Views, and

Stored Procedures nodes, and verify that the objects created are now in the data-tier

application.


Data-tier developers and database administrators interested in working in Visual Studio

to initiate any of the actions mentioned in this section, such as importing or creating

a data-tier application, can refer to the article “Creating and Managing Databases and

Data-tier Applications in Visual Studio” at http://msdn.microsoft.com/en-us/library

/dd193245(VS.100).aspx.


Extracting a Data-Tier Application with SQL Server

Management Studio


The Extract Data-Tier Application Wizard is another tool that you can use for creating a new

data-tier application. The wizard is in SQL Server 2008 R2 Management Studio. In this method,

the wizard works its way into an existing SQL Server database, reads the content of the

database and the logins associated with it, and ensures that the new data-tier application can

be created. Finally, the wizard either creates a new DAC package or communicates all errors

and issues that need to be addressed before one can be created. This approach comes with a

big advantage. The extraction process can be applied to many versions of SQL Server, not just

SQL Server 2008 R2. For example, database administrators can use the wizard to generate a

DAC package from SQL Server 2000, SQL Server 2005, SQL Server 2008, or SQL Server 2008

R2 databases.


IMPORTANT DAC definitions remain unregistered when you use the Extract Data-Tier

Application Wizard. Database administrators must use the Register Data-Tier Application

Wizard in SQL Server 2008 R2 Management Studio to register a DAC definition. For

additional information on registering a DAC definition, see the “Registering a Data-Tier

Application” section later in this chapter.


Follow these steps to extract a data-tier application:


1. In Object Explorer, connect to a SQL Server instance containing the database that

houses the data-tier application to be extracted.


2. Expand the Database folder, and select a database to extract.


3. Invoke the Extract Data-Tier Application Wizard by right-clicking the desired database,

selecting Tasks, and then selecting Extract Data-Tier Application.


4. Review the information on the Introduction page, and then click Next to begin the extraction

process. Select the Do Not Show This Page Again check box if you do not want

the Introduction page displayed in the future when using the wizard.


5. On the Set Properties page, illustrated in Figure 3-5, complete the DAC properties by

typing in the application name, version, and description, as described here:


¦ Application name This refers to the name of the DAC. Although this name can

be different from the DAC package file, it is recommended that you make it similar

enough so that it still identifies the application.


¦ Version The DAC version identification helps developers manage changes when

working in Visual Studio. In addition, the version information helps identify the DAC

package version used during deployment. The DAC version information is stored

in the msdb database and can be viewed in SQL Server Management Studio in the

data-tier applications node.


¦ Description This property is optional. Use it to describe the DAC. If this section

is completed, the information is saved in the msdb database under the data-tier

applications node in Management Studio.


FIGURE 3-5 Specifying DAC properties when using the Extract Data-Tier Application Wizard


6. Next, indicate where the DAC package file is to be saved. Remember to use the appropriate

extension, .dacpac. Alternatively, click the Browse button and identify the name

and location for the DAC package file.


7. You also have the option to select the Overwrite Existing File check box to replace a

DAC package with the same name. If you choose a name that already exists for a DAC

package, the existing file is not automatically overwritten. Instead, an exclamation mark

appears next to the Browse button. The Next button on the page is also disabled until

you change the name you specified or select the Overwrite Existing File check box.


8. After you have entered all the DAC properties, click Next to continue.


9. On the Validation And Summary page, illustrated in Figure 3-6, review the information

presented in the DAC properties summary tree because these settings are used to

extract the DAC you specified. The wizard checks and validates object dependencies,


confirms that the information is supported by the DAC, and displays DAC object issues,

DAC object warnings, and DAC objects that are supported. If there are no issues, click Next

to continue. You also have the option to click Save Report to capture the entire report.


FIGURE 3-6 The Extract Data-Tier Application Wizard’s Validation And Summary page


NOTE The Next button is disabled on the Validation And Summary page if one or

more objects are not supported by the DAC. These items need to be addressed before

the wizard can proceed. You usually remedy these issues by removing the unsupported

objects from the database and rerunning the wizard.


10. The Build Package page is the final screen and is used to monitor the status of the

extraction and build process affiliated with the DAC package file. The wizard extracts

a DAC from the selected database, creates the package in memory, and saves the file

to the location specified in the previous steps. You can also click the links in the Result

column to review the outcome and any additional corresponding steps if required, and

then click Save to capture the entire report. Click Finish to complete the data-tier application

extraction process.


Installing a New DAC Instance with the Deploy

Data-Tier Application Wizard


After the DAC package has been created using the data-tier application project template

in Visual Studio 2010, the Extract Data-Tier Application Wizard in SQL Server Management

Studio, or Windows PowerShell commands, the next step is to deploy the DAC package to

a Database Engine instance running SQL Server 2008 R2. This can be achieved by using the

Deploy Data-Tier Application Wizard located in SQL Server Management Studio.


During the deployment process, the wizard registers a DAC instance by storing the DAC

definition in the msdb system database, creates the new database, and then populates the

database with all the database objects defined in the DAC. If a DAC is installed on a managed

instance of the Database Engine, the Data-Tier Application is monitored by the SQL Server Utility.

The DAC can be viewed in the Deployed Data-Tier Applications node of the Management

Studio Utility Explorer and reported in the Deployed Data-Tier Applications details page.


NOTE Data-tier applications can be deployed only on Database Engine instances of SQL

Server running SQL Server 2008 R2. Unfortunately, SQL Server 2008, SQL Server 2005, and

SQL Server 2000 are not supported when you are deploying data-tier applications. However,

upcoming SQL Server cumulative updates or service packs will include functionality

for down-level support.


Follow these steps to deploy a DAC package to an existing SQL Server 2008 R2 Database

Engine instance:


1. In Object Explorer, connect to the SQL Server instance in which you plan to deploy the

Data-Tier Application.


2. Expand the SQL Server instance, and then expand the Management folder.


3. Right-click the Data-Tier Applications node, and then select Deploy Data-Tier Application

to invoke the Deploy Data-Tier Application Wizard.


4. Review the information in the Introduction page, and then click Next to begin the

deployment process. Select the Do Not Show This Page Again check box if you do not

want the Introduction page displayed in the future when using the wizard.


5. On the Select Package page, specify the DAC package you want to deploy. Alternatively,

use the Browse button to specify the location for the DAC package.


6. When the DAC package is selected, verify the DAC details, such as the application

name, version number, and description in the read-only text boxes, as shown in Figure

3-7. Click Next to continue.


FIGURE 3-7 Specifying a DAC package to deploy with the Deploy Data-Tier Application Wizard


NOTE If a database with the same name already exists on the instance of SQL Server,

the wizard cannot proceed.


7. The wizard then analyzes the DAC package to ensure that it is valid. If the DAC package

is valid, the Update Configuration page is automatically invoked. Otherwise, an error is

displayed. You need to address the error(s) and start over again.


8. On the Update Configuration page, specify the database deployment properties. The

options include


¦ Name Specify the name of the deployed DAC and database.


¦ Data File Path Accept the default location or use the Browse button to specify

the location and path where the data file will reside.


¦ Log File Path Accept the default location or use the Browse button to specify the

location and path where the transaction log file will reside.


9. The next page includes a summary of the settings that are used to deploy the data-tier

application. Review the information displayed in the Summary page and DAC properties

tree to ensure that the actions taken are correct, and then click Next to continue.


10. The Deploy DAC page, shown in Figure 3-8, includes results such as success or failure

based on each action performed during the deployment process. These actions include

preparing system tables in msdb, preparing deployment scripts, creating the database,

creating schema objects affiliated with the database, renaming the database, and registering

the DAC in msdb. Review the results for every action to confirm success. You

can also click Save Report to capture the entire report. Then click Finish to complete

the deployment.


FIGURE 3-8 Viewing the deployment and results page associated with deploying the DAC


NOTE Throughout this chapter, you can also use Windows PowerShell scripts in conjunction

with data-tier applications to do many of the tasks discussed, such as


¦ Creating data-tier applications.


¦ Creating server objects.


¦ Loading DAC packages from a file.


¦ Upgrading data-tier applications.


¦ Deleting data-tier applications.


If you are interested in learning more about building Windows PowerShell scripts for

data-tier applications, you can find more information in the white paper “Data-tier

Applications in SQL Server 2008 R2″ at http://go.microsoft.com/fwlink/?LinkID=183214.


Registering a Data-Tier Application


There may be situations in which a database administrator needs to create a data-tier application

based on an existing database and then register and store the newly created DAC definition

for the database in the msdb system database. This execution, often referred to as creating

a DAC in place, is achieved by using either the Register Data-Tier Application Wizard or

Windows PowerShell. Unlike the Extract Data-Tier Application Wizard, which creates a .dacpac

file from an existing database, the Register Data-Tier Application Wizard creates a DAC in place

by registering the DAC definition and metadata in the msdb system database. A DAC registration

can be performed only on a Database Engine instance running SQL Server 2008 R2.


Use the following steps to register a data-tier application from an existing database by using

the Register Data-Tier Application Wizard in Management Studio:


1. In Object Explorer, connect to a SQL Server instance containing the database you want

to register as a data-tier application.


2. Expand the SQL Server instance, and then expand the Databases folder.


3. Invoke the Register Data-Tier Application Wizard by right-clicking the desired database,

selecting Tasks, and then selecting Register As Data-Tier Application.


4. Review the information on the Introduction page, and then click Next to begin the

registration process. Select the Do Not Show This Page Again check box if you do not

want the Introduction page displayed in the future when using the wizard.


5. On the Set Properties page, complete the DAC properties by typing in the application

name, version, and description, as described here:


¦ Application name This refers to the name of the DAC. This value cannot be

altered and is always identical to the name of the database.


¦ Version The DAC version identification helps developers working in Visual Studio

identify the version in which they are currently working. In addition, creating a version

helps identify the version of the DAC package used during deployment. The

DAC version information is stored in the msdb database and can be viewed in SQL

Server Management Studio in the Data-Tier Applications node.


¦ Description This property is optional. Use it to describe the DAC. If this section

is completed, the information is saved in the msdb database under the Data-Tier

Applications node in Management Studio.


6. On the Validation And Summary page, review the information presented in the DAC

properties summary tree because these settings are used to register the specified DAC.

The wizard checks and validates SchemaName, ObjectName, and object dependencies,

and it confirms that the information is supported by the DAC. Review the summary. It

displays DAC object issues, DAC object warnings, and the DAC objects supported. If

there are no issues, click Next to continue. You can also click Save Report to capture

the entire report.


7. The Register DAC screen indicates whether or not the DAC was successfully registered

in the msdb system database. Review the success and failure of each action, and then

click Finish to conclude the registration process.


The data-tier application can now be viewed under the Data-Tier Applications node in SQL

Server Management Studio. Moreover, if a database resides on a utility-managed instance,

resource utilization associated with the data-tier application can be viewed in Utility Explorer

after you connect to a Utility Control Point.


Deleting a Data-Tier Application


Database administrators may encounter occasions when they need to delete a data-tier application

from an instance of SQL Server. This is accomplished by using the Delete Data-Tier Application

Wizard in SQL Server Management Studio. Database administrators should be aware that

they will be prompted by the wizard to choose one of three predefined options for handling

the database linked to the application before the DAC is deleted. The three options are


¦ Delete Registration This method keeps the associated database and login in

place while deleting the DAC metadata from the instance.


¦ Detach Database This method detaches the associated database and removes

the DAC metadata. Detaching the associated database means that although the

data files, log files, and logins remain in place, the database can no longer be referenced

by an instance of the Database Engine.


¦ Delete Database The DAC metadata and the associated database are dropped.

The data and log files are deleted. Logins are not removed.


To delete the DAC, follow these steps:


1. In Object Explorer, connect to a SQL Server instance containing the data-tier application

you plan to delete.


2. Expand the SQL Server instance, and then expand the Management folder.


3. Expand the Data-Tier Applications node, right-click the data-tier application you want

to delete, and then select Delete Data-Tier Application.


4. Review the information in the Introduction page, and then click Next to begin the deletion

process. Select the Do Not Show This Page Again check box if you do not want

the Introduction page displayed in the future when using the wizard.


5. On the Choose Method page, specify the method you want to use to delete the

data-tier application, as illustrated in Figure 3-9. The options are Delete Registration,

Detach Database, and Delete Database. Click Next to continue.


FIGURE 3-9 Choosing the method with which to delete the DAC with the Delete Data-Tier Application

Wizard


6. Review the information displayed in the Summary page, as shown in Figure 3-10.


FIGURE 3-10 Viewing the Summary page when deleting a DAC


Ensure that the application name, database name, and delete method are correct. If

the information is correct, click Next to continue.


7. On the Delete DAC page, take a moment to review the information. This page communicates

which actions failed or succeeded. Unsuccessful actions have a link next to

them in the Result column. Click the link for detailed information about the error. In

addition, you can click Save Report to save the results on the Delete DAC page to an

HTML file. Click Finish to complete the deletion process and close the wizard.


Upgrading a Data-Tier Application


Let us recall the past for a moment, when updating changes to existing database schemas

and database applications was a noticeably challenging task. Database administrators usually

created scripts that included the new or updated database schema changes to be deployed.

The other option was to use third-party tools. Both processes could be expensive, time

consuming, and challenging to manage from a release or build perspective. Today, with SQL

Server 2008 R2, database administrators and developers can upgrade their existing deployed

data-tier applications to a new version of the DAC by simply building a new DAC package that

contains the new or updated schema and properties.


The upgrade can be accomplished by using Windows PowerShell commands or the Upgrade

Data-Tier Application Wizard in SQL Server Management Studio. The tools are intended

to upgrade a deployed DAC to a different version of the same application. For example,

an organization may want to upgrade the Accounting DAC from version 1.0 to version 2.0.

The upgrade wizard first preserves the database that will be upgraded by making a copy of

it. It then creates a new database that includes the schema and objects of the new version of

the DAC. The original database’s mode is then set to read-only, and the data is copied to the

new version. After the data transfer is complete, the new DAC assumes the original database

name. The renamed DAC remains on the SQL Server instance.


There are a few actions that data-tier developers and database administrators should

always perform before a data-tier application upgrade. First, the schema associated with the

original DAC should be compared to the new DAC. Second, database administrators must

confirm that the amount of data held in the existing DAC does not exceed the size limit of the

new DAC database. To upgrade a data-tier application by using the Upgrade Data-Tier Application

Wizard, follow these steps:


1. In Object Explorer, connect to a SQL Server instance containing the DAC you want to

upgrade.


2. Expand the SQL Server instance, and then expand the Management folder.


3. Expand the data-tier applications tree and select the data-tier application that you

want to upgrade.


4. Right-click the data-tier application, and select Upgrade Data-Tier Application. This

starts the Upgrade Data-Tier Application Wizard.


5. Review the information on the Introduction page, and then click Next to begin the upgrade

process. Select the Do Not Show This Page Again check box if you do not want

the Introduction page displayed in the future when using the wizard.


6. On the Select Package page, specify the DAC package that contains the new DAC version

to upgrade to. Alternatively, you can use the Browse button to specify the location of the

DAC package. When the DAC package is selected, you can verify the DAC details, such as

the application name, version number, and description in the read-only text boxes.


IMPORTANT Ensure that the DAC package and the original DAC have the same name.


7. When invoked, the Detect Change page starts off by displaying a progress bar while the

wizard verifies differences between the current schema of the database and the objects

in the DAC definition. The change detection results indicate whether the database objects

have changed or remain the same. If the database has changed, you are warned that

there may be data loss if you proceed with the upgrade, as illustrated in Figure 3-11.

Select the Proceed Despite Possible Loss Of Changes check box, and click Next to continue.


FIGURE 3-11 The Detect Change page of the Upgrade Data-Tier Application Wizard


NOTE If the database has changed, it is a best practice to review the potential data

losses before you proceed and verify that this is the outcome you want for the upgraded

database. However, the original database is still preserved, renamed, and maintained

on the SQL Server instance. Any data changes can be migrated from the original database

to the new database after the upgrade is complete.


8. The next page includes a summary of the settings that will be used to upgrade the

data-tier application. Review the information displayed in the Summary page and the

DAC properties tree to ensure that the actions to be taken are correct, and then click

Next to continue.


9. The Upgrade DAC page, shown in Figure 3-12, includes results, such as the success

or failure of each action performed during the upgrade process. Some of the actions

tested include


¦ Validating the upgrade.


¦ Preparing system tables in msdb.


¦ Preparing the deployment script.


¦ Creating the new database.


¦ Creating schema objects in the database.


¦ Setting the source database as read-only.


¦ Disconnecting users from the existing source database.


¦ Preparing scripts to copy data from the database.


¦ Disabling constraints on the database.


¦ Setting the database to read/write.


¦ Renaming the database.


¦ Upgrading the DAC metadata in msdb to reflect the new DAC version.


Review the result for every action. You can also click Save Report to capture the entire

report. Then click Finish to complete the upgrade.


FIGURE 3-12 Reviewing the result information on the Upgrade DAC page


NOTE Data-tier applications are a large and intricate subject. See the following

sources for more information:


¦ “Designing and Implementing Data-tier Applications” at http://msdn.microsoft.com

/en-us/library/ee210546(SQL.105).aspx


¦ “Creating and Managing Data-tier Applications” at http://msdn.microsoft.com

/en-us/library/ee361996(VS.100).aspx


¦ Tutorials at http://msdn.microsoft.com/en-us/library/ee210554(SQL.105).aspx


¦ “Data-tier Applications in SQL Server 2008 R2” white paper at http://go.microsoft.com

/fwlink/?LinkID=183214


63


C H A P T E R 4


High Availability and

Virtualization Enhancements


Microsoft SQL Server 2008 R2 delivers several enhancements in the areas of high

availability and virtualization. Many of the enhancements are affiliated with the

Windows Server 2008 R2 operating system and the Hyper-V platform. Windows Server

2008 R2 builds on the successes and foundation of Windows Server 2008 by expanding

on the existing high availability technologies, while adding new features that allow

for maximum availability and reliability for SQL Server 2008 R2 implementations. This

chapter discusses the enhancements to high availability that significantly contribute to

the capabilities of SQL Server 2008 R2 in both physical and virtual environments.


Enhancements to High Availability with

Windows Server 2008 R2


In the following list are a few of the improvements that will appeal to SQL Server and

Windows Server professionals looking to gain maximum high availability within their

database infrastructures.


¦ Hot add CPU and memory When using SQL Server 2008 R2 in conjunction

with Windows Server 2008 R2, database administrators can upgrade hardware

online by dynamically adding processors and memory to a system that supports

dynamic hardware partitioning. This is a very convenient feature for organizations

that cannot endure downtime for SQL Server systems running in mission-critical

environments.


¦ Failover clustering Greater high availability is achievable for SQL Server R2 with

failover clustering on Windows Server 2008 R2. Windows Server 2008 R2 enhances

the failover cluster installation experience by increasing the number of validation

tests within the Cluster Validation Wizard. Moreover, Windows Server 2008 R2

introduces a Best Practices Analyzer tool to help database administrators reduce best

practice violations. Similar to its predecessor, Windows Server 2008 R2 continues to

supports up to 16 nodes within a failover cluster and organizations can also protect

their applications from site failures with SQL Server multi-site failover cluster support

by using stretched VLANs built on Windows Server support for multi-site clusters.


64 CHAPTER 4 High Availability and Virtualization Enhancements


¦ Windows Server 2008 R2 Hyper-V The Hyper-V virtualization technology improvements

in Windows Server 2008 R2 were the most sought-after and anticipated

enhancements for Windows Server 2008 R2. It is now possible to virtualize heavy SQL

Server workloads because Windows Server 2008 R2 scales far beyond its predecessors.

In addition, database administrators can achieve increased virtualization availability by

leveraging new technologies, such as Clustered Shared Volumes (CSV) and Live Migration,

both of which are included in Windows Server 2008 R2. Guest clustering with SQL

Server 2008 R2 in Windows Server 2008 R2 Hyper-V is also supported.


¦ Live Migration and Hyper-V By leveraging Live Migration and CSV—two new

technologies included with Hyper-V and failover clustering on Windows Server 2008

R2—it is possible to move virtual machines between Hyper-V hosts within a failover

cluster without downtime. It is worth noting that CSV and Live Migration are independent

technologies; CSV is not required for Live Migration.


¦ Cluster Shared Volumes (CSV) CSV enables multiple Windows servers running

Hyper-V to access Storage Area Network (SAN) storage using a single consistent

namespace for all volumes on all hosts. This provides the foundation for Live Migration

and allows for the movement of virtual machines between Hyper-V hosts.


¦ Dynamic virtual machine (VM) storage It is possible to add or remove virtual

hard disk (VHD) files and pass-through disks while a VM is running. Support for hot

plugging and hot removal of storage is based on Hyper-V. This is very handy when you

are working with dynamic SQL Server 2008 R2 storage workloads, which are continuously

evolving.


¦ Second Level Address Translation (SLAT) Enhanced processor support and

memory management can be achieved with SLAT, which is a new feature supported

with Hyper-V in Windows Server 2008 R2. SLAT leverages Intel Virtualization Technology

(VT) Extended Page Tables (EPT) and AMD-V Rapid Virtualization Indexing (RVI)

technology in an effort to reduce the overhead incurred during mapping of a guest

virtual address to a physical address for virtual machines. This significantly reduces

hypervisor CPU time and saves memory for each VM, allowing the physical computer

to do more work while utilizing fewer system resources.


Failover Clustering with Windows Server 2008 R2


If you’re unfamiliar with failover clustering, don’t stop reading to run out and purchase a book

on the topic—this section begins with an overview of failover clustering. It may surprise some

readers to know that SQL Server failover clustering has been available since Microsoft SQL

Server 7.0. Back in those days, failover clustering proved to be quite a challenge to set up. It

was necessary to install multiple Microsoft products to form the Microsoft cluster environment,


Failover Clustering with Windows Server 2008 R2 CHAPTER 4 65


including Internet Information Services (IIS), Cluster Server, SQL Server 7.0 Enterprise Edition,

Microsoft Distributed Transaction Coordinator (MSDTC) 2.0, and sometimes the Windows NT

4.0 Option Pack. Moreover, the hardware support, driver support, and documentation were

not as forthcoming as they are today. Many IT organizations came to believe that failover

clustering was a difficult technology to install and maintain. That has all changed, thanks to the

efforts of the SQL Server and Failover Clustering product groups at Microsoft. Today, forming a

cluster with SQL Server 2008 R2 on Windows Server 2008 R2 is very easy. In addition, the two

technologies combined provide maximum availability compared to previous versions, especially

for database administrators who want to virtualize their SQL Server workloads.


Now that you know some of the history behind failover clustering, it’s time to take a

closer look into what failover clustering is all about and what it means for organizations and

database administrators. A SQL Server failover cluster is built on the foundation of a Windows

failover cluster, while providing high availability and protecting the whole instance of SQL

Server in the event of a server failure. Failover clustering allows organizations to meet their

high availability uptime requirements through redundancy in their SQL Server infrastructure

by eliminating single points of failure for the clustered application. The server that is used to

form a cluster can be either physical or virtual. The next section introduces the different types

of failover clusters that can be achieved with these two products (SQL Server 2008 R2 and

Windows Server 2008 R2), which work very well with one another.


Traditional Failover Clustering


The traditional SQL Server failover cluster has been around for years. With a traditional

failover cluster, there are two or more nodes (servers) connected to shared storage. A quorum

is formed between all nodes in the failover cluster, and this quorum determines the health

and number of failures the failover cluster can sustain. Communication between cluster nodes

is required for cluster operations and is achieved by using two or more independent networks

that connect the nodes of a cluster to avoid a single point of failure. SQL Server 2008 R2 is

installed on all nodes within a failover cluster. If a node in the cluster fails, the SQL Server

instance automatically fails over to a surviving node within the failover cluster. Note that the

failover is seamless from an end-user or application perspective. Like its predecessor, SQL

Server 2008 R2 delivers single-instance and multiple-instance failover cluster configurations.

In addition, SQL Server 2008 R2 on Windows Server 2008 R2 supports up to 16 nodes and a

maximum of 23 instances within a failover cluster due to the drive letter limitation.


IMPORTANT When you are configuring a cluster, make sure to connect the nodes by

more than one network; otherwise Microsoft Product Support Services does not support

the implementation. In addition, it is a best practice to always use more than one network.


Figure 4-1 illustrates a two-node single-instance failover cluster running SQL Server on

Windows Server 2008 R2.


Public Network

Heartbeat Network

SQL Cluster\Instance01

SAN Storage

Node1 Node2


FIGURE 4-1 A two-node single-instance failover cluster


Figure 4-2 illustrates a multiple-instance failover cluster running SQL Server on Windows

Server 2008 R2.


Public Network

Heartbeat Network

SQL Cluster\Instance01

SAN Storage

Node1 Node2

SQL Cluster\Instance02


FIGURE 4-2 A two-node multiple-instance failover cluster


Guest Failover Clustering


In the past, physical servers were usually affiliated with the nodes in a failover cluster. Today,

virtualization technologies make it possible to form a cluster with each node being a guest

operating system on virtual servers. This is known as guest failover clustering. To achieve a

guest failover cluster, you must have a quorum, a public network, a private network, and

shared storage; however, instead of using physical servers for each node in the SQL Server

failover cluster, each node is virtualized through Hyper-V. Organizations taking advantage of

guest failover clustering with SQL Server 2008 R2 must have the physical host running Hyper-V

on Windows Server 2008 R2, and the configurations must be certified through the Server Virtualization

Validation Program (SVVP). Likewise, the guest operating system must be Windows

Server 2008 R2, and the virtualization environment must meet the requirements of Windows

Server 2008 R2 failover clustering, including passing the Validate a Configuration tests.


NOTE When implementing failover clusters, you can combine both physical and virtual

nodes in a single failover cluster solution.


Figure 4-3 illustrates a multiple-instance guest failover cluster running SQL Server 2008

R2 on Windows Server 2008 R2. SQLNode1 is a virtual machine running on the server called

Hyper-V01, which is a Hyper-V host, and SQLNode2 is a virtual machine running on the

Hyper-V02 Hyper-V host.


Public Network

Heartbeat Network

SQL Cluster\Instance01

SAN Storage

SQL Node1 SQL Node2

SQL Cluster\Instance02

Hyper-V01 Hyper-V02

V V

P P

P = Physical Server

V = Virtual Server


FIGURE 4-3 A two-node guest failover cluster


NOTE Guest clustering is also supported when Hyper-V is on Windows Server 2008.

However, Windows Server 2008 R2 provides Live Migration for moving virtual machines

between physical hosts. This is much more beneficial for a virtualized environment running

SQL Server 2008 R2.


Real World


When you use guest failover clustering, make sure that the virtualized guest

operating systems used for the nodes in the guest failover cluster are not

on the same physical Hyper-V host. If this situation exists, you have a physical host

running Hyper-V, which means that you have created a single point of failure. For

example, if a single physical host running all of the guest operating systems suddenly

failed, all the nodes associated with the guest failover cluster would no longer

be available, ultimately causing the whole SQL Server failover cluster instance to fail.

This could be catastrophic in a mission-critical production environment. This problem

can be avoided, however, if you use multiple Hyper-V hosts and Live Migration,

and ensure that each guest operating system is running on a separate Hyper-V host.


Enhancements to the Validate A Configuration Wizard


As mentioned earlier in this chapter, organizations in the past found it difficult to implement a

SQL Server failover cluster. One thing that clearly stood out was the need for an intuitive tool

that could verify whether or not an organization’s configuration met the failover clustering

prerequisites. This issue was addressed with the introduction of Windows Server 2008, which

offered for the first time a tool called the Validate A Configuration Wizard.


Database administrators and Windows administrators used this tool to conduct validation

tests to determine whether servers, settings, networks, and storage affiliated with a failover

cluster were set up correctly. This tool was also used to verify whether or not prerequisite tasks

were met and to confirm that the hardware supported a successful cluster implementation.


The Validate A Configuration Wizard tool included with Windows Server 2008 R2 still

delivers inventory, network, storage, and system configuration tests. In addition, the Failover

Clustering product team made enhancements to the Validate A Configuration Wizard tool

that further improve the testing ability of this tool. Some of the enrichments include the following

options:


¦ Cluster Configuration


• List Cluster Core Groups


• List Cluster Network Information


• List Cluster Resources


• List Cluster Volumes


• List Cluster Services And Applications


• Validate Quorum Configuration


• Validate Resource Status


• Validate Service Principal Name


• Validate Volume Consistency


¦ Network


• List Network Binding Order


• Validate Multiple Subnet Properties


¦ System Configuration


• Validate Cluster Service And Driver Settings


• Validate Memory Dump Settings


• Validate System Drive Variable


NOTE The wizard tests configurations and also lists information. See “Failover Cluster

Step-by-Step Guide: Validating Hardware for a Failover Cluster,” a Knowledge Base

article that describes each test in detail, at http://technet.microsoft.com/en-us/library

/cc732035(WS.10).aspx.


Running the Validate A Configuration Wizard


Prior to installing a failover cluster for SQL Server 2008 R2 on Windows Server 2008 R2, administrators

should run the Validate A Configuration Wizard tool by following these steps:


1. Ensure that the failover clustering feature is installed on all the nodes associated with

the new cluster being validated.


2. On one of the nodes of the cluster, open the Failover Cluster Management snap-in.


3. Review the information on the Before You Begin page, and then click Next. You can

select the option to hide this page when using the wizard in the future.


4. On the Select Servers Or A Cluster page, in the Enter Name field, type either the host

name or the fully qualified domain name (FQDN) of a node in the cluster. Alternatively,

you can click the Browse button and select one or more nodes in the cluster. Click Next

to continue.


5. On the Testing Options page, select Run All Tests or Run Only Test I Select, and then

click Next. It is recommended that you choose Run All Tests when using the wizard for

the first time. The tests are organized into Inventory, Network, Storage, and System

Configuration categories.


6. On the Confirmation page, review the details for each test, and then click Next to

begin the validation process. While the validation process is running, status information

is continually displayed on the Validating page until all tests are complete. After all

tests are complete, the Summary page is displayed, as shown in Figure 4-4. It includes

the results of the validation tests and numerous details about the information collected

during each test. Any errors or warnings listed in the validation results should

be looked into and rectified as soon as possible. It is also possible to proceed without

fixing errors; however, the failover cluster will not be supported by Microsoft.


FIGURE 4-4 The Failover Cluster Validation Report


7. Click View Report to observe the report in the default Web browser. The report is displayed

in Web archive (.mht) format. Click Finish to close the wizard.


NOTE The Validate A Configuration Wizard is quite useful for troubleshooting a failover

cluster. Administrators who run tests relating to the specific issues they are experiencing

are likely to yield valuable information and answers on how to address their issues. For example,

if you are experiencing issues with Multipath I/O (MPIO), a specific driver, or shared

storage after a successful implementation of a failover cluster, the wizard would identify

the problem for quick resolution.


The Windows Server 2008 R2 Best Practices Analyzer


Another tool available in Windows Server 2008 R2 is a server management tool referred to

as the Best Practices Analyzer (BPA). The BPA determines how compliant a server role is by

comparing it against best practices in eight categories: security, performance, configuration,

policy, operation, pre-deployment, post-deployment, and BPA prerequisites. In each category,

the effectiveness, trustworthiness, and reliability of a role is taken into consideration. Each

role measured by the BPA will be assigned one of the following three severity levels: Noncompliant,

Compliant, or Warning. A server role not in agreement with best practice guidelines

is labeled as Noncompliant, and a role in agreement with best practice guidelines is

labeled as Compliant. Server roles inherit the Warning severity level when a BPA scan detects

compliance but also a risk that the server role will fall out of compliance.


Database administrators find this tool instrumental in achieving success with their failover

cluster setup. First, the Windows Server 2008 R2 BPA can help database administrators reduce

best-practice violations by scanning one or more roles installed on a server running Windows

Server 2008 R2. On completion, the BPA creates a report that itemizes every best-practice

violation, from the most severe to the least severe. It is also possible to customize a BPA

report. For example, database administrators can omit results they deem unnecessary or

unimportant. Last, administrators can also perform BPA tasks by using either the Server Manager

GUI or Windows PowerShell cmdlets.


Running the Best Practices Analyzer


The BPA is installed by default on all editions of Windows Server 2008 R2 except the Server

Core installation option. If BPA is installed on your edition, run it in Server Manager. Follow

these steps:


1. Click Start, click Administrative Tools, and then select Server Manager.


2. Open Roles from the navigation pane. Next, select the role to be scanned with BPA.


3. Open the Summary section in the details pane. Next, open the Best Practices Analyzer

area.


4. Click Scan This Role to initiate the scan.


5. When the scan is complete, review the results in the Best Practices Analyzer results

window.


SQL Server 2008 R2 Virtualization and Hyper-V


Virtualization is one of the hottest topics of discussion in almost every SQL Server architecture

design session or executive briefing session, mainly because organizations are beginning to

understand the immediate and long-term benefits virtualization can offer them. SQL Server

virtualization not only promises to be very positive and rewarding from an environmental

perspective—reducing power and thermal costs which translate to green IT—it also promises

to help organizations achieve strategic business objectives and consolidation goals, including

lower hardware costs, smaller data centers, and less management associated with SQL Server.


As a result, increasing numbers of organizations are showing interest in virtualizing their

SQL Server workloads, including their test, staging, and even production environments. This

trend toward virtualization has undoubtedly become stronger with the release of Windows

Server 2008 R2, which includes Live Migration and Cluster Shared Volumes (CSV). By leveraging

Live Migration and CSV, organizations can achieve high availability for SQL Server virtual

machines (VMs). In addition, it is possible to move virtualized SQL Server 2008 R2 guest operating

systems between physical Hyper-V hosts without any perceived downtime.


Live Migration Support Through CSV


Live Migration is a new Hyper-V feature in Windows Server 2008 R2 that is used to increase

high availability of SQL Server VMs. By leveraging the new Live Migration feature, organizations

can transparently move SQL Server 2008 R2 VMs from one Hyper-V physical host to

another Hyper-V physical host within the same cluster, without disrupting the services of the

guest operating system or SQL Server application running on the VM. This is achieved via an

intricate process. First, all VM memory pages are transferred from the source Hyper-V physical

host to the destination Hyper-V physical host. Second, any VM modifications to the VMs

memory pages on the source Hyper-V physical host are tracked. These tracked and modified

pages are transferred to the physical Hyper-V target computer. Third, the storage handles for

the VMs’ VHD files are moved to the Hyper-V target computer. Finally, the destination VM is

brought online.


The Live Migration feature is supported only when Hyper-V is run on Windows Server

2008 R2. Live Migration can take advantage of the new CSV feature within failover clustering

in Windows Server 2008 R2. The CSVs let multiple nodes in the same failover cluster concurrently

access the same logical unit number (LUN). Equally important, because a Hyper-V

cluster must be formed as a prerequisite task, Live Migration requires the failover clustering

feature to be added and configured on all of the servers running Hyper-V. In addition, the

Hyper-V cluster hosts require shared storage for the cluster nodes. This can be achieved by

either an iSCSI, Serial Attached SCSI (SAS) or Fibre Channel Storage Area Network (SAN).


Figure 4-5 illustrates a four-node Hyper-V failover cluster with two CSVs and eight SQL

Server guest operating systems. With Live Migration, running SQL Server VMs can be seamlessly

moved between Hyper-V hosts.


Hyper-V01 Hyper-V02 Hyper-V03 Hyper-V04

C:\ClusterShares\Volume1

VHD VHD VHD VHD

C:\ClusterShares\Volume2

VHD VHD VHD VHD


FIGURE 4-5 A Hyper-V cluster and Live Migration


Windows Server 2008 R2 Hyper-V System Requirements


Table 4-1 below outlines the minimum requirements, along with the recommended system

configuration, for using Hyper-V on Windows Server 2008 R2.


TABLE 4-1 Hyper-V System Requirements


MINIMUM


RECOMMENDED


Processor


x64-compatible processor with

Intel VT or AMD-V technology

enabled


CPU speed


1.4 GHz


2.0 GHz or faster—additional CPUs

are required for each guest operating

system


RAM


1 GB—additional RAM is required

for each guest operating system


2 GB or higher—additional RAM is

required for each guest operating

system


Disk space


8 GB—additional disk space is

needed for each guest operating

system


20 GB or higher—additional disk

space is needed for each guest

operating system


NOTE System requirements vary based on an organization’s virtualization requirements.

Organizations should size their workloads to ensure that the Hyper-V hosts can successfully

accommodate all of the virtual servers and associated workloads from a CPU, memory, and

disk perspective.


Practical Uses for Hyper-V and SQL Server 2008 R2


Hyper-V on Windows Server 2008 R2 is capable of accomplishing almost the same successes

as dedicated servers, including the same kinds of peak load handling and security. Knowing

this, you might wonder when Hyper-V on Windows Server 2008 R2 should be employed from

a SQL Server 2008 R2 perspective. Hyper-V on Windows Server 2008 R2 can be utilized for


¦ Consolidating SQL Server databases or instances on a single physical server.


¦ Virtualizing SQL Server infrastructure workloads with low utilization.


¦ Achieving high availability for SQL Server VMs by using Live Migration or guest clustering.


¦ Maintaining different versions of SQL Server and the operating system on the same

physical server.


¦ Virtualizing test and development environments to reduce total cost of ownership.


¦ Reducing licensing, power, and thermal costs.


¦ Extending physical space when the data center lacks it.


¦ Repurposing and extending the life of old SQL Server hardware by conducting a

physical-to-virtual (P2V) migration.


¦ Migrating legacy SQL Server editions off hardware that is old and that has expired

warranties.


¦ Generating self-contained SQL Server environments, also known as sandboxes.


¦ Taking advantage of the rapid deployment capabilities of SQL Server VMs by using

Microsoft System Center Virtual Machine Manager (VMM) 2008 R2.


¦ Storing and managing SQL Server VMs in VMM libraries.


By using virtual servers, organizations can take advantage of powerful features such as

multi-core technology, and they can achieve better handling of disk access and greater memory

support. In addition, Hyper-V improves scalability and performance for a SQL Server VM.


NOTE The Microsoft Assessment and Planning Toolkit can be used to identify whether or

not an organization’s SQL Server systems are good candidates for virtualization. The toolkit

also includes tools for SQL Server inventory, assessments, and intuitive reporting. A download

of the Microsoft Assessment and Planning Toolkit is available on the Microsoft Download

Center at http://www.microsoft.com/downloads/details.aspx?FamilyID=67240b76-

3148-4e49-943d-4d9ea7f77730&displaylang=en.


Implementing Live Migration for SQL Server 2008 R2


Follow these steps to take advantage of Live Migration for SQL Server 2008 R2 VMs:


1. Ensure that the hardware, software, drivers, and components are supported by

Microsoft and Windows Server 2008 R2.


2. Set up the hardware, shared storage, and networks as recommended in the failover

cluster deployment guides.


NOTE “Hyper-V: Using Hyper-V and Failover Clustering,” the TechNet article at the

following link, includes step-by-step instructions on how to implement Hyper-V and

failover clustering: http://technet.microsoft.com/en-us/library/cc732181(WS.10).aspx.


In addition to step-by-step instructions on how to implement Hyper-V and failover

clustering, this page also gives information on the requirements for using Hyper-V and

failover clustering, which might be helpful because, the steps in the following sections

assume that a Hyper-V cluster is already in place.


3. For all nodes that you are including in the failover cluster, install Windows Server 2008 R2

(full installation or Server Core installation).


4. Enable the Hyper-V role on each node of the failover cluster.


5. Install the Failover Clustering feature on each node of the failover cluster.


6. Validate the cluster configuration by using the Validate A Configuration Wizard tool

located in Failover Cluster Manager.


7. Configure CSV.


8. Create a SQL Server VM with Hyper-V.


9. Set up a SQL Server VM for Live Migration.


10. Configure cluster networks for Live Migration.


Enabling CSV


Assuming that the Hyper-V cluster has already been built, the next step is enabling CSV in

Failover Cluster Manager. Follow the steps in this section to enable CSV on a Hyper-V failover

cluster running on Windows Server 2008 R2.


1. On a server in the Hyper-V failover cluster, click Start, click Administrator Tools, and

then click Failover Cluster Manager.


2. In the Failover Cluster Manager snap-in, verify that CSV is present for the cluster that is

being enabled. If it is not in the console tree, right-click Failover Cluster Manager, click

Manage A Cluster, and then select or specify the cluster to be configured.


3. Right-click the failover cluster, and then choose Enable Cluster Shared Volumes.


4. The Enable Cluster Shared Volumes dialog box opens. Read and accept the terms and

restrictions associated with CSV. Then click OK.


5. In this step, you add storage to the CSV. You can do this either by right-clicking Cluster

Shared Volumes and selecting Add Storage or by selecting Add Storage under Actions.


6. In the Add Storage dialog box, select from the list of available disks, and then click OK.


7. After the disk or disks selected have been added, they appear in the Results pane for

Cluster Shared Volumes.


NOTE SystemDrive\ClusterStorage is the CSV storage location for each node associated

with the failover cluster. Folders for each volume added to the CSV are stored in this

location. Administrators needing to view the list of volumes can do so in Failover Cluster

Manager.


Creating a SQL Server VM with Hyper-V


Before leveraging Live Migration, organizations must follow the instructions in this section to

create a SQL Server VM with Hyper-V in Windows Server 2008 R2.


1. Ensure that the Hyper-V role is installed on the server that you use to create the SQL

Server 2008 R2 VM.


2. Click Start, click Administrative Tools, and then click Hyper-V Manager.


3. In the Action pane, click New, and then click Virtual Machine. The New Virtual Machine

Wizard starts.


4. Read the information on the Before You Begin page, and then click Next. You can

select the option to hide this page on all future uses of the wizard.


5. On the Specify Name And Location page, enter the name of the SQL Server VM and

specify where it will be stored. For example, the name SQLServer2008R2-VM01 and the

VM can be stored on Cluster Shared Volume 1, as displayed in Figure 4-6.


FIGURE 4-6 The Specify Name And Location Screen when a new virtual machine is being created


NOTE If a folder is not selected, the SQL Server VM is stored in the default folder configured

for the Hyper-V server.


6. On the Memory page, enter the amount of memory to be allocated to the SQL Server’s

VM guest operating system. Click Next.


NOTE With SQL Server 2008 R2, it is recommended that you have 2.048 GB or more of

RAM, whereas with Windows Server 2008 R2 a minimum of 512 MB of RAM is recommended.

Remember to ensure that SQL Server workloads are sized accordingly, and

remember to take into consideration the amount of RAM required for each SQL Server

VM. Also, remember that it is possible to shut down the guest operating system and

add more RAM to the virtual machine if necessary.


7. On the Networking page, connect the network adapter to an existing virtual network

by selecting the appropriate network adapter from the menu. Click Next to continue.


8. On the Connect Virtual Hard Disk page, as shown in Figure 4-7, specify the name, location,

and size to create a virtual hard disk so that you can install an operating system.

Click Next to continue.


FIGURE 4-7 The Connect Virtual Hard Disk page when a new virtual machine is being created


9. On the Installation Options page, choose a method to install the operating system. The

options include


¦ Installing an operating system from a boot CD/DVD-ROM.


¦ Installing an operating system from a boot floppy disk.


¦ Installing an operating system from a network-based installation server.


¦ Installing an operating system at a later time.


After choosing the method, click Next to continue.


10. Review the selections in the Completing The New Virtual Machine Wizard, and then

click Finish.


The new VM is created; however, it is in an offline state.


11. From the Virtual Machines section of the results pane in Hyper-V Manager, rightclick

the name of the SQL Server VM you just created, and click Connect. The Virtual

Machine Connection tool opens.


12. In the Action menu in the Virtual Machine Connection window, click Start.


13. Follow the prompts to install the Windows Server 2008 R2 operating system.


14. When the operating system installation is complete, install SQL Server 2008 R2.


Real World


After an operating system is set up, best practice guidelines recommend the

installation of the Hyper-V Integration Services tools for every VM that was

created. The Hyper-V Integration Services tool provides virtual server client (VSC)

code, which ultimately increases Hyper-V performance of the VM from an I/O,

memory management, and network performance perspective. Hyper-V Integration

Services is installed by connecting to the VM and selecting Insert The Integration

Services Setup Disk from the Action Menu of the Virtual Machine Connection window.

Click Install in the AutoPlay dialog box to install the tools.


Configuring a SQL Server VM for Live Migration


Organizations interested in using Live Migration need to set up a VM for Live Migration. This

is accomplished by reconfiguring the automatic start action for the VM and then preparing

the VM for high availability by using Failover Cluster Manager. The following steps illustrate

this series of actions in more detail:


1. Create a SQL Server 2008 R2 VM based on the steps in the previous section. Verify that

the VM is using CSV.


2. In Hyper-V Manager, under Virtual Machines, highlight the VM created in the previous

steps (SQLServer2008R2-VM01 in the example in this chapter). In the Action pane,

under the VM name, click Settings.


3. In the left pane, click Automatic Start Action.


4. Under Automatic Start Action, for the What Do You Want This Virtual Machine To Do

When The Physical Computer Starts? question, select Nothing, as shown in Figure 4-8.

Then click Apply and OK.


FIGURE 4-8 Configuring the Automatic Start Action Setting screen


5. Launch Failover Cluster Manager from Administrative Tools on the Start menu.


6. In the Failover Cluster Manager snap-in, if the cluster that will be configured is not displayed

in the console tree, right-click Failover Cluster Manager. Click Manage A Cluster,

and then select or specify the cluster.


7. If the console tree is collapsed, expand the tree under the cluster you want.


8. Click Services And Applications.


9. In the Action pane, click Configure A Service Or Application.


10. If the Before You Begin page of the High Availability Wizard appears, click Next.


11. On the Select Service Or Application page, shown in Figure 4-9, click Virtual Machine,

and then click Next.


FIGURE 4-9 Selecting the service and application for high availability


12. On the Select Virtual Machine page, shown in Figure 4-10, confirm the name of the VM

you plan to make highly available. In this example, SQLServer2008R2-VM01 is used.

Click Next.


FIGURE 4-10 Configuring a VM for high availability


NOTE To make a VM highly available, you must ensure that it is not running. It must

be either turned off or shut down.


13. Confirm the selection, and then click Next.


14. The wizard configures the VM for high availability and provides a summary. To view

the details of the configuration, click View Report. To close the wizard, click Finish.


15. To verify that the virtual machine is now highly available, look in one of two places in

the console tree:


¦ Expand Services And Applications, shown in Figure 4-11. The VM should be listed

under Services And Applications.


¦ Expand Nodes. Select the node on which the VM was created. The VM should be

listed under Services And Applications in the Results pane.


FIGURE 4-11 Verifying that the VM is now highly available


16. To bring the VM online, right-click it under Services And Applications, and then click

Start Virtual Machine. This action brings the VM online and starts it.


Initiating a Live Migration of a SQL Server VM


After an administrator has enabled CSV, created a SQL Server 2008 R2 VM, configured the

automatic start option, and made the VM highly available, it is time to initiate a live migration.

Perform the following steps to initiate Live Migration:


1. In the Failover Cluster Manager snap-in, if the cluster to be configured is not displayed

in the console tree, right-click Failover Cluster Manager.


2. Click Manage A Cluster, and then select or specify the cluster. Expand Nodes.


3. In the console tree located on the left side, select the node to which Live Migration will

move the clustered VM.


4. Right-click the VM resource that is displayed in the center pane, and then click Live

Migrate Virtual Machine To Another Node.


5. Select the node that the VM will be moved to in the migration, as shown in Figure 4-12.

After the migration is complete, the VM should be running on the node selected.


FIGURE 4-12 Initiating Live Migration for a SQL Server VM.


6. Verify that the VM successfully migrated to the node selected. The VM should be listed

under the new node in Current Owner.


85


C H A P T E R 5


Consolidation and Monitoring


Today’s competitive economy dictates that organizations reduce cost and improve

agility in their database environments. This means the large percentage of organizations

out there running underutilized Microsoft SQL Server installations must take control

of their environments in order to experience significant cost savings and increased

activity. Thankfully, enhancements in hardware and software technologies have unlocked

new opportunities to reduce costs through consolidation. Consolidation reduces the

number of physical servers in an organization’s environment, directly impacting costs in

numerous areas including, but not limited to hardware, administration, power consumption,

and licenses. Equally important, by leveraging the new SQL Server Utility feature

in Microsoft SQL Server 2008 R2, organizations can streamline consolidation efforts

because this feature provides database administrators (DBAs) with insight into resource

utilization through policy evaluation and historical analysis.


This chapter begins by describing the consolidation options available to DBAs. It then explains

how DBAs can take advantage of viewpoints and dashboards in the SQL Server Utility

to identify consolidation opportunities, which is done by monitoring resource utilization

and health state for SQL Server instances, databases, and deployed data-tier applications.


SQL Server Consolidation Strategies


The goal of SQL Server consolidation is to identify underutilized hardware and improve

utilization by choosing an appropriate consolidation strategy. With SQL Server, hardware

could be considered to be underutilized when workloads are using less than 30 percent

of server resources. However, underutilization thresholds vary based on the hardware

utilized for SQL Server and the organization. Some compelling reasons for organizations

to consolidate are to reduce costs, improve efficiency, address lack of physical space in

the data center, create more effective service levels, standardize, and centralize management.

Some common consolidation strategies organizations can apply are described in

the rest of this section.


86 CHAPTER 5 Consolidation and Monitoring


Consolidating Databases and Instances


A very common SQL Server consolidation strategy involves placing many databases on a single

instance of SQL Server. This approach offers organizations improved operations through

centralized management, standardization, and improved performance. For example,

multiple databases belonging to the same SQL Server instance facilitates shared memory

optimization, and database consolidation helps to reduce overhead due to fixed resource

costs per instance. There are some limitations with database-level consolidation, however. For

example, in this scenario, all databases share the same service account, maintain the same

global settings, and share a single tempdb database for processing temporary workloads.

Figure 5-1 shows many databases being consolidated onto a single physical host running one

instance of SQL Server.


SQLInstance01


FIGURE 5-1 Consolidating many databases onto a single physical host running one instance of SQL Server


Many times, it is not possible to consolidate all of your databases onto a single instance,

possibly because additional service isolation is required or a single instance cannot sustain

the workload of all of the databases. In addition, a single tempdb database could be a

performance bottleneck. Your organization might also find this scenario problematic if it has

requirements to maintain different service level agreements for each database, if there are

too many databases consolidated on the system, if databases need to be isolated for security

and regulatory compliance reasons, or if databases require different collation settings.


You can still consolidate databases if you have these types of requirements; however, you

may need more instances or physical hosts to support your consolidation needs. For example,

the diagram in Figure 5-2 illustrates the consolidation of many databases onto a single physical

host running three instances of SQL Server, whereas the diagram in Figure 5-3 represents

an alternative, in which many databases are consolidated onto many instances residing on

two separate physical hosts.


SQL Server Consolidation Strategies CHAPTER 5 87


SQLInstance01

SQLInstance02

SQLInstance03


FIGURE 5-2 Consolidating many databases onto a single physical host running three instances

of SQL Server


SQLInstance01

SQLInstance02

SQLInstance03


FIGURE 5-3 Consolidating many databases onto multiple physical hosts running multiple instances

of SQL Server


Consolidating SQL Server Through Virtualization


Another SQL Server consolidation strategy attracting interest is virtualization. Virtualization’s

growing popularity is based on many factors, including its ability to significantly reduce

total cost of ownership (TCO) and the number of physical servers within an infrastructure.

Benefits include the need for fewer physical servers, as well as lower licensing costs. At the

heart of all the excitement over virtualization is Live Migration. This new, built-in feature is

a Windows Server 2008 R2 Hyper-V enhancement. Live Migration increases high availability

and improves service by reducing planned outages. It allows DBAs to move SQL Server

virtual machines (VMs) between physical Hyper-V hosts without any perceived interruption in

service. Hyper-V on Windows Server 2008 R2 also allows for maximum scalability because it

supports up to 64 logical processors. As a result, it is possible to virtualize and consolidate numerous

SQL Server instances, databases, and workloads onto a single host. Another benefit is

that Live Migration allows an organization to not only completely isolate its operating system

with virtualization but also to host multiple editions of SQL Server while running both 32-bit


and 64-bit versions within a single host. In addition, physical SQL Servers can easily be virtualized

by using the physical-to-virtual (P2V) migration tool included with System Center Virtual

Machine Manager 2008 R2. Figure 5-4 illustrates a consolidation strategy in which many databases,

instances, and physical SQL Server systems are virtualized on a single Hyper-V host.


SQLInstance01

SQLInstance02

SQLInstance03

SQLInstance01

SQLInstance03

Server 1

Server 2

Server 3

Hyper-V host


FIGURE 5-4 Consolidating many databases, instances, and physical hosts with virtualization


No matter what consolidation strategy an organization adapts, the benefits are significant

without any sacrifice of scalability and overall performance. Now that the consolidation

strategies have been explained, it is time to explore how an organization can quickly recognize

whether its database environment is a candidate for consolidation and can ultimately

streamline its consolidation efforts by monitoring resource utilization.


Using the SQL Server Utility for Consolidation and

Monitoring


The SQL Server Utility is the center of operations for monitoring managed instances of SQL

Server, databases, and deployed data-tier applications. By using the dashboards and viewpoints

included in the SQL Server Utility, DBAs can proactively monitor and view resource

utilization, health state, and health policies for managed instances, databases, and deployed

data-tier applications at scale. The results obtained from monitoring allow DBAs to easily

identify consolidation candidates across an organization’s database environment. To experience

the dashboards and viewpoints yourself, launch the SQL Server Utility by following these steps:


IMPORTANT Before you can carry out these steps, you must have created a Utility

Control Point, and you must enroll at least one instance of SQL Server. For more information

on how to do this, see Chapter 2,”Multi-Server Administration.”


1. In SQL Server Management Studio, connect to the SQL Server 2008 R2 Database Engine

instance in which the UCP was created.


2. Launch Utility Explorer by clicking View and then selecting Utility Explorer.


3. In the Utility Explorer navigation pane, click the Connect To Utility icon.


4. In the Connect To Server dialog box, specify the SQL Server instance running the UCP,

select the type of authentication, and then click Connect.


5. Connection to a Utility Control Point is complete. Begin monitoring the health state

and resource utilization by viewing the dashboards and viewpoints.


Utility Explorer in SQL Server Management Studio provides a tree view that includes nodes

for monitoring and managing settings within the SQL Server Utility. The summary dashboard

is automatically displayed in the Utility Explorer Content pane when you connect to a UCP.

You can view additional dashboards and viewpoints by clicking the Managed Instances node

or the Deployed Data-Tier Applications node in the Utility Explorer navigation pane, as displayed

in Figure 5-5.


FIGURE 5-5 Utility Explorer and the navigation tree


The three main dashboards for monitoring and managing resource utilization and consolidation

efforts are discussed in the next sections. These dashboards and viewpoints are


¦ The SQL Server Utility dashboard.


¦ The Managed Instance viewpoint.


¦ The Data-Tier Applications viewpoint.


Using the SQL Server Utility Dashboard


The SQL Server Utility dashboard is the starting place for obtaining summary information

about managed instances of SQL Server and deployed data-tier applications in the SQL Server

Utility. The summary of the data, as illustrated in Figure 5-6, is sectioned into nine parts and

can be viewed in the Utility Explorer Content pane by clicking a Utility Control Point, which is

the top node in the Utility Explorer tree.


FIGURE 5-6 The SQL Server Utility dashboard


The SQL Server Utility dashboard includes the following information:


¦ Utility Summary Found in the center of the top row of the Utility Explorer Content

pane, this section is the first place to look. It displays the number of managed instances

of SQL Server and the number of deployed data-tier applications managed by the SQL

Server Utility. Use the Utility Summary section to gain quick insight into the number of

objects being managed by the SQL Server Utility. In Figure 5-6, there are 14 managed instances

and nine deployed data-tier applications displayed in the Utility Summary section.


NOTE After you have reviewed the summary information, it is recommended that

you analyze either the managed instances or deployed data-tier application section

in its entirety to gain a comprehensive understanding of its overall health status. For

example, the first set of the following bullets interpret the health of managed instances.

After managed instances are analyzed and explained, then the health of data-tier

applications is reviewed from beginning to end.


¦ Managed Instance Health This section is located in the top-left corner of the Utility

Explorer Content pane and summarizes the health status of all managed instances

of SQL Server in the SQL Server Utility. Health status is illustrated in a pie chart and has

four possible designations:


. Well Utilized The number of managed instances of SQL Server that are not violating

resource utilization policies is displayed.


. Overutilized A SQL Server instance is marked as overutilized if any of the following

conditions are true:


¦ CPU resources for the instance of SQL Server are overutilized.


¦ CPU resources of the computer that hosts the SQL Server instance are

overutilized.


¦ The instance contains data or log files with overutilized storage space.


¦ The instance contains data or log files that reside on volumes with overutilized

storage space.


. Underutilized A SQL Server instance is marked as underutilized if it is not

marked as overutilized and any of the following conditions are true:


¦ CPU resources allocated to the instance of SQL Server are underutilized.


¦ CPU resources of the computer that hosts the SQL Server instance are

underutilized.


¦ The instance contains data or log files with underutilized storage space.


¦ The instance contains data or log files that reside on volumes with underutilized

storage space.


. No Data Available Either data has not been uploaded from a managed instance

or there is a problem with the collection and upload process.


By viewing the Managed Instance Health section, DBAs are able to quickly obtain an

overview of resource utilization across all managed instances within the utility. The

example in Figure 5-6 shows that five managed instances are well utilized, six are overutilized,

none are underutilized, and data is unavailable for three managed instances in

the Managed Instance Health section.


¦ Managed Instances With Overutilized Resources This section is found directly

under the Managed Instance Health section. It displays overutilization data for managed

instances of SQL Server based on the following categories:


. Overutilized Instance CPU This represents the number of managed instances

of SQL Server that are violating instance CPU overutilization policies.


. Overutilized Database Files This represents the number of managed instances

of SQL Server with database files that are violating file space overutilization policies.


. Overutilized Storage Volumes This represents the number of managed instances

of SQL Server with database files on storage volumes that are violating file

space overutilization policies.


. Overutilized Computer CPU This represents the number of managed instances

of SQL Server running on computers that are violating computer CPU overutilization

policies.


Detailed status for each health parameter is listed in a sliding indicator to the right of

each element in this section.


¦ Managed Instances With Underutilized Resources This section is located under

the Managed Instances With Overutilized Resources section and displays underutilization

data for managed instances of SQL Server based on the following categories:


. Underutilized Instance CPU This represents the number of managed instances

of SQL Server that are violating instance CPU underutilization policies.


. Underutilized Database Files This represents the number of managed instances

of SQL Server with database files that are violating volume space underutilization

policies.


. Underutilized Storage Volumes This represents the number of managed

instances of SQL Server with database files on storage volumes that are violating file

space underutilization policies.


. Underutilized Computer CPU This represents the number of managed instances

of SQL Server running on computers that are violating computer CPU underutilization

policies.


Detailed status for each health parameter is listed in a sliding indicator to the right of

each element in this section.


¦ Data-Tier Application Health This section is located in the top-right corner of the

Utility Explorer Content pane. Health status is illustrated in a pie chart and has four

possible designations:


. Well Utilized The number of deployed data-tier applications that are not violating

resource utilization policies is displayed.


. Overutilized The number of deployed data-tier applications that are violating

resource overutilization policies is displayed. A deployed data-tier application is

marked as overutilized if any of the following conditions are true:


¦ CPU resources for the deployed data-tier application are overutilized.


¦ CPU resources of the computer that hosts the SQL Server instance are

overutilized.


¦ Storage volumes associated with the deployed data-tier application are

overutilized.


¦ The deployed data-tier application contains data or log files that reside on volumes

with overutilized storage space.


. Underutilized The number of deployed data-tier applications that are violating

resource underutilization policies is displayed. A deployed data-tier application is

marked as underutilized if any of the following conditions are true:


¦ CPU resources for the deployed data-tier application are underutilized.


¦ CPU resources of the computer that hosts the SQL Server instance are

underutilized.


¦ Storage volumes associated with the deployed data-tier application are

underutilized.


¦ The deployed data-tier application contains data or log files that reside on

volumes with underutilized storage space.


. No Data Available Either data affiliated with deployed data-tier applications has

not been uploaded to the Utility Control Point or there is a problem with the collection

and upload process.


By viewing the Data-Tier Application Health section, DBAs can quickly obtain a holistic

view of resource utilization for all deployed data-tier applications managed by the SQL

Server Utility. In Figure 5-6, there are seven well-utilized and two overutilized data-tier

applications.


¦ Data-Tier Applications With Overutilized Resources This section is found

directly under the Data-Tier Application Health section. It displays overutilization data

for deployed data-tier applications based on the following categories:


. Overutilized Data-Tier Application CPU This represents the number of

deployed data-tier applications that are violating data-tier application CPU

overutilization policies.


. Overutilized Database Files This represents the number of deployed data-tier

applications with database files that are violating file space overutilization policies.


. Overutilized Storage Volumes This represents the number of deployed datatier

applications with database files on storage volumes that are violating file space

overutilization policies.


. Overutilized Computer CPU This represents the number of deployed data-tier

applications running on computers that are violating computer CPU overutilization

policies.


Detailed status for each health parameter is listed in a sliding indicator to the right of

each element in this section.


¦ Data-Tier Applications With Underutilized Resources This section is located

directly under the Data-Tier Applications With Overutilized Resources section. This

section displays underutilization data of individual instances based on the following

categories:


. Underutilized Data-Tier Application CPU This represents the number of

deployed data-tier applications that are violating data-tier application CPU underutilization

policies.


. Underutilized Database Files This represents the number of deployed data-tier

applications with database files that are violating file space underutilization policies.


. Underutilized Storage Volumes This represents the number of deployed datatier

applications with database files on storage volumes that are violating file space

underutilization policies.


. Underutilized Computer CPU This represents the number of deployed datatier

applications running on computers that are violating computer CPU underutilization

policies.


Detailed status for each health parameter is listed in a sliding indicator to the right of

each element in this section.


¦ Utility Storage Utilization History Located at the bottom-left corner of the Utility

Explorer Content pane, this section uses a time graph to display the storage utilization

history for the amount of storage the SQL Server Utility is consuming in gigabytes.

By using the buttons under the Interval heading , you can view data in the graph by

the following intervals:


. 1 Day Displays data in 15-minute intervals


. 1 Week Displays data in one-day intervals


. 1 Month Displays data in one-week intervals


. 1 Year Displays data in one-month intervals


¦ Utility Storage Utilization The bottom-right corner shows a pie chart that displays

the amount of space used and the amount of free space available on the volume hosting

the SQL Server Utility. It is worth noting that the data is refreshed every 15 minutes.


This section explained how to obtain summary information for all managed instances of

SQL Server. DBAs seeking more information might be interested in the Managed Instances

node in the tree view of Utility Explorer. This node helps database administers gain deeper

knowledge of health status and resource utilization data for each managed instances of SQL

Server. The next section discusses this dashboard.


TIP When working with the SQL Server Utility dashboard, you can click on a link to reveal

additional details about a specific policy.


Using the Managed Instances Viewpoint


DBAs can display the Managed Instances viewpoint in the Utility Explorer Content pane by

connecting to a UCP and then selecting the Managed Instances node in the Utility Explorer

tree. The Utility Explorer Content pane displays the viewpoint, as shown in Figure 5-7, which

communicates the health state and resource utilization information for numerous items including

the CPU, storage, and policies for each managed instance of SQL Server.


FIGURE 5-7 The Managed Instances viewpoint


Resource utilization for each managed instance of SQL Server is presented in the list view

located at the top of the Utility Explorer Content pane. Health state icons appear to the right

of each managed instance and provide summary status for each instance of SQL Server based

on the utilization category. Three icons are used to indicate the health of each managed

instance of SQL Server. A green check mark indicates that an instance is well utilized and does

not violate any policies. A red arrow indicates that an instance is overutilized, and a green arrow

indicates underutilization. The lower half of the dashboard contains tabs for CPU utilization,

storage utilization, policy details, and property details for each managed instance.


In Figure 5-7, the instance CPU, computer CPU, file space, and volume space columns for

SQL2K8R2-01\INSTANCE01 and SQL2K8R2-01\INSTANCE05 are all underutilized. In addition,

the following other elements are underutilized: the Instance CPU for SQL2K8R2-03\

INSTANCE03, Computer CPU for SQL2K8R2-01\INSTANCE02, SQL2K8R2-01\INSTANCE03,

SQL2K8R2-01\INSTANCE04 and SQL2K8R2-01\INSTANCE05, File Space for SQL2K8R2-02\INSTANCE03

and Volume Space for SQL2K8R2-01\INSTANCE02, SQL2K8R2-01\INSTANCE03, and

SQL2K8R2-01\INSTANCE04. The volume space for SQL2K8R2-02, SQL2K8R2-02\INSTANCE02,

SQL2K8R2-03, SQL2K8R2-03\INSTANCE02, SQL2K8R2-03\INSTANCE03, and SQL2K8R2-03\

INSTANCE04 are all overutilized, and the remainder of managed instances are well utilized.


The Managed Instances list view columns and utilization tabs are discussed in more detail

in the next sections.


The Managed Instances List View Columns


The health status of each managed instance of SQL Server in the Managed Instances list view

is analyzed against four types of utilization and the current policy in place for each:


¦ Instance CPU This column indicates processor utilization of the managed instance.

The health state is determined by the global CPU Utilization For All Managed Instances

Of SQL Server policy, which is predetermined for all managed instances of SQL Server.

However, by clicking on the Policy Tab in the bottom half of the view, DBAs can override

this global policy to configure overutilization and underutilization policies for

a single instance. The CPU Utilization tab shows the CPU utilization history for the

selected managed instance of SQL Server.


¦ Computer CPU This column communicates computer processor utilization where

the managed instance resides. Health is based on the settings of two policies: the CPU

utilization policy in place for the computer and the configuration setting for the Volatile

Resource Evaluation policy. The CPU Utilization tab shows the processor utilization

history for a managed instance of SQL Server.


¦ File Space The File Space column summarizes file space utilization for all of the

databases belonging to a selected instance of SQL Server. The health state for this

parameter is determined by global or local file space utilization policies. Because there

are many database associated with a managed instance of SQL server, the health state

is reported as overutilized if only one database is overutilized. The Storage Utilization

tab shows health state information on all other database files.


¦ Volume Space Volume space utilization is summarized in this column for volumes

with databases belonging to each managed instance. The health of this parameter

is determined by the global or local storage volume utilization policies for managed

instances of SQL Server. As with file space reports, the health of a storage volume associated

with a managed instance of SQL Server that is overutilized is reported with a red

up arrow, and underutilization is reported with a green arrow. The Storage Utilization

tab shows additional health information and history for volumes.


¦ Policy Type The final column in the list view specifies the type of policy applied to

the managed instance of SQL Server. Policy type results are reported as either Global

or Override, with Global meaning that default policies are in use, and Override meaning

that custom policies are in use.


DBAs can appreciate the value of the information each list view column holds. But, in the

case of the Managed Instances view, DBAs can gain an even greater appreciation by also accessing

the Managed Instances viewpoint tabs to better understand their present infrastructure

and to better prepare for a successful consolidation.


The Managed Instances Detail Tabs


The Managed Instances viewpoint includes tabs for additional viewing. The tabs are located

at the bottom of the viewpoint and consist of


¦ CPU Utilization The CPU Utilization tab, illustrated earlier in Figure 5-7, displays

historical information of CPU utilization for a selected managed instance of SQL Server

according to the interval specified on the left side of the display area. DBAs can change

the display intervals for the graphs by selecting one of these options:


. 1 Day Displays data in 15-minute intervals


. 1 Week Displays data in one-day intervals


. 1 Month Displays data in one-week intervals


. 1 Year Displays data in one-month intervals


Two linear graphs are presented next to each other. The first graph shows CPU utilization

based on the managed instance of the SQL Server, and the second graph displays

data based on the computer associated with the managed instance.


¦ Storage Utilization The next tab displays storage utilization for a selected managed

instance of SQL Server, as depicted in Figure 5-8. Data is grouped by either

database or volume. When the Database option button is selected, storage utilization

is displayed for each database, filegroup, or a specific database file, which is based on

the node selected in the tree view. If the Volume option button is selected, storage utilization

history is displayed according to file space used by all data files and all log files

located on the storage volume. The tree view also can be expanded to present storage

utilization information and history for each volume and database file associated with a

volume.


FIGURE 5-8 The Storage Utilization tab on the Managed Instances viewpoint


Independent of how the files are grouped, health status is communicated for every database,

filegroup, database file, or volume. For example, the green arrows in Figure 5-8

indicate that all databases, filegroups, and data files are underutilized. No health states

are shown as overutilized. Once again, the display intervals for the graphs are changed

by selecting one of the following options:


. 1 Day Displays data in 15-minute intervals


. 1 Week Displays data in one-day intervals


. 1 Month Displays data in one-week intervals


. 1 Year Displays data in one-month intervals


¦ Policy Details DBAs can use the Policy Details tab, shown in Figure 5-9, to view

the global policies applied to a selected managed instance of SQL Server. In addition,

the Policy Details tab can be used to create a custom policy that overrides the default

global policy applied to a selected managed instance of SQL Server. The display is

broken into the following four policies that can be viewed or modified:


. Managed Instance CPU Utilization Policies


. File Space Utilization Policy


. Computer CPU Utilization Policies


. Storage Volume Utilization Policies


FIGURE 5-9 The Policy Details tab on the Managed Instances viewpoint


NOTE To override the global policy for a specific managed instance, select the Override

The Global Policy option button. Next, specify the new overutilized and underutilized

numeric values in the control boxes to the right of the policy description, and

then click Apply. For example, in Figure 5-9, the default global policy for the CPU of a

managed instance is to consider the CPU overutilized when its usage is greater than 70

percent. The global policy was overridden, and the new setting is 50 percent. Similarly,

the CPU underutilization setting is changed from zero percent to 10 percent.


¦ Property Details This tab, shown in Figure 5-10, displays property details for the

selected managed instance of SQL Server. The Property detail information displays the

processor name, processor speed, processor count, physical memory, operating system

version, SQL Server version, SQL Server edition, backup directory, collation information,

case sensitivity, language, whether or not the instance of SQL Server is clustered,

and the last time data was successfully updated.


FIGURE 5-10 The Property Details tab on the Managed Instances viewpoint


Using the Data-Tier Application Viewpoint


As it is when you use the Managed Instances viewpoint to monitor health status and resource

utilization for managed instances of SQL Server, using the Data-Tier Applications viewpoint

enables you to monitor deployed data-tier applications managed by the SQL Server Utility

Control Point.


NOTE The viewpoints associated with this section may at first appear identical to the

information under the previous section, “The Managed Instances Detail Tab.” However,

the policies and files in this section do differ from those described previously, sometimes

slightly and sometimes significantly.


Similar to the Managed Instance viewpoint, DBAs can access the Data-Tier Applications

view and viewpoints in the Utility Explorer Content pane by connecting to a UCP and then

selecting the Deployed Data-Tier Application node in the Utility Explorer tree. The Utility

Explorer Content pane displays the view, as illustrated in Figure 5-11, that communicates

the health and utilization status for the application CPU, the computer CPU, file space, and

volume space.


FIGURE 5-11 The data-tier application viewpoint


Resource utilization for each deployed data-tier application is presented in the list view located

at the top of the Utility Explorer Content pane. Health state icons appear at the right of

each deployed data-tier application and provide summary status for each deployed data-tier

application based on the utilization category. Three icons are used to indicate the health state

of each deployed data-tier application. A green check mark indicates that the deployed datatier

application is well utilized and does not violate any policies. A red arrow indicates that

the deployed data-tier application is overutilized, and a green arrow indicates underutilization.

The lower half of the view contains tabs for CPU utilization, storage volume utilization,

access policy definitions, and property details for each data-tier application. For example, the

computer CPU and volume space for the AccountingDB and FinanceDB data-tier applications

shown in Figure 5-11 are underutilized. In addition, the application CPU and the file space

utilization for all deployed data-tier applications are well utilized, and the volume space for

AdventureWorks2005 and AdventureWorks2008R2 are overutilized.


The data-tier application list view columns and utilization tabs are discussed in the upcoming

sections.


The Data-Tier Application List View


The columns presenting the state of health for each deployed data-tier application in the

data-tier application list view include


¦ Application CPU This column displays the health state utilization of the processor

for the deployed data-tier application. The health state is determined by the CPU utilization

policy for deployed data-tier applications. The CPU Utilization tab shows CPU

utilization history for the selected deployed data-tier application.


¦ Computer CPU This column communicates computer processor utilization for

deployed data-tier applications. The CPU Utilization tab shows the processor utilization

history for the deployed data-tier application.


¦ File Space The File Space column summarizes file space utilization for each deployed

data-tier application. The health state for this parameter is determined by global or

local file space utilization policies. The Storage Utilization tab shows health state information

on all other database files.


¦ Volume Space Volume space utilization is summarized in this column for volumes with

databases belonging to each deployed data-tier application. The health of this parameter

is determined by the global or local Storage Volume utilization policies for deployed

data-tier application of SQL Server. Similar to File Space reports, the health of a storage

volume associated with a deployed data-tier application of SQL Server that is overutilized

is reported with a red arrow, and underutilization is reported with a green arrow. The

Storage Utilization tab shows additional health information and history for volumes.


¦ Policy Type This column in the list view specifies the type of policy applied to a

deployed data-tier application of SQL Server. Policy Type results are reported as either

Global or Override. Global indicates that default policies are in use, and Override indicates

that custom policies are in use.


¦ Instance Name The final column in the list view specifies the name of the SQL

Server instance to which the data-tier application has been deployed.


The Data-Tier Application Tabs


The Data-Tier Applications viewpoint includes tabs for additional viewing. The tabs are located

at the bottom of the viewpoint and consist of


¦ CPU Utilization The CPU Utilization tab, illustrated in Figure 5-11, displays historical

information on CPU utilization for a selected deployed data-tier application according

to the interval specified on the left side of the display area. DBAs can change the

display intervals for the graphs by selecting one of the following options:


. 1 Day Displays data in 15-minute intervals


. 1 Week Displays data in one-day intervals


. 1 Month Displays data in one-week intervals


. 1 Year Displays data in one-month intervals


Two linear graphs are presented next to each other. The first graph shows CPU utilization

based on the selected deployed data-tier application, and the second graph displays

data based on the computer associated with the deployed data-tier application.


¦ Storage Utilization The next tab displays storage utilization for a selected deployed

data-tier application, as depicted in Figure 5-12. Data is grouped by either

filegroup or volume. When the Filegroup option button is selected, storage utilization

is displayed for each data-tier application based on the node selected in the tree

view. If the Volume option button is selected, storage utilization history is displayed

by volume. The tree view also can be expanded to present storage utilization information

and history for each volume and filegroup associated with a deployed data-tier

application. In Figure 5-12, the volume space for the AdventureWorks2005 deployed

data-tier application is shown as overutilized because a red arrow is displayed in the

Volume Space column of the Storage Utilization tab.


Once again, the display intervals for the graphs are changed by selecting one of the

options available below:


. 1 Day Displays data in 15-minute intervals


. 1 Week Displays data in one-day intervals


. 1 Month Displays data in one-week intervals


. 1 Year Displays data in one-month intervals


FIGURE 5-12 The Storage Utilization tab on the Data-Tier Applications viewpoint


¦ Policy Details The Policy Details tab, shown in Figure 5-13, is where a DBA can view

the global policies applied to a selected deployed data-tier application. The Policy

Details tab can also be used to create a custom policy that overrides the default global

policy applied to a deployed data-tier application. For example, by expanding the

Data-Tier Application CPU Utilization Policies section, you can observe that the global

policy is applied. With this policy, a CPU of a data-tier application is considered to be

overutilized when its usage is greater than 70 percent and underutilized when it is less

than zero percent. If you wanted to override this global policy for a data-tier application,

you would select the Override The Global Policy option button and specify the

new overutilized and underutilized numeric values in the box. You would then click

Apply to enforce the new policy. In Figure 5-13, the global policy has been modified

from its original settings, and the CPU of a data-tier application is now considered to

be overutilized when its usage is greater than 30 percent. To override this setting, you

would choose the Override The Global Policy option button and set a desired value

in the box to the right of the policy description. For this example, the setting was

changed from 30 percent to 70 percent.


FIGURE 5-13 The Policy Details tab on the Data-Tier Applications viewpoint


The display is broken up into the following four policies, which can be viewed or

overridden:


. Data-Tier Application CPU Utilization Policies


. File Space Utilization Policies


. Computer CPU Utilization Policies


. Storage Volume Utilization Policies


¦ Property Details The Property Details tab, shown in Figure 5-14, displays generic

property details for the selected deployed data-tier application. Property detail information

consists of database name, deployed date, trustworthiness, collation, compatibility

level, encryption-enabled state, recovery model, and the last time data was

successfully updated.


FIGURE 5-14 The Property Details tab on the Data-Tier Applications viewpoint


109


C H A P T E R 6


Scalable Data Warehousing


Microsoft SQL Server 2008 R2 Parallel Data Warehouse is an enterprise data warehouse

appliance based on technology originally created by DATAllegro and

acquired by Microsoft in 2008. In the months following the acquisition, Microsoft revamped

the product by changing it from a product that used the Linux operating system

and Ingres database technologies to a product based on SQL Server 2008 R2 and the

Windows Server 2008 operating system. SQL Server 2008 Enterprise has many features

supporting scalability and data warehouse performance that Parallel Data Warehouse

uses to its advantage. The combination of SQL Server scalability and performance with

a massively parallel processing (MPP) architecture in Parallel Data Warehouse creates a

powerful new option for hosting a very large data warehouse.


Parallel Data Warehouse Architecture


Parallel Data Warehouse does not install like other editions of SQL Server. Instead, it is

a data warehouse appliance that bundles multiple software and hardware technologies,

including SQL Server, into a platform well suited for a very large data warehouse. A key

characteristic of this platform is the MPP architecture, which enables fast data loads and

high-performance queries. This architecture consists of a multi-rack system, which parallelizes

queries across an array of dedicated servers connected by a high-speed network

to deliver results at speeds that are typically faster than possible with a traditional symmetric

multiprocessing (SMP) architecture.


Data Warehouse Appliances


You purchase a data warehouse appliance as preassembled and preconfigured integrated

components with all software preinstalled. When you place an order for an appliance

with an authorized vendor, you specify the number of appliance racks that you want to

purchase. The vendor works with you to add options, such as an optional backup node,

and to optimize the system to meet your requirements for faster query performance

and for storage of high data volumes. The vendor then assembles industry-standard

hardware components and loads the operating system, SQL Server, and Parallel Data


110 CHAPTER 6 Scalable Data Warehousing


Warehouse software. When the assembly process is complete, the vendor ships the appliance

to you using shockproof pallets. When it arrives, you remove the appliance from the pallets,

plug it into a power source, and connect it to your network.


Parallel Data Warehouse is a data warehouse appliance that includes all server, networking,

and storage components required to host a data warehouse. In addition, your purchase of

Parallel Data Warehouse includes cables, power distribution units, and racks. Furthermore, the

components have redundancy to prevent downtime caused by a failure. The vendor installs all

software at the factory and configures Parallel Data Warehouse to balance CPU, memory, and

disk space. After you receive the Parallel Data Warehouse at your location, you use a configuration

tool that Parallel Data Warehouse includes to complete the network setup and configure

appliance settings for your environment. You can also install Microsoft or third-party

software to use when copying data between your corporate network and the appliance.


Processing Architecture


A traditional data warehouse deployment of SQL Server is an SMP architecture, in which identical

processors share memory on a single server. One physical instance of a database processes

all queries. You can improve performance by partitioning the data, thereby achieving

multi-threaded parallelization. You can add higher powered servers with more CPU, memory,

storage, and networking capacity to scale up, but the cost to scale up is high.


By contrast, Parallel Data Warehouse is an MPP architecture that uses multiple database

servers that operate together to process queries. Behind the scenes, each database server

runs one SQL Server instance with its own dedicated CPU, RAM, storage, and network

bandwidth. Each database managed by Parallel Data Warehouse is distributed across multiple

database servers that execute Parallel Data Warehouse queries in parallel. Parallel Data

Warehouse’s architecture includes a controlling server to coordinate these parallel queries

and all other database activity across the multiple database servers. This controlling server

also presents the distributed database as a single logical database to users. If you need to

scale out the MPP hardware, you can simply add inexpensive commodity servers and storage

rather than expensive high-end servers and storage.


The Multi-Rack System


Parallel Data Warehouse is configured as a multi-rack system in which there is a control rack

and one or more data racks, as shown in Figure 6-1. Each rack is a collection of nodes, each of

which has a dedicated role within the appliance. These nodes transfer data among themselves

using an InfiniBand network that ships with the appliance. Only the nodes in the control rack

communicate with the corporate Ethernet network. The nodes in the data rack can export

tables to a corporate SMP SQL Server database by using the InfiniBand network.


Parallel Data Warehouse Architecture CHAPTER 6 111


Control rack Data rack

Management node

active/passive

User queries

Control node

active/passive

Landing Zone

Backup node

Control rack

Active server Dedicated storage

Passive server

Data loading

Data backup

Dual Fibre

Dual Channel

InfiniBand

SQL

SQL

SQL

SQL

SQL

SQL

SQL

SQL


FIGURE 6-1 The multi-rack system


The Data Rack


All activity related to parallel query processing occurs in the data rack, which is a collection of

compute nodes. Each compute node consists of a server with dedicated storage, a SQL Server

instance, and additional Parallel Data Warehouse software that provides communication and

data transfer functions. Although the compute nodes run separate SQL Server instances in

parallel to manage each distributed appliance database, you query the database as if it were a

single database.


The number of compute nodes in a data rack varies among the vendors, although each

vendor follows a standard architecture specification. For example, each data rack includes a

spare server for high availability. If a compute node server fails or needs to be taken offline

for maintenance, the compute node server automatically fails over to the spare server.

The current connections to the appliance stay intact while the appliance reconfigures itself.

Just as with SQL Server failover, queries that were in progress before the failover need to be

restarted.


The Control Rack


The control rack is a separate rack that houses the servers, storage, and networking components

for the nodes that provide control, management, or interface functions. It contains

several types of nodes that Parallel Data Warehouse uses to process user queries, to load

and back up data, and to manage the appliance. Some of the nodes serve as intermediaries

between the corporate network and the private network that connects the nodes in both the

control rack and data rack. You never interact directly with the data rack; you submit a data

load or a query to the control rack, which then coordinates the processes between nodes to

complete your request.


Most Parallel Data Warehouse activity involves coordination with the control node. To support

high availability, the control node is a two-node active/passive cluster. If the active node

fails for any reason, the passive node takes over. The redundancy between the two nodes

ensures the appliance can recover quickly from a failure.


Parallel Data Warehouse uses multiple networking technologies. The control rack servers

connect to the corporate network by using the corporate Ethernet. The compute node servers

connect to their dedicated database storage by using a Fibre Channel network. A highspeed

InfiniBand network internally connects all the servers in the appliance to one another.

Because InfiniBand is much faster than a Gigabit Ethernet network, it is better suited for the

Parallel Data Warehouse nodes, which must transfer high volumes of data and be as fast as

possible. For high availability, the switching fabric of each network includes redundancy.


The Control Node


The control node is in the control rack and manages client authentication; accepts client connections

to Parallel Data Warehouse; manages the query execution process, which it distributes

across the compute nodes; and serves as the central point for all hardware monitoring.

To support high availability, the control node is a two-node active/passive cluster in which the

passive node instantly takes over if the active node fails for any reason. The control node also

contains a SQL Server instance.


To support the distributed architecture of Parallel Data Warehouse, the control node contains

the MPP Engine, the Data Movement Service (DMS), and Windows Internet Information

Services (IIS), as shown in Figure 6-2. The MPP Engine coordinates parallel query processing,

storage of appliance-wide metadata and configuration data, and authentication and authorization

for the appliance and databases. The DMS, which runs on most appliance nodes, is the

communication interface for copying data between appliance nodes. IIS hosts a Web application,

called the Admin Console, that you access by using Windows Internet Explorer and use

to manage and monitor the appliance status and query performance.


You can connect to the Parallel Data Warehouse control node by using a variety of client

access tools. Parallel Data Warehouse integrates with SQL Server 2008 R2 Business Intelligence


Development Studio, SQL Server Integration Services, SQL Server Analysis Services, and SQL

Server Reporting Services. The Nexus client is the query editor that you can use to submit

queries by using SQL statements to Parallel Data Warehouse. Parallel Data Warehouse also

includes DWSQL, a command-line tool for submitting SQL statements to the control node.

These client tools use Data Direct’s SequeLink client drivers that support the following data

access driver types:


¦ ODBC


¦ OLE DB


¦ ADO.NET


SQL Server

SMP SQL database

Appliance nodes

Client access tools

SQL

Server BI

(AS, RS, IS)

Data rack

Compute

DMS

SQL Server

User data

Control rack

Management

Backup

DMS

Landing Zone

Landing tool DMS

Control

IIS

Admin

Console

Data

Movement

Service

(DMS)

MPP Engine

SQL Server

Control

database

OLEDB

ODBC

ADO.NET

NEXUS

query

editor

DWSQL


FIGURE 6-2 Appliance software


The Landing Zone Node


The Landing Zone is a high-capacity data storage node in the control rack that contains terabytes

of disk space for temporary storage of user data before loading it into the appliance.

Using your ETL processes to move data to the Landing Zone, you can either copy data to the

Landing Zone and then load it into the appliance, or you can load data directly without first

storing it on the Landing Zone. With either approach, the Landing Zone uses the appliance’s

high-speed fabric to copy that data in parallel into the data rack. To perform parallel data

loading, you can use SQL Server Integration Services or a command-line tool.


The Backup Node


Another node in the control rack is the Backup node that, as the name implies, is dedicated

to the backup process, which it can perform at very high speed. The backup node uses SQL

Server’s native database-level backup and restore functionality and coordinates the backup

across nodes. You can create full backups or differential backups of user databases, or

backups of the system database that contains information about user accounts, passwords,

and permissions. The initial backup takes the longest time because it contains all data in a

database, but subsequent differential backups run much faster because they contain only

the changes in the data that were made since the last full backup. Furthermore, the backup

process runs in parallel across nodes to help performance.


TIP To restore the backup, the destination appliance must have at least as many of compute

nodes as the appliance where the backup was created.


The Management Node


The final node in the control rack is the management node, which operates as the hub for

software deployment, servicing, and system health and performance monitoring. This node

also runs a Windows domain controller to manage authentication within the appliance. It

performs functions related to the management of hardware and software in the appliance

and is not visible to users. Like the control node, the management node is a two-node active/

passive cluster.


NOTE Parallel Data Warehouse does not use the domain controller on the management

node for user authentication.


The Compute Node


Each compute node is the host for a single SQL Server instance and runs the DMS to communicate

with and transfer data to other appliance nodes. Each compute node stores a subset of

each user database. Before parallel query processing begins, Parallel Data Warehouse copies


any necessary data to each compute node so that it can process the query in parallel with

other compute nodes without requiring data from other locations during processing. This

feature, called data colocation, ensures that each compute node can execute its portion of the

parallel query with no effect on the query performance of the other compute nodes.


Hub-and-Spoke Architecture


Rather than using Parallel Data Warehouse exclusively for a data warehouse, you can use a

hub-and-spoke architecture to support both a corporate data warehouse and special purpose

data marts. These data marts reside on servers outside of the appliance. The data warehouse

at the hub is the primary data source for the spokes. A spoke can be a data mart, a host for

Analysis Services, or even a development or test environment. You can enforce business rules

and data quality standards for all data at the hub, and then you can quickly copy data as

needed from the Parallel Data Warehouse to the spokes residing outside the appliance.


Data Management


Loading, processing, and backing up terabytes of data with balanced hardware resources is

vitally important in a very large data warehouse. Parallel Data Warehouse uses carefully balanced

hardware to maximize the efficiency of each hardware component and avoid the need

to over-purchase hardware. Parallel Data Warehouse accomplishes this goal of balancing

speed and hardware by using a shared nothing (SN) architecture.


In addition to the shared nothing architecture, there are other differences from other editions

of SQL Server to notice. For example, SQL commands to create a database and tables

are slightly different from their standard Transact-SQL counterparts. In addition, although

Parallel Data Warehouse supports most of the SQL Server 2008 data types, there are a few

exceptions. Last, the architecture requires a new approach to query processing and data

load processing.


Shared Nothing Architecture


An SN architecture is a type of architecture in which each node of a system uses its own CPU,

memory, and storage to avoid performance bottlenecks caused by resource contention with

other nodes. In Parallel Data Warehouse, each compute node contains its own data, CPU, and

storage to function as a self-sufficient and independent unit. Although the SN architecture

is gaining popularity as a data warehousing architecture, performance can still be slow when

a parallel query must first move data among the nodes before execution. When a SQL join

operation requires data that is not already on the requisite compute nodes, Parallel Data

Warehouse copies data to these nodes temporarily for use during query execution.


You design the data layout on the appliance to avoid or minimize data movement for parallel

queries by using either a replicated or a distributed strategy for storage. When planning

which strategy to implement, you consider the types of joins that the parallel queries require.

Some tables require a replicated strategy, whereas others require a distributed strategy.


Replicated Strategy


For best performance, you can add small tables—such as dimension tables in a star schema—

to Parallel Data Warehouse by using a replicated strategy. Parallel Data Warehouse makes

a copy of the table on each compute node, as shown in Figure 6-3. You then perform the

initial load of the table, followed by any subsequent inserts, updates, or deletes, as if you were

working with a single table, without the need to manage each copy of the table. Parallel Data

Warehouse handles all changes to the table for you. When a query performs a join on a replicated

dimension, Parallel Data Warehouse joins the dimension to the portion of the fact table

that exists on the same compute node. All compute nodes run the query in parallel and can

find data very quickly because the complete dimension table is on each compute node.


Table

Compute nodes

All table rows are copied

to each compute node

Replicated table


FIGURE 6-3 Replicated strategy


Distributed Strategy


One of the keys to performance in an MPP architecture is the distribution of large tables

across multiple nodes, as shown in Figure 6-4. To distribute a fact table, you simply select a

column from the table to use as the distribution column, and when data is loaded into the

table, Parallel Data Warehouse automatically spreads the rows across all of the compute


nodes in the appliance. There are performance considerations for the selection of a distribution

column, such as distinctness, data skew, and the types of queries executed on the system. For

a detailed discussion of the choice of distributed tables, refer to the product documentation.


To distribute the rows in the fact table, a hash function assigns each row to one of many storage

locations based on the distribution column. Each compute node has 8 storage locations,

called distributions, for the hashed rows. If a data rack has 8 compute nodes, the data rack has

64 distributions, which are queried in parallel.


Hash

function

Table

Compute nodes

Each table row

belongs to one

distribution

Distributed table


FIGURE 6-4 Distributed strategy


It is not essential that equal numbers of table rows are assigned to each distribution. There

will almost always be some data skew among the distributions. If the amount of data skew

becomes too large, the parallel system continues to run, but query times might be affected.

You might have to experiment with several approaches before finding the best distributed

strategy. A distributed strategy does not affect other table options that you might want to

implement. For example, you can still define partitions and clustered indexes as needed.


DDL Extensions


To support the MPP architecture, Parallel Data Warehouse includes a SQL language that

works with appliance databases. This SQL language includes data definition language (DDL)

statements to create and alter databases, tables, views, and other entities on the appliance.

You use these statements to operate on these objects as if they were on a single database

instance. Behind the scenes, Parallel Data Warehouse allocates space for the objects and

instantiates them across nodes.


CREATE DATABASE


The CREATE DATABASE statement has a set of options for supporting distributed and replicated

tables. You determine how much space you need in total for the database for replicated

tables, distributed tables, and logs. Parallel Data Warehouse manages the database according

to your specifications.


Here is an example of the statement you use in Parallel Data Warehouse to create a new

database:


CREATE DATABASE DW

WITH (

AUTOGROW = ON,

REPLICATED_SIZE = 50,

DISTRIBUTED_SIZE = 10000,

LOG_SIZE = 25

);


This statement uses the following options:


¦ AUTOGROW This option specifies whether to enable or disable the automatic

growth feature. This feature allows Parallel Data Warehouse to manage the growth of

data and log files as needed over time.


¦ REPLICATED_SIZE This specifies the total space in gigabytes allocated to replicated

tables (and associated data) on each compute node. Parallel Data Warehouse stores

replicated tables in a SQL Server filegroup on each compute node.


¦ DISTRIBUTED_SIZE This specifies the total space in gigabytes allocated to distributed

tables on the appliance. Parallel Data Warehouse divides the space among all distributions

on the compute nodes and stores each distribution in a separate SQL Server

filegroup. In the SN architecture of Parallel Data Warehouse, each distribution has its

own set of disks for storage. This set of disks is configured as a logical unit number

(LUN).


¦ LOG_SIZE This option specifies the total space in gigabytes allocated to the transaction

log on the appliance. You should plan for the log file size to be large enough to

accommodate the largest data load that you expect. The automatic growth feature

adjusts the log size as needed if you underestimate the required log file size.


CREATE TABLE


The CREATE TABLE statement syntax varies slightly from its syntax in standard Transact-SQL.

For Parallel Data Warehouse, the statement includes options for specifying whether the table

uses a replicated or a distributed strategy and whether to store the table with a clustered index

or with a heap. You can also use this syntax to create partitions by specifying the partition

boundary values.


NOTE Parallel Data Warehouse does not use the Transact-SQL partition schema or partition

function. Also, you can create a clustered index only when you use CREATE TABLE. To

create a nonclustered index, you use CREATE INDEX.


Here is an example of the syntax to create a replicated table:


CREATE TABLE DimProduct

(

ProductId BIGINT NOT NULL,

Description VARCHAR(50),

CategoryId INT NOT NULL,

ListPrice DECIMAL(12,2)

) WITH ( DISTRIBUTION = REPLICATE );


This syntax instructs Parallel Data Warehouse to create a table on all compute nodes. Subsequent

commands to insert or delete data affect data in each copy of the table.


Here is an example of the syntax to create a distributed table:


CREATE TABLE FactSales

( CustomerId BIGINT,

SalesId BIGINT,

ProductId BIGINT,

SaleDate DATE,

Quantity INT,

Amount DECIMAL(15,2)

) WITH (

DISTRIBUTE = HASH (CustomerId),

CLUSTERED INDEX (SaleDate),

PARTITION ( SaleDate

RANGE RIGHT FOR VALUES

( ‘2009-01-01′,’2009-02-01′,’2009-03-01′,’2009-04-01′,’2009-05-01′,’2009-06-01’

,’2009-07-01′,’2009-08-01′,’2009-09-01′,’2009-10-01′,’2009-11-01′,’2009-12-01′)

));


The CREATE TABLE statement for Parallel Data Warehouse includes the following items:


¦ DISTRIBUTION Specifies the column to hash for distributing rows across all compute

nodes in Parallel Data Warehouse


¦ CLUSTERED INDEX Specifies the column for a clustered index—if you omit this

item from the statement, Parallel Data Warehouse stores the table as a heap


¦ PARTITION Specifies the boundary values of the partition and the column to use for

partitioning the rows


In addition, you can use a CREATE TABLE AS SELECT statement to create a table from the

results of a SELECT statement. You might use this technique when you are redistributing or

defragmenting a table.


Here is an example of the syntax for a CREATE TABLE AS SELECT statement:


CREATE TABLE DimCustomer

WITH

( CLUSTERED INDEX (CustomerID) )

AS

SELECT * FROM DimCustomer;


Another option for creating tables is the CREATE REMOTE TABLE statement, which you

can use to export a table to a non-appliance SQL Server database in an SMP architecture. To

use this statement, you must ensure that the target database is available on the appliance’s

InfiniBand network.


Data Types


Many SQL Server data types supported by SQL Server 2008 are also supported by Parallel

Data Warehouse. Character and binary strings are supported, but you must limit the string

length to 8,000 characters. Another point to note is that Parallel Data Warehouse uses only

Latin1_General_BIN2 collation.


The following data types are supported:


¦ Binary and varbinary


¦ Bit


¦ Char and varchar


¦ Date


¦ Datetime and datetime2


¦ Datetimeoffset


¦ Decimal


¦ Float and real


¦ Int, bigint, smallint, and tinyint


¦ Money and smallmoney


¦ Nchar and nvarchar


¦ Smalldatetime


¦ Time


Query Processing


Query processing in Parallel Data Warehouse is more complex than in an SMP data warehouse

because processing must manage high availability, parallelization, and data movement

between nodes. In general, Parallel Data Warehouse’s control node follows these steps to

process a query (shown in Figure 6-5):


1. Parse the SQL statement.


2. Validate and authorize the objects.


3. Build a distributed execution plan.


4. Run the execution plan.


5. Aggregate query results.


6. Send results to the client application.


Client

Management

Compute

Control

Compute

Landing Zone

Compute

Backup

Compute

Appliance

Create query plan

User query

Query results

Aggregate query results Compute nodes

process query plan

operations in parallel


FIGURE 6-5 Query processing steps


A query with a simple join on columns of replicated tables or distribution columns of distributed

tables does not require the transfer of data between compute nodes before executing

the query. By contrast, a more complex join that includes a nondistribution column of a

distributed table does require Parallel Data Warehouse to copy data among the distributions

before executing the query.


Data Load Processing


The design of data load processing in Parallel Data Warehouse takes full advantage of the

parallel architecture to move data to the compute nodes. You have several options for loading

data into your data warehouse. You can use your ETL process to copy files to the Parallel


Data Warehouse’s Landing Zone. You then invoke a command-line tool, DWLoader, and specify

options to load the data into the appliance. Or you can use Integration Services to move

data to the Landing Zone and call the loading functionality directly. To load small amounts of

data, you can connect to the control node and use the SQL INSERT statement.


Queries can run concurrently with load processing, so your data warehouse is always available

during ETL processing. DWLoader loads table rows in bulk into an existing table in the

appliance. You have several options for loading rows into a table. You can add all rows to the

end of the table by using append mode. Another option is to append new rows and update

existing rows by using upsert mode. A third option is to delete all existing rows first and then

to insert all rows into an empty table by using reload mode.


Monitoring and Management


Parallel Data Warehouse includes the Admin Console, a Web-based application with which

you can monitor the health of the appliance, query execution status, and view other information

useful for tuning user queries. This application runs on IIS on the control node and is

accessible by using Internet Explorer.


The Admin Console allows you to view these options:


¦ Appliance Dashboard Displays status details, such as utilization metrics for CPUs,

disks, and the network, and displays activity on the nodes


¦ Queries Activity Displays a list of running queries and queries recently completed,

with related errors, if any, and provides the ability to drill down to details to view the

query execution plan and node execution information


¦ Load Activity Displays load plans, the current state of loads, and related errors, if any


¦ Backup and Restore Displays a log of backup operations


¦ Active Locks Displays a list of locks across all nodes and their current status


¦ Active Sessions Displays active user sessions to aid monitoring of resource contention


¦ Application Errors Displays error event information


¦ Node Health Displays hardware and software alerts and allows an administrator to

view the health of specific nodes


To manage database objects, you might need to query the tables or view the objects. The

version of SQL Server Management Studio included with SQL Server 2008 R2 is not currently

compatible with Parallel Data Warehouse, but you can still use other tools. For example, you

can use a command-line utility, Dwsql, to query a table. Using Dwsql is similar to using Sqlcmd.

An alternative with a graphical user interface is the Nexus query tool from Coffing Data

Warehousing (Coffing DW), which is distributed with each appliance installation. This tool operates

much like SQL Server Management Studio (SSMS) by allowing you to navigate through

an object explorer to find tables and views and to run queries interactively.


Business Intelligence Integration


Parallel Data Warehouse integrates with the SQL Server business intelligence (BI) components—

Integration Services, Reporting Services, and SQL Server Analysis Services.


Integration Services


Integration Services is the ETL component of SQL Server. You use Integration Services packages

to extract and merge data from multiple data sources and to filter and cleanse your

data before loading it into the data warehouse. In SQL Server 2008 R2, Integration Services

includes the SQL Server Parallel Data Warehouse connection manager and the SQL Server

Parallel Data Warehouse Destination as new components that you use in Integration Services

packages to load data into Parallel Data Warehouse. This new data destination provides optimized

throughput and very fast performance because it loads data directly and quickly into

the target database. You also have the option to deploy packages to the Landing Zone.


Reporting Services


You can use Parallel Data Warehouse as a data source for reports that you develop for Reporting

Services using the Report Designer in Business Intelligence Development Studio or

SQL Server 2008 R2 Report Builder 3.0. The Parallel Data Warehouse data source extension

provides support for the graphical query designer, parameterized queries, and basic transactions,

but it does not support Windows integrated security or advanced transactions. To

use the Parallel Data Warehouse data source extension, you must install the ADO.NET data

provider for Parallel Data Warehouse on the report server and each computer on which you

create reports.


You can also use Parallel Data Warehouse as a source for report models. By using Report

Manager or the report server API, you can generate a model from a Parallel Data Warehouse

database. For more precise control of the model, you can use the Model Designer in Business

Intelligence Development Studio.


Analysis Services and PowerPivot


Parallel Data Warehouse is also a valid data source for Analysis Services databases and Excel

PowerPivot models. Using the OLE DB provider, you can configure an Analysis Services cube

to use either multidimensional online analytical processing (MOLAP) or relational online

analytical processing (ROLAP) storage. When using MOLAP storage, Analysis Services extracts

data from Parallel Data Warehouse and stores it in a separate structure for reporting and

analysis. By contrast, when using ROLAP storage, Analysis Services leaves the data in Parallel

Data Warehouse. At query time, Analysis Services translates the multidimensional expression

(MDX) query into a SQL query, which it sends to the Parallel Data Warehouse control node for

query processing.


125


C H A P T E R 7


Master Data Services


Microsoft SQL Server 2008 R2 Master Data Services (MDS) is another new technology

in the SQL Server family and is based on software from Microsoft’s acquisition of

Stratature in 2007. Just as SQL Server Reporting Services (SSRS) is an extensible reporting

platform that ships with ready-to-use applications for end users and administrators, MDS

is both an extensible master data management platform and an application for developing,

managing, and deploying master data models. MDS is included with the Datacenter,

Enterprise, and Developer editions of SQL Server 2008 R2.


Master Data Management


In the simplest sense, master data refers to nontransactional reference data. Put another

way, master data represents the business entities—people, places, or things—that

participate in a transaction. In a data mart or data warehouse, master data becomes

dimensions. Master data management is the set of policies and procedures that you

use to create and maintain master data in an effort to overcome the many challenges

associated with managing master data. Because it’s unlikely that a single set of policies

and procedures would apply to all master data in your organization, MDS provides the

flexibility you need to accommodate a wide range of business requirements related to

master data management.


Master Data Challenges


As an organization grows, the number of line-of-business applications tends to increase.

Furthermore, data from these systems flows into reporting and analytical solutions.

Often, the net result of this proliferation of data is duplication of data related to key

business entities, even though each system might maintain only a subset of all possible

data for any particular entity type. For example, customer data might appear in a sales

application, a customer relationship management application, an accounting application,

and a corporate data warehouse. However, there might be fields maintained in one application

that are never used in the other applications, not to mention information about

customers that might be kept in spreadsheets independent of any application. None of

the systems individually provide a complete view of customers, and the multiple systems

quite possibly contain conflicting information about specific customers.


126 CHAPTER 7 Master Data Services


This scenario presents additional problems for operational master data in an organization

because there is no coordination across multiple systems. Business users cannot be

sure which of the many available systems has the correct information. Moreover, even when

a user identifies a data quality problem, the process for properly updating the data is not

always straightforward or timely, nor does fixing the data in one application necessarily ripple

through the other applications to keep all applications synchronized.


Compounding the problems further is data that has no official home in the organization’s

data management infrastructure. Older data might be archived and no longer available in

operational systems. Other data might reside only in e-mail or in a Microsoft Access database

on a computer sitting under someone’s desk.


Some organizations try their best not to add another system dedicated to master data

management to minimize the number of systems they must maintain. However, ultimately

they find that neither existing applications nor ETL processes can be sufficiently extended to

accommodate their requirements. Proper master data management requires a wide range of

functionality that is difficult, if not impossible, to replicate through minor adaptations to an

organization’s technical infrastructure.


Last, the challenges associated with analytic master data stem from the need to manage

dimensions more effectively. For example, analysts might require certain attributes in a

business intelligence (BI) solution, but these attributes might have no source in the line-ofbusiness

applications on which the BI solution is built. In such a case, the ETL developer can

easily create a set of static attributes to load into the BI solution, but what happens when

the analyst wants to add more attributes? Moreover, how gracefully can that solution handle

changes to hierarchical structures?


Key Features of Master Data Services


The goal of MDS is to address the challenges of both operational and analytical master data

management by providing a master data hub to centrally organize, maintain, and manage

your master data. This master data hub supports these capabilities with a scalable and extensible

infrastructure built on SQL Server and the Windows Communication Foundation (WCF)

APIs. By centralizing the master data in an external system, you can more easily align all business

applications to this single authoritative source. You can adapt your business processes to

use the master data hub as a System of Entry that can then update downstream systems. Another

option is to use it as a System of Record to integrate data from multiple source systems

into a consolidated view, which you can then manage more efficiently from a central location.

Either way, this centralization of master data helps you improve and maintain data quality.


Because the master data hub is not specific to any domain, you can organize your master

data as you see fit, rather than force your data to conform to a predefined format. You can

easily add new subject areas as necessary or make changes to your existing master data to

meet unique requirements as they arise. The master data hub is completely metadata driven,

so you have the flexibility you need to organize your master data.


Master Data Services Components CHAPTER 7 127


In addition to offering flexibility, MDS allows you to manage master data proactively.

Instead of discovering data problems in failed ETL processes or inaccurate reports, you can

engage business users as data stewards. As data stewards, they have access to Master Data

Manager, a Web application that gives them ownership of the processes that identify and

react to data quality issues. For example, a data steward can specify conditions that trigger

actions, such as creating a default value for missing data, sending an e-mail notification, or

launching a workflow. Data stewards can use Master Data Manager not only to manage data

quality issues, but also to edit master data by adding new members or changing values. They

can also enhance master data with additional attributes or hierarchical structures quickly and

easily without IT support. Using Master Data Manager, data stewards can also monitor changes

to master data through a transaction logging system that tracks who made a change, when

the change was made, which record was changed, and what the value was both before and

after the change. If necessary, the data steward can even reverse a change.


MDS uses Windows integrated security for authentication and a fine-grained, role-based

system for authorization that allows administrators to give the right people the direct access

they need to manage and update master data. As an administrator, you can grant broad access

to all objects in a model, or you can restrict users to specific rows and columns in a data set.


To capture the state of master data at specific points in time, MDS allows administrators

to create versions of the master data. As long as a version has an Open status, anyone with

access to the model can make changes to it. Then you can lock the version for validation and

correction, and commit the version when the model is ready use. If requirements change

later, you copy a committed version and start the process anew.


Because MDS is a platform, not simply an application, you can use the API to integrate

your existing applications with MDS and automate the import or export processes. Anything

that you can do by using Master Data Manager can be built into your own custom application

because the MDS API supports all operations. This capability also enables Microsoft partners

to quickly build master data support into their applications with domain-specific user interfaces

and transparent application integration.


Master Data Services Components


Although MDS is included on the SQL Server installation media, you perform the MDS installation

separately from the SQL Server installation by using a wizard interface. The wizard

installs Master Data Services Configuration Manager, installs the files necessary to run the

Master Data Services Web service, and registers assemblies. After installation, you use the

Master Data Services Configuration Manager to create and configure a Master Data Services

database in a SQL Server instance that you specify, create the Master Data Services Web application,

and enable the Web service.


Master Data Services Configuration Manager


Before you can start using MDS to manage your master data, you use Master Data Services

Configuration Manager. This configuration tool includes pages to create the MDS database,

configure the system settings for all Web services and applications that you associate with

that database, and configure the Master Data Services Web application.


On the Databases page of Master Data Services Configuration Manager, you specify the

SQL Server instance to use for the new MDS database and launch the process to create the

database. After creating the database, you can modify the system settings that govern all

MDS Web applications that you establish on the same server. You configure system settings

to set thresholds, such as time-out values or the number of items to display in a list.

You can also use system settings to manage application behavior, such as whether users can

copy committed model versions or any model version and whether the staging process logs

transactions. For e-mail notifications, you can configure system settings to include a URL to

Master Data Manager in e-mails, to manage the frequency of notifications, and whether to

send e-mails in HTML or text format, among other settings. Most settings are configurable by

using Master Data Services Configuration Manager. You can change values for other settings

directly in the System Settings table in the MDS database.


On the Web Configuration page of Master Data Services Configuration Manager, you associate

the Master Data Services Web application, Master Data Manager, with an existing Web

site or create a new Web site and application pool for it. You can also opt to enable the Web

service for Master Data Manager to support programmatic access to the application.


The Master Data Services Database


The MDS database is the central repository for all information necessary to support the Master

Data Manager application and the MDS Web service. This database stores application settings,

metadata tables, and all versions of the master data. In addition, it contains tables that

MDS uses to stage data from source systems and subscription views for downstream systems

that consume master data.


Master Data Manager


Master Data Manager is a Web application that serves as a stewardship portal for business

users and a management interface for administrators. Master Data Manager includes the following

five functional areas:


¦ Explorer Use this area to change attributes, manage hierarchies, apply business rules

to validate master data, review and correct data quality issues, annotate master data,

monitor changes, and reverse transactions.


¦ Version Management Use this area to create a new version of your master data

model and underlying data, uncover all validation issues in a model version, prevent

users from making changes, assign a flag to indicate the current version for subscribing

systems, review changes, and reverse transactions.


¦ Integration Management Use this area to create and process batches for importing

data from staging tables into the MDS database, view errors arising from

the import process, and create subscription views for consumption of master data by

operational and analytic applications.


¦ System Administration Use this area to create a new model and its entities and

attributes, define business rules, configure notifications for failed data validation, and

deploy a model to another system.


¦ User And Group Permissions Use this area to configure security for users and

groups to access functional areas in Master Data Manager, to perform specific functions,

and to restrict or deny access to specific model objects.


Data Stewardship


Master Data Manager is the data stewardship portal in which authorized business users can

perform all activities related to master data management. At minimum, a user can use this

Web application to review the data in a master data model. Users with higher permissions can

make changes to the master data and its structure, define business rules, review changes to

master data, and reverse changes.


Model Objects


Most activities in MDS revolve around models and the objects they contain. A model is a

container for all objects that define the structure of the master data. A model contains at least

one entity, which is analogous to a table in a relational database. An entity contains members,

which are like the rows in a table, as shown in Figure 7-1. Members (also known as leaf members)

are the master data that you are managing in MDS. Each leaf member of the entity has

multiple attributes, which correspond to table columns in the analogy.


Attributes

Members


FIGURE 7-1 The Product entity


By default, an entity has Name and Code attributes, as shown in Figure 7-1. These two attributes

are required by MDS. The Code attribute values must be unique, in the same way that

a primary key column in a table requires unique values. You can add any number of additional

free-form attributes to accept any type of data that the user enters; the Name attribute

of the Product entity shown in Figure 7-1 is one such attribute.


An entity can also have any number of domain-based attributes whose values are members

of another related entity. In the example in Figure 7-1, the ProductSubCategory attribute

is a domain-based attribute. That is, the ProductSubCategory codes are attribute values in the

Product entity, and they are also members of the ProductSubCategory entity. A third type of

attribute is the file attribute, which you can use to store a file or image.


You have the option to organize attributes into attribute groups. Each attribute group contains

the name and code attributes of the entity. You can then assign the remaining attributes

to one or more attribute groups or not at all. Attribute groups are securable objects.


You can organize members into hierarchies. Figure 7-2 shows partial data from two types

of hierarchies. On the left is an explicit hierarchy, which contains all members of a single entity.

On the right is a derived hierarchy, which contains members from multiple, related entities.


FIGURE 7-2 Product hierarchies


In the explicit hierarchy, you create consolidated members to group the leaf members. For

example, in the Geography hierarchy shown in Figure 7-2, North America, United States, and

Bikes are all consolidated members that create multiple levels for summarization of the leaf

members.


In a derived hierarchy, the domain-based attribute values of an entity define the levels. For

example, in the Category hierarchy in the example, Wholesale is in the ProductGroup entity,

which in turn is a domain-based attribute of the ProductCategory entity of which Components

is a member. Likewise, the ProductCategory entity is a domain-based attribute of the

ProductSubCategory entity, which contains Forks as a member. The base entity, Product,

includes ProductSubCategory as a domain-based attribute.


Regardless of hierarchy type, each hierarchy contains all members of the associated entities.

When you add, change, or delete a member, all hierarchies to which the member belongs

will also update to maintain consistency across hierarchies.


A collection is an alternative way to group members by selecting nodes from existing

explicit hierarchies, as shown in Figure 7-3. Although this example shows only leaf members,

a collection can also contain branches of consolidated members and leaf members. You can

combine nodes from multiple explicit hierarchies into a single collection, but all members

must belong to the same entity.


FIGURE 7-3 A collection


Master Data Maintenance


Master Data Manager is more than a place to define model objects. It also allows you to

create, edit, and update leaf members and consolidated members. When you add a leaf

member, you initially provide values for only the Name and Code attributes, as shown in

Figure 7-4. You can also use a search button to locate and select the parent consolidated

member in each hierarchy.


FIGURE 7-4 Adding a new leaf member


After you save your entry, you can edit the remaining attribute values immediately or at a

later time. Although a member can have hundreds of attributes and belong to multiple hierarchies,

you can add the new member without having all of this information at your fingertips;

you can update the attributes at your leisure. MDS always keeps track of the missing

information, displaying it as validation issue information at the bottom of the page on which

you edit the attribute values, as shown in Figure 7-5.


FIGURE 7-5 Attributes and validation issues


Business Rules


One of the goals of a master data management system is to set up data correctly once and to

propagate only valid changes to downstream systems. To achieve this goal, the system must

be able to recognize valid data and to alert you when it detects invalid data. In MDS, you

create business rules to describe the conditions that cause the data to be considered invalid.

For example, you can create a business rule that specifies the required attributes (also known

as fields) for an entity. A business entity is likely to have multiple business rules, which you can

sequence in order of priority, as shown in Figure 7-6.


FIGURE 7-6 The Product entity’s business rules


Figure 7-7 shows an example of a simple condition that identifies the required fields for the

Product entity. If you omit any of these fields when you edit a Product member, MDS notes

a validation issue for that member and prevents you from using the master data model until

you supply the missing values.


FIGURE 7-7 The Required Fields business rule


When creating a business rule, you can use any of the following types of actions:


¦ Default Value Sets the default value of an attribute to blank, a specific value that

you supply in the business rule, a generated value that increments from a specified

starting value, or a value derived by concatenating multiple attribute values


¦ Change Value Updates the attribute value to blank, another attribute value, or a

value derived by concatenating multiple attribute values


¦ Validation Creates a validation warning and, if you choose, sends a notification

e-mail to a specified user or group


¦ External Action Starts a workflow at a specified Microsoft SharePoint site or

initiates a custom action


Because users can add or edit data only while the master data model version is open,

invalid data can exist only while the model is still in development and unavailable to other

systems. You can easily identify the members that pass or fail the business rule validation

when you view a list of members in Explorer, as shown in Figure 7-8. In this example, the first

two records are in violation of one or more of the business rules. Remember that you can see

the specific violation issues for a member when you open it for editing.


FIGURE 7-8 Business rule validation


Transaction Logging


MDS uses a transaction log, as shown in Figure 7-9, to capture every change made to master

data, including the master data value before and after the change, the user who made the

change (not shown), the date and time of the change, and other identifying information

about the master data. You can access this log to view all transactions for a model by version

in the Version Management area of Master Data Manager. If you find that a change was made

erroneously, you can select the transaction in the log and click the Undo button above the

log to restore the prior value. The transaction log also includes the reversals you make when

using this technique.


FIGURE 7-9 The transaction log


MDS allows you to annotate any transaction so that you can preserve the reasons for a

change to the master data. When you select a transaction in the transactions log, a new section

appears at the bottom of the page for transaction annotations. Here you can view the

complete set of annotations for the selected transaction, if any, and you can enter text for a

new annotation, as shown in Figure 7-10.


FIGURE 7-10 A transaction annotation


Integration


Master Data Manager also provides support for data integration between MDS and other applications.

Master Data Manager includes an Integration Management area for importing and

exporting data. However, the import and export processes here are nothing like those of the

SQL Server Import And Export wizard. Instead, you use the Import page in Master Data Manager

to manage batch processing of staging tables that you use to load the MDS database,

and you use the Export page to configure subscription views that allow users and applications

to read data from the MDS database.


Importing Master Data


Rather than manually entering the data by using Master Data Manager, you can import your

master data from existing data sources by staging the data in the MDS database. You can

stage the data by using either the SQL Server Import And Export wizard or SQL Server Integration

Services. After staging the data, you use Master Data Manager to process the staged

data as a batch. MDS moves valid data from the staging tables into the master data tables in

the MDS database and flags any invalid records for you to correct at the source and restage.


You can use any method to load data into the staging tables. The most important part of

this task is to ensure that the data is correct in the source and that you set the proper values

for the columns that provide information to MDS about the master data. For example, each

record must identify the model into which you will load the master data. When staging data,

you use the following tables in the MDS database as appropriate to your situation:


¦ tblSTGMember Use this table to stage leaf members, consolidated members, or

collections. You provide only the member name and code in this table.


¦ tblSTGMemberAttribute Use this table to stage the attribute values for each

member using one row per attribute, and include the member code to map the attribute

to the applicable member.


¦ tblSTGRelationship Use this table to stage parent-child or sibling relationships

between members in a hierarchy or a collection.


NOTE For detailed information about the table columns and valid values for required

columns, refer to the “Master Data Services Database Reference” topic in SQL Server 2008

R2 Books Online at http://msdn.microsoft.com/en-us/library/ee633808(SQL.105).aspx.


The next step is to use Master Data Manager to create a batch. To do this, you identify

the model and the version that stores the master data for the batch. The version must have

a status of either Open or Locked to import data from a staging table. On your command to

process the batch, MDS attempts to locate records in the staging tables that match the specified

model and load them into the tables corresponding to the model and version that you


selected. When the batch processing is complete, you can review the status of the batch in

the staging batch log, which is available in Master Data Manager, as shown in Figure 7-11.


FIGURE 7-11 The staging batch log


If the log indicates any errors for the staging batch, you can select the batch in the log and

then view the Staging Batch Errors page to see a description of the error for each record that

did not successfully load into the MDS database. You can also check the Status_ID column of

the staging table to distinguish between successful and failed records, which have a column

value of 1 and 2, respectively. At this point, you should return to the source system and

update the pertinent records to correct the errors. The next steps would be to truncate the

staging table to remove all records and finally to load the updated records. At this point, you

can create a new staging batch and repeat the process until all records successfully load.


Exporting Master Data


Of course, MDS is not a destination system for your master data. It can be both a system

of entry and a system of record for applications important to the daily operations of your

organization, such as an enterprise resource planning (ERP) system, a customer relationship

management (CRM) system, or a data warehouse. After you commit a model version, your

master data is available to other applications through subscription views in the MDS database.

Any system that can consume data from SQL Server can use these views to access up-to-date

master data.


To create a subscription view in Master Data Manager, you start by assigning a name to

the view and selecting a model. You then associate the view with a specific version or a version

flag.


TIP You can simplify the administration of a subscription view by associating it with a

version flag rather than a specific version. As the version of a record changes over time,

you can simply reset the flag for the versions. If you don’t use version flags, a change in

version requires you to update every subscription view that you associate with the version,

which could be a considerable number.


Next, you select either an entity or a derived hierarchy as the basis for the view and the

format of the view. For example, if you select an entity, you can format the view to use leaf

members, consolidated members, or collection members and the associated attribute values.

When you save the view, it is immediately available in the MDS database to anyone (or

any application) with Read access to the database. For example, after creating the Product


subscription view in Master Data Manager as an entity-based leaf member view, you can

query the Product view and see the results in SQL Server Management Studio, as shown in

Figure 7-12.


FIGURE 7-12 Querying the Product subscription view


Administration


Of course, Master Data Manager supports administrative functions, too. Administrators use

it to manage the versioning process of each master data model and to configure security for

individual users and groups of users. When you need to make a copy of a master data model

on another server, as you would when you want to recreate your development environment on

a production server, you can use the model deployment feature in Master Data Manager.


Versions


MDS uses a versioning management process to support multiple copies of master data. With

versioning, you can maintain an official working copy of master data that no one can change,

alongside historical copies of master data for reference and a work-in-progress copy for use

in preparing the master data for changing business requirements.


MDS creates the initial version when you create a model. Anyone with the appropriate permissions

can populate the model with master data and make changes to the model objects

in this initial version until you lock the version. After that, only users with Update permissions

on the entire model can continue to modify the data in the locked version to add missing

information, fix any business rule violation, or revert changes made to the model. If necessary,

you can temporarily unlock the version to allow other users to correct the data.


When all data validates successfully, you can commit the version. Committing a version

prevents any further changes to the model and allows you to make the version available to

downstream systems through subscriptions. You can use a flag, as shown in Figure 7-13, to

identify the current version to use so that subscribing systems do not need to track the current

version number themselves. If you require any subsequent changes to the model, you


create a new version by copying a previously committed version and allowing users to make

their changes to the new version.


FIGURE 7-13 Model versions


Security


MDS uses a role-based authorization system that allows you to configure security both by

functional area and by object. For example, you can restrict a user to the Explorer area of

Master Data Manager, as shown in Figure 7-14, while granting another user access to only the

Version Management and Integration Management areas. Then, within the functional area,

you must grant a user access to one or more models to control which data the user can see

and which data the user can edit. You must assign the user permission to access at least one

functional area and one model for that user to be able to open Master Data Manager.


FIGURE 7-14 Functional area permissions


You can grant a user either Read-only or Update permissions for a model. That permission

level applies to all objects in the model unless you specifically override the permissions for

a particular object; the new permission cascades downward to lower level objects. Similarly,

you can grant permissions on specific members of a hierarchy and allow the permissions to

cascade to members at lower levels of the hierarchy.


To understand how security works in MDS, let’s configure security for a sample user and

see how the security settings affect the user experience. As you saw earlier in Figure 7-14,

the user can access only the Explorer area in Master Data Manager. Accordingly, that is the

only functional area that is visible when the user accesses Master Data Manager, as shown in


Figure 7-15. An administrator with full access privileges would instead see the full list of functional

areas on the home page.


FIGURE 7-15 The Master Data Manager home page for a user with only Explorer permissions


Data security begins at the model level. When you deny access to a model, the user does

not even see it in Master Data Manager. With Read-only access, a user can view the model

structure and its data but cannot make changes. Update permissions allow a user to see the

data as well as make changes to it. To continue the security example, Figure 7-16 shows that

this user has Read-only permissions for the Product model (as indicated by the lock icon) and

Deny permissions on all other models (as indicated by the stop symbol) in the Model Permissions

tree view on the left. In the Model Permissions Summary table on the right, you can

see the assigned permissions at each level of the model hierarchy. Notice that the user has

Update permission on leaf members of the ProductCategory entity.


FIGURE 7-16 A user’s model permissions


With Read-only access to the model, except for the ProductCategory entity, the user

can view data for all other entities or hierarchies, such as Color, as shown in Figure 7-17, but

cannot edit the data in any way. Notice the lock icons in the Name and Code columns in the


Color table on the right side of the page. These icons indicate that the values in the table are

not editable. The first two buttons above the table allow a user with Update permissions to

add or delete a member, but those buttons are unavailable here because the user has Readonly

permission. The user can also navigate through the hierarchy in the tree view on the left

side of the page, but the labels are gray to indicate the Read-only status for every member of

the hierarchy.


FIGURE 7-17 Read-only permission on a hierarchy


At this point in the example, the user has Update permission on the ProductCategory entity,

which allows the user to edit any member of that entity. However, you can apply a more

granular level of security by changing permissions of individual members of the entity within

a hierarchy. As shown in Figure 7-18, you can override the Update permission at the entity

level by specifying Read-only permission on selected members. The tree view on the left side

of the page shows a lock icon for the members to which Read-only permissions apply and a

pencil icon for the members for which the user has Update permissions.


FIGURE 7-18 Member permissions within a hierarchy


More specifically, the security configuration allows this user to edit only the Bikes and Accessories

categories in the Retail group, but the user cannot edit categories in the Wholesale

group. Let’s look first at the effect of these permissions on the user’s experience on the ProductCategory

page (shown in Figure 7-19). The lock icon in the first column indicates that the

Components and Clothing categories are locked for editing. However, the user has Update

permission for both Bikes and Accessories, and can access the member menu for either of

these categories. The member menu, as shown in the figure, allows the user to edit or delete

the member, view its transactions, and add an annotation. Furthermore, the user can add new

members to the entity.


FIGURE 7-19 Mixed permissions for an entity


Last, Figure 7-20 shows the page for the Category derived hierarchy. Recall from Figure

7-19 that the user has Update permission for the Retail group. The user can therefore modify

the Retail member, but not the Wholesale member, as indicated by the lock icon to the left

of the Wholesale member in the ProductGroup table. You can also see the color-coding of

the labels in the tree view of the Category hierarchy, which indicates whether the member is

editable by the user. The user can edit members that are shown in black, but not the members

shown in gray. When the user selects a member in the tree view, the table on the right

displays the children of the selected member if the user has the necessary permission.


FIGURE 7-20 Mixed permissions for a derived hierarchy


Model Deployment


When you have finalized the master data model structure, you can use the model deployment

capabilities in Master Data Manager to serialize the model and its objects as a package

that you can later deploy on another server. In this way, you can move a master data model

from development to testing and to production without writing any code or moving data

at the table level. The deployment process does not copy security settings. Therefore, after

moving the master data model to the new server, you must grant the users access to functional

areas and configure permissions.


To begin the model deployment, you use the Create Package wizard in the System Administration

area of Master Data Manager. You specify the model and version that you want to

deploy and whether you want to include the master data in the deployment. When you click

Finish to close the wizard, Master Data Manager initiates a download of the package to your

computer, and the File Download message box displays. You can then save the package for

deployment at a later time.


When you are ready to deploy the package, you use the Deploy Package wizard in Master

Data Manager on the target server and provide the wizard with the path to the saved package.

The wizard checks to see whether the model and version already exist on the server. If so,

you have the option to update the existing model by adding new items and updating existing

items. Alternatively, you can create an entirely new model, but if you do so, the relationship

with the source model is then permanently broken, and any subsequent updates to the

source model cannot be brought forward to the copy of the model on the target server.


Programmability


Rather than use Master Data Manager exclusively to perform master data management

operations, you might prefer to automate some operations to incorporate them into a custom

application. Fortunately, MDS is not just an application ready to use after installation, but also

a development platform that you can use to integrate master data management directly into

your existing business processes.


TIP For a code sample that shows how to create a model and add entities to the model,

see the following blog entry by Brent McBride, a Senior Software Engineer on the MDS

team: “Creating Entities using the MDS WCF API,” at http://sqlblog.com/blogs/mds_team

/archive/2010/01/29/creating-entities-using-the-mds-wcf-api.aspx.


The Class Library


The MDS API allows you to fully customize any or all activities necessary to create, populate,

maintain, manage, and secure master data models and associated data. To build your own

data stewardship or management solution, you use the following namespaces:


¦ Microsoft.MasterDataServices.Services Contains a class to provide instances

of the MdsServiceHost class and a class to provide an API for operations related to

business rules


¦ Microsoft.MasterDataServices.Services.DataContracts Contains classes to

represent models and model objects


¦ Microsoft.MasterDataServices.Services.MessageContracts Contains classes to

represent requests and responses resulting from MDS operations


¦ Microsoft.MasterDataServices.Services.ServiceContracts Contains an interface

that defines the service contract for MDS operations based on WCF related to

business rules, master data, metadata, and security


NOTE For more information about the MDS class libraries, refer to the “Master Data Services

Class Library” topic in SQL Server 2008 R2 Books Online at http://msdn.microsoft.com

/en-us/library/ee638492(SQL.105).aspx.


Master Data Services Web Service


MDS includes a Web services API as an option for creating custom applications that integrate

MDS with an organization’s existing applications and processes. This API provides access to

the master data model definitions, as well as to the master data itself. For example, by using

this API, you can completely replace the Master Data Manager Web application.


TIP For a code sample that shows how to use the Web service in a client application,

see the following blog entry by Val Lovicz, Principal Program Manager on the MDS team:

“Getting Started with the Web Services API in SQL Server 2008 R2 Master Data Services,”

at http://sqlblog.com/blogs/mds_team/archive/2010/01/12/getting-started-with-the-webservices-

api-in-sql-server-2008-r2-master-data-services.aspx.


Matching Functions


MDS also provides you with several new Transact-SQL functions that you can use to match

and cleanse data from multiple systems prior to loading it into the staging tables:


¦ Mdq.NGrams Outputs a stream of tokens (known as a set of n-grams) in the length

specified by n for use in string comparisons to find approximate matches between strings


¦ Mdq.RegexExtract Finds matches by using a regular expression


¦ Mdq.RegexIsMatch Indicates whether the regular expression finds a match by

using a regular expression


¦ Mdq.RegexIsValid Indicates whether the regular expression is valid


¦ Mdq.RegexMask Converts a set of regular expression option flags into a binary

value


¦ Mdq.RegexMatches Finds all matches of a regular expression in an input string


¦ Mdq.RegexReplace Replaces matches of a regular expression in an input string

with a different string


¦ Mdq.RegexSplit Splits an input string into an array of strings based on the positions

of a regular expression within the input string


¦ Mdq.Similarity Returns a similarity score between two strings using a specified

matching algorithm


¦ Mdq.SimilarityDate Returns a similarity score between two date values


¦ Mdq.Split Splits an input string into an array of strings using specified characters as

a delimiter


NOTE For more information about the MDS functions, refer to the “Master Data

Services Functions (Transact-SQL)” topic in SQL Server 2008 R2 Books Online at

http://msdn.microsoft.com/en-us/library/ee633712(SQL.105).aspx.


145


C H A P T E R 8


Complex Event Processing

with StreamInsight


Microsoft SQL Server StreamInsight is a complex event processing (CEP) engine. This

technology is a new offering in the SQL Server family, making its first appearance

in SQL Server 2008 R2. It ships with the Standard, Enterprise, and Datacenter editions of

SQL Server 2008 R2. StreamInsight is both an engine built to process high-throughput

streams of data with low latency and a Microsoft .NET Framework platform for developers

of CEP applications. The goal of a CEP application is to rapidly aggregate high

volumes of raw data for analysis as it streams from point to point. You can apply analytical

techniques to trigger a response upon crossing a threshold or to find trends or exceptions

in the data without first storing it in a data warehouse.


Complex Event Processing


Complex event processing is the task of sifting through streaming data to find meaningful

information. It might involve performing calculations on the data to derive information,

or the information might be the revelation of significant trends. As a development platform,

StreamInsight can support most types of CEP applications that you might need.


Complex Event Processing Applications


There are certain industries that regularly produce high volumes of streaming data.

Manufacturing and utilities companies use sensors, meters, and other devices to monitor

processes and alert users when the system identifies events that could lead to a potential

failure. Financial trading firms must monitor market prices for stocks, commodities,

and other financial instruments and rapidly calculate profits or losses based on changing

conditions.


146 CHAPTER 8 Complex Event Processing with StreamInsight


Similarly, there are certain types of applications that benefit from the ability to analyze

data as close as possible to the time that the applications capture the data. For example,

companies selling products online often use clickstream analysis to change the page layout

and site navigation and to display targeted advertising while a user remains connected to a

site. Credit card companies monitor transactions for exceptions to normal spending activities

that could indicate fraud.


The challenge with CEP arises when you need to process and analyze the data before

you have time to perform ETL activities to move the data into a more traditional analytical

environment, such as a data warehouse. In CEP applications, the value of the information

derived from low-latency processing, defined in milliseconds, can be extremely high. This

value begins to diminish as the data ages. Adding to the challenge is the rate at which source

applications generate data, often tens of thousands of records per second.


StreamInsight Highlights


StreamInsight’s CEP server includes a core engine that is built to process high-throughput

data. The engine achieves high performance by executing highly parallel queries and using

in-memory caches to avoid incurring the overhead of storing data for processing. The engine

can handle data that arrives at a steady rate or in intermittent bursts, and can even rearrange

data that arrives out of sequence. Queries can also incorporate nonstreaming data sources,

such as master reference data or historical data maintained in a data warehouse.


You write your CEP applications using a .NET language, such as Visual Basic or C#, for rapid

application development. In your applications, you embed declarative queries using Language

Integrated Query (LINQ) expressions to process the data for analysis.


StreamInsight also includes other tools for administration and development support. The

CEP server has a management interface and diagnostic views that you can use to develop

applications to monitor StreamInsight. For development support, StreamInsight includes an

event flow debugger that you can use to troubleshoot queries. An example of a situation that

might require troubleshooting is the arrival of a larger number of events than expected.


StreamInsight Architecture


As with any new technology, you will find it helpful to have an understanding of the StreamInsight

architecture before you begin development of your first CEP application. Your application

must restructure data streams to a format usable by the processing engine. You use

adapters to perform this restructuring before passing the data to queries that run on the CEP

server. The way you choose to develop your application also depends on the deployment

model you use to implement StreamInsight.


StreamInsight Architecture CHAPTER 8 147


Data Structures


The high-throughput data that StreamInsight requires is known as a stream. More specifically,

a stream is a collection of data that changes over time. For example, a Web log contains

data about each server hit, including the date, time, page request, and Internet protocol (IP)

address of the visitor. If a visitor clicks on several pages in the Web site, the Web log contains

multiple lines, or hits, for the same visitor, and each line records a different time. The information

in the Web log shows how each user’s activity in a Web site changes over time, which

is why this type of information is considered a stream. You can query this stream to find the

average number of hits or the top five referring sites over time.


StreamInsight splits a stream into individual units called events. An event contains a header

and a payload. The event header includes the event kind and one or more timestamps for the

event. The event kind is an indicator of a new event or the completeness of events already in

the stream. The payload contains the event’s data as a .NET data structure.


There are three types of event models that StreamInsight uses. The interval event model

represents events with a fixed duration, such as a stock bid price that is valid only for a certain

period of time. The edge event model is another type of duration model, but it represents an

event with a duration that is unknown at the time the event starts, such as a Web user session.

The point model represents events that occur at a specific point in time, such as a Web user’s

click entry in a Web log.


The CEP Server


The CEP server is a run-time engine and a set of adapter instances that receive and send

events, as shown in Figure 8-1. You develop these adapters in a .NET language and register

the assemblies on the CEP server, which then instantiates the adapters at run time. Input

adapters receive data as a continuous stream from event stores, such as sensors on a factory

floor, Web servers, data feeds, or databases. The data passes from the input adapter to the

CEP engine, which processes and transforms the data by using standing queries, which are

query instances that the CEP engine manages. The engine then forwards the query results

to output adapters, which connect to event consumers, such as pagers, monitoring devices,

dashboards, and databases. The output adapters can also include logic to trigger a response

based on the query results.


Pagers and

monitoring devices

Input Adapters

Data feeds Event stores

and databases

Web servers Devices

and sensors

Event Event Event Event

CEP Engine

Standing Queries

Event

Event

Event

Event Event

Output Adapters

CEP Application

at Run Time

Static

reference data

Event Sources

Event stores

and databases

KPI dashboards

and SharePoint UI

Event Targets


FIGURE 8-1 StreamInsight architecture


Input Adapters


The input adapters translate the incoming events into the event format that the CEP engine

requires. You can create a typed adapter if the source produces a single event type only, but

you must create an untyped adapter when the payload format differs across events or is unknown

in advance. In the case of the typed adapter, the payload format is defined in advance

with a static number of fields and data types when you implement the adapter. By contrast,

an untyped adapter receives the payload format only when the adapter binds to the query (as

part of a configuration specification). In the latter case, the number of fields and data types

can vary with each query instantiation.


Output Adapters


The output adapters reverse the operations of the input adapters by translating events into a

format that is usable by the target device and then sending the translated data to the device.

The development process for an output adapter is very similar to the process you use to

develop an input adapter.


Query Instances


Standing queries receive the stream of data from an input adapter, apply business logic to the

data (such as an aggregation), and send the results as an event stream to an output adapter.

You encapsulate the business logic used by a standing query instance in a query template

that you develop using a combination of LINQ and a .NET language. To create the standing

query instance in the CEP server, you bind a query template with specific input and output.

You can use the same query template with multiple standing queries. After you instantiate a

query, you are can start, stop, or manage it.


Deployment Models


You have two options for deploying StreamInsight. You can integrate the CEP server into an

application as a hosted assembly, or you can deploy it as a standalone server.


Hosted Assembly


Embedding the CEP server into a host application is a simple deployment approach. You

have greater flexibility than you would have with a standalone server because there are no

dependencies between applications that you must consider before making changes. Each

application and the CEP server run as a single process, which may be easier to manage on

your server.


You can use any of the development approaches described later, in the “Application Development”

section of this chapter, when hosting the CEP server in your application. However, if

you decide later that you want your application to run on a standalone server, you will need

to rewrite your application using the explicit server development model.


Standalone Server


You should deploy the CEP server as a standalone server when applications need to share

event streams or metadata objects. For example, you can reuse event types, adapter types,

and query templates and thereby minimize the impact of changes to any of these metadata

objects across applications by maintaining a single copy. You can run the CEP server as an

executable, or you can configure it as a Windows service. If you want to run it as a service

application, you can use StreamInsightHost.exe as a host process or develop your own host

process.


If you choose to deploy CEP as a standalone server, there are some limitations that affect

the way you develop applications. First, you can use only the explicit server development

model (which is described in the next section of this chapter) when developing CEP applications

for a standalone server. Second, you must connect to the CEP server by using the Web

service Uniform Resource Identifier (URI) of the CEP server host process.


Application Development


You start the typical development cycle for a new CEP application by sampling the existing

data streams and developing functions to process the data. You then test the functions, review

the results, and determine the changes necessary to improve the functions. This process

continues in an iterative fashion until you complete development.


As part of the development of your CEP application, you create event types, adapters, and

query templates. The way you use these objects depends on the development model you

choose. When you develop using the explicit server development model, you explicitly create

and register all of these objects and can reuse these objects in multiple applications. In the

implicit server development model, you concentrate on the development of the query logic

and rely on the CEP server to act as an implicit host and to create and register the necessary

objects.


TIP You can locate and download sample applications by searching for StreamInsight at

CodePlex (http://www.codeplex.com).


Event Types


An event type defines events published by the event source or consumed by the event consumer.

You use event types with a typed adapter or as objects in LINQ expressions that you

use in query templates. You create an event type as a .NET Framework class or structure by

using only public fields and properties as the payload fields, like this:


public class sampleEvent

{

public string eventId { get; set; }

public double eventValue { get; set; }

}


An event type can have no more than 32 payload fields. Payload fields must be only scalar

or elementary CLR types. You can use nullable types, such as int? instead of int. The string and

byte[] types are always nullable.


You do not create an event type when your application uses untyped adapters for scenarios

that must support multiple event types. For example, an input adapter for tables in a SQL


Server database must adapt to the schema of the table that it queries. Instead, you provide

the table schema in a configuration specification when the adapter is bound to the query.

Conversely, an untyped output adapter receives the event type description, which contains

a list of fields, when the query starts. The untyped output adapter must then map the event

type to the schema of the destination data source, typically in a configuration specification.


Adapters


Input and output adapters provide transformation interfaces between event sources, event

consumers, and the CEP server. Event sources can push events to event consumers, or event

consumers can pull events from event sources. Either way, the CEP application operates

between these two points and intercepts the events for processing. The input adapter reads

events from the source, transforms them into a format recognizable by the CEP server, and

provides the transformed events to a standing query. As the CEP server processes the event

stream, the output adapter receives the resulting new events, transforms them for the event

consumers, and then delivers the transformed events.


Before you can begin developing an adapter, you must know whether you are building

an input or output adapter. You must also know the event type, which in this context means

you must understand the structure of the event payload and how the application timestamps

affect stream processing. The .NET class or structure of the event type provides you with

information about the event payload if you are building a typed adapter. The information

necessary for the management of stream processing, known as event metadata, comes from

an interface in the adapter API when it creates an event. In addition to knowing the event

payload and event metadata, you must also know whether the shape of the event is a point,

interval, or edge model. Having this information available allows you to choose the applicable

base class. The adapter base classes are listed in Table 8-1.


TABLE 8-1 Adapter base classes


ADAPTER TYPE

AND EVENT MODEL


INPUT ADAPTER

BASE CLASS


OUTPUT ADAPTER

BASE CLASS


Typed point


TypedPointInputAdapter


TypedPointOutputAdapter


Untyped point


PointInputAdapter


PointOutputAdapter


Typed interval


TypedIntervalInputAdapter


TypedIntervalOutputAdapter


Untyped interval


IntervalInputAdapter


IntervalOutputAdapter


Typed edge


TypedEdgeInputAdapter


TypedEdgeOutputAdapter


Untyped edge


EdgeInputAdapter


EdgeOutputAdapter


If you are developing an untyped input adapter, you must ensure that it can use the configuration

specification during query bind time to determine the event’s field types by inference

from the query’s SELECT statement. You must also add code to the adapter to populate


the fields one at a time and enqueue the event. The untyped output adapter works similarly,

but instead it must be able to use the configuration specification to retrieve query processing

results from a dequeued event.


The next step is to develop an AdapterFactory object as a container class for your input

and output adapters. You use an AdapterFactory object to share resources between adapter

implementations and to pass configuration parameters to adapter constructors. Recall that

an untyped adapter relies on the configuration specification to properly handle an event’s

payload structure. The adapter factory must implement the Create() and Dispose() methods

as shown in the following code example, which shows how to create adapters for events in a

text file:


public class TextFileInputFactory : IInputAdapterFactory<TextFileInputConfig>

{

public InputAdapterBase Create(TextFileInputConfig configInfo,

EventShape eventShape, CepEventType cepEventType)

{

InputAdapterBase adapter = default(InputAdapterBase);

if (eventShape == EventShape.Point)

{

adapter = new TextFilePointInput(configInfo, cepEventType);

}

else if (eventShape == EventShape.Interval)

{

adapter = new TextFileIntervalInput(configInfo, cepEventType);

}

else if (eventShape == EventShape.Edge)

{

adapter = new TextFileEdgeInput(configInfo, cepEventType);

}

else

{

throw new ArgumentException(

string.Format(CultureInfo.InvariantCulture,

“TextFileInputFactory cannot instantiate adapter with event shape {0}”,

eventShape.ToString()));

}

return adapter;

}

public void Dispose()

{

}

}


The final step is to create a .NET assembly for the adapter. At minimum, the adapter

includes a constructor, a Start() method, a Resume() method, and either a ProduceEvents() or

ConsumeEvents() method, depending on whether you are developing an input adapter or an

output adapter. You can see the general structure of the adapter class in the following code

example:


public class TextFilePointInput : PointInputAdapter

{

public TextFilePointInput(TextFileInputConfig configInfo,

CepEventType cepEventType)

{ … }

public override void Start()

{ … }

public override void Resume()

{ … }

private void ProduceEvents()

{ … }

}


Using the constructor method for an untyped adapter, such as TextFilePointInput as in the

example, you can pass the configuration parameters from the adapter factory and the event

type object that passes from the query binding. The constructor also includes code to connect

to the event source and to map fields to the event payload. After the CEP server instantiates

the adapter, it invokes the Start() method, which generally calls the ProduceEvents()

or ConsumeEvents()method to begin receiving streams. The Resume() method invokes the

ProduceEvents() or ConsumeEvents() method again if the CEP server paused the streaming

and confirms that the adapter is ready.


The core transformation and queuing of events occurs in the ProduceEvents() method. This

method iterates through either reading the events it is receiving from the source or writing

events it is sending to the event consumer. It makes calls as necessary to push or pull events

into or from the event stream using calls to Enqueue() or Dequeue(). Calls to Enqueue() and

Dequeue() return the state of the adapter. If Enqueue() returns FULL or Dequeue() returns

EMPTY, the adapter transitions to a suspended state and can no longer produce or consume

events. When the adapter is ready to resume, it calls Ready(), which then causes the server to

call Resume(), and the cycle of enqueuing and dequeuing begins again from the point in time

at which the adapter was suspended.


Another task the adapter must perform is classification of an event. That is, the adapter

must specify the event kind as either INSERT or Current Time Increment (CTI). The adapter

adds events with the INSERT event kind to the stream as it receives data from the source. It

uses the CTI event kind to ignore any additional INSERT events it receives afterward that have

a start time earlier than the timestamp of the CTI event.


Query Templates


Query templates encapsulate the business logic that the CEP server instantiates as a standing

query instance to process, filter, and aggregate event streams. To define a query template,

you first create an event stream object. In a standalone server environment, you can create

and register a query template as an object on the CEP server for reuse.


The Event Stream Object


You can create an event stream object from an unbound stream or a user-defined input

adapter factory.


You might want to develop a query template to register on the CEP server without binding

it to an adapter. In this case, you can use the Create() method of the EventStream class to

obtain an event stream that has a defined shape, but without binding information. To do this,

you can adapt the following code:


CepStream<PayloadType> inputStream = CepStream<PayloadType>.Create(“inputStream”);


If you are using the implicit server development model, you can create an event stream

object from an input adapter factory and an input configuration. With this approach, you

do not need to implement an adapter, but you must specify the event shape. The following

example illustrates the syntax to use:


CEPStream<PayloadType> inputStream =

CepStream<PayloadType>.Create (streamName, typeof(AdapterFactory), myConfig,

EventShape.Point);


The QueryTemplate Object


When you use the explicit server development model for standalone server deployment,

you can create a QueryTemplate object that you can reuse in multiple bindings with different

input and output adapters. To create a QueryTemplate object, you use code similar to the

following example:


QueryTemplate myQueryTemplate = application.CreateQueryTemplate(“myQueryTemplate”,

outputStream);


Queries


After you create an event stream object, you write a LINQ expression on top of the event

stream object. You use LINQ expressions to define the fields for output events, to filter events

before query processing, to group events into subsets, and to perform calculations, aggregations,

and ranking. You can even use LINQ expressions to combine events from multiple

streams through join or union operations. Think of LINQ expressions as the questions you ask

of the streaming data.


Projection


The projection operation, which occurs in the select clause of the LINQ expression, allows you

to add more fields to the payload or apply calculations to the input event fields. You then

project the results into a new event by using field assignments. You can create a new event

type implicitly in the expressions, or you can refer to an existing event type explicitly.


Consider an example in which you need to increment the fields x and y from every event in

the inputStream stream by one. The following code example shows how to use field assignments

to implicitly define a new event type by using projection:


var outputStream = from e in inputStream

select new {x = e.x + 1, y = e.y + 1};


To refer to an existing event type, you cannot use the type’s constructor; you must use

field assignments in an expression. For example, assume you have an existing event type

called myEventType. You can change the previous code example as shown here to reference

the event type explicitly:


var outputStream = from e in inputStream

select new myEventType {x = e.x + 1, y = e.y + 1};


Filtering


You use a filtering operation on a stream when you want to apply operations to a subset of

events and discard all other events. All events for which the expression in the where clause

evaluates as true pass to the output stream. In the following example, the query selects

events where the value in field x equals 5:


var outputStream = from e in inputStream

where e.x == 5

select e;


Event Windows


A window represents a subset of data from an event stream for a period of time. After you

create a stream of windows, you can perform aggregation, TopK (a LINQ operation described

later in this chapter), or user-defined operations on the events that the windows contain. For

example, you can count the number of events in each window.


You might be inclined to think of a window as a way to partition the event stream by time.

However, the analogy between a window and a partition is useful only up to a point. When

you partition records in a table, a record belongs to one and only one partition, but an event

can appear in multiple windows based on its start time and end time. That is, the window

that covers the time period that includes an event’s start time might not include the event’s

end time. In that case, the event appears in each subsequent window, with the final window

covering the period that includes the event’s end time. Therefore, you should instead think of

a window as a way to partition time that is useful for performing operations on events occurring

between the two points of time that define a window.


In Figure 8-2, each unlabeled box below the input stream represents a window and contains

multiple events for the period of time that the window covers. In this example, the input

stream contains three events, but the first three windows contain two events and the last

window contains only one event. Thus, a count aggregation on each window yields results

different from a count aggregation on an input stream.


e1

e2

e3

0 30 60 90 120

e1

e2

e1

e2

e2

e3

e3

Input

events

Time (minutes)


FIGURE 8-2 Event windows in an input stream


As you might guess, the key to working with windows is to have a clear understanding of

the time span that each window covers. There are three types of window streams that StreamInsight

supports—hopping windows, snapshot windows, and count windows. In a hopping

windows stream, each window spans an equal time period. In a snapshot windows stream,

the size of a window depends on the events that it contains. By contrast, the size of a count

windows stream is not fixed, but varies according to a specified number of consecutive event

start times.


To create a hopping window, you specify both the time span that the window covers (also

known as window size) and the time span between the start of one window and the start of

the next window (also known as hop size). For example, assume that you need to create windows

that cover a period of one hour, and a new window starts every 15 minutes, as shown in

Figure 8-3. In this case, the window size is one hour and the hop size is 15 minutes. Here is the

code to create a hopping windows stream and count the events in each window:


var outputStream = from eventWindow in

inputStream.HoppingWindow(TimeSpan.FromHours(1), TimeSpan.FromMinutes(15))

select new { count = eventWindow.Count() };


0 30 60 90 120

e1

e2

e1

e2

e2

e3

e3

Input

events

Time (minutes)

e1

e2

e3

Hopping

windows


FIGURE 8-3 Hopping windows


When there are no gaps and there is no overlap between the windows in the stream,

hopping windows are also called tumbling windows. Figure 8-2, shown earlier, provides an

example of tumbling windows. The window size and hop size are the same in a tumbling


windows stream. Although you can use the HoppingWindow method to create tumbling windows,

there is a TumblingWindow method. The following code illustrates how to count events

in tumbling windows that occur every half hour.


var outputStream = from eventWindow in

inputStream.TumblingWindow(TimeSpan.FromMinutes(30))

select new { count = eventWindow.Count() };


Snapshot windows are similar to tumbling windows in that the windows do not overlap,

but whereas fixed points in time determine the boundaries of a tumbling window, events

define the boundaries of a snapshot window. Consider the example in Figure 8-4. At the start

of the first event, a new snapshot window starts. That window ends when the second event

starts, and a second snapshot window starts and includes both the first and second event.

When the first event ends, the second snapshot also ends, and a third snapshot window

starts. Thus, the start and stop of an event triggers the start and stop of a window. Because

events determine the size of the window, the Snapshot method takes arguments, as shown in

the following code, which counts events in each window:


var outputStream = from eventWindow in inputStream.Snapshot()

select new { count = eventWindow.Count() };


e1

e2

e1

e1

e2

e2

e3

Input

events

Time

e3

Snapshot

windows


FIGURE 8-4 Snapshot windows


Count windows are completely different from the other window types because the size of

the windows is variable. When you create windows, you provide a parameter n as a count of

events to fulfill within a window. For example, assume n is 2 as shown in Figure 8-5. The first

window starts when the first event starts and ends when the second event starts, because a

count of 2 events fulfills the specification. The second event also resets the counter to 1 and

starts a new window. The third event increments the counter to 2, which ends the second window.


e1

e2

e1

e2

e2

e3

Input

events

Time

e3

Count

windows

(n=2)


FIGURE 8-5 Count windows


Aggregations


You cannot perform aggregation operations on event streams directly; instead you must first

create a window to group data into periods of time that you can then aggregate. You then

create an aggregation as a method of the window and, for all aggregations except Count, use

a lambda expression to assign the result to a field.


StreamInsight supports the following aggregation functions:


¦ Avg


¦ Sum


¦ Min


¦ Max


¦ Count


Assume you want to apply the Sum and Avg aggregations to field x in an input stream. The

following example shows you how to use these aggregations as well as the Count aggregation

for each snapshot window:


var outputStream = from eventWindow in inputStream.Snapshot()

select new { sum = eventWindow.Sum(e => e.x),

avg = eventWindow.Avg(e => e.x),

count = eventWindow.Count() };


TopK


A special type of aggregation is the TopK operation, which you use to rank and filter events in

an ordered window stream. To order a window stream, you use the orderby clause. Then you

use the Take method to specify the number of events that you want to send to the output

stream, discarding all other events. The following code shows how to produce a stream of the

top three events:


var outputStream = (from eventWindow in inputStream.Snapshot()

from e in eventWindow

orderby e.x ascending, e.y descending

select e).Take(3);


When you need to include the rank in the output stream, you use projection to add the

rank to each event’s payload. This is accessible through the Payload property, as shown in the

following code:


var outputStream = (from eventWindow in inputStream.Snapshot()

from e in eventWindow

orderby e.x ascending, e.y descending

select e).Take(3, e=> new { x = e.Payload.x, y = e.Payload.y, rank = e.Rank });


Grouping


When you want to compute operations on event groups separately, you add a group by

clause. For example, you might want to produce an output stream that aggregates the input

stream by location and compute the average for field x for each location. In the following

example, the code illustrates how to create the grouping by location and how to aggregate

events over a specified column:


var outputStream = from e in inputStream

group e by e.locationID into eachLocation

from eventWindow in eachLocation.Snapshot()

select new { avgValue = eventWindow.Avg(e => e.x), locationId = eachGroup.Key };


Joins


You can use a join operation to match events from two streams. The CEP server first matches

events only if they have overlapping time intervals, and then applies the conditions that you

specify in the join predicate. The output of a join operation is a new event that combines payloads

from the two matched events. Here is the code to join events from two input streams,

where field x is the same value in each event. This code creates a new event containing fields

x and y from the first event and field y from the second event.


var outputStream = from e1 in inputStream1

join e2 in inputStream2

on e1.x equals e2.x

select new { e1.x, e1.y, e2.y };


Another option is to use a cross join, which combines all events in the first input stream

with all events in the second input stream. You specify a cross join by using a from clause for

each input stream and then creating a new event that includes fields from the events in each

stream. By adding a where clause, you can filter the events in each stream before the CEP

server performs the cross join. The following example selects events with a value for field x

greater than 5 from the first stream and selects events with a value for field y less than 20

from the second stream, performs the cross join, and then creates a stream of new events

containing field x from the first event and field y from the second event:


var outputStream = from e1 in inputStream1

from e2 in inputStream2

where e1.x > 5 && e2.y < 20

select new { e1.x, e2.y };


Unions


You can also combine events from multiple streams by performing a union operation. You

can work with only two streams at a time, but you can cascade a series of union operations if

you need to combine events from three or more streams, as shown in the following code:


var outputStreamTemp = inputStream1.Union(inputStream2);

var outputStream = outputStreamTemp.Union(inputStream3);


User-defined Functions


When you need to perform an operation that the CEP server does not natively support, you

can create user-defined functions (UDFs) by reusing existing .NET functions. You add a UDF to

the CEP server in the same way that you add an adapter. You can then call the UDF anywhere

in your query where an expression can be used, such as in a filter predicate, a join predicate,

or a projection.


Query Template Binding


The method that the CEP server uses to instantiate the query template as a standing query

depends on the development model that you use. If you are using the explicit server development

model, you create a query binder object, but you create an event stream consumer

object if you are using the implicit server development model.


The Query Binder Object


In the explicit server development model, you first create explicit input and output adapter

objects. Next you create a query binder object as a wrapper for the query template object on

the CEP server, which in turn you bind to the input and output adapters, and then you call the

CreateQuery() method to create the standing query, as shown here:


QueryBinder myQuerybinder = new QueryBinder(myQueryTemplate);

myQuerybinder.BindProducer(“querySource”, myInputAdapter, inputConf,

EventShape.Point);

myQuerybinder.AddConsumer(“queryResult”, myOutputAdapter, outputConf,

EventShape.Point, StreamEventOrder.FullyOrdered);

Query myQuery = application.CreateQuery(“query”, myQuerybinder, “query description”);


Rather than enqueuing CTIs in the input adapter code, you can define the CTI behavior by

using the AdvanceTimeSettings class as an optional parameter in the BindProducer method.

For example, to send a CTI after every 10 events, set the CTI’s timestamp as the most recent

event’s timestamp, and drop any event that appears later in the stream but has an end timestamp

earlier than the CTI, use the following code:


var ats = new AdvanceTimeSettings(10, TimeSpan.FromSeconds(0),

AdvanceTimePolicy.Drop);

queryBinder.BindProducer (“querysource”, myInputAdapter, inputConf,

EventShape.Interval, ats);


The Event Stream Consumer Object


After you define the query logic in an application that uses the implicit server development

model, you can use the output adapter factory to create an event stream consumer object.

You can pass this object directly to the CepStream.ToQuery() method without binding the

query template to the output adapter, as you can see in the following example:


Query myQuery = outputStream.ToQuery<ResultType>(typeof(MyOutputAdapterFactory),

outputConf, EventShape.Interval, StreamEventOrder.FullyOrdered);


The Query Object


In both the explicit and implicit development models, you create a query object. With that

object instantiated, you can use the Start() and Stop() methods. The Start() method instantiates

the adapters using the adapter factories, starts the event processing engine, and calls the

Start() methods for each adapter. The Stop() method sends a message to the adapters that

the query is stopping and then shuts down the query. Your application must include the following

code to start and stop the query object:


query.Start();

// wait for signal to complete the query

query.Stop();


The Management Interface


StreamInsight includes the ManagementService API, which you can use to create diagnostic

views for monitoring the CEP server’s resources and the queries running on the server. Another

option is to use Windows PowerShell to access diagnostic information.


Diagnostic Views


Your diagnostic application can retrieve static information, such as object property values,

and statistical information, such as a cumulative event count after a particular point in time or

an aggregate count of events from child objects. Objects include the server, input and output

adapters, query operators, schedulers, and event streams. You can retrieve the desired information

by using the GetDiagnosticView() method and passing the object’s URI as a method

argument.


If you are monitoring queries, you should understand the transition points at which the

server records metrics about events in a stream. The name of a query metric identifies the

transition point to which the metric applies. For example, Total Outgoing Event Count provides

the total number of events that the output adapter has dequeued from the engine. The

following four transition points relate to query metrics:


¦ Incoming The event arrival at the input adapter


¦ Consumed The point at which the input adapter enqueues the event into the engine


¦ Produced The point at which the event leaves the last query operator in the engine


¦ Outgoing The event departure from the output adapter


Windows PowerShell Diagnostics


For quick analysis, you can use Windows PowerShell scripts to view diagnostic information

rather than writing a complete diagnostic application. Before you can use a Windows PowerShell

script, the StreamInsight server must be running a query. If the server is running as a

hosted assembly, you must expose the Web service.


You start the diagnostic process by loading the Microsoft.ComplexEventProcessing assembly

from the Global Assembly Cache (GAC) into Windows PowerShell by using the following

code:


PS C:\>

[System.Reflection.Assembly]::LoadWithPartialName(“Microsoft.ComplexEventProcessing”)


Then you need to create a connection to the StreamInsight host process by using the code

in this example:


PS C:\> $server =

Microsoft.ComplexEventProcessing.Server]::Connect(“http://localhost/StreamInsight&#8221;)


Then you can use the GetDiagnosticView() method to retrieve statistics for an object, such

as the Event Manager, as shown in the following code:


PS C:\> $dv = $server.GetDiagnosticView(“cep:/Server/EventManager”)

PS C:\> $dv


To retrieve information about a query, you must provide the full name, following the

StreamInsight hierarchical naming schema. For example, for an application named myApplication

with a query named myQuery, you use the following code:


PS C:\> $dv =

$server.GetDiagnosticView(“cep:/Server/Application/myApplication/Query/myQuery”)

PS C:\> $dv


NOTE For a complete list of metrics and statistics that you can query by using diagnostic

views, refer to the SQL Server Books Online topic “Monitoring the CEP Server and Queries”

at http://msdn.microsoft.com/en-us/library/ee391166(SQL.105).aspx.


C H A P T E R 9


Reporting Services

Enhancements


If you thought Microsoft SQL Server 2008 Reporting Services introduced a lot of great

new features to the reporting platform, just wait until you discover what’s new in

Reporting Services in SQL Server 2008 R2. The Reporting Services development team

at Microsoft has been working hard to incorporate a variety of improvements into the

product that should make your life as a report developer or administrator much simpler.


New Data Sources


This release supports a few new data sources to expand your options for report development.

When you use the Data Source Properties dialog box to create a new data source,

you see Microsoft SharePoint List, Microsoft SQL Azure, and Microsoft SQL Server Parallel

Data Warehouse (covered in Chapter 6, “Scalable Data Warehousing”) as new options in

the Type drop-down list. To build a dataset with any of these sources, you can use a graphical

query designer or type a query string applicable to the data source provider type.


You can also use SQL Server PowerPivot for SharePoint as a data source, although this

option is not included in the list of data source providers. Instead, you use the SQL Server

Analysis Services provider and then provide the URL for the workbook that you want to

use as a data source. You can learn more about using a PowerPivot workbook as a data

source in Chapter 10, “Self-Service Analysis with PowerPivot.”


Expression Language Improvements


There are several new functions added to the expression language, as well as new capabilities

for existing functions. These improvements allow you to combine data from two

different datasets in the same data region, create aggregated values from aggregated

values, define report layout behavior that depends on the rendering format, and modify

report variables during report execution.


165


Combining Data from More Than One Dataset


To display data from more than one source in a table (or in any data region, for that matter),

you must create a dataset that somehow combines the data because a data region binds to

one and only one dataset. You could create a query for the dataset that joins the data if both

sources are relational and accessible with the same authentication. But what if the data comes

from different relational platforms? Or what if some of the data comes from SQL Server and

other data comes from a SharePoint list? And even if the sources are relational, what if you

can access only stored procedures and are unable to create a query to join the sources? These

are just a few examples of situations in which the new Lookup functions in the Reporting

Services expression language can help.


In general, the three new functions, Lookup, MultiLookup, and LookupSet, work similarly

by using a value from the dataset bound to the data region (the source) and matching it to

a value in a second dataset (the destination). The difference between the functions reflects

whether the input or output is a single value or multiple values.


You use the Lookup function when there is a one-to-one relationship between the source

and destination. The Lookup function matches one source value to one destination value at a

time, as shown in Figure 9-1.


Month-to-Date Sales

State/Province

British Columbia

Oregon

Washington

Sales Amount

1,225

750

1,000

StProvName

British Columbia

Oregon

Washington

StProv

BC

OR

WA

StateProvinceCode

BC

OR

WA

SalesAmount

1225

750

1000

Dataset1 Dataset2


FIGURE 9-1 Lookup function results


In the example, the resulting report displays a table for the sales data returned for

Dataset2, but rather than displaying the StateProvinceCode field from the same dataset, the

Lookup function in the first column of the table instructs Reporting Services to match each

value in that field from Dataset2 with the StProv field in Dataset1 and then to display the

corresponding StProvName. The expression in the first column of the table is shown here:


166 CHAPTER 9 Reporting Services Enhancements


=Lookup(Fields!StateProvinceCode.Value, Fields!StProv.Value,

Fields!StProvName.Value, “Dataset1”)


The MultiLookup function also requires a one-to-one relationship between the source and

destination, but it accepts a set of source values as input. Reporting Services matches each

source value to a destination value one by one, and then returns the matching values as an

array. You can then use an expression to transform the array into a comma-separated list, as

shown in Figure 9-2.


StProvName

British Columbia

Oregon

Washington

StProv

BC

OR

WA

Dataset1

Florida

Georgia

FL

GA

BC

OR

WA

FL

GA

Salesperson StateProvinceCode

Dataset2

SalesAmount

Month-to-Date Sales by Salesperson

David Campbell BC, OR, WA 2975

Tsvi Reiter FL, GA 3000

Saleperson

David Campbell

Tsvi Reiter

Territory

British Columbia, Oregon, Washington

Florida, Georgia

Sales Amount

2,975

3,000


FIGURE 9-2 MultiLookup function results


The MultiLookup function in the second column of the table requires an array of values

from the dataset bound to the table, which in this case is the StateProvinceCode field in

Dataset2. You must first use the Split function to convert the comma-separated list of values

in the StateProvinceCode field into an array. Reporting Services operates on each element

of the array, matching it to the StProv field in Dataset1, and then combining the results into

an array that you can then transform into a comma-separated list by using the Join function.

Here is the expression in the Territory column:


=Join(MultiLookup(Split(Fields!StateProvinceCode.Value, “,”), Fields!StProv.Value,

Fields!StProvName.Value, “Dataset1 “), “, “)


Expression Language Improvements CHAPTER 9 167


When there is a one-to-many relationship between the source and destination values, you

use the LookupSet function. This function accepts a single value from the source dataset as

input and returns an array of matching values from the destination dataset. You could then

use the Join function to convert the result into a delimited string, as in the example for the

MultiLookup function, or you could use other functions that operate on arrays, such as the

Count function, as shown in Figure 9-3.


Salesperson SalespersonCode

Dataset2

DC

TR

David Campbell

Tsvi Reiter

Salesperson- CustomerName

Code

DC

DC

DC

TR

K. Gregersen

T. Yee

L. Miller

J. Frank

Dataset2

K. Gregersen

T. Yee

L. Miller

Customer Counts

Salesperson

David Campbell

Tsvi Reiter

Customer Count

3

1 J. Frank


FIGURE 9-3 LookupSet function results


The Customer Count column uses this expression:


LookupSet(Fields!SalespersonCode.Value,Fields!SalesperonCode.Value,

Fields!CustomerName.Value,”Dataset2″).Length


Aggregation


The aggregate functions available in Reporting Services since its first release with the SQL

Server 2000 platform provided all the functionality most people needed most of the time.

However, if you needed to use the result of an aggregate function as input for another

aggregate function and weren’t willing or able to put the data into a SQL Server Analysis

Services cube first, you had no choice but to preprocess the results in the dataset query.

In other words, you were required to do the first level of aggregation in the dataset query,

and then you could perform the second level of aggregation by using an expression in the

report. Now, with SQL Server 2008 R2 Reporting Services, you can nest an aggregate function

inside another aggregate function. Put another way, you can aggregate an aggregation.

The example table in Figure 9-4 shows the calculation of average monthly sales for a selected

year. The dataset contains one row for each product, which the report groups by year and by

month while hiding the detail rows.


FIGURE 9-4 Aggregation of an aggregation


Here is the expression for the value displayed in the Monthly Average row:


=Avg(Sum(Fields!SalesAmount.Value,”EnglishMonthName”))


Conditional Rendering Expressions


The expression language in SQL Server 2008 R2 Reporting Services includes a new global

variable that allows you to set the values for “look-and-feel” properties based on the rendering

format used to produce the report. That is, any property that controls appearance (such

as Color) or behavior (such as Hidden) can use members of the RenderFormat global variable

in conditional expressions to change the property values dynamically, depending on the

rendering format.


Let’s say that you want to simplify the report layout when a user exports a report to

Microsoft Excel. Sometimes other report items in the report can cause a text box in a data

region to render as a set of merged cells when you are unable to get everything to align

perfectly. The usual reason that users export a report to Excel is to filter and sort the data,

and they are not very interested in the information contained in the other report items.

Rather than fussing with the report layout to get each report item positioned and aligned just

right, you can use an expression in the Hidden property to keep those report items visible in

every export format except Excel. Simply reference the name of the extension as found in the

RSReportServer.config file in an expression like this:


=iif(RenderFormat.Name=”EXCEL”, True, False)


Another option is to use the RenderFormat global variable with the IsInteractive member

to set the conditions of a property. For example, let’s say you have a report that displays summarized

sales but also allows the user to toggle a report item to display the associated details.

Rather than export all of the details when the export format is not interactive, you can easily

omit those details from the rendered output by using the following expression in the Hidden

property of the row group containing the details:


=iif(RenderFormat.IsInteractive, False, True)


Page Numbering


Speaking of global variables, you can use the new Globals!OverallPageNumber and

Globals!OverallTotalPages variables to display the current page number relative to the entire

report and the total page count, respectively. You can use these global variables, which are

also known as built-in fields, in page headers and page footers only. As explained later in

this chapter in the “Pagination Properties” section, you can specify conditions under which

to reset the page number to 1 rather than incrementing its value by one. The variables

Globals!PageNumber and Globals!TotalPages are still available from earlier versions. You can

use them to display the page information for the current section of a report. Figure 9-5 shows

an example of a page footer when the four global variables are used together.


FIGURE 9-5 Global variables for page counts


The expression to produce this footer looks like this:


=”Section Page ” + CStr(Globals!PageNumber) + ” of ” + CStr(Globals!TotalPages) +

” (Overall ” + Cstr(Globals!OverallPageNumber) + ” of ” +

CStr(Globals!OverallTotalPages) +”)”


Read/Write Report Variable


Another enhancement to the expression language is the new support for setting the value

of a report variable. Just as in previous versions of Reporting Services, you can use a report

variable when you have a value with a dependency on the execution time. Reporting Services

stores the value at the time of report execution and persists that value as the report continues

to process. That way, as a user pages through the report, the variable remains constant even if

the actual page rendering time varies from page to page.


By default, a report variable is Read Only, which was the only option for this feature in the

previous version of Reporting Services. In SQL Server 2008 R2, you can now clear the Read-

Only setting, as shown in Figure 9-6, when you want to be able to change the value of the

report variable during report execution.


FIGURE 9-6 Changing report variables


To write to your report variable, you use the SetValue method of the variable. For example,

assume that you have set up the report to insert a page break between group instances, and

you want to update the execution time when the group changes. Add a report variable to the

report, and then add a hidden text box to the data region with the group used to generate

a page break. Next, place the following expression in the text box to force evaluation of the

expression for each group instance:


=Variables!MyVariable.SetValue(Now())


In the previous version of Reporting Services, the report variable type was a value just

like any text box on the report. In SQL Server 2008 R2, the report variable can also be a .NET

serializable type. You must initialize and populate the report variable when the report session

begins, then you can independently add or change the values of the report variable on each

page of the report during your current session.


Layout Control


SQL Server 2008 R2 Reporting Services also includes several new report item properties that

you can use to control layout. By using these properties, you can manage report pagination,

fill in data gaps to align data groupings, and rotate the orientation of text.


Pagination Properties


There are three new properties available to manage pagination: Disabled, ResetPageNumber,

and PageName. These properties appear in the Properties window when you select a tablix,

rectangle, or chart in the report body or a group item in the Row Groups or Column Groups

pane. The most common reason you set values for these properties is to define different paging

behaviors based on the rendering format, now that the global variable RenderFormat is

available.


For example, assume that you create a tablix that summarizes sales data by year, and

group the data with the CalendarYear field as the outermost row group. When you click the

CalendarYear group item in the Row Groups pane, you can access several properties in the

Properties window, as shown in Figure 9-7. Those properties, however, are not available in the

item’s Group Properties dialog box.


FIGURE 9-7 Pagination properties


Assume also that you want to insert page breaks between each instance of CalendarYear

only when you export the report to Excel. After setting the BreakLocation property to Between,

you set the Disabled property to False when the report renders as Excel by using the

following expression:


=iif(Globals!RenderFormat.Name=”EXCEL”,False,True)


Reporting Services keeps as many groups visible on one page as possible and adds a soft

page break to the report where needed to keep the height of the page within the dimensions

specified by the InteractiveSize property when the report renders as HTML. However,

when the report renders in any other format, each year appears on a separate page, or on a

separate sheet if the report renders in Excel.


Whether or not you decide to disable the page break, you can choose the conditions to

apply to reset the page number when the page break occurs by assigning an expression to

the ResetPageNumber property. To continue with the current example, you can use a similar

conditional expression for the ResetPageNumber property to prevent the page number from

resetting when the report renders as HTML and only allow the reset to occur in all other

formats. Therefore, in HTML format, the page number of the report increments by one as you

page through it, but in other formats (excluding Excel), you see the page number reset each

time a new page is generated for a new year.


Last, consider how you can use the PageName property. As one example, instead of using

page numbers in an Excel workbook, you can assign a unique name to each sheet in the

workbook. You might, for example, use the group expression that defines the page break as

the PageName property. When the report renders as an Excel workbook, Reporting Services

uses the page break definition to separate the CalendarYear groups into different sheets of

the same workbook and uses the PageName expression to assign the group instance’s value

to the applicable sheet.


As another example, you can assign an expression to the PageName property of a rectangle,

data region, group, or map. You can then reference the current value of this property

in the page header or footer by using Globals!PageName in the expression. The value

of Globals!PageName is first set to the value of the InitialPageName report property when

report processing begins and then resets as each report item processes if you have assigned

an expression to the report item’s PageName property.


Data Synchronization


One of the great features of Reporting Services is its ability to create groups of groups by

nesting one type of report item inside another type of report item. In Figure 9-8, a list that

groups by category and year contains a matrix that groups by month. Notice that the months

in each list group do not line up properly because data does not exist for the first six months

of the year for the Accessories 2005 group. Each monthly group displays independently of

other monthly groups in the report.


FIGURE 9-8 Unsynchronized groups


A new property, DomainScope, is available in SQL Server 2008 R2 Reporting Services to fix

this problem. This property applies to a group and can be used within the tablix data region,

as shown in Figure 9-9, or in charts and other data visualizations whenever you need to fill gaps

in data across multiple instances of the same grouping. You simply set the property value to

the name of the data region that contains the group. In this example, the MonthName group’s

DomainScope property is set to Tablix1, which is the name assigned to the list. Each instance of

the list’s group—category and year—renders an identical set of values for MonthName.


FIGURE 9-9 Synchronized groups


Text Box Orientation


Each text box has a WritingMode property that by default displays text horizontally. There is

also an option to display text vertically to accommodate languages that display in that format.

Although you could use the vertical layout for other languages, you probably would not

be satisfied with the result because it renders each character from top to bottom. An English

word, for example, would have the bottom of each letter facing left and the top of each letter

facing right. Instead, you can set this property to a new value, Rotate270, which also renders

the text in a vertical layout, but from bottom to top, as shown in Figure 9-10. This feature is

useful for tablix row headers when you need to minimize the width of the tablix.


FIGURE 9-10 Text box orientation


Data Visualization


Prior to SQL Server 2008 R2 Reporting Services, your only option for enhancing a report with

data visualization was to add a chart or gauge. Now your options have been expanded to

include data bars, sparklines, indicators, and maps.


Data Bars


A data bar is a special type of chart that you add to your report from the Toolbox window.

A data bar shows a single data point as a horizontal bar or as a vertical column. Usually you

embed a data bar inside of a tablix to provide a small data visualization for each group or

detail group that the tablix contains. After adding the data bar to the tablix, you configure the

value you want to display, and you can fine-tune other properties as needed if you want to

achieve a certain look. By placing data bars in a tablix, you can compare each group’s value to

the minimum and maximum values within the range of values across all groups, as shown in

Figure 9-11. In this example, Accessories 2005 is the minimum sales amount, and Bikes 2007

is the maximum sales amount. The length of each bar allows you to visually assess whether a

group is closer to the minimum or the maximum or some ratio in between, such as the Bikes

2008 group, which is about half of the maximum sales.


FIGURE 9-11 Data bars


Sparklines


Like data bars, sparklines can be used to include a data visualization alongside the detailed

data. Whereas a data bar usually shows a single point, a sparkline shows multiple data points

over time, making it easier to spot trends.


You can choose from a variety of sparkline types such as columns, area charts, pie charts,

or range charts, but most often sparklines are represented by line charts. As you can see in

Figure 9-12, sparklines are pretty bare compared to a chart. You do not see axis labels, tick

marks, or a legend to help you interpret what you see. Instead, a sparkline is intended to

provide a sense of direction by showing upward or downward trends and varying degrees of

fluctuation over the represented time period.


FIGURE 9-12 Sparklines


Indicators


Another way to display data in a report is to use indicators. In previous versions of Reporting

Services, you could produce a scorecard of key performance indicators by uploading

your own images and then using expressions to determine which image to display. Now

you can choose indicators from built-in sets, as shown in Figure 9-13, or you can customize

these sets to change properties such as the color or size of an indicator icon, or even by

using your own icons.


FIGURE 9-13 Indicator types


After selecting a set of indicators, you associate the set with a value in your dataset or with

an expression, such as a comparison of a dataset value to a goal. You then define the rules

that determine which indicator properly represents the status. For example, you might create

an expression that compares SalesAmount to a goal. You could then assign a green check

mark if SalesAmount is within 90 percent of the goal, a yellow exclamation point if it is within

50 percent of the goal, and a red X for everything else.


Maps


A map element is a special type of data visualization that combines geospatial data with other

types of data to be analyzed. You can use the built-in Map Gallery as a background for your

data, or you can use an ESRI shapefile. For more advanced customization, you can use SQL

Server spatial data types and functions to create your own polygons to represent geographical

areas, points on a map, or a connected set of points representing a route. Each map can

have one or more map layers, each of which contains spatial data for drawing the map, analytical

data that will be projected onto the map as color-coded regions or markers, and rules

for assigning colors, marker size, and other visualization properties to the analytical data. In

addition, you can add Bing Maps tile layers as a background for other layers in your map.


Although you can manually configure the properties for the map and each map layer, the

easiest way to get started is to drag a map from the Toolbox window to the report body (if

you are using Business Intelligence Development Studio) or click the map in the ribbon (if

you are using Report Builder 3.0). This starts the Map Wizard, which walks you through the

configuration process by prompting you for the source of the spatial data defining the map

itself and the source of the analytical data to display on the map. You then decide how the

report should display this analytical data—by color-coding elements on the map or by using

a bubble to represent data values on the map at specified points. Next, you define the relationship

between the map’s spatial data and the analytical data by matching fields from each

dataset. For example, the datasets for the map shown in Figure 9-14 have matching fields for

the two-letter state codes. In the next step, you specify the field in your analytical data to

display on the map, and you configure the visualization rules to apply, such as color ranges.

In the figure, for example, the rule is to use darker colors to indicate a higher population.


FIGURE 9-14 A map using colors to show population distribution


Reusability


SQL Server 2008 R2 Reporting Services has several new features to support reusability of

components. Report developers with advanced skills can build shared datasets and report

parts that can be used by others. Then, for example, a business user can quickly and easily

pull together these preconstructed components into a personalized report without knowing

how to build a query or design a matrix. To help the shared datasets run faster, you can

configure a cache refresh schedule to keep a copy of the shared dataset in cache. Last, the

ability to share report data as an Atom data feed extends the usefulness of data beyond a

single source report.


Shared Datasets


A shared dataset allows you to define a query once for reuse in many reports, much as you

can create a shared datasource to define a reusable connection string. Having shared datasets

available on the server also helps SQL Server 2008 R2 Report Builder 3.0 users develop

reports more easily, because the dataset queries are already available for users who lack the

skills to develop queries without help. The main requirement when creating a shared dataset

is to use a shared data source. In all other respects, the configuration of the shared dataset

is just like the traditional embedded dataset used in earlier versions of Reporting Services.

You define the query and then specify options, query parameter values, calculated fields, and

filters as needed. The resulting file for the shared dataset has an .rsd extension and uploads to

the report server when you deploy the project. The project properties now include a field for

specifying the target folder for shared datasets on the report server.


NOTE You can continue to create embedded datasets for your reports as needed, and

you can convert an embedded dataset to a shared dataset at any time.


In Report Manager, you can check to see which reports use the shared dataset when you

need to evaluate the impact of a change to the shared dataset definition. Simply navigate to

the folder containing the shared dataset, click the arrow to the right of the shared dataset

name, and select View Dependent Items, as shown in Figure 9-15.


FIGURE 9-15 The shared dataset menu


Cache Refresh


The ability to configure caching for reports has been available in every release of Reporting

Services. This feature is helpful in situations in which reports take a long time to execute and

the source data is not in a constant state of change. By storing the report in cache, Reporting


Services can respond to a report request faster, and users are generally happier with the

reporting system. However, cache storage is not unlimited. Periodically, the cache expires

and the next person that requests the report has to wait for the report execution process to

complete. A workaround for this scenario is to create a subscription that uses the NULL delivery

provider to populate the cache in advance of the first user’s request.


In SQL Server 2008 R2 Reporting Services, a better solution is available. A new feature

called Cache Refresh allows you to establish a schedule to load reports into cache. In addition,

you can configure Cache Refresh to load shared datasets into cache to extend the performance

benefit to multiple reports. Caching shared datasets is not only helpful for reports,

but also for any dataset that you use to populate the list of values for a parameter. To set up

a schedule for the Cache Refresh, you must configure stored credentials for the data source.

Then you configure the caching expiration options for the shared dataset and create a new

Cache Refresh Plan, as shown in Figure 9-16.


FIGURE 9-16 The Cache Refresh Plan window


Report Parts


After developing a report, you can choose which report items to publish to the report server

as individual components that can be used again later by other report authors who have

permissions to access the published report parts. Having readily accessible report parts in a

central location enables report authors to build new reports more quickly. You can publish

any of the following report items as report parts: tables, matrices, rectangles, lists, images,

charts, gauges, maps, and parameters.


You can publish report parts both from Report Builder 3.0 and Report Designer in Business

Intelligence Development Studio. In Report Designer, the Report menu contains the Publish

Report Parts command. In the Publish Report Parts dialog box, shown in Figure 9-17, you

select the report items that you want to publish. You can replace the report item name and

provide a description before publishing.


FIGURE 9-17 The Publish Report Parts dialog box


When you first publish the report part, Reporting Services assigns it a unique identifier

that persists across all reports to which it will be added. Note the option in the Publish Report

Parts dialog box in Report Designer (shown in Figure 9-15) to overwrite the report part on the

report server every time you deploy the report. In Report Builder, you have a different option

that allows you to choose whether to publish the report item as a new copy of the report.

If you later modify the report part and publish the revised version, Reporting Services can

use the report part’s unique identifier to recognize it in another report when another report

developer opens that report for editing. At that time, the report author receives a notification

of the revision and can decide whether to accept the change.


Although you can publish report parts in Report Designer and Report Builder 3.0, you

can only use Report Builder 3.0 to find and use those report parts. More information about

Report Builder 3.0 can be found later in this chapter in the “Report Builder 3.0” section.


Atom Data Feed


SQL Server 2008 R2 Reporting Services includes a new rendering extension to support

exporting report data to an Atom service document. An Atom service document can be used

by any application that consumes data feeds, such as SQL Server PowerPivot for Excel. You

can use this feature for situations in which the client tools that users have available cannot

access data directly or when the query structures are too complex for users to build on their

own. Although you could use other techniques for delivering data feed to users, Reporting

Services provides the flexibility to use a common security mechanism for reports and data

feeds, to schedule delivery of data feeds, and to store report snapshots on a periodic basis.


The Atom service document contains at least one data feed per data region in the report if

a report author has not disabled this feature. Depending on the structure of the data, a matrix

that contains adjacent groups, a list, or a chart might produce multiple data feeds. Each data

feed has a URL that you use to retrieve the content.


To export a report to the Atom data feed, you click the last button on the toolbar in the

Report Viewer, as shown in Figure 9-18.


FIGURE 9-18 Atom Data Feed


The Atom service document is an XML document containing a connection to each data

feed that is defined as a URL, as shown in the following XML code:


<?xml version=”1.0″ encoding=”utf-8″ standalone=”yes” ?>

<service xmlns:atom=”http://www.w3.org/2005/Atom&#8221;

xmlns:app=”http://www.w3.org/2007/app&#8221; xmlns=”http://www.w3.org/2007/app”&gt;

<workspace>

<atom:title>Reseller Sales</atom:title>

<collection

href=”http://yourserver/ReportServer?%2fExploring+Features%2fReseller+Sales

&rs%3aCommand=Render&rs%3aFormat=ATOM&rc%3aDataFeed=xAx0x0″>

<atom:title>Tablix1</atom:title>

</collection>

</workspace>

</service>


Report Builder 3.0


Report Builder 1.0 was the first release of a report development tool targeted for business

users. That version restricted the users to queries based on a report model and supported

limited report layout capabilities. Report Builder 2.0 was released with SQL Server 2008 and

gave the user expanded capabilities for importing queries from other report definition files or

for writing a query on any data source supported by Reporting Services. In addition, Report

Builder 2.0 included support for all layout options of Report Definition Language (RDL).

Report Builder 3.0 is the third iteration of this tool. It supports the new capabilities of SQL

Server 2008 R2 RDL including maps, sparklines, and data bars. In addition, Report Builder 3.0

supports two improvements intended to speed up the report development process—edit

sessions and the Report Part Gallery.


Edit Sessions


Report Builder 3.0 operates as an edit session on the report server if you perform your development

work while connected to the server. The main benefit of the edit session is to speed

up the preview process and render reports faster. The report server saves cached datasets

for the edit session. These datasets are reused when you preview the report and have made

report changes that affect the layout only. If you know that the data has changed in the

meantime, you can use the Refresh button to retrieve current data for the report. The cache

remains available on the server for two hours and resets whenever you preview the report.

After the two hours have passed, the report server deletes the cache. An administrator can

change this default period to retain the cache for longer periods if necessary.


The edit session also makes it easier to work with server objects during report development.

One benefit is the ability to use relative references in expressions. Relative references

allow you to specify the path to subreports, images, and other reports that you might configure

as targets for the Jump To action relative to the current report’s location on the report

server. Another benefit is the ability to test connections and confirm that authentication

credentials work before publishing the report to the report server.


The Report Part Gallery


Report Builder 3.0 includes a new window, the Report Part Gallery, that you can enable from

the View tab on the ribbon. At the top of this window is a search box in which you can type

a string value, as shown in Figure 9-19, and search for report parts published to the report

server where the name or the description of the report part contains the search string. You

can also search by additional criteria, such as the name of the creator or the date created.

To use the report part, simply drag the item from the list onto the report body. The ability

to find and use report parts is available only within Report Builder 3.0. You can use Report

Designer to create and publish report parts, but not to reuse them in other reports.


FIGURE 9-19 The Report Part Gallery


Report Access and Management


In this latest release of Reporting Services, you can benefit from a few enhancements that

improve access to reports and to management operations in Report Manager, in addition to

an additional feature that supports sandboxing of the report server environment.


Report Manager Improvements


When you open Report Manager for the first time, you will immediately notice the improved

look and feel. The color scheme and layout of this Web application had not changed since the

product’s first release, until now. When you open a report for viewing, you notice that more

screen space is allocated to the Report Viewer, as shown in Figure 9-20. All of the space at the

top of the screen has been eliminated.


FIGURE 9-20 Report Viewer


Notice also that the Report Viewer does not include a link to open the report properties.

Rather than requiring you to open a report first and then navigate to the properties pages,

Report Manager gives you direct access to the report properties from a menu on the report

listing page, as shown in Figure 9-21. Another direct access improvement to Report Manager

is the ability to test the connection for a data source on its properties page.


FIGURE 9-21 The report menu


Report Viewer Improvements


The display of reports is also improved in the Report Viewer available in this release of SQL

Server, which now supports AJAX (Asynchronous JavaScript and XML). If you are familiar with

earlier versions of Reporting Services, you can see the improvement that AJAX provides by

changing parameters or by using drilldown. The Report Viewer no longer requires a refresh

of the entire screen, nor does it reposition the current view to the top of the report, which

results in a much smoother viewing experience.


Improved Browser Support


Reporting Services no longer supports just one Web browser, as it did when it was first

released. In SQL Server 2008 R2, you can continue to use Windows Internet Explorer 6, 7, or

8, which is recommended for access to all Report Viewer features. You can also use Firefox,

Netscape, or Safari. However, these browsers do not support the document map, text search

within a report, zoom, or fixed table headers. Furthermore, Safari 3.0 does not support the

Calendar control for date parameters or the client-side print control and does not correctly

display image files that the report server retrieves from a remote computer.


If you choose to use a Web browser other than Internet Explorer, you should understand

the authentication support that the alternative browsers provide. Internet Explorer is the only

browser that supports all authentication methods that you can use with Reporting Services—

Negotiated, Kerberos, NTLM, and Basic. Firefox supports Negotiated, NTLM, and Basic, but

not Kerberos authentication. Safari supports only Basic authentication.


NOTE Basic authentication is not enabled by default in Reporting Services. You must

modify the RSReportServer.config file by following the instructions in SQL Server Books

Online in the topic “How to: Configure Basic Authentication in Reporting Services” at

http://msdn.microsoft.com/en-us/library/cc281309.aspx.


RDL Sandboxing


When you grant external users access to a report server, the security risks multiply enormously,

and additional steps must be taken to mitigate those risks. Reporting Services now supports

configuration changes through the use of the RDL Sandboxing feature on the report server to

isolate access to resources on the server as an important part of a threat mitigation strategy.

Resource isolation is a common requirement for hosted services that have multiple tenants

on the same server. Essentially, the configuration changes allow you to restrict the external

resources that can be accessed by the server, such as images, XLST files, maps, and data

sources. You can also restrict the types and functions used in expressions by namespace and

by member, and check reports as they are deployed to ensure that the restricted types are

not in use. You can also restrict the text length and the size of an expression’s return value

when a report executes. With sandboxing, reports cannot include custom code in their code

blocks, nor can reports include SQL Server 2005 custom report items or references to named

parameters in expressions. The trace log will capture any activity related to sandboxing and

should be monitored frequently for evidence of potential threats.


SharePoint Integration


SQL Server 2008 R2 Reporting Services continues to improve integration with SharePoint. In

this release, you find better options for configuring SharePoint 2010 for use with Reporting

Services, working with scripts to automate administrative tasks, using SharePoint lists as data

sources, and integrating Reporting Services log events with the SharePoint Unified Logging

Service.


Improved Installation and Configuration


The first improvement affects the initial installation of Reporting Services in SharePoint integrated

mode. Earlier versions of Reporting Services and SharePoint require you to obtain the

Microsoft SQL Server Reporting Services Add-in for SharePoint as a separate download for

installation. Although the add-in remains available as a separate download, the prerequisite

installation options for SharePoint 2010 include the ability to download the add-in and install

it automatically with the other prerequisites.


After you have all components installed and configured on both the report server and the

SharePoint server, you need to use SharePoint 2010 Central Administration to configure the

General Application settings for Reporting Services. As part of this process, you can choose

to apply settings to all site collections or to specific sites, which is a much more streamlined

approach to enabling Reporting Services integration than was possible in earlier versions.


Another important improvement is the addition of support for alternate access mappings

with Reporting Services. Alternate access mappings allow users from multiple zones, such as

the Internet and an intranet, to access the same report items by using different URLs. You can

configure up to five different URLs to access a single Web application that provides access

to Reporting Services content, with each URL using a different authentication provider. This

functionality is important when you want to use Windows authentication for intranet users

and Forms authentication for Internet users.


RS Utility Scripting


Report server administrators frequently use the rs.exe utility to perform repetitive administrative

tasks, such as bulk deployment of reports to the server and bulk configuration of report

properties. Lack of support for this utility in integrated mode had been a significant problem

for many administrators, so having this capability added to integrated mode is great news.


SharePoint Lists as Data Sources


Increasing numbers of companies use SharePoint lists to store information that needs to be

shared with a broader audience or in a standard report format. Although there are some

creative ways you could employ to get that data into Reporting Services, custom code was

always part of the solution. SQL Server 2008 R2 Reporting Services has a new data extension

provider that allows you to access SharePoint 2007 or SharePoint 2010 lists. After you


create the data source using the Microsoft SharePoint List connection type and provide

credentials for authentication, you must supply a connection string to the site or subsite in

the form of a URL that references the site or subsite. That is, use a connection string such as

http://MySharePointWeb/MySharePointSite or http://MySharePointWeb/MySharePointSite

/Subsite. A query designer is available with this connection provider, as shown in Figure 9-22,

allowing you to select fields from the list to include in your report.


FIGURE 9-22 SharePoint list Query Designer


SharePoint Unified Logging Service


In SharePoint integrated mode, you now have the option to view log information by using the

SharePoint Unified Logging Service. After you enable diagnostic logging, the log files capture

information about activities related to Reporting Services in Central Administration, calls from

client applications to the report server, calls made by the processing and rendering engines

in local mode, calls to Reporting Services Web pages or the Report Viewer Web Part, and

all other calls related to Reporting Services within SharePoint. Having all SharePoint-related

activity, including the report server, in one location should help the troubleshooting process.


189


C H A P T E R 1 0


Self-Service Analysis with

PowerPivot


Many business intelligence (BI) solutions require access to centralized, cleansed data

in a data warehouse, and there are many good reasons for an organization to

continue to maintain a data warehouse for these solutions. There are even self-service

tools available that allow users to build ad hoc reports from this data. But for a variety of

reasons, business users cannot limit their analyses to data that comes from the corporate

data warehouse. In fact, their analyses often require data that will never be part of the

data warehouse, such as miscellaneous spreadsheets or text files prepared for specific

needs or data obtained from third parties that might be used only once.


Users can spend a great deal of time gathering data from disparate sources and then

manually consolidating and integrating the data in the form of one or more Microsoft

Excel workbooks. PivotTables and PivotCharts are popular tools for performing analyses,

but Excel requires all the data for these objects to be consolidated first into a single table

or to be available in the form of a cube in a SQL Server Analysis Services database. What

does the user do when the insight is so useful that the spreadsheet needs to be shared

with others on a frequent basis with fresh data?


Sometime users are also constrained by the volume of data that they want to analyze.

Excel 2007 can support one million rows of data, but what if the user has data that is

more than a million rows? These users need a tool that enables them to analyze huge

sets of data without dependence on IT support.


Microsoft SQL Server 2008 R2 comes to the rescue for these users with two new

features to meet these needs—SQL Server PowerPivot for Excel 2010 and SQL Server

PowerPivot for SharePoint 2010. PowerPivot for Excel gives analysts a way to integrate

large volumes of data outside of a corporate data warehouse, whether they are creating

reports to support decision making or prototyping solutions that will eventually be

part of a larger BI implementation. To provide multiple users with centralized access to

reports developed with PowerPivot for Excel, information technology staff can implement

PowerPivot for SharePoint. This server-side PowerPivot product provides the necessary

infrastructure to manage, secure, refresh, and monitor these PowerPivot reports efficiently.


190 CHAPTER 10 Self-Service Analysis with PowerPivot


PowerPivot for Excel


PowerPivot for Excel is an add-in that extends the functionality of Excel 2010 to support

analysis of large, related datasets on your computer. After installing the add-in, you can

import data from external data sources and integrate it with local files, and then develop the

presentation objects, all within the Excel environment. You save all your work in a single file

that is easy to manage and share.


The PowerPivot Add-in for Excel


To create your own PowerPivot workbooks or to edit workbooks that others have created,

you must first install the PowerPivot add-in for Excel 2010.


Modifications to Excel


When you install the add-in, several changes are made to Excel. First, the installation adds

the PowerPivot menu to the Excel ribbon. Second, it adds the PowerPivot window, a design

environment for working with PowerPivot data within Excel. You can use this design environment

to import millions of rows of data, which you can later view as summarized results in

Excel worksheets.


When you are ready to create a PowerPivot workbook, you click the PowerPivot tab on the

Excel ribbon and click the PowerPivot Window button in the Launch group (shown in Figure

10-1) to open the PowerPivot window. The PowerPivot window opens separately from the

Excel window, which allows you to switch back and forth as necessary between working with

your PowerPivot data and working with the presentation of that data in Excel worksheets.


FIGURE 10-1 The PowerPivot Window button in the Excel window


The Local Analysis Services Engine


The add-in also installs a local Analysis Services engine on your computer. Installation also

adds the client providers necessary for connecting to Analysis Services. PowerPivot uses the

Analysis Services engine to compress and process large volumes of data, which Analysis Services

loads into workbook objects.


The Analysis Services engine runs exclusively in-process in Excel, which means that there

is no need to manage a separate Windows service running on your computer. This version

of Analysis Services uses the new VertiPaq storage mode, which works efficiently with large

volumes of columnar data in memory. For example, VertiPaq mode allows you to very quickly

sort and filter millions of rows of data. Furthermore, you can store workbooks on your local

drive because VertiPaq compresses the data by tenfold on average.


PowerPivot for Excel CHAPTER 10 191


The Atom Data Feed Provider


Last, the add-in installs an Atom data feed provider to allow you to import data from Atom

data feeds into a PowerPivot workbook. A data feed provides data to a client application

on request. The structure remains the same each time you request data, but the data can

change between requests. Usually, you identify the online data source as a URL-addressable

HTTP endpoint. The online data source, or data service, responds to requests at this endpoint

by returning an atomsvs document that describes how to retrieve the data feed. When you

open an atomsvc document, the PowerPivot Atom data feed provider detects the file type

and prompts you to load data into PowerPivot. When you confirm the load operation, the

provider connects to the data service, which in turn encapsulates the data in XML by using

the Atom 1.0 format and sends the data to the provider.


Data Sources


Your first step in the process of developing a PowerPivot workbook is to create data sources

and import data into the workbook. You can import data from a variety of external data

sources, including relational or multidimensional databases, text files, and Web services. You

can also import data by linking to tables in Excel, or simply by copying and pasting data. Each

data source that you add to the workbook becomes a separate table.


External Data


When your data comes from an external data source, you use the applicable button in the

Get External Data group of the ribbon in the PowerPivot window, as shown in Figure 10-2.

The button you choose launches the Table Import Wizard for the type of data that you are

importing.


FIGURE 10-2 The Get External Data group in the PowerPivot window


You can choose from a wide variety of data sources:


¦ Databases


• SQL Server 2005, SQL Server 2008, SQL Server 2008 R2, and Windows Azure


• Microsoft Office Access 2003, Access 2007, and Access 2010


• SQL Server 2005 Analysis Services, SQL Server 2008 Analysis Services, and SQL

Server 2008 R2 Analysis Services


• Oracle 9i, Oracle 10g, and Oracle 11g


• Teradata V2R6 and Teradata V12


• Informix


• IBM DB2 8.1


• Sybase


• Any database that can be accessed by using an OLE DB provider or an ODBC driver


¦ Files


• Delimited text files (.txt, .tab, and .csv)


• Files from Excel 97 through Excel 2010


• PowerPivot workbooks published to a PowerPivot-enabled Microsoft SharePoint

Server 2010 farm


¦ Data feeds


• SQL Server 2008 R2 Reporting Services Atom data feeds


• SharePoint lists


• ADO.NET Data Services


• Commercial datasets, such as Microsoft Codename “Dallas”

(http://pinpoint.com/en-US/Dallas)


TIP A new feature in SQL Server 2008 R2 Reporting Services is the ability to export an

Atom data feed for any report, whether you export from a native mode or from an integrated

mode report server. If the PowerPivot client is installed on your computer when you

perform the export, PowerPivot detects the document type and opens a wizard for you

to use to import the data directly into a table. You might find it beneficial to get some of

your data integrated in a report first and take advantage of Reporting Services’ support for

calculations, aggregations, data sources, and refresh schedules before you bring the data

into PowerPivot.


The wizard walks you through the process of specifying connection information for the

source and selecting data to import. If your source is a database, you can choose to select

either tables or views or to provide a query for the data selection. Regardless of the data

source type, the wizard gives you two options for filtering the data before you import it. First,

you can select specific columns rather than importing every column from the source table.

Second, you can apply a filter to a column to select the row values to include in the import. By

applying these filtering options, you can eliminate unnecessary overhead in your workbook,

reducing both the file size of the workbook and the amount of time necessary to refresh and

recalculate the workbook.


TIP When you are working with large datasets, you should use the filtering options to

import only the columns you need for analysis. By limiting the workbook to the essential

columns, you can import more rows of data.


Linked Tables


If your data is in an Excel table already, or if you convert a range of data into an Excel table,

you can add the table to your workbook in the Excel window and then use the Create Linked

Table button to import the data into the PowerPivot window. You can find this button on the

PowerPivot ribbon in the Excel window, as shown in Figure 10-3. After the data is available in

the PowerPivot window, you can then enhance it by defining relationships with other tables

or by adding calculations.


FIGURE 10-3 The Create Linked Table button


One of the benefits of using an Excel table as a source for a PowerPivot table is the ability

to change the data in the Excel table to immediately update the PowerPivot table. Because

you cannot make changes to data in the PowerPivot window, a linked table is the quickest

and easiest way to edit the data in a PowerPivot table.It is also a great way to try out different

values in “what-if” scenarios or to use variable values in a calculation.


Another reason you might consider using a linked table is to support Time Intelligence functions

in PowerPivot’s formula language. Examples of Time Intelligence functions include TotalMTD,

StartOfYear, and PreviousQuarter. Often, source data includes dates and times but does not have

the corresponding attributes to describe these dates and times, such as month, quarter, or year.

You can create your own table in Excel with the necessary attributes, link it to PowerPivot, and

then use Time Intelligence functions to support analysis involving comparative time periods.


Copying and Pasting


If you do not need to change data after importing into PowerPivot, you can copy the data

from another Excel workbook and then in the PowerPivot window, click the Paste button

in the Clipboard group of the PowerPivot ribbon. The Paste preview dialog box displays to

shows the data to be pasted into PowerPivot. Although you cannot directly edit the data after

adding it to PowerPivot, you can replace it by pasting in fresh data or add to it by appending

additional data. To do this, you use the Paste Replace or Paste Append button, respectively.


Data Preparation


After importing data into tables, your next step is to prepare the data for analysis by defining

relationships between tables. You can also choose to enhance the data by applying filters and

modifying column properties.


Relationships


By building relationships between the data, you can analyze the data as if it all came from a

common source. Relationships enable you to use related data in the same PivotTable even

though the underlying data actually comes from different sources. Defining relationship

between columns into two PowerPivot tables is similar to defining a foreign key relationship

between two columns in a relational database. Excel power users can understand defining

relationships as analogous to using the VLOOKUP function to reference data elsewhere.


In addition to consolidating data for PivotTables, there are other benefits of building

relationships. You can filter data in a table based on data found in related columns, or you

can use the formula language to perform a lookup of values in a related column. These

techniques provide alternative ways to eliminate data redundancy, which keeps the workbook

smaller.


When you import related tables at the same time, the Table Import Wizard automatically

detects that they are related and creates the detected relationships. You can also manually

create relationships by using the Create Relationship button on the Design tab of the PowerPivot

ribbon, as shown in Figure 10-4.


NOTE A column cannot participate in more than one relationship, and you cannot create

circular relationships.


FIGURE 10-4 The Create Relationship button


Filters


After you import data into PowerPivot, you cannot delete rows from the resulting PowerPivot

table. To keep your workbook as small as possible, you should apply filters during the import

process to exclude unneeded rows right away. After completing the import, you can modify

the table properties to add a filter, and then update the table to keep only rows that meet the

filter criteria.


You can also apply filters to the imported data if you want the data to be available for other

purposes later, while hiding specific rows from the presentation layer in the current report.

You can filter by name in the same way that you normally filter in Excel, by selecting from a

list of values in a column to identify the rows that you want to keep. As an alternative, you

can filter a numeric column by value, as shown in Figure 10-5. For example, you can use the

Between operator to apply a filter that will select rows with a value in a range that you specify.


FIGURE 10-5 Filtering a numeric column by value


IMPORTANT Use of a filter is not a security measure. Although a filter effectively hides

data from a presentation, anyone who can open the Excel workbook can also clear the

filters and view the data if he or she has installed the PowerPivot add-in.


Columns


As part of the data preparation process, you might need to make changes to column properties.

On the Home tab of the PowerPivot ribbon, you can access tools to make some of these

changes, as shown in Figure 10-6. For example, you can select a column in the table and then

use the ribbon buttons to change the formatting of the column. You can also change the

width of the column for better viewing of its contents, or you can freeze a column to make it

easier to explore the data as you scroll horizontally.


FIGURE 10-6 The Home tab of the PowerPivot ribbon


Although the Table Import Wizard detects and sets column data types, you can use the

Data Type drop-down list on the ribbon to change a data type if necessary. You might need

to adjust data types to create a relationship between two tables, for example. PowerPivot

supports only the following data types:


¦ Currency


¦ Decimal Number


¦ Text


¦ TRUE/FALSE


¦ Whole Number


You can use the Hide and Unhide button on the Design tab (shown in Figure 10-4) to control

the appearance of a column in the PowerPivot window and also in the PivotTable Field List. For

example, you might choose to display a column in the PowerPivot window, but hide that column

in the PivotTable window because you want to use it in a formula for a calculated column.


PowerPivot Reports


A PowerPivot report is an Excel worksheet that presents your PowerPivot data in a summarized

form by using at least one PivotTable or PivotChart. You can convert a PivotTable to a

collection of cube function formulas if you prefer a free-form layout of your PowerPivot data.

Regardless of which layout you choose for the report, you can add slicers to support interactive

filtering.


PivotTables


You create a report by selecting a layout template from the PivotTable menu (available from

the PivotTable button on the PowerPivot ribbon, as shown in Figure 10-7) and specifying a

target worksheet in the Excel workbook. You can create a layout independently of the available

templates by selecting Single PivotTable or Single PivotChart as many times as you need

and targeting a different location on the same worksheet for each object.


FIGURE 10-7 Report layout templates


NOTE The standard Excel ribbon also includes buttons for building a PivotTable or

PivotChart, but you must use the buttons on the PowerPivot ribbon when you want to use

PowerPivot data.


Assume that you select the Chart And Table (Horizontal) template. Placeholders for the

chart and table appear on the worksheet, and a new worksheet appears in the workbook to


store the data that you selected for the chart. Just as you do with a standard PivotTable or

PivotChart, you select the placeholder and then use the associated field list to select and

arrange fields for the selected object, as shown in Figure 10-8.


FIGURE 10-8 A PivotChart and PivotTable report


Cube Functions


As an alternative to the symmetrical layout of a PivotTable, you can use cube functions in cell

formulas to arrange PowerPivot data in a free-form arrangement of cells. Cube functions,

introduced in Excel 2007, allow you to query an Analysis Services database and return metadata

or values from a cube. Because PowerPivot creates an in-memory version of an Analysis

Services database, you can also use cube functions with your PowerPivot data.


Although you can create a formula that uses a cube function in any cell in your PowerPivot

workbook, the simplest way to get started with these functions is to convert an existing PivotTable.

To do this, click the OLAP Tools button on the Options tab under PivotTable Tools, and

click Convert To Formulas. The conversion replaces the row and column labels with a formula

using the CUBEMEMBER function and replaces values with the CUBEVALUE function, as shown

in Figure 10-9. The first argument of either of these functions references the data connection,

which by default is Sandbox for embedded PowerPivot data. All other arguments are pointers

to dimension member names that define the coordinates of the value to retrieve from the

in-memory cube.


FIGURE 10-9 The CUBEVALUE function


Slicers


The task pane for PowerPivot is similar to the one you use for an Excel PivotTable, but it

includes two additional drop zones for slicers. Slicers are a new feature in Excel 2010 that can

be associated with PowerPivot. Slices work much like report filters but link to multiple objects,

such as a PivotTable and a PivotChart, so that the slicer selection can filter an entire report. If

two slicers are related, a selection of items in one slicer automatically highlights and filters the

related items in the second slicer. For example, if you select a year in one slicer, the quarters

related to that year in a second slicer will also be selected, as shown in Figure 10-10.


FIGURE 10-10 Selecting Year slicer values also selects QuarterCode slicer values.


Data Analysis Expressions


The ability to combine data from multiple sources into a single PivotTable is amazingly powerful,

but you can create even more powerful reports by enriching the PowerPivot data with

Data Analysis Expressions (DAX) to add custom aggregations, calculations, and filters to your

report. DAX is a new expression language for use with PowerPivot for Excel. DAX formulas

are similar to Excel formulas. However, rather than working with cells, ranges, or arrays as in

Excel, DAX works only with tables and columns. You can use DAX either to create calculated

columns or to create new measures.


Calculated Columns


A calculated column is the set of values resulting from an expression that you apply to a table

column or another calculated column. For example, you can concatenate values from two

separate columns to produce a single string value that displays in a third column. You can

also perform mathematical operations, manipulate strings, look up values in related tables, or

compare values to produce results in a calculated column. To add a calculated column, click

an empty cell under the Add Column column heading and type an expression in the formula

bar. In your report, you can use the new calculated column just like any other column from

your PowerPivot data. An expression that calculates gross profit looks like this:


=[Sales Amount]-[Total Product Cost]


Measures


A measure is a dynamic calculation that is displayed in the value area of the PivotTable. Its

value depends on the current selection of items in rows and columns and in the report filter.

A measure differs from a calculated column in that the calculated column values persist in

the PowerPivot data whereas the measure values calculate at query time and do not persist in

the data store. The calculated column values are scalar, and the measure values are aggregates.

Last, a calculated column may contain string values or numeric values, but a measure is

always a numeric value.


As an example, consider a calculated column that shows gross profit. The PowerPivot

table would include a gross profit value for each sales transaction, which a PivotTable can

later aggregate. However, if you create a calculated column to store a gross profit margin

percentage value, the aggregate in the PivotTable will not be correct because percentage

values are not additive.


To create a measure, you must first create a PivotTable or PivotChart. In the Excel window,

select the PivotTable or PivotChart, and then click the New Measure button on the PowerPivot

tab of the ribbon. You then provide a name for the measure for all PivotTables in the


report, provide a name for the current PivotTable if you want, and then specify the formula

for the measure, as shown in Figure 10-11.


FIGURE 10-11 Measure settings


DAX Functions


The examples shown for a calculated column and a measure are very basic, although representative

of the common ways that you would use DAX. Table 10-1 lists the types of functions

that DAX provides:


TABLE 10-1 DAX Function Types


FUNCTION TYPE


EXAMPLE


DESCRIPTION


Date and time


=WEEKDAY([OrderDate],1)


Returns the number of the weekday

where Sunday = 1 and Saturday = 7


Filter and value


=FILTER(ProductSubcategory,

[EnglishProductSubcategoryName]

= “Road Bikes”)


Returns a subset of a table based

on the filter expression


Information


=IsNumber([OrderQuantity])


Returns TRUE if the value is numeric

and FALSE if it is not


Logical


=IF([OrderQuantity]<10,”low”,

IF([OrderQuantity]<100,”medium”

,”high”))


Returns the second argument’s

value if the first argument’s condition

is TRUE and otherwise returns

the third argument’s value


Math and trig


=ROUND([SalesAmount] *

[DiscountAmount],2)


Returns the value of the first argument

rounded to the number of

digits specified in second argument


FUNCTION TYPE


EXAMPLE


DESCRIPTION


Statistical


=AVERAGEX(ResellerSales,

[SalesAmount]-

[TotalProductCost])


Evaluates the expression in the

second argument for each row of

the table in the first argument, and

then calculates the arithmetic mean


Text


=CONCATENATE([FirstName],

[LastName])


Returns a string that joins two text

items


Time Intelligence


=DATEADD([OrderDate],10,day)


Returns a table of dates obtained

by adding the number of days

specified in the second argument

(or other period as specified by

the third argument) to the column

specified in the first argument


PowerPivot for SharePoint


PowerPivot for SharePoint provides server-side support for PowerPivot workbooks by

extending the capabilities of SharePoint and Excel Services in SharePoint. SharePoint provides

centralized management of the PowerPivot workbooks, and Excel Services manages data

queries and the rendering of the query results in the browser. Installation of PowerPivot for

SharePoint adds services to the SharePoint farm and includes a document library template,

content types, dashboards, and Web parts that provide access to PowerPivot reports and

support monitoring their usage.


Architecture


PowerPivot for SharePoint requires SharePoint Enterprise Edition and Excel Services. You

must install Analysis Services with SharePoint Integration on a SharePoint Web front end. In

SharePoint Central Administration, you configure the PowerPivot System Service and activate

the PowerPivot feature on the target site collection. PowerPivot for SharePoint uses a scalable

architecture (shown in Figure 10-12) that allows you to add or remove instances as needed

when you require more or less processing capacity. When you add an instance, the SharePoint

autodiscovery feature ensures that the new instance can be found, and the PowerPivot

System Service has a load balancing feature that will use the new instance when possible.


SharePoint Farm

Web front end Application server

PowerPivot

database

Analysis Services-

VertiPaq Mode

Excel Calculation

Services

PowerPivot

System Service

Excel Web Access

Excel Web Service

PowerPivot

Web Service

Excel 2010 with

PowerPivot-

View or

create reports

Browser-

View reports


FIGURE 10-12 PowerPivot for SharePoint Architecture


Analysis Services in VertiPaq Mode


To support users without the PowerPivot for Excel client, Excel Services connects to a server

instance of Analysis Services in VertiPaq mode to process PowerPivot workbooks and respond

to user queries. This type of Analysis Services server instance enables in-memory data storage

on a large scale for multiple users and provides rapid processing of large PowerPivot data

sets. Just like the in-memory version of VertiPaq mode on the client, the server version uses

data compression and columnar storage. Unlike a standard Analysis Services instance that

you manage using SQL Server Management Studio, you manage Analysis Services in VertiPaq

mode exclusively in SharePoint Central Administration.


In response to requests for PowerPivot data, Analysis Services loads the cube into memory

where it stays until no longer required or until SharePoint monitoring detects that contention

for resources has reached a threshold requiring action. You can monitor system performance

through usage data, as explained later in this chapter. Analysis Services loads the PowerPivot

data from the workbook as raw, unaggregated data into the cube, compresses the data, and

dynamically restructures the data based on the user’s actions.


The PowerPivot System Service


The PowerPivot service runs as a service application on SharePoint called PowerPivot System

Service. A service application is configurable independently of other service applications and

isolates service application data. You can install one physical instance of a server but then

create multiple service applications to isolate data at the application level. Another benefit of

the service application model is the ability to delegate administration.


The PowerPivot System Service listens for requests for PowerPivot data, connects to Analysis

Services to manage the loading and unloading of PowerPivot data, collects usage data,

and monitors system health and availability of Analysis Services servers. It also provides load


balancing across servers for query processing if multiple servers are available. Furthermore,

the PowerPivot System Service manages the connections for active, reusable, and cached

connections to PowerPivot workbooks, as well as administrative connections to other PowerPivot

System Services on the SharePoint farm.


To speed up access to data, the PowerPivot System Service caches a local copy of a workbook

and stores it in Program Files\Microsoft SQL Server\MSAS10_50.POWERPIVOT\OLAP\

Backup. The service unloads this copy of the workbook from memory if no one has accessed

the workbook after 48 hours and deletes it from the folder after an additional 72 hours of

inactivity. If a user updates the workbook in SharePoint and a copy of the workbook already

exists in the cache, the PowerPivot System Service also removes the older cache copy.


The PowerPivot Database


Each service application has its own relational database, called the PowerPivot database. In

particular, this PowerPivot database stores the load or cache status of workbooks, server usage

information, and schedule information for data refresh operations. More specifically, the

application database stores an instance map that identifies whether a workbook is currently

loaded on the server or in the cache. Usage information in the application database applies to

connections, query response times, load and unload events, and other information pertinent to

server health statistics. The data refresh schedule information includes details about data sources,

users, and the workbooks associated with a schedule. None of the workbook content is in the

PowerPivot database. Instead, workbooks are stored in the SharePoint content database.


The PowerPivot Web Service


The PowerPivot Web Service is a thin middle-tier connection manager implemented as a Windows

Communication Foundation (WCF) Web service that runs on a SharePoint Web front end.

The Web service listens on the port assigned to a Web application enabled for PowerPivot, and

responds to requests by coordinating the request-response exchange between client applications

and PowerPivot for SharePoint instances in the farm. This Web service requires no

separate configuration or management.


The PowerPivot Managed Extension


The PowerPivot Managed Extension is an assembly in the Analysis Services OLE DB provider

client. This provider client is installed on a client computer when you install the PowerPivot

for Excel add-in, and on the SharePoint server when you install PowerPivot for SharePoint. For

managed connections, the Web service and the managed extension operate the same way.

The query processing request determines which one is used.


Content Management


Content management for PowerPivot is quite simple because the data and the presentation

layout are kept in the same document. If they weren’t, you would have to maintain separate

files in different formats and then manually integrate them each time one of the files required

replacement with fresh data. By storing the PowerPivot workbooks in SharePoint, you can

reap the benefits applicable to any content type, such as workflows, retention policies, and

versioning. For example, you can copy data to a new location by copying the document. Or if

you need to formally approve data before allowing others to access it, you can easily set up a

document approval workflow.


The PowerPivot Gallery


The PowerPivot Gallery is a special type of document library that provides document management

capabilities for PowerPivot workbooks. You can use it to preview and open PowerPivot

workbooks from a central location. In the PowerPivot Gallery, shown in Figure 10-13,

you can see all available sheets in the workbook as thumbnails with current data, without

opening the workbook. A snapshot service creates the thumbnail images by periodically

reading the workbooks file.


FIGURE 10-13 The PowerPivot Gallery


In addition to the default Gallery view, the PowerPivot Gallery also includes the Theater

and Carousel views, which are most useful when you want to highlight a small number of

workbooks. In Theater view, you can see a central preview area, and thumbnails of the other

reports in the workbook display at the bottom of the page. In Carousel view, the thumbnails

appear to the left and right of the preview area. In either of these views, you can click the left


or right arrow to bring a different thumbnail into the preview area. You can also switch to All

Documents view, which allows you to see all the workbooks in a standard document library

view. You can then download a document, check documents in or out, or perform any other

activity that is permissible within a document library.


The Data Feed Library


A special type of document library is available for the storage of Atom svc documents, also

known as data service documents. You can share these documents for the use of other

PowerPivot authors who want to import data feeds into PowerPivot tables. You can create

a data service document in the document library by specifying the URL request to the data

service or Web application that serves data on request. The URL request should include a

parameter that requests data in the Atom 1.0 format.


Data Refresh


In addition to the content management support, another good reason to share a PowerPivot

workbook in SharePoint is to manage the data refresh process. Usually, data that appears in a

PowerPivot table changes from time to time. To keep the workbook up to date and relevant,

you must periodically update the data. You can automate this process by assigning a refresh

schedule to each data source in the workbook.


The data refresh feature is not enabled by default. When you enable data refresh, a timer

job runs every minute on the PowerPivot server. This job is a trigger for the PowerPivot System

service, which in turn reads the predefined schedule found in the PowerPivot database. When

a schedule to run is found, the PowerPivot System Service gets the list of data sources and the

credentials to use, and initiates the data refresh. If the workbook is not checked out or in edit

mode, the data refresh job saves the new data to the workbook.


Linked Documents


Your PowerPivot workbook can be used as a data source for other report types. When

viewing the workbooks in the PowerPivot Gallery, you can use the Create Linked Document

button to create either a Reporting Services report or a PowerPivot report in Excel. You must

have the appropriate client application for the report type that you choose. That is, to build

a Reporting Services report, you must first install SQL Server 2008 R2 Report Builder 3.0, and

to build a PowerPivot report, you must install the PowerPivot for Excel add-in. The query

designer in Report Builder and the Field List in Excel display only the fields presented in the

source workbook rather than all fields available in that workbook’s embedded data.


The PowerPivot Web Service


Another way to use a PowerPivot workbook as a data source is by using the PowerPivot Web

Service to connect to the embedded data. That way, you can reuse the data in multiple places

without having to duplicate all the effort required to create the initial workbook. Any client


application that can connect to Analysis Services directly can use the PowerPivot Web Service. You

simply use the SharePoint URL for the workbook instead of an Analysis Services server name in the

connection string of the provider. For example, if you have a workbook named Bike Sales.xlsx in

the PowerPivot Gallery located at http://<servername>/PowerPivot Gallery, the SharePoint URL to

use as an Analysis Services data source is http://<servername>/PowerPivot Gallery/Bike Sales.xlsx.


The PowerPivot Management Dashboard


PowerPivot for SharePoint includes several tools for configuring the service application and

for monitoring usage in a management dashboard. All management tools are accessible to

farm and service administrators in Central Administration. The easiest way to access settings

related to PowerPoint for SharePoint is to use the PowerPivot Management Dashboard.


The PowerPivot Management Dashboard displays data for one service application at a time.

In this dashboard, you can see a collection of Web parts and PowerPivot reports that display data

that is collected daily from multiple sources. One of the Web parts displays a chart showing CPU

and memory usage over time to help you determine whether the server is running at maximum

capacity or whether it is underutilized. Another Web part shows trending of query response times,

which you can use to determine whether queries are responding within configurable thresholds.

The dashboard page includes links to the PowerPivot reports that provide the source data for

these Web parts. These reports consist of data from an internal reporting database that in turn

collects data from the PowerPivot database, SharePoint usage log data, and other sources. You

can build new reports using this internal reporting database as a source, but you cannot change it.


In addition to giving you information about the state of the server, the dashboard also

provides insight into the usage of published workbooks. An interactive chart allows you to

monitor which workbooks users access most frequently and which workbooks have recent

activity. You can view this information at the daily or weekly level.


One section of the dashboard provides information about data refresh activity, providing a

single location from which you can verify whether data refreshes are occurring as scheduled.

One Web part in this section lists recent activity for data refresh jobs by workbook and also

includes the job duration. Another Web part lists the workbooks for which the data refresh

job fails, and displays the data refresh error message as a tooltip.


The dashboard is also extensible. It includes a link to add new items, which you can use to

add more workbooks to access from the dashboard page. For example, you can create a new

PowerPivot workbook by using the Usage workbook as a data source, and then upload your

workbook to the same document library.


Last, the dashboard page includes links to pages in Central Administration that you can

use to check or reconfigure the settings for PowerPivot. One link takes you to the service

settings page, where you can schedule database timeouts, data refresh hours, and query response

time thresholds. You can use another link to review timer job settings for data refresh,

dashboard processing, PowerPivot configuration, and the health statistics collector. A third

link takes you to the settings page for usage log collection.


Index


207


A


adapter base classes, 151


AdapterFactory objects, 152


adapters, for CEP applications, 151-154


Admin Console, 122


aggregate functions, 168


AJAX, 186


Analysis Services engine, 123, 190


annotating transactions in MDS, 134


application errors, monitoring, 122


applications, data-tier. See DACs (data-tier applications)


arrays, converting comma-separated lists of values

into, 167


Atom data feed


exporting reports to, 182


importing data into PowerPivot workbook, 191


authentication


Extended Protection for, 10


in MDS (Master Data Services), 127


authorization (MDS), 138


Azure, 9


B


Backup node, 114


Best Practices Analyzer (BPA)


overview of, 11


running, 71


binding query templates, 162


Bing Maps tile layers as backgrounds, 177


browser support for Reporting Services, 186


built-in fields, 170


business intelligence (BI) integration, 123


business rules (MDS), 132-133


C


Cache Refresh (reports), 179-180


calculated columns, 199


capacity planning, 25


Carousel view (PowerPivot Gallery), 204-205


class library (MDS), 142-143


Cluster Shared Volumes (CSV). See CSV (Cluster

Shared Volumes)


collections (MDS), 130


comma-separated lists of values, converting into

arrays, 167


Compact edition, 14


complex event processing (CEP). See also StreamInsight


adapters, 151-154


application development cycle, 150


application language, 146


applications for, 145-146


defined, 145


diagnostic views, 163


filtering operation, 155


input adapters, 148


output adapters, 149


overview of, 145


projection operation, 155


query instances, 149


query templates, 154


server, 147-149


compression, Unicode, 10


compute node, 114-115, 118


connecting to UCPs, 33-34, 89


consolidation


of databases, 86


goals of, 85


management strategies, 5


with virtualization, 87-88


control node, 112-113


208


control racks, 112


count windows, 159


CPU


overutilized, 92


upgrading online, 63


CREATE DATABASE statement, 118


Create Package wizard, 142


CREATE REMOTETABLE statement, 120


CREATE TABLE statement, 118-120


Create Utility Control Point Wizard, 26-28


CSV (Cluster Shared Volumes). See also failover clustering


adding storage to, 76


enabling, 76


overview of, 64


storage location, 76


cube functions, 197


D


DAC file packages, 45


DACs (data-tier applications)


benefits of, 44


configuration options, 53


defined, 41


definition registration, 49


definition storage, 43


deleting, 56-58


deploying, 4, 45, 52-55


detaching database, 56


extracting, 49-51


generating, 43


importing, 47-48


life cycle of, 42-43


monitoring, 93-94, 100-105


project templates, 45-46


properties, setting, 49-50


red or yellow icons, 45


registering, 55-56


SQL Server objects supported in, 44-45


upgrading, 59-61


uses for, 43


Visual Studio deployment of, 45-46


dashboard, PowerPivot, 206


Data Analysis Expressions (DAX), 199-201


data bars, 175


data colocation, 114-115


data feed, Atom


exporting reports to, 182


importing data into PowerPivot workbook, 191


data feed libraries, 205


Data Movement Service (DMS), 112


data racks, 111


data sources


joining, 166-168


for PowerPivot for Excel, 191-193


data stewards, 127


data types


supported in Parallel Data Warehouse, 120


supported in PowerPivot, 195


data warehouse appliances, 109-110. See also Parallel

Data Warehouse


database consolidation, 86


database creation, 118


database objects, managing, 122


Datacenter edition, 12


datasets. See also PowerPivot for Excel; PowerPivot for

SharePoint


combining data from multiple, 166-168


importing large, 192


shared, 179


data-tier applications (DACs). See DACs (data-tier

applications)


Data-Tier Applications viewpoint (Utility Explorer),

100-105


DAX (Data Analysis Expressions), 199-201


DDL extensions, 117


default policies, restoring, 36


definitions, DAC


registering, 49


storing, 43


Delete Data-Tier Application Wizard, 56-58


Deploy Data-Tier Application Wizard, 52-55


deploying DACs, 45


configuration options, 53


with Deploy Data-Tier Application Wizard, 52-55


overview of, 4


report for, 54


in Visual Studio 2010, 45-46


deploying StreamInsight, 149-150


deploying UCPs


with Create Utility Control Point Wizard, 26-28


prerequisites for, 25, 26


report, saving, 28


with Windows PowerShell, 28


detaching DAC database, 56


Developer edition, 13


diagnostic views (StreamInsight), 163


disconnecting from UCPs, 34


disk space consumption, 25


control racks


209


disk space requirements, 15


DMS (Data Movement Service), 112


document libraries, 204-205


DomainScope property (reports), 173


DWLoader, 122


Dwsql, 122


dynamic report formatting, 169-170, 172-173


dynamic virtual machine storage, 64


E


edge event model, 147


edit sessions, 183


enrolling instances, 29-32


enterprise data warehousing. See Parallel Data

Warehouse


Enterprise edition, 12, 29


entities (MDS), 129-130


event classification, 154


event stream objects, 154


aggregation operations, 159-160


consumer objects, 162


event types, 150-151


event windows, 156-159


Excel add-ins. See PowerPivot for Excel


Excel tables, linking to PowerPivot tables, 193


Excel workbooks, 173, 193


exporting master data, 136-137


exporting tables, 120


Express edition, 13


expression language, 165-171. See also Data Analysis

Expressions (DAX)


expressions, 183


Extended Protection for Authentication, 10


Extract Data-Tier Application Wizard, 45, 49-51


extracting DACs (data-tier applications), 49-51


F


Failover Cluster Manager, 80


failover clustering. See also CSV (Cluster Shared Volumes)


benefits of, 65


best practices compliance, testing, 11, 71


connecting by multiple networks, 65


enhancements in Windows Server 2008, 63


guest model, 67-68


history of, 64-65


traditional model, 65


troubleshooting, 70


validating prerequisites for, 68-70


feedback on book, xix


file space utilization monitoring, 96


filtering operation, 155


filtering PowerPivot data, 192, 194


formatting reports dynamically, 169-170, 172-173


free edition. See Express edition


functions


aggregate, 168


cube, 197


Lookup, 166


LookupSet, 168


MultiLookup, 167


Split, 167


Time Intelligence, 193


Transact-SQL, 143-144


G


Generate And Publish Scripts Wizard, 9


global monitoring settings, 34


guest failover clustering, 67-68


H


hardware, upgrading online, 63


hardware requirements, 14-15


headers and footers, 170


hierarchies (MDS), 130


high availability enhancements, 63-64


hopping windows stream, 157


hot adding hardware, 63


hub-and-spoke architecture, 115


Hyper-V. See also Live Migration; virtualization


benefits of, 74


on guest failover clustering, 67-68


improvements in, 11


overview of, 64


system requirements for, 73-74


uses for, 74


virtual machines, creating with, 76-79


Hyper-V Integration Services tool, 79


Hyper-V Integration Services tool


I


importing master data, 135


indicators in reports, 176-177


InfiniBand network, 110, 112


in-place upgrades, 16-17


input adapters, base classes, 151


installing MDS (Master Data Services), 127


instances. See also managed instances; SQL Server

instances


enrolling, 29-32


utilization, monitoring, 91


validating, 31


viewing, 91


Integration Services, 123


InteractiveSize property (reports), 172


Internet Explorer requirement, 15


interval event model, 147


J


join operations, 161


L


Landing Zone node, 114


linked documents, 205


linked tables, 193


LINQ expressions, 155


Live Migration. See also Hyper-V


benefits of, 87-88


configuring virtual machines for, 79-82


implementing, 75


initiating, 83


overview of, 64, 72


load activity, monitoring, 122


look-and-feel properties, 169-170


Lookup function, 166


LookupSet function, 168


M


managed instances. See also instances; SQL Server

instances


global policies for, 34


health status of, 91


maximum number of, 29


overutilized resources, 92


processor utilization, 96


underutilized resources, 92


viewing, 91


Managed Instances viewpoint (Utility Explorer), 95-100


management node, 114


management utilities. See Best Practices Analyzer (BPA);

SQL Server Utility


ManagementService API, 163


maps, 177-178


massively parallel processing (MPP), 9


master data, 125-126


Master Data Manager


areas in, 128-129


batch creation, 135-136


data maintenance with, 131


data stewards, 127


model deployment, 142


subscription view, creating, 136


Master Data Services Configuration Manager, 128


MDS (Master Data Services)


API, 127, 142-143


authentication, 127


authorization, 138


business rules, 132-133


class library, 142-143


configuring, 128


data stewards, 127


database, 128


as development platform, 142


exporting master data, 136-137


flexibility of, 126


importing master data, 135


installing, 127


locking data in, 139-140


master data hub, 126


overview of, 125


permissions, 138


tables in, 135


transaction logs, 131-134


Transact-SQL functions, 143-144


versioning, 127-128, 137-138


Web services API, 143


measures (PivotTables), 199-200


members (MDS), 129-130


memory, upgrading online, 63


memory requirements, 14


Microsoft Assessment and Planning Toolkit, 75


Microsoft Press support Web site, xix


Microsoft SQL Azure, 9


importing master data


migrating SQL Server installations, 18-19


migrating virtual machines. See Live Migration


models (MDS)


defined, 129


deploying, 142


security settings, 139-140


monitoring, with SQL Server Utility, 89


monitoring DACs, 100-105


monitoring settings, 34


MPP architecture, 110


msdb database


creation of, 52


disk space consumption, 25


MultiLookup function, 167


multi-rack system


Backup node, 114


compute node, 114-115


control node, 112-113


control rack, 112


data racks, 111


Landing Zone node, 114


management node, 114


overview of, 110


N


naming UCPs, 27


nesting aggregate functions, 168


.NET Framework requirement, 15


New Virtual Machine Wizard, 76-77


Nexus query tool, 122


non-transactional reference data, 125-126


O


objects, SQL Server, 45


operating system requirements, 15


output adapters, 151


overutilized instances, 91


overutilized threshold default, 34


P


page headers and footers, 170


page numbering in reports, 170


PageName property (reports), 173


pagination, report, 172-173


Parallel Data Warehouse


Admin Console, 122


architecture of, 109-115


automatic growth feature, toggling, 118


configuring, 110


control node, 112-113


creating tables, 118-120


data load processing, 121-122


data types supported in, 120


DDL extensions, 117


distributed strategy, 116-117


networking technologies, 112


overview of, 9, 109


query processing, 121


replicated strategy, 116


shared nothing (SN) architecture, 115-120


Parallel Data Warehouse edition, 12


pasting data into PowerPivot, 193


PivotCharts, creating, 196


PivotTables. See also tables


converting to formulas, 197


creating, 196


measures, 199-200


point model, 147


policies


changing, 36


defaults, restoring, 36


managing, 34


violation reporting settings, 35


PowerPivot database, 203


PowerPivot for Excel


Analysis Services engine, 190


Atom data feed, importing, 191


columns, formatting, 195


copying and pasting data into, 193


creating databases, 118


cube functions, 197


data sources, creating, 191-193


data types, changing, 195


filtering data, 194


hiding columns, 196


installing, 190


modifications made by, 190


overview of, 189


relationships in, 194


slicers, 198


Time Intelligence functions, 193


VertiPaq storage mode, 202


workbook, creating, 190


PowerPivot for Excel


PowerPivot for SharePoint


application database, 203


architecture of, 201


caching, 203


content management, 204


data feed libraries, 205


data refreshing in, 205


linked documents, creating, 205


overview of, 10, 189, 201


Parallel Data Warehouse and, 123


prerequisites for, 201


System Service, 202-203


PowerPivot Gallery, 204-205


PowerPivot Managed Extension, 203


PowerPivot Management Dashboard, 206


PowerPivot reports, 196-198


PowerPivot Web Service, 203, 205-206


PowerShell. See Windows PowerShell


premium editions. See Datacenter edition; Parallel Data

Warehouse edition


processor requirements, 14


projection operation, 155


publishing reports, 180-182


Q


query objects, 163


query processing (Parallel Data Warehouse), 121


query templates, 154, 162


QueryTemplate object, 154


R


RAM requirements, 14


registering DAC definitions, 49, 55-56


relationships, in PowerPivot, 194


relative references in expressions, 183


RenderFormat global variable, 169-170


replicated tables, creating, 118-120


Report Builder 3.0, 183


Report Designer, 123


Report Manager, 184-186


Report Part Gallery, 183


report variables, 170-171


Report Viewer, 186


Reporting Services, 186-188. See also reports


reports


alternate access mappings, 187


cache configuring, 179-180


on DAC deployment, 54


data synchronization, 173


data visualization enhancements, 175-178


edit sessions, 183


exporting to Atom data feed, 182


layout, dynamic, 169-170, 172-173


naming pages in, 173


nesting items in, 173


page numbering, 170


pagination, managing, 172-173


parts, searching for, 183


PowerPivot, 196-198


publishing in parts, 180-182


reusability of components in, 178-182


sandboxing, 186


text box orientation, 174


on UCP creation, 28


on validation, 28, 31


ResetPageNumber property (reports), 172


resource isolation, 186


resource utilization monitoring, 95-99


reusability of report components, 178-182


Role-Based Access security model, 39


rs.exe, 187


S


sandboxing reports, 186


scalability, 10


Second Level Address Translation (SLAT), 64


security


in MDS (Master Data Services), 138-141


Role-Based Access model, 39


SequeLink client drivers, 112-113


Server Manager, 11


shared datasets, 179


shared nothing (SN) architecture, 115-120


SharePoint, Reporting Services integration, 187-188


SharePoint Unified Logging Service, 188


shell access. See Windows PowerShell


side-by-side migration, 18-19


SLAT (Second Level Address Translation), 64


slicers, 198


SMP architecture, 110


PowerPivot for SharePoint


snapshot windows, 158


software requirements, 15


sparklines, 176


Split function, 167


SQL Azure, 9


SQL Server editions, 11. See also specific editions


SQL Server instances. See instances; managed instances


SQL Server Management Studio, 49-51


SQL Server objects, 44-45


SQL Server PowerShell. See Windows PowerShell


SQL Server Utility. See also Utility Control Points (UCPs);

Utility Explorer


dashboard, 89-95


monitoring with, 89


overview of, 4, 21-23


Standard edition, 13


StreamInsight


aggregation functions, 159-160


core engine, 146


deploying, 149-150


development support, 146


event models, 147


event windows, 156-159


events, 147


as hosted assembly, 149


join operations, 161


ManagementService API, 163


overview of, 145


query objects, 163


as standalone server, 149-150


streams, 147


TopK operation, 160


union operations, 161


subscription views (MDS), 136


support for book, xix


Sysprep, 9


sysutility_mdw. See Utility Management Data

Warehouse (UMDW)


T


tables. See also PivotTables


calculated columns in, 199


exporting, 120


loading rows into, 122


measures in, 199-200


text box orientation in reports, 174


Theater view (PowerPivot Gallery), 204-205


Time Intelligence functions (PowerPivot), 193


TopK operation, 160


transaction logs


for MDS, 131-134


space allocation, 118


Transact-SQL functions, 143-144


troubleshooting failover clustering, 70


tumbling windows, 157-158


U


UCPs (Utility Control Points). See Utility Control Points

(UCPs)


UMDW (Utility Management Data Warehouse). See

Utility Management Data Warehouse (UMDW)


underutilization thresholds


default, 34


variance in, 85


underutilized instances, 91


Unicode compression, 10


union operations, 161


upgrading data-tier applications (DACs), 59-61


upgrading hardware online, 63


upgrading SQL Server


in-place upgrades, 16-17


side-by-side migration, 18-19


user-defined functions (UDFs), 161


Utility Administrator, 37


utility collection set account, specifying, 27, 30


Utility Control Points (UCPs), 21-22


capacity specifications, 25


connecting to, 33-34, 89


creating, 26-29


disconnecting from, 34


enrollment of, 29


frequency of data collection, 23


managed instances, maximum number of, 29


msdb database, 25, 52


naming, 27


overview of, 4, 23


prerequisites for deployment, 25-26


report on creation of, 28


SQL Server edition required for, 26


validating, 28


Utility Control Points


Utility Explorer. See also SQL Server Utility


dashboard and list views, 5, 24


data refreshing in, 29


Data-Tier Applications viewpoint, 100-105


launching, 24


Managed Instances viewpoint, 95-99


user interface, 24


Utility Administration node, 33-36


Utility Management Data Warehouse (UMDW), 23


collection upload frequency, 23


data retention period, modifying, 39-40


disk space consumption, 25


verifying, 29


Utility Reader, 37-38


utility storage utilization history, 94-95


utilization policies, 6, 34-35


V


Validate A Configuration Wizard, 68-70


validating failover clustering setup, 68-70


validating instances, 31


validating UCPs, 28


validation reports, 28, 31


VertiPaq storage mode, 190, 202


violation reporting settings, 35


virtual machines


automatic start action, configuring, 79-80


configuring for Live Migration, 79-82


creating with Hyper-V, 76-79


high availability, configuring, 81-82


live migration of. See Live Migration


virtualization. See also Hyper-V


consolidation with, 87-88


technology for, 72


Visual Studio 2010


deploying DACs from, 45-46


importing DACs into, 47-48


volume space utilization monitoring, 97


W


Web browser support for Reporting Services, 186


Web edition, 13


windows, event, 156-159


Windows Communication Foundation (WCF) Web

services, 203


Windows domain accounts, 27, 30


Windows PowerShell


deploying UCPs with, 28


diagnostics, 164


enrolling instances with, 32


improvements in, 11


launching, 28


Windows Server 2008 integration, 10-11


workbooks, 173, 192


Workgroup edition, 13


WritingMode property (reports), 174


Utility Explorer


215


About the Authors


Ross Mistry is a technical architect at the Microsoft Technology Center

(MTC) in Silicon Valley. Ross provides executive briefings, architectural

design sessions, and proof of concept workshops to organizations

located in the Silicon Valley. His core specialty is Microsoft SQL Server,

although he also focuses on Windows Active Directory, Microsoft Exchange,

and Windows Server Hyper-V.


Ross’s latest books include Windows Server 2008 R2 Unleashed and

Microsoft SQL Server 2008 Management and Administration. He was a

contributing writer on Microsoft Exchange Server 2010 Unleashed, Microsoft

SharePoint 2007 Unleashed, and Windows Server 2008 Hyper-V Unleashed. He frequently

writes for TechTarget and is currently working on a series of SQL Server virtualization white

papers, which will be published shortly. Ross is a former SQL Server MVP, is well known in the

worldwide SQL Server community, and frequently speaks at technology conferences and user

groups around the world. He has recently spoken at the North American PASS Community Summit,

SQL Connections, European PASS, SQL BITS, and Microsoft.


Prior to joining Microsoft, Ross was a managing partner and principal consultant at Convergent

Computing (CCO), where he was responsible for designing and implementing technology

solutions for organizations with a global presence. Some of his customers included eBay,

McAfee, Yahoo!, Gilead Sciences, Ross Stores, The Sharper Image, McDonald’s, CIBC, Radio Shack,

Wells Fargo, and TD Waterhouse.


You can follow and contact Ross on Twitter @RossMistry.


Stacia Misner is the founder of Data Inspirations (www.datainspirations.

com), which delivers global business intelligence (BI) consulting and

education services. She is a consultant, educator, mentor, and author

specializing in business intelligence and performance management

solutions that use Microsoft technologies. Stacia has more than 25 years

of experience in information technology and has focused exclusively on

Microsoft BI technologies since 2000. She is the author of Microsoft SQL

Server 2000 Reporting Services Step by Step, Microsoft SQL Server 2005

Reporting Services Step by Step, Microsoft SQL Server 2005 Express Edition:

Start Now!, and Microsoft SQL Server 2008 Reporting Services Step

by Step and the coauthor of Business Intelligence: Making Better Decisions Faster, Microsoft SQL

Server 2005 Analysis Services Step by Step, and Microsoft SQL Server 2005 Administrator’s Companion.

She is also a Microsoft Certified IT Professional-BI and a Microsoft Certified Technology

Specialist-BI. Stacia lives in Las Vegas, Nevada, with her husband, Gerry. You can contact Stacia

via e-mail at smisner@datainspirations.com.
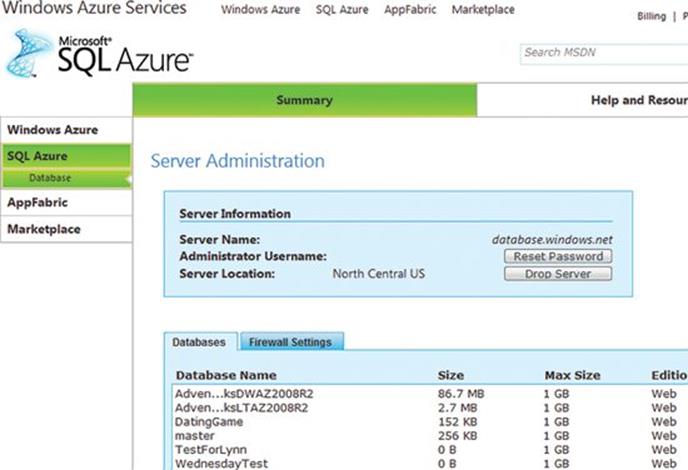


First Look Office 2010


Table of Contents


Acknowledgments ix


Introduction . xi


Part I Envision the Possibilities


1 Welcome to Office 2010 . 3


Features that Fit Your Work Style . 3


Changes in Office 2010 4


Let Your Ideas Soar . 5


Collaborate Easily and Naturally 5


Work Anywhere—and Everywhere . 6


Exploring the Ribbon 7


A Quick Look at the Ribbon 8


Contextual Tabs . 9


New Backstage View 9


Managing Files in Backstage View . 10


Streamlined Printing . 11


Languages and Accessibility 11


Coming Next 12


2 Express Yourself Effectively and Efficiently 13


Understanding Your Audience 14


How Visuals Help . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 15


Adding Text Effects . 16


Adding Artistry to Your Images 17


Correcting and Recoloring Pictures . 18


Working Font Magic in Word 2010 and Publisher 2010 . . . . . . . . . . . . . . . . . . . 21


Creating Data Visualizations in Excel 2010 . 23


Editing Video in PowerPoint 2010 24


Communicating Visually in Access 2010 . 25


Enhancing and Streamlining Communications in Outlook 2010 26


Coming Next 28


iv Table of Contents


3 Collaborate in the Office and Around the World 29


It’s All About the Teamwork 29


What Teams Look Like Today 30


Team Tasks and Methods 30


Benefits of Office 2010 Collaboration 32


Stay in Touch with Your Team . 32


Share Files in the Workspace 33


Share Files and Folders 34


Co-Author Files Across Applications 34


Connect via Presence 36


Using Office Web Apps 37


Sharing on the Road with Office Mobile . 38


Coming Next 38


Part II Hit the Ground Running


4 Create and Share Compelling Documents with Word 2010 41


Start Out with Word 2010 41


Get Familiar with the Word Ribbon . 42


Find What You Need Easily with the Navigation Pane . 43


Print and Preview in a Single View . 45


Format Your Text . 45


Apply Text-Formatting Effects 47


Preserve Your Format Using Paste with Live Preview . 48


Illustrate Your Ideas 49


Apply Artistic Effects 50


Insert Screen Shots 51


Improve Your Text . 52


Catch More Than Typos with a Contextual Spell Check . 52


Use Language Tools, and Translate on the Fly . 53


Co-Author and Share Documents 55


Working with Shared Documents 57


Access Your Documents Anywhere 58


Use Word Web 2010 . 59


Check Your Document with Word Mobile 2010 60


Table of Contents v


5 Create Smart Data Insights with Excel 2010 61


Start Out with Excel 2010 . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 61


Summarize Your Data Easily 63


Illustrate Information Effectively 65


Call Attention to Your Data with Icon Sets . 66


Data Bar Improvements . 68


New SmartArt Enhancements 70


Use Slicers to Show Data Your Way 70


Work Anywhere with Excel 2010 72


Excel 2010 Web App . 72


6 Manage Rich Communications with Outlook 2010 75


Starting Out with Outlook 2010 . 76


Using the Outlook 2010 Ribbon . 77


Setting Preferences with Backstage View . 77


Managing Your Conversations 78


Cleaning Up Your Messages 80


Streamlining E-mail Tasks 81


Working with Presence and Social Media . 83


Coordinating Calendars . 84


Viewing Group Schedules 84


Create a Calendar Group . 85


Improving the Look of Your Messages 86


Keeping in Touch with Outlook Mobile 88


7 Produce Dynamic Presentations with PowerPoint 2010 89


Starting Out with PowerPoint 2010 89


Editing and Formatting Video 91


Creating and Working with Animations 94


Enhancing Your Presentation with Transitions and Themes 95


Adding Sections to Your Presentation . 97


Managing and Sharing Your Presentation 98


Merging Presentations . 98


Broadcasting Your Presentation . 99


Printing Presentation Notes 101


Save Your Presentation as a Video . 102


Work with the PowerPoint 2010 Web App . 103


Using PowerPoint Mobile 2010 103


8 Organize, Store, and Share Ideas with OneNote 2010 . 105


Starting Out with OneNote 2010 . 106


Capturing Notes Easily . 107


Using OneNote as You Work 107


Create Notes Anywhere . 108


Working with Linked Notes and Task Notes . 110


Finding Just the Notes You Need . 112


Sharing Ideas Effectively 113


Creating a Shared Notebook 113


Finding Entries by Author 114


Working with Page Versions . 114


Accessing Your Notes Anywhere 115


9 Collaborate Effectively with SharePoint Workspace 2010 . 117


What Can You Do with SharePoint Workspace 2010? 118


Starting Out with SharePoint Workspace 2010 119


What About Groove? 120


Setting Workspace Preferences 122


Accessing Your Files Seamlessly 123


Simplified Searching . 124


Checking Files In and Out 125


Connecting with Your Team Instantly 126


SharePoint with InfoPath and SharePoint Business Connectivity Services 128


Using SharePoint Workspace on the Go . 128


10 Create Effective Marketing Materials with Publisher 2010 129


Starting Out with Publisher 2010 129


Collapse and Expand Page Navigation Panel 130


Use the Mini Toolbar 131


Creating and Using Templates and Building Blocks 131


Creating Precise Layouts 135


Enhancing Typography with OpenType Features 135


Working with the Improved Color Palette 137


Previewing and Printing Publications 138


Preparing for Commercial Printing 139


Sharing Publisher Files 140


11 Make Sense of Your Data with Access 2010 141


Starting Out with Access 2010 141


Using Application Parts 143


Applying Office Themes 144


Adding New Fields 146


Adding Quick Start Fields 146


Inserting Calculated Fields 148


Showing Data Bars and Conditional Formatting 149


Creating Navigation Forms 150


Designing Access 2010 Macros . 150


Working with Access 2010 and the Web . 151


Adding Web Controls . 152


Using Access 2010 with SharePoint 153


Part III Next Steps with Office 2010


12 Putting It All Together 157


Using Excel 2010 Data with Word 2010 . 157


Sharing SmartArt Among Office 2010 Applications . 159


Dragging Word 2010 Content to PowerPoint 2010 160


Mail Merging Word 2010 Documents in Outlook 2010 . 161


Sharing Access 2010 Data with Other Applications . 162


Scheduling a Meeting from a Shared Document 163


13 Security in Office 2010 165


Understanding Security in Office 2010 . 165


Opening Files Safely 166


Working with Protected View . 168


Password Protecting a File . 169


Limiting File Changes 170


Setting Role-Based Permissions 171


Recovering Unsaved Versions . 172


Working with the Trust Center 173


14 Training Made Easy 177


Getting Help in Office 2010 177


Finding What You Need on Office Online 180


Take Your Learning to the Next Level with Microsoft eLearning 182


Continue Learning with Microsoft Press Books . 183


ix


Acknowledgments


Writing a book is a fun and typically fast-paced process that involves the talents of many

individuals, and some projects involve more team members than others. First Look Microsoft

Office 2010 was a particularly exciting and challenging project because it involved working

with Office 2010 in its various stages of development—which is like writing about a moving

target—and coordinating ongoing feedback from the people on the front lines: Office 2010

product managers, reviewers, and content providers.


Thanks very much to everyone who has helped out along the way. Specifically a big Thanks

to Lynn Finnel, a great project manager and friend; Rosemary Caperton, an excellent project

editor with a green heart; Juliana Aldous, who provided help with hurdles and roadblocks;

Joanna Yuan and her crew (Stephanie Krieger and Beth Melton) who gave feedback and program

assistance; and Steve Sagman of Waypoint Press and editor Roger LeBlanc for the great

copy editing and fine layout of the book you are now viewing. And thanks, always, to my

agent, Claudette Moore, for doing everything she does so naturally and well in making these

projects possible.


xi


Introduction


In this chapter:


n The Road to Office 2010


n Who Uses Office 2010?


n What’s in Office 2010?


n Office 2010 System Requirements


n What You’ll Find in First Look: Microsoft Office 2010


You’ve probably noticed that part of living and working in the world today requires that you

do many things at once. For many of us, managing multiple tasks is our normal work mode.

You prepare a new presentation for a client while you’re working collaboratively with your

team, corresponding with people through e-mail, and inserting Microsoft Office Excel data—

which might be changing moment to moment—into the slides you create.


And if you’re like many people, you’re multitasking when out of the office, too. You check

e-mail while you wait in line for your morning coffee, or you make a quick edit to finalize a

report when you’re waiting for your luggage at the airport, Or perhaps you set up a group

meeting with teammates on three continents and trade documents just moments before it

starts so that you’re all looking at the same plan.


Welcome to Office 2010. Whether you work primarily in the office or on the go, you’ll find

smart tools in this release that enable you to get your work done easier, faster, and more

professionally than ever. All the freedom to multitask built into Office 2010 has an upside you

might not expect: being able to work anywhere, anytime means more flexibility, which translates

to higher efficiency and effectiveness. And when your work is done quickly and well,

you have more time left over for the people, places, and possibilities that intrigue you.


The Road to Office 2010


Did you know that Microsoft Office celebrated its twenty-fifth birthday in 2009? Throughout

the last two and a half decades, Office has grown and improved dramatically—partially

thanks to developments in technology, but primarily thanks to you.


It’s no secret that Microsoft places great importance on customer feedback. Users all over the

world continually provide comments and suggestions through various channels. Microsoft

gathers information through extensive beta programs, market research, the help systems,

and discussion forums. Focus groups galore provide veritable mountains of data for researchers,

program developers, and communications people to sift through. All this feedback


xii Introduction


comes together to provide current, relevant pictures that show which features you want and

need most in the programs you use every day. No matter where you fit on the scale ranging

from new user to power user, the new features in Office 2010 give you the option of becoming

more productive, more collaborative, and more mobile as you work.


We live in interesting times. There’s a major shift occurring in the way technology weaves

through all aspects of our lives. Limitations that seemed all but insurmountable a few years

ago—such as having your team divided among three different continents or needing to

access

your data immediately when you’re away from your desk—are now gone for good.


Office 2010 makes it possible to work virtually anywhere—on the desktop, on the train, in

the carpool line, in the coffee shop—with almost anyone, on any continent. And no longer

are you tied to your desktop PC—now you can work on the go using Web-based and mobile

versions of your favorite Office applications.


The tools you use in Office 2010 on a daily basis are no longer just designed for creating

documents or spreadsheets—although the programs do help you accomplish those common

tasks, and with style. The Office 2010 applications also deliver features you’ve been asking

for—professional formats that are a breeze to apply, easy exchange of data among applications,

and streamlined techniques that enable you to get more out of the time you invest in

the documents and presentations you create.


Worldwide, Office users demonstrate that they want reliable, easy-to-use applications that

enable them to produce professional results, work collaboratively in both local and global

teams, and work anywhere from flexible locations limited only by Web access or phone

reach. These three ideas—express yourself, collaborate, and work anywhere—are the key

visions

behind the changes in Office 2010.


Fast, professional, collaborative, flexible. You’re going to love this new release!


Who Uses Office 2010?


One fascinating result that emerges from Microsoft research is the picture of Office 2010

users.

Think of one of those amazing mosaic portraits, which—when you look closely—you

see is actually made up of thousands of tiny, individual photos. Office 2010 users represent

an amazing, diverse, multitalented global group that uses Office to accomplish just about

every possible productivity task you can imagine. Their needs and interests vary greatly,

and their use of the different Office applications runs the gamut from the very simple to the

incredibly

complex.


Introduction xiii


Note The dramatic redesign of the Office interface, introduced in Office 2007, was due in

part to a desire to help Office users discover a wider range of tools in their favorite programs.

Customer research had shown that most users worked with specific tools in the applications they

were familiar with, but a larger percentage of users weren’t getting the full benefit from the

programs they might have if they had been aware of the wider range of features and possibilities.

Data is showing that the redesign of Office really did reach this goal—Word 2007 and Excel

2007 users are now using four times as many features as they used in previous versions, and for

PowerPoint, the increase in feature use is a factor of five.


Today’s Office 2010 users often move back and forth among applications, depending on the

tasks they’re engaged in at any given time. Here are some typical scenarios:


n Meredith is a customer service representative in a large company. Her job includes

fast-paced communications: she receives and sends e-mail messages to dozens of customers,

prepares and sends proposals, updates Web information, and tracks campaign

results in the customer services database. Occasionally, Meredith gets to lead brainstorming

sessions for new campaigns (she loves that) and compiles the notes for the

team. Printouts of colorful SmartArt diagrams she created in Word and PowerPoint—as

well as her favorite “The Far Side” cartoon—are hanging on her cubicle walls. Her daily

tasks require a whole palette of applications: Outlook, Word, PowerPoint, Publisher,

OneNote, and occasionally, Access.


n Ian is a mid-level manager in the communications department of the same company.

As team leader, he is in charge of planning, budgeting, and managing all reports and

support materials that are developed to support the company’s product line. He uses

Outlook for scheduling and task management, and works with Word, Access, and Excel

for reviewing and working with important data. Ian’s team also prepares company

reports

and public relations materials using Word and Publisher.


n Dominik is marketing coordinator—she is responsible for messaging campaigns,

running

budgets, hiring contractors, working with the board, maintaining a database,

conducting webinars, providing online training, and more. She uses Word, Excel,

PowerPoint, Outlook, Publisher, and Access, and she needs to be available for decisions

and updates continually. Because she manages a department of five, she uses Microsoft

SharePoint 2010 to keep the team organized and working efficiently.


n Kamil is an Office power user who has a long commute to and from his Washington

office each day. He has reduced the impact of his travel time by telecommuting two

days a week, but he also wants to be able to get a start on work—or wrap things up for

the day—when he’s on the train. Whether he’s working from home or he’s in the office,

he uses Outlook, Excel, Word, and SharePoint to run his department, keep the team on

track, host meetings, review and sign off on documents, and make the calls that impact

the bottom line in his department.


n Todd is the IT manager for the business. He is in charge of upgrading, deploying, and

training staff on Office 2010. He also secures and backs up all files, writes custom utilities

for the Web portal, and works in customer and staff support. He is a programmer

and power user of all Office applications, but he has a small staff, so he needs to be

able to offer training and support in a cost-effective and productive way.


Office 2010 includes a range of features that will support the daily activities of each of these

users. The consistent look and feel of the Ribbon helps ensure that users are comfortable and

confident working with any of the Office applications. Changes in each of the applications

make it easier to produce and share professional results in a variety of ways. And not only do

the Office applications work together smoothly as an integrated system, they provide easy

collaboration, anywhere access, and all the productivity tools users need as their work tasks

change and grow.


What’s in Microsoft Office 2010?


Similar to earlier releases, Microsoft Office 2010 is available in several versions, each designed

with a specific group of users in mind, and each accessible via PC, browser, or phone. Here’s

what you’ll find in each version of Microsoft Office 2010:


n Office Professional Plus 2010 is for the high-end user who collaborates with

others,

manages data, and needs flexibility, mobility, and coauthoring capabilities. This

edition includes Word 2010, Excel 2010, PowerPoint 2010, OneNote 2010, Outlook

2010, Publisher 2010, Access 2010, SharePoint Workspace 2010, InfoPath 2010, and

Communicator 2010.


n Office Professional 2010 is designed for the business user who needs all the power

of the traditional applications as well as access to data management tools. This version

includes Word 2010, Excel 2010, PowerPoint 2010, OneNote 2010, Outlook 2010,

Publisher 2010, and Access 2010.


n Office Standard 2010 removes Access 2010 from the mix. It offers users who work

with documents, worksheets, marketing materials, presentations, notebooks, and—of

course—e-mail and schedules just what they need: Word 2010, Excel 2010, PowerPoint

2010, OneNote 2010, Outlook 2010, and Publisher 2010.


n Office Home and Business 2010 streamlines the suite to the basic applications used

by small business and home users: Word 2010, Excel 2010, PowerPoint 2010, OneNote

2010, and Outlook 2010.


n Office Home and Student 2010 is geared toward student and home users, offering

the traditional applications for creating documents, worksheets, presentations, and

workbooks: Word 2010, Excel 2010, PowerPoint 2010, and OneNote 2010.


n Office Professional Academic 2010 is designed for faculty members who

need access to all the core applications—Word 2010, Excel 2010, Outlook 2010,

PowerPoint 2010—as well as OneNote 2010, Access 2010, and Publisher 2010.


n Office Starter 2010 is for the beginning user who wants to work with only

Word 2010 and Excel 2010.


Office 2010 System Requirements


In keeping with green efforts to maximize efficiency on systems users already have, Office

2010 was designed for any system capable of running Office 2007. Here are the suggested

system requirements for Office 2010:


n Computer and processor: 500-MHz processor or higher.


n Memory: 256 MB (megabytes) of RAM or more.


n Hard disk space: 2 GB (gigabytes)*.


n Drive: CD-ROM or DVD drive.


n Display: 1024 by 768 or higher resolution monitor.


n Operating system: Windows XP SP3 (32-bit), Windows Vista SP1 (32-bit or 64-bit),

Windows 7 (32-bit or 64-bit), Windows Server 2003 R2 with SP2 (32-bit or 64-bit),

or Windows Server 2008 with SP1 (32-bit or 64-bit). Terminal Server and Windows on

Windows (WOW) are also supported. **


* Part of the used hard disk space can be released after installation is complete.


** WOW allows users to install 32-bit Office 2010 on 64-bit systems.


What You’ll Find in First Look: Microsoft Office 2010


I hope First Look: Microsoft Office 2010 inspires you and gives you a good sense of the

exciting

features coming in the release of Office 2010. This book was written while the

software was in development, so you may find some variance in screen illustrations and

procedures, but the overall story is the same: The key to the new features is freedom and

flexibility—you’ll be able to see how to get more from your applications no matter how—or

where—you choose to use them. Office 2010 is designed to help you express your ideas


clearly and creatively, work seamlessly with a group to get things done efficiently and on

time, and access and work with your files virtually anywhere with a similar look and feel

whether you’re using your PC, browser, or phone. To showcase these key points, First Look:

Microsoft Office 2010 follows this organization:


n Part I, “Envision the Possibilities,” introduces you to the changes in Office 2010 and

shows you how you can make the most of the new features to fit the way you work

today. Chapter 1, “Welcome to Office 2010,” gives you a play-by-play introduction to

new features; Chapter 2, “Express Yourself Effectively and Efficiently,” details the great

feature enhancements and visual effects throughout the applications; and Chapter 3,

“Work Anywhere with Office 2010,” explores the flexibility factor by presenting a set

of scenarios that enable users to complete their work no matter where their path takes

them.


n Part II, “Hit the Ground Running,” focuses on each of the Office 2010 applications in

turn, spotlighting the key new features and showing how they relate to the whole.

These chapters provide a how-to guide for many of the top features you’re likely to

use right off the bat, and they offer inspiring ideas on how to get the most from your

favorite

applications.


n Part III, “Next Steps with Office 2010,” zooms up to the big picture and provides

examples

to help you think through interoperability. How often do you use the various

Office applications together? Customer research shows that people often don’t

realize how well the applications work together as a complete system—which means

they might be laboring over items they could easily incorporate from somewhere else.

This part of the book provides examples for integrating the applications and explores

Office 2010 security and training opportunities, as well.


So if you’re ready, let’s take a closer look at the ways Office 2010 can help you express

your ideas, whether you work on your own or as a part of a team, and share your work

with the world.


First Look: Microsoft Office 2010


1


Part I


Envision the Possibilities


Office 2010 ushers in a new era in productivity software by making the reliable tools

you’ve come to expect from Microsoft easier to use and more powerful than ever. In this

part of the book, you’ll get the big picture view of how Office 2010 improves the way you

work every day.


This part of First Look: Microsoft Office 2010 includes the following chapters:


n Chapter 1: Welcome to Office 2010


n Chapter 2: Express Yourself Effectively and Efficiently


n Chapter 3: Collaborate in the Office and Around the World


3


Chapter 1


Welcome to Office 2010


In this chapter:


n Features that Fit Your Work Style


n Changes in Office 2010


n Exploring the Ribbon


n New Backstage View


n Languages and Accessibility


n Coming Next


This is an exciting time to be working with technology. Changes are occurring with what feels

like ever-increasing speed. The world is growing continually smaller, and far-away places are

more and more within our reach. Today our coworkers are almost as likely to be working on

a different continent as they are to be down the hall. Opportunities are possible now that we

couldn’t envision a few years back—more of us are telecommuting, training by webinar, and

planning projects virtually, all of which is accomplished through Web and phone access to

the tools that make it all possible.


Office 2010 was designed with evolving workplace trends in mind. With Office 2010, you

can use familiar, reliable Office applications to work more efficiently, produce better-thanever

results, collaborate in real time with peers in your office or around the world, and continue

your work from any point on the globe with Web or phone access. And even though

these are big changes, they fit easily into what you’re already doing. The tools you need to

implement

these changes in your work efforts don’t have a steep learning curve. By adding

to the functionality of your favorite features (Print, Paste, and Picture Effects, to name a

few examples), Office 2010 helps you get more done with less effort. And the collaboration

and anywhere access features make working with anyone, anytime, a natural and intuitive

process.


Features that Fit Your Work Style


For many of us, our long workdays of focusing on single projects have evolved into days with

smaller blocks of time dedicated to one of many things we have going on. We are getting

more done than ever—and Office 2010 can help you better enjoy the process.


4 Part I Envision the Possibilities


What’s exciting about Office 2010 is that it’s more than a set of powerful tools that help you

meet and manage the demands of your fast-paced workday. For example, if you do most of

your work at your desk, crunching numbers, answering e-mail, and preparing reports, Office

2010 helps you work faster, manage huge worksheets, design effective documents easily, and

present your work in new, visual, and flexible ways that help your diverse audience understand

your ideas.


If you work primarily in a team, you’ll find that Office 2010 makes collaboration easy with

features that enable you to share files, co-author documents, and even contact teammates in

real time.


If you work predominantly on the road—and frequently need to get updates on projects,

add items to the calendar, or approve new documents and strategies—Office 2010 gives you

the flexibility to use the Office applications you know and love regardless of whether you’re

logging in from your PC, your browser, or your phone.


In Part II, “Hit the Ground Running,” you get a closer look at the new features in each of your

favorite Office 2010 applications.


Office 2010 at a Glance


With Office 2010, you can


n Increase your productivity with more effective, reliable tools


n Express your ideas creatively and effectively, for multiple audiences


n Produce and share professional results easier and faster


n Communicate—and manage communications—easily whether you work

independently,

collaboratively, or remotely


n Gain more freedom and flexibility to work anywhere, with anyone


n Enjoy the consistent and high-quality Office experience from your PC,

browser,

or phone


Changes in Office 2010


This section presents a look at the key ideas behind the development of the features you will

find in Office 2010. Working independently or in a group, at your PC or on the road, you’ll

find new tools and techniques that help you create great-looking documents, worksheets,

presentations, and more, and enable you to share your work easily with others.


Chapter 1 Welcome to Office 2010 5


Tip One significant change that has a large impact on processing speed and power is that

Office 2010 is now available in a 64-bit version. This expanded capacity really shines in Excel,

where enormous spreadsheets require that kind of processing power.


Let Your Ideas Soar


Office 2010 shows that powerful programs don’t have to be difficult to use. Program designers

know that users today need a great variety of powerful, flexible tools, and that it’s important

that those tools and features be easy to find and use. For this reason, you’ll find quick

access to style galleries, themes, and more that help you select professional designs, choose

from color schemes that work, and create a professional look whether you’re creating documents,

worksheets, presentations, notebooks, or database tables.


To help you take your ideas to the next level, Office 2010 offers artistic effects and picture

editing, video editing in PowerPoint, new data visualizations (including sparklines and slicers)

in Excel, and the ability to manipulate fonts professionally in Word. And this is just the beginning—

there’s much more, as you’ll see in the chapters in Part II, “Hit the Ground Running.”


And not only will your output be better, but the whole document creation process is easier,

thanks to enhanced search features, simplified navigation, the contextual spell checker,

translation

tools, and more.


Collaborate Easily and Naturally


Unless you’ve been living off the grid for the last couple of years, you’ve probably noticed

that the world has gotten substantially smaller, thanks to the continuing expansion of Web

technologies. Blogs, social media, and new online publishing alternatives have steeped most

of us in a culture that is always on, always connected, and always talking.


An increasing number of people are now working in teams, and those teams might be spread

throughout the office or located around the world. A writer in Omaha could be working with

a software developer in India who might have been hired by an administrator in Scotland.

This geographical diversity within a project team is no longer an unusual occurrence—an

increasing number of Office 2010 users need to collaborate with peers and clients all over the

globe.


Office 2010 includes powerful tools to facilitate easy and successful team collaboration

and management. Co-authoring features in Word 2010, Excel 2010, PowerPoint 2010,

and OneNote 2010 enable you to work with a variety of teammates on a single project in

real time. And, when you use these features, your changes are automatically tracked and

coordinated.


Microsoft SharePoint Workspace 2010, included with Microsoft Office Professional Plus,

enables

users to move files online and offline easily. Team leaders and members use

SharePoint Workspace to create and update the team calendar, conduct project management,

assign tasks, create document libraries, and more. Team members can collaborate in

real time, and their documents show who is working on what so that duplication of effort

or trading outdated versions of files is no longer a problem when several users work on the

same document.


Presence information is available with Office Communicator throughout Office 2010,

enabling

you to see which of your teammates are online and communicate instantly—via

instant messaging, e-mail, or phone—to clarify questions on the project. You don’t have to

leave the application you are working in to ask questions you need answered right away.


Work Anywhere—and Everywhere


Laptop, notebook, desktop, kiosk—any place that gives you an on-ramp to the Internet is

a potential workplace in Office 2010. Office 2010 Web Apps let you work with the familiar

Office 2010 interface and work with your Word 2010, Excel 2010, PowerPoint 2010, and

OneNote 2010 files. You can share files with other users by using Windows Live or SharePoint

Workspace 2010 and then open and work with the files on your PC when you get back to the

office.


If you are a gadget lover, you might already have a smartphone with all the bells and whistles

you can get. Office Mobile 2010 gives you another way to work on the go, using your

Windows Mobile smartphone. You can write up an idea before breakfast, create a new document,

and share it with the team—all before you get into work in the morning. Later, on the

way to meet a vendor, you can add a few more details, insert a picture, and send the file for

review—all from your phone.


Office Mobile works with Word, Excel, Outlook, PowerPoint, and SharePoint Workspace. The

application windows have been customized to fit the small phone screen and browser so that

you can find what you need easily and enjoy the familiarity of the Office 2010 interface.


This flexibility in Office 2010 gives you the freedom to follow through on your creative ideas

in real time—whenever and wherever they occur.


Exploring the Ribbon


At the top of the interface in all Office 2010 applications, the Ribbon brings you all the tools

you need—and only the tools you need—to complete specific tasks in the various Office

2010 applications. The Ribbon includes tabs that reflect the various tasks you perform within

each of the applications, and each tab contains tool groups offering the tools you need as

you work with the files you create, Every application has the same look and feel, which enables

you to learn the Ribbon once in your favorite or most often used Office program and

then easily find your way around any other Office program. The Ribbon was introduced in

Office 2007 and has been improved in Office 2010 to include some new tools and provide

more flexibility. You can use the Minimize The Ribbon button to hide the Ribbon so that you

have more room to work on-screen, and you can customize the Ribbon to create your own

tabs and tool groups specific to your needs.


The simple design of the Ribbon enables you to find the tools you need in the tab that reflects

the task you want to perform. When you want to add a picture to your annual report,

for example, you look in the Insert tab and find Picture in the Illustrations group. Figure 1-1

introduces you to the Ribbon in Word 2010 and Excel 2010.


Quick Access toolbar Tabs Groups

Microsoft Office Button

Dialog box launcher


FIGURE 1-1 Exploring the Office 2010 Ribbon.


A Quick Look at the Ribbon


The Ribbon simplifies the way you find and work with tools and options in Office. With a

simple, easy-to-understand layout for your commands, the Ribbon helps you find the tools

you need:


n Ribbon Tabs Each tab provides a set of tools related to an overall task you are likely

to be performing in a specific application. In Figure 1-1, the Word 2010 tabs are File,

Home, Insert, Page Layout, References, Mailings, Review, and View; the Excel tabs are

File, Insert, Page Layout, Formulas, Data, Review, and View. The File tab takes you to

Microsoft Office Backstage view, which gives you a central place to work with the files

you create in Office 2010 applications.


n Ribbon Groups Within each tab are groups that help organize common commands to

help you quickly find what you need for a specific task. For example, on the Insert tab

in Word 2010, you’ll find Picture, Clip Art, Shapes, SmartArt, Chart, and Screenshot in

the Illustrations group.


n Galleries A down-arrow appears to the right of some options in groups. Clicking the

down-arrow display a gallery of options you can select or a list of additional choices.

(See Figure 1-2.)


FIGURE 1-2 Galleries display visual examples of options.


Contextual Tabs


In addition to the tabs, groups, and tools shown in the Ribbon during normal use, contextual

tabs appear when you perform specific actions in a file. The fact that they appear only when

you need them is part of the beauty of the Office 2010 interface—this keeps the number

of commands on-screen at any one time at a minimum and easy to navigate through. For

example, when you click a photo in a Word document, the Picture Tools contextual tab appears,

providing options related to picture editing. (See Figure 1-3.)


FIGURE 1-3 The contextual tab provides options related to the task you are performing.


New Backstage View


One of the major improvements in Office 2010 is Microsoft Office Backstage view, a kind of

one-stop shop for all tasks related to managing the files you create in Office 2010 applications.

The round and colorful Microsoft Office Button in Office 2007 has been replaced by

the File tab. When you click it, you are taken to a screen outside the document where you

can manage file information and save, share, print, protect, and work with version information

for the document. (See Figure 1-4.)


FIGURE 1-4 Backstage view helps you prepare, manage, and share the files you create.


Backstage view is organized in three panels. The left panel includes the commands you’ll use

to work with the files you create. The center panel offers related options, and the third panel

displays a preview image of the selection or additional options. For example, when you click

Print, the center panel shows print options, and the right panel displays a preview of your

document as it will appear in print. This streamlines the print process so that you can preview

and print your document in one step.


Managing Files in Backstage View


In Backstage view, you’ll find the commands you traditionally found on the File menu: New,

Open, Recent, Close, Save, Save As, Print, and Exit. In addition to each of these basic filemanagement

commands, you’ll find Share, which enables you to share the file in a variety of

ways. You can share your desktop directly from Backstage view by using Communicator integration,

sending the file by e-mail or fax, or saving it to a SharePoint Workspace or to a blog.


Tip Another great option Backstage view offers is that you can customize it to include your own

workflows and procedures.


Backstage view is designed to give you access to important tools users sometimes forget to

use. For example, you can run the Document Inspector by clicking Check For Issues in the

Info panel of the Backstage view and clicking Inspect Document.


Streamlined Printing


Another great time-saving feature in Backstage view is the new Print process. Microsoft research

shows that more than 60 percent of Office users print more than 60 times per month.

That’s a lot of time clicking Print options! Now in Office 2010, Print Preview has been combined

with Print so that instead of working through multiple dialog boxes, you get a onepage

view of how the file will look in print. (See Figure 1-5.) You can choose your options

right on the screen and click Print—and you’re done.


FIGURE 1-5 Now you can preview and print in one smooth process.


Languages and Accessibility


In keeping up with the reach of the global workforce, Microsoft Office 2010 has more robust

language tools than ever, including a choice of translation tools. According to Microsoft research

data, more than 1.6 million words have been translated using the Microsoft Language

tools—plus more than 6.2 million words online—into more than 100 languages. Office


Online, which provides all kinds of content for Office users—including tips and tricks, how-to

articles, and video tutorials—provides content in more than 90 languages.


You’ll find the Translate tool, which enables you to translate words or phrases, in the Review

tab of Word 2010, Excel 2010, PowerPoint 2010, and OneNote 2010. Or you can use the Mini-

Translator tool for on-the-spot translations. (See Figure 1-6.) The Editing Language feature

enables you to choose the language used by the dictionary for the proofing tools you select.


FIGURE 1-6 Translate words or phrases on the fly, and choose the language dictionary you want to use.


In terms of extending the reach of applications for users who are differently abled, Microsoft

works with more than 175 partners to create assistive software that enables Office to provide

screen readers, high-visibility color schemes, and special keyboards.


Coming Next


This chapter painted the big picture of Office 2010 changes, introducing you to the overall

design goals in this release. It also summarized changes to the Ribbon, introduced you to

Backstage view, and discussed enhancements to print and language functions. The next

chapter takes a closer look at the Office 2010 features that will help you express your ideas in

a lively and effective way—through words, images, numbers, and more.


13


Chapter 2


Express Yourself Effectively

and Efficiently


In this chapter:


n Understanding Your Audience


n How Visuals Help


n Adding Text Effects


n Adding Artistry to Your Images


n Working Font Magic in Word 2010 and Publisher 2010


n Creating Data Visualizations in Excel 2010


n Editing Video in PowerPoint 2010


n Communicating Visually in Access 2010


n Enhancing and Streamlining Communications in Outlook 2010


n Coming Next


People use Microsoft Office to do many, many things. Depending on the nature of your

work, you might create documents, design worksheets, prepare reports, develop and

manage

databases, create and give presentations, e-mail clients and coworkers, gather

information,

analyze information, and share information. And that’s just Monday!


Chances are that many tasks you do in Office 2010 involve communicating ideas to others.

Those others might be peers, clients, board members, prospective customers, students,

and more. You need to be able to create, prepare, and share worksheets, charts, reports,

databases,

Web pages, e-mail messages, and brochures that other people can view and

understand. And of course, once they understand what you’re sharing, you want them to

give you the response you’re hoping for—whether that’s a new contract, an important sale,

startup funding, or accolades for a job well done.


Office 2010 includes a variety of new features and tools that can help you communicate your

ideas clearly, visually, and in ways your readers will understand. Framing both what you want

to show and tell is important and can help you make sure your points hit their mark. This

chapter gives you a tour through the various new features that will help you showcase your


14 Part I Envision the Possibilities


thoughts more creatively than ever, bringing more visual energy to the items you produce.

Specifically, this chapter introduces you to features that help you do the following:


n Improve the formatting of your Word 2010 text by adding special artistic effects such

as shadows, reflections, glows, and more.


n Take advantage of the professional typography capabilities available in many OpenType

fonts, such as ligatures and stylistic sets. Edit pictures within your document, worksheet,

brochure, or presentation by using the image-editing features in the various Office

2010 applications.


n Edit videos within PowerPoint 2010, customizing the length, formatting, and effects to

meet your needs.


n Create data visualizations that help your customers grasp the trends in your Excel 2010

data.


Understanding Your Audience


Beginning with the end in mind is a good approach for just about any document, worksheet,

presentation, notebook, and database you create in Office 2010. When you first begin a new

file, consider your answer to the following questions:


n Who will be reading or using this file?


n What will they expect to see?


n Do you have photos that support the points you’re making in the document or

worksheet?


n Will you use special text effects to call attention to key points, headlines, or labels in

Word 2010?


n Will charts, diagrams, or screen shots help your audience understand what you want

them to do?


n How can you help your audience understand the ideas you’re putting in front of

them—and what do you hope they’ll do as a result? Do you want them to fill out a

form, subscribe to your magazine, purchase your product, or understand how much

your department has accomplished this year? Knowing what kind of response you want

from your communication—before you even begin—will help create the framework of

the whole process for you. And the visual elements you add along the way will be more

likely to take you closer to that goal.


Chapter 2 Express Yourself Effectively and Efficiently 15


How Visuals Help


Not too long ago, most business reports weren’t very exciting. They might have had a cover

page, a column or two, and maybe a page border. The title might have been in a larger font

(Times Roman, most likely), and the body text was probably your basic 10-point or 12-point

standard font. But it was just business communication, right? Better to focus on the facts and

leave the fancy stuff to the marketing brochures.


The affordability of color laser printers and the ability to design attention-getting materials

on the desktop have changed all that. Today we recognize that no matter what we produce,

our materials are competing for readers’ attention. And research shows us that documents,

presentations, notebooks, and worksheets that are clear, easy to read, and include visual cues

that help lead our eyes to the most important points capture our attention and reinforce key

concepts in the document or presentation.


By adding special artistic effects to text; formatting headlines, captions, and tables in an inviting

way; and thinking through the way you use pictures, charts, diagrams, and more, you

can dramatically increase the power of your message and make sure your readers get the

point.


Benefits of Pictures in Communications


The images you add to your documents, worksheets, presentations, notebooks, and

e-mail messages serve several purposes. They not only add visual interest and give your

readers’ eyes a rest, they are also known to provide the following real communication

benefits:


n Pictures linked to written text increase attention and help recall.


n Pictures help improve your readers’ comprehension.


n Readers’ emotional response to pictures can help or hinder communication.


n Readers with lower literacy skills show improved comprehension when

pictures

are used in documents.


n Captions help readers make the connection between pictures and text.


n Pictures showing outcomes, actions, or processes can help readers know what

to do after reading a document.


Adding Text Effects


What are your favorite formatting features in the different Office 2010 applications? Most

people use boldface text to make sure headings, row and column labels, and table headings

stand out. You might also use the styles in Word or Excel to apply the look you want to the

different elements in your file, make changes to font size or color, and occasionally use more

specialized text controls such as small caps and strikethrough.


Word 2010 includes a number of easy-to-apply text effects that help you add special artistic

touches to the text in your documents. Now in addition to using 3-D effects, you can add

glows, bevels, shadows, reflections, and outlines. (See Figure 2-1.) These text effects apply

directly

to your text and can be included in styles you create. And they act like traditional

text when you check spelling or edit your document.


Tip Did you know Paste is one of the most frequently used tools in all of Office 2010? You

now have more control when you copy and paste items in your files; the Paste Options gallery

enables you to preview the changes before you paste. Chapter 4, “Create and Share Compelling

Documents with Word 2010,” includes details on using Paste with Live Preview.


FIGURE 2-1 New text effects enable you to add artistic touches to your text.


Adding Artistry to Your Images


Great photos can be more than just nice-looking images when you apply special artistic

effects

to the pictures you use in your files. Now Office 2010—specifically, Word 2010, Excel

2010, Outlook 2010, and PowerPoint 2010—includes a palette of artistic filters you can apply

to images in your documents. (See Figure 2-2.)


FIGURE 2-2 Choosing artistic effects.


You can choose from a variety of effects that apply different filters to the selected image,

including chalk, watercolor, sponge, rain, and more. You can also use the new Remove

Background feature to remove an image from the foreground and place it on a different

background. This feature is great for product catalogs, or for any image in which you need

to spotlight a particular element without showing a background that might detract from the

central element you hope will catch the reader’s eye.


Figure 2-3 shows an image with various artistic effects applied. As you can see, each image

conveys a different feeling, which means it’s communicating a different idea with each effect.


FIGURE 2-3 With artistic effects, one photo can be used to communicate several different ideas.


When will you use artistic effects in the files you create? Here are just a few ideas:


n Use an artistic photo or treatment of your company logo to show that this year’s annual

report demonstrates innovation and creativity.


n Create an effect viewers will remember by choosing not to show a product or place in a

realistic way.


n Capture your readers’ attention and communicate something new by modifying an

existing

photo they will recognize.


Correcting and Recoloring Pictures


Of course, not all images you take on your digital camera or phone are ready to use just as

you’ve captured them. The lighting might be wrong in that product photo; the person might

be just slightly out of focus; the range of contrast in the picture of the new building might be

too great to show up well in print.


Although the Picture tools in Office 2007 went a long way toward giving you control over

the images you add to your files, they were limited in the range of changes they allowed.

You could adjust the picture by changing the contrast and brightness, recoloring the image,

applying styles and effects, or arranging the picture on the page. The Corrections tools in

Office 2010 give you a customizable palette of choices for brightness and contrast, and they

allow you to set your own standards for sharpening or softening images. This means you

can now insert and edit photos as you work in Word 2010, Excel 2010, PowerPoint 2010, and

Outlook 2010 without ever leaving the application.


Cropping also has received a makeover in Office 2010. Now when you choose the Crop tool,

the entire image is displayed in shadow behind your crop marks; you can then use the cropping

tool to zoom in on the part of the image you want by resizing the image, panning to

the area you want to capture, and cropping out the rest. The display makes it easy for you to

select only the part of the photo that you want people to see.


Leaving the Background Behind


One of the great new artistic tools in Office 2010 is Remove Background, which lets you

pull the object of a photo from its background. This is a great technique when you’re

preparing product information, introducing a new employee, or creating materials to

spotlight a key element you don’t want your readers to miss.


To grab an image in the foreground and remove it from the background of your

photo,

use the new Background Removal tool on the Picture Tools tab of Word 2010,

Excel 2010, PowerPoint 2010, and Outlook 2010. Here’s how:


1. Select the photo, click the Picture Tools Format tab, and click Background

Removal.


2. Drag the bounding box to include the areas of the image you want to display.

The magenta areas are those that will be removed.


3. Use the Remove Background tool in the upper left area of the Ribbon to mark

areas of the image you want to keep or remove.


4. Click Close Background Removal to complete the task.


Pretty neat, eh? Experiment with this feature to discover ways you can point your

readers’

attention to just what you want them to see in your images.


The new Color tools also have had a major overhaul: now you can choose from a wide

range of color management tools and make choices for saturation, tone, and an expanded

selection of color wash effects. (See Figure 2-4.)


FIGURE 2-4 The Color tools in Office 2010 allow more choices for saturation, tone, and recoloring.


Color Effects Defined


If you’re new to the whole landscape of picture editing, you might be wondering what

the new features in the Color tools of Office 2010 enable you to do. Here’s a quick introduction

to the phrases and what they mean:


n Color saturation controls the amount of color used in the picture—in other

words, how saturated the image is with the colors represented. A picture

with a Saturation of 0 percent is a black-and-white image; a picture with

a Saturation of 400 percent is flooded with color. (Use this option only for

special

effects.)


n Color tone enables you to choose the overall temperature for the image. The

underlying tone for the image ranges on a scale from “cool” blues (4700 K) to

“hot” oranges (11,200 K). Experiment with an image to test the range of tones,

and choose the look that best fits the overall design of your file.


n Recoloring applies a color filter to the image, making it monochrome (in blue,

red, green, or purple, for example) and creating a special artistic look that can

fit the color scheme in the file you’re preparing.


Working Font Magic in Word 2010 and Publisher 2010


Another new feature in Office 2010 that adds a touch of visual sophistication to the files you

create is support for OpenType typography. OpenType fonts are a type of scalable font developed

by Microsoft and Adobe to provide an expressive font format that enables software

users to create files reflecting an increasingly diverse range of languages. Word 2010 and

Publisher 2010 now support the typography features found in some OpenType fonts, such as

working with ligatures and stylistic sets. Word 2010 and Publisher 2010 also include support

for Number Forms and Spacing. (The feature is called Number Styles in Publisher.)


A ligature is a character in typography that consists of two or more connecting letters; for

example, the letters fi are often set as a ligature. Ligatures were originally invented (back in

the dark ages when typesetters cast type in lead before inking them and printing pages) to

save space and reduce typesetting effort.


A stylistic set is a font displayed with a specific set of characteristics, enabling you to get

a subtly different look and feel for selected text even though you’re using the same font

throughout a document. Gabriola, a new font in Office 2010, offers a variety of stylistic

sets you can try in your documents. Different stylistic sets might give you a whole range

of choices

for that particular font, including whether you want to display serifs or not, how

characters

with extenders are displayed, and much more.


To see your typography choices in Word 2010, click the dialog launcher in the Font group on

the Home tab, and then click the Advanced tab. The Ligatures setting enables you to choose

how you want the ligatures to be applied when they are available, and the Stylistic Sets

choice offers a list of available sets you can select for the current font. Figure 2-5 shows several

different stylistic sets selected for a headline in the Gabriola font. Take a close look at the

length and shape of the extenders on the letters h, k, and p as well as the spacing between

the characters to see the difference.


FIGURE 2-5 Fine-tuning fonts in Word 2010.


Ligatures and stylistic sets work similarly in Publisher 2010. Here you can choose the

typographical

controls from the Typography group in the Text Box Tools Format contextual

tab. (See Figure 2-6.)


FIGURE 2-6 Choosing a stylistic set in Publisher 2010.


Tip Publisher 2010 also includes a number of specialized font options, including stylistic alternatives,

and specialized number styles. You’ll learn more about the steps involved in working with

fonts in Publisher 2010 in Chapter 10, “Create Effective Marketing Materials with Publisher 2010.”


Creating Data Visualizations in Excel 2010


If you work with numbers all day long, you’re probably comfortable with a language many

other people struggle to understand. Equations and trend lines make perfect sense to you;

business intelligence is part of your language; numbers tell you what you need to know

about product status, market saturation, and potential return on investment. You build your

documents and presentations around these numbers.


But wait a minute! Could you please translate that for the rest of us?


Excel 2010 now includes simple but effective tools that will enable even the most advanced

numbers people to show the rest of us what the numbers mean in a language we can understand.

Take sparklines, for example. Newly added sparklines are small graphical representations

of data on your worksheets—small charts that can depict a trend and visually convey to

your audience what the values actually mean. Sparklines can show, for example, an increase

in enrollment for new webinars, a spike in sales related to a recent event, or a fall-off in hard

goods purchasing.


When you use sparklines to illustrate the data in your worksheet, you help those for whom

numbers might be a foreign language stop struggling with what it all means and enable

them to clearly understand your point. Figure 2-7 shows simple sparklines added to a column

on a worksheet to illustrate the data trend reflected in the displayed row.


The conditional formatting features in Excel 2010 have been improved and expanded with

new icon sets, data bars that are capable of showing negative values, and proportional displays

in data bar sets. You can also control the formatting of data bars to get just the right

effect in the worksheets and documents you prepare.


Tip For more detail on using sparklines and making conditional formatting improvements to

your Excel worksheet, see Chapter 5, “Create Smart Data Insights with Excel 2010.”


FIGURE 2-7 Sparklines give you data snapshots in Excel 2010.


Editing Video in PowerPoint 2010


It’s no secret that seeing how something is done in video format is a simple way to learn a

new technique, whether you’re changing the oil in your car, learning how to plant a rosebush,

or designing a new brochure in Publisher 2010. A video clip enables you to share with others

the “how to” as well as the “why” because you can explain the reasons for the action while

you’re demonstrating the technique for those viewing the clip.


Are you ready to let your creativity out of the box? Take a look at the new video capabilities

in PowerPoint 2010. Now the video from your files is embedded by default, which means that

you no longer have to carry all your media files along whenever you copy, move, or share a

presentation. Because the video is embedded, you can edit the video directly in PowerPoint

without using any other video-editing software.


The video-editing features in PowerPoint 2010 enable you to shorten long video segments,

apply fade-in and fade-out settings, add bookmarks to help you quickly access important

points in the video or even trigger animation from key points in your video. Figure 2-8 shows

you several of the available video-editing capabilities in PowerPoint 2010.


Tip If you have online video you’d like to use in your PowerPoint 2010 presentation, you can easily

embed the code from the online video site right in your PowerPoint slide. To find out more about

how to do this, see Chapter 7, “Produce Dynamic Presentations with PowerPoint 2010.”


FIGURE 2-8 PowerPoint 2010 includes powerful video-editing and formatting tools that enable you to modify

video without leaving the program.


Communicating Visually in Access 2010


Maybe it’s all about the data for you. You design elegant databases; you create new data

tables

and forms. You know how to put together such a sophisticated query that it leaves

others in awe. When you need to communicate your ideas to others who aren’t as comfortable

with data as you are, chances are that you know what happens when other peoples’

eyes glaze over. They are no longer listening, which means they aren’t following what you’re

saying. How can you make sure they understand what your data is saying in a way that

makes sense? Access 2010 data visualizations can help.


Conditional formatting in Access 2010 now supports data bars, which enable you to depict

data visually so that your audience can understand your ideas. See Figure 2-9. In addition

to the traditional data bars, now you can set negative values for data bar display as well.

Improved tools in Access 2010 enable you to apply a greater range of conditional formatting

to the tables and reports you create. Here are other ways you can add visual elements to

Access 2010:


n Include data bars, icons for minimum and maximum values, and more.


n Display an image on the background of your reports by using the Background Image

feature in the Report Design Tools Format tab.


FIGURE 2-9 Access 2010 lets you add data bars that help you compare data values at a glance.


Enhancing and Streamlining Communications in

Outlook 2010


One of the big changes you’ll notice right away in Outlook 2010 is that the Ribbon replaces

the menu and toolbars at the top of the main Outlook window. (See Figure 2-10.) Now all the

tools you need—including the new Quick Steps—are within easy reach and you can find the

right commands when you need them.


All the formatting capabilities—SmartArt graphics, styles, and Office themes—are available

for the e-mail messages you create. This means that even though the messages you create

compete for attention with the hundreds of messages your recipients receive, you can take

steps to make sure your messages are as compelling and inviting as possible.


Depending on the nature of the work you do, the feature that enables you to include screen

shots in the messages you send can be a big help. (See Figure 2-11.) If you help customers

find products online, support your staff through technical training, or assist users as they try


to find specific items on your Web site, including a screen shot can show readers what you’re

talking about and help them understand an important process.


Tip Setting up Outlook 2010 to send items to your mobile phone is as simple as clicking the File

tab to display Backstage view, choosing Options, and clicking Mobile. If you have an SMS Service

Provider, you can send calendar items, reminders, and messages to your mobile phone by simply

choosing the options you want to set and clicking OK. If you don’t yet have an SMS Service

Provider, you can find one on Office.com.


FIGURE 2-10 The main window of Outlook 2010 now sports the Ribbon, offering the tools you need within

easy reach.


Not only can you make your e-mail messages look more attractive and inviting for those

you contact, but Outlook 2010 gives you a number of ways to keep up with the mountain of

messages you receive every day. Here are a few of the key features that help you manage the

volume of mail you receive:


n Work faster with Quick Steps. The addition of Quick Steps enables you to carry out

routine

tasks with a quick click of the mouse. Now you can move a message to a

specific

folder, reply to a meeting, or send a message to your team with one little click.

Simple.


n Conversation View enables you to view the most relevant threads of a conversation

and suppress redundant threads. Having the ability to remove redundant messages in

the conversation saves Inbox space and helps you manage the volume of e-mail you

receive.


n Easily manage and clean up threads and move on to more pressing tasks without

getting

bogged down in messages that don’t relate to the task at hand.


n Easily manage your multiple e-mail accounts, whether you want to combine home and

work or any one of a number of Web-based e-mail accounts. Now you can bring them

all together in one place with Outlook 2010.


FIGURE 2-11 With Outlook 2010, you can easily add and enhance pictures, screen shots, and more.


Coming Next


In this chapter, you learned about the range of features in Office 2010 that enable you to add

visual effects and enhancements to the ideas you share with others. You explored new and

improved features in Word 2010, Excel 2010, PowerPoint 2010, Outlook 2010, Access 2010,

and Publisher 2010. The next chapter gives you this same kind of big-picture view of the

collaboration

features you’ll use as you work with teams in your office or around the world.


29


Chapter 3


Collaborate in the Office and

Around the World


In this chapter:


n It’s All About the Teamwork


n Benefits of Office 2010 Collaboration


n Stay in Touch with Your Team


n Co-Author Files Across Applications


n Use the Presence Icon to See Author Availability


n Using the Office Web Apps


n Sharing on the Road with Office Mobile


Depending on the type of work you do, you might work on your own most of the time,

or you might work as part of a larger group—or perhaps, several groups. Your groups might

come together to complete a specific project—for example, to produce a new marketing

plan—or they might work together over the long term, completing multiple projects.

Whether your need for collaboration is short term or ongoing, you’ll find features in

Office 2010 that enable you to


n Work with others simultaneously on the same file.


n Connect instantly with others working on your document or presentation.


n Know when others are actively working in the document you are viewing.


n Collaborate in real time with others working from their PCs, browsers, or phones.


It’s All About the Teamwork


As the world grows smaller and more accessible, our teams expand and grow. Today it isn’t

unusual to have someone from another continent on your team—whether the home office

for your company is in the U.S., the U.K., India, or another Web-enabled place on the globe.

In a team context, we plan projects, assign tasks, share documents, work collaboratively on

files, resolve problems, and ultimately produce materials that further the missions of our

companies, reach customers, and accomplish the tasks we’re asked to complete.


30 Part I Envision the Possibilities


What Teams Look Like Today


So how many of us are working in groups today? The exhaustive research data Microsoft

compiled shows that 52 percent of those surveyed currently work on two or more projectbased

teams. Others responded that most of their work is done independently, but they

collaborate

with others occasionally.


How do teams work collaboratively?


n Surprisingly, many workers collaborate by e-mail, sending versions of documents back

and forth. This isn’t the most accurate or most secure method of working collaboratively

because file versions can be misplaced and a sensitive file might be vulnerable to

interception unless it’s encrypted or sent only on the company intranet.


n Others collaborate via instant messaging (IM), discussing projects, making decisions,

and planning next steps.


n Still others use social networking tools to discuss items in a group, set up an event, and

more.


n Some businesses encourage the use of an employee portal or provide collaboration

software to facilitate teamwork.


n Other ways to collaborate include face-to-face meetings (of course) as well as shared

blogs, wikis, SharePoint sites, and more.


Office 2010 makes collaborating a natural and intuitive process by bringing collaboration

tools into all the major applications. You can share your team document on SharePoint, share

OneNote notebooks, create Word and PowerPoint projects, and ask fellow authors questions

while you work.


Team Tasks and Methods


In most workplace environments, teams are made up of people who are brought together by

role, not by choice. This means you might be part of a group that is an interesting mix of personalities

and talents. No matter how similar or how different team members might be, your

team will need to accomplish two primary goals to be productive and deliver what you came

together to create:


n You need to be able to communicate effectively.


n You need to find a way to solve problems.


Chapter 3 Collaborate in the Office and Around the World 31


The content of each team’s tasks might vary widely. One team might be organized to assess

the need for a human resources program; another team might come together to produce an

annual report. Still another team might be charged with planning, hosting, and evaluating a

national event.


Whatever the focus your work has or whatever the objective is you’re working toward, you

need to be able to share information, connect with others, and coordinate your efforts.

Along the way, each and every team needs to discover how to work together most effectively

to get the job done.


A Quick Look at Group Process


American psychologist Bruce Tuckman studied group dynamics, and in 1965, he

proposed

that every group goes through four stages:


n Forming is the stage in which the group comes together. During this stage,

the members get to know one another and begin the process of communicating.

Some members might be polite and others might be anxious, but basically

everyone is on his or her best behavior.


n Storming is the stage when team members begin evaluating their place in

the group and struggling to determine the overall work goals of the group.

Personalities might clash at this point as the group begins to carve out helpful

ways to interact.


n Norming occurs when the group members begin to settle into individual roles

that feel like a good fit for the group. The anxiety of testing roles and boundaries

calms down, personality differences are less of an obstacle, and the leadership

of the group seems suitably established.


n Performing is the stage when the group finally comes together as a team.

The group has a shared vision of the final goal of the work and is able to

move productively toward that end.


In the 1970s, Tuckman added a fifth stage that he called adjourning, which involves

disbanding

the group. This stage might bring anxiety for group members, but

it also offers closure if the group was convened to accomplish a specific goal or

complete

a project.


Benefits of Office 2010 Collaboration


No matter where your team might be in the group-formation process, the tools in

Office 2010 can help you communicate effectively, share questions and concerns, complete

project-related tasks, and speak each others’ languages. With the tools in Office 2010, you

can streamline the following team-related activities:


n Staying in touch no matter where you’re working


n Creating shared folders that others can use to access project assets such as images,

logos,

charts, documents, and more


n Working with more than one teammate on the same file at the same time


n Checking the online status of other authors of your shared document using the

presence

icon


n Translating words and phrases easily as you work


Stay in Touch with Your Team


Office 2010 Professional Plus includes SharePoint Workspace 2010, a data-sharing workspace

that enables you to have access to all the files and data you need as you work with your

team. With SharePoint Workspace 2010 (shown in Figure 3-1), you can create a team workspace

that gives you access—both online and offline—to tasks, links, announcements, team

discussions, and document and picture libraries.


FIGURE 3-1 SharePoint Workspace 2010 enables you to take your work offline and share your files and other

project resources with team members.


Share Files in the Workspace


You can create new workspaces related to specific projects your team will be working on and

set up the elements you want to share. Because SharePoint Workspace 2010 is a true Office

2010 application, you can simply drag and drop the files you want to work on later offline or

make available to the team into the Documents library. (See Figure 3-2.)


FIGURE 3-2 You can easily drag and drop files to a workspace to share items with the team.


The files are available whether you’re offline or connected to the server; when a server

connection

is established, features such as Check In and Check Out are enabled, and you can

navigate easily through the original site to sync, download, or review files.


Not only can teams share files, post announcements, and chat in real time in SharePoint

Workspace 2010, but team members can also post to a discussion board to carry on

conversations

related to the project at hand. (See Figure 3-3.) A chat feature also is available

to allow team members to ask and answer quick questions as they work in the space.


FIGURE 3-3 With SharePoint Workspace 2010, you can have conversations with teammates on topics related

to your shared project.


Share Files and Folders


SharePoint Workspace 2010 also enables you to create shared folders in your own system so

that you can exchange files easily with your server or share them with other people. By creating

and sharing a folder with files related to your specific folder, teammates can access the

resources they need in the shared folder you created. This enables you to share files easily

without uploading them to your company’s server space and also gives you an easy way to

organize and work with files you eventually check back in to the server.


Co-Author Files Across Applications


The new co-authoring feature, available in Word 2010 and PowerPoint 2010, is one of the

new collaboration features in Office 2010. Co-authoring is also available in the Excel Web

App. Now you can work collaboratively on a document at the same time others are working

in the file. You can edit files in real time, coordinating your changes, talking about revisions,

and reviewing the work of each person on your team.


Tip You also can simultaneously edit a shared notebook that is stored on SharePoint or

Windows Live with others who are using OneNote 2010, OneNote Web App, and OneNote

Mobile 2010.


No matter how many people on your team are working together online at the same time,

each person can work on her respective section, and then changes are synchronized automatically

when the file is saved or when the user logs on the next time. The names of all

authors are displayed next to the areas of the document they are editing. Additionally, a

pop-up list of available authors is available on the application status bar when the shared

document is active. (See Figure 3-4.)


FIGURE 3-4 Co-authoring enables you to see who else is working on the current document.


Note Co-authoring requires Office Communicator 2007 R2 and Office Communications Server

2007 R2. For Office 2010 users in a business environment, SharePoint Workspace 2010 is also

needed for co-author capability. Home users can use Windows Live as the co-authoring platform

for file collaboration.


Connect via Presence


The Presence icon is a new feature in Office 2010 that shows you the availability of team

members when you’re working on shared documents. When you point to the icon, a contact

card expands, listing the ways you can contact that person. (See Figure 3-5.)


If you’re using Windows Live for document sharing, you’ll be able to send an instant message

to other authors working on the document. You’ll also be able to schedule a meeting, add

the author to your Microsoft Outlook contacts, and work with Outlook properties. If you’re

using Office Communicator R2, you’ll have these choices and also be able to start a video

call, tag the contact for presence alerts, and add the contact to your Quick Contacts list.


FIGURE 3-5 When you click the Presence icon of a contact, the contact card for that person is displayed.


So how does Office 2010 know all this information about the various members of your team?

The Presence icon reflects online status information available in either Windows Live or

Office Communicator.


Microsoft Office Communicator 2007 R2


Microsoft Office Communicator 2007 R2 is an enterprise communications tool that

enables

you to unify the various ways you communicate with others—by e-mail, instant

message, voice, or video.


Microsoft Office Communicator 2007 R2 requires Microsoft Office Communications

Server 2007 R2, which runs only on 64-bit systems. Communicator client does not

require

a 64-bit computer.


Using Office Web Apps


Today more and more of us are escaping the confines of the cubicle and venturing out to

work in unusual places—the corner coffee shop, classroom, convention floor, park bench,

or client office. Flexibility is good, but we also need an easy, secure, and reliable way to access

mission-critical documents and files. We need to review records, update reports, quickly

check the budget, get an estimate on reservations, and approve the finals on the four-color

report before it goes to the printer.


The new Office Web Apps enable you to access and work with your files anywhere in the

world you have Web access. (See Figure 3-6.) And if you don’t have Internet Explorer, no

problem—Office Web Apps support Windows Internet Explorer 7 or later for Windows,

Safari 4 or later for Mac, and Firefox 3.5 or later for Windows, Mac, and Linux. That means

that whether you’re logging in on a Mac, PC, or kiosk at a hotel or airport, you’ll find the

same reliable Microsoft Office interface and be able to review, edit, and save the files that are

important for your work.


FIGURE 3-6 Office Web Apps offer the consistent look and feel in an easy-to-use, light editing interface.


Sharing on the Road with Office Mobile


Office Mobile 2010 (shown in Figure 3-7) lets you take Office with you wherever you go—

whether you’re carrying your laptop with you or not. Using Office Mobile 2010, you can

easily

check e-mail in Outlook Mobile 2010, organize your inbox, update schedules and tasks,

and even work on your favorite Office documents, all from your favorite smart phone.


The rich interface for small devices enables you to view and edit files from your mobile

phone. You can choose from a variety of display options, perform editing and formatting

operations,

and send files to SharePoint Server 2010 or to your Windows Live account.


FIGURE 3-7 The clear, easy-to-read Office Mobile interface makes it simple for you to read e-mail, work with

Office Mobile applications, and send and receive files.


Coming Next


The collaboration features in Office 2010 enable you to continue working with your favorite

applications in real time, no matter where you are or who you’re working with. With

SharePoint Workspace 2010, you can keep your team headed in the right direction; using the

coauthoring features and the presence icon, you can work collaboratively on documents and

contact other authors in your shared documents. And Office Web Apps and Office Mobile

both help you access your files remotely so that you can keep things moving whether or

not you’re able to be at your desk to do it. The next chapter kicks off Part II of this book by

showcasing

the new features available to you in Office Word 2010.


First Look: Microsoft Office 2010


39


Part II


Hit the Ground Running


Each of the applications in Office 2010 offers new ways to communicate your ideas more

visually and effectively, features that enable you to collaborate easier than ever before,

and ways to access your work from anywhere, anytime. Whether you spend your time in

Office 2010 generating content, managing projects, or analyzing financial data, you will

discover

new capabilities that streamline your tasks, add professional impact, and add

flexibility

and creativity along the way.


This part of the book introduces you to the new features in each application and gives you

some hands-on experience with different elements so that you can get up to speed quickly

with this new release:


n Chapter 4: Create and Share Compelling Documents with Word 2010


n Chapter 5: Create Smart Data Insights with Excel 2010


n Chapter 6: Manage Rich Communications with Outlook 2010


n Chapter 7: Produce Dynamic Presentations with PowerPoint 2010


n Chapter 8: Organize, Store, and Share Ideas with OneNote 2010


n Chapter 9: Collaborate Effectively with SharePoint Workspace 2010


n Chapter 10: Create Effective Marketing Materials with Publisher 2010


n Chapter 11: Make Sense of Your Data with Access 2010


41


Chapter 4


Create and Share Compelling

Documents with Word 2010


In this chapter:


n Start Out with Word 2010


n Format Your Text


n Illustrate Your Ideas


n Improve Your Text


n Co-Author Documents


n Access Your Documents Anywhere


What’s the big story in Microsoft Word 2010? Think flexibility and freedom of expression.

Imagine working on documents in the quiet of your neighborhood coffee shop, collaborating

with a coauthor who lives in Taipei, or doing a quick review on your smartphone before

you forward the document to a major client.


Word 2010 is designed to be simple to use and yet give you all the tools you need to create

sophisticated, professional documents that express your ideas clearly and well. The new features

enable you to work efficiently and collaboratively, in a consistent, familiar interface,

whether you’re working on your computer, in your browser, or on your smartphone.


Additionally, you’ll discover simplified ways for getting around in the document and an

expanded

slate of tools that enable you to include great quality fonts and picture effects so

that your finished product looks as good as possible. This chapter introduces you to the key

new features in Word 2010 and encourages you to try a few techniques along the way.


Start Out with Word 2010


The Word 2010 window is designed to help you focus on the task at hand, whether you are

writing, formatting, editing, illustrating, securing, or sharing documents. The Ribbon (shown

in Figure 4-1) stretches across the top of the window, providing all the tools you need, just

when you need them. The status bar at the bottom of the window enables you to get current

statistics on the document as you work (for example, checking the number of words in the

file) and change views so that you can display the document in different ways.


42 Part II Hit the Ground Running


Ribbon

Status bar elements View controls


FIGURE 4-1 The Word 2010 window maximizes your workspace while providing tools across the top and

document information and views along the bottom.


Tip To display the Customize Status Bar list and add other information elements to the status

bar, right-click the status bar at the bottom of the Word window.


Get Familiar with the Word Ribbon


The Ribbon in Word 2010 makes it easy for you to find just the tools you need when you

need them. (See Figure 4-2.) Tabs contain tools related to specific tasks you want to complete.

The Insert tab, for example, includes the tools you need to add illustrations, links,

tables, and much more.


Chapter 4 Create and Share Compelling Documents with Word 2010 43


FIGURE 4-2 The Ribbon offers just the tools you need, depending on what you’re working on in Word.


Contextual tabs appear when you select a specific element in the document—for example,

when you click a picture, the Picture Tools contextual tab appears, as you see in Figure 4-3.


FIGURE 4-3 Contextual tabs offer tools that relate to the selected object in the document.


One great feature common to all Office 2010 applications is the ability to customize the

Ribbon so that you can add your own tabs, putting together the tools you use most often in

the configuration that fits you best. You can create your own custom tabs or tab groups, and

move tools on the existing Ribbon tabs to create groups just the way you want them.


Tip You can hide the Ribbon easily and maximize your work area by pressing Ctrl+F1 or clicking

the Minimize The Ribbon button on the right side of the window above the Ribbon.


Find What You Need Easily with the Navigation Pane


The new Navigation Pane is a great addition to Word 2010. Combining the best of the Find

utility with Outline view and thumbnail displays, the Navigation Pane gives you multiple ways

to find what you’re looking for in your document. Now you can move right to a section in

your document by clicking the heading you want (as shown in Figure 4-4), scroll through the

list of page thumbnail images, or enter a search phrase and choose from the list of results (as

shown in Figure 4-5).


FIGURE 4-4 With the Navigation Pane, you can move easily through the document by clicking the heading of

the section you want to see.


The improved search features offered in the Navigation Pane enable you to find the content

you need, whether it is in the basic body text or headings of the document or whether it

appears

in your document in the body text, headings, tables, graphics, footnotes, sidebars, or

comments.


FIGURE 4-5 The powerful search capability in the Navigation Pane displays a clickable results list showing all

the places in the document your search word or phrase appears.


Print and Preview in a Single View


If you are like most Word users, you print your documents on a regular basis. And using Print

Preview is part of the process, enabling you to make sure the overall page looks the way you

want it to look, the pictures are in the right places, and the headings are in the appropriate

spots. Word 2010 smooths out the printing process by combining the print and preview tasks

into a single step.


Now you can preview and print your document in Backstage view with literally a single click.

You can still change your print options, setting print quality, choosing the paper source and

size, and specifying the number of copies before you print. You can also page through the

document easily and shrink or enlarge the page view so that you can check all details easily

before sending the document to the printer.


Format Your Text


Word users typically spend quite a bit of time formatting documents. New features in

Word 2010 enable you to apply stylized effects to text, use high-quality fonts, and choose

just the right paste options for the task at hand so that your documents look professional

with just a little help from you.


Did You Know?


n Eighty percent of all documents use fewer than 20 styles.


n Word users include an average of 16 styles in each document.


n The most common formatting changes are font size, font face, and font color.


Step by Step: Printing and Previewing


Because the print and preview features are streamlined into one process in Word 2010,

you can easily review and print the file. Here’s how to print and preview a document in

Backstage view:


1. Open a document or create a new document that you’d like to print. If you create

the file, save it before you prepare to print.


2. Click the File tab on the Ribbon. This displays the Word 2010 Backstage view.


3. Click Print. The document appears in the Print Preview window to the right of the

Print options.


4. Preview the document by clicking the Previous Page or Next Page controls in

the bottom left corner of the preview window. You can also change the size of

the page display by adjusting the Zoom control in the lower right corner of the

preview

window.


5. Use the options in the center column to choose the print settings you want to

apply

to the printed document. For example, you might need to select your

printer,

specify the pages you want to print, or change from one-sided to

double-sided printing.


6. When the document in the preview looks the way you want your printout to

appear,

click the Print button at the top of the center column.


Tip Before you print a long document or multiple copies of the same document, test print one

copy to ensure the format of the document and the page margins appear the way you want

them to.


Apply Text-Formatting Effects


You’ll find a number of features in Word 2010 that help you create a pleasing, professional

look for documents of all types. Document themes let you choose a consistent color scheme,

font style, and object format; Quick Styles give you a gallery of text styles to apply to your

text; and the Font and Paragraph groups in the Home tab enable you to make changes to

individual words, phrases, lists, and more in the documents you create.


Now Word 2010 gives you the ability to add special touches to the format of your text. You

might use a special text effect to create a compelling headline, make a product name stand

out, or create an attention-getting banner for a flyer or brochure. You’ll find the Text Effects

tool in the Font group of the Home tab. Clicking it reveals a list of ready-to-apply text effects,

as well as a collection of artistic effects (Outline, Shadow, Reflection, and Glow) that

enable you to fine-tune the look even more. (See Figure 4-6.)


FIGURE 4-6 Text effects give you the tools to format headlines and text elements to make them stand out.


Tip Even after you’ve applied a special effect to your text, you can continue to modify the look

by making additional choices in the Text Effects list. You might change the bevel style of the

letters,

for example, or add a glow to specially formatted text.


Preserve Your Format Using Paste with Live Preview


How often do you copy and paste something in the documents you create? Microsoft research

shows that Copy and Paste are two of the most often-used features in Word 2010;

users might copy and paste as many as 300 times per month. Both procedures are simple,

requiring only that you select the item you want to copy, click Copy on the Home tab, put

the cursor where you want the item, and click Paste. Simple, right?


The challenge was that pasting the text or object sometimes had unexpected results,

depending

on where users pasted the item and what type of item was being inserted in

the document. In fact, users undo paste operations more than any other in Office 2010.

To answer this challenge and provide consistently what users expect, Copy and Paste have

been improved in Word 2010. Now more than 400 clipboard formats are supported to

make copying

and pasting as easy and as reliable as possible while you’re working on your

documents.


Step by Step: Pasting Content Your Way


Use Paste with Live Preview to get just the paste results you want.


The variety of paste formats and the flexibility Word 2010 offers you when you paste

text and objects in your document results in more reliable formats and less tweaking

after the fact. And that means better efficiency and reliable results. Nice!


This example shows you how to use Paste with Live Preview so that you can get the

results

you want when you paste content in your Word 2010 document:


1. With your document open on the screen, highlight and copy the text or object

you want to paste. Click Copy in the Clipboard group of the Home tab or press

Ctrl+C.


2. Click at the point in your document where you want to paste the copied item.


3. Click the Paste arrow in the Clipboard group of the Home tab. A Paste Options

gallery appears as you see here:


4. Point to each Paste icon to see a live preview of the way the item will appear in

your document.


5. Click your choice. The item is pasted in the document as you selected.


You can also display the Paste Options gallery by right-clicking in the document at the

point you want to paste the copied information. After you paste the content, Paste

Options are displayed near the paste location in case you want to make a change:


Tip Paste with Live Preview is available in all Office 2010 applications, and the selections

displayed

under Paste Options in the gallery vary depending on the type of content you have

copied to the Clipboard. To display the Office 2010 Clipboard, click the dialog launcher

in the

lower right corner of the Clipboard group in the Home tab.


Illustrate Your Ideas


With Word 2010, you don’t need to switch back and forth between software programs to

include professional-quality images in your documents. Using Word’s illustration features,

you can easily apply special artistic filters to your photos or capture screen shots to include in

your documents.


Apply Artistic Effects


The Artistic Effects in Word 2010 give you a variety of filters you can apply to your images

to produce a wide range of special effects. For example, you might apply the Pencil Sketch

effect to convert an image to an artistic black-and-white rendering, or use the Paint

Brush effect

to create a dramatic image of a new product.


To apply an artistic effect, simply select the image in the document you want to modify.

The Picture Tools contextual tab is available. Click Artistic Effects in the Adjust group.

(See Figure 4-7.) Preview the different effects by pointing to the effect you want to see; the

image is displayed with that particular effect. Click the one you want, and it is applied to

the image.


Tip Office 2010 offers enhancements to SmartArt in Word 2010, Excel 2010, and PowerPoint 2010.

Learn about SmartArt’s new features in Chapter 5, “Create Smart Data Insights with Excel 2010.”


FIGURE 4-7 Artistic effects enable you to apply a variety of special filters to the figures in a document.


Insert Screen Shots


Adding pictures of your screen can come in handy when you are preparing team documents,

sharing procedures with others, or writing a process to let others know how to work with a

specific document. No matter what you might want to capture on the screen, Word 2010

makes it easy for you to grab the parts you need and include them in your document.


When you click the new Screenshot tool, available in the Illustrations group of the Insert

tab, a gallery of screen-shot options appears. (See Figure 4-8.) The images in the gallery are

thumbnails of the various applications you currently have active on your system. To choose

one of the screen shots, click it; the image is added at the cursor position in your document.


FIGURE 4-8 You can insert a screen shot of any window currently open on your system.


Step by Step: Adding a Screen Clipping


Grab just the portion of the screen you want to include in your Word 2010 document.


Suppose that you want to quickly clip a segment of a worksheet to include in the report

you’re writing. You can grab a screen shot of the worksheet and add it to your document

by following these steps:


1. Open the document in which you want to add the screen shot, and click where

you want to insert the screen shot.


2. Open the worksheet you want to use for the screen shot.


3. Display the document again, and click the Insert tab. In the Illustrations group,

click the Screenshot arrow and choose Screenshot Clipping.


4. The worksheet automatically displays. Click in the upper left corner of the area

you want to clip, and drag across the area to be included.


5. When you release the mouse button, the area is clipped and inserted in the

document

at the cursor position.


Improve Your Text


The Word 2010 Spell Check is smarter than ever; now it takes context into account as it

checks your document. And the Word 2010 language tools make it easy to translate on the

fly when you work with colleagues around the world.


Catch More Than Typos with a Contextual Spell Check


Have you ever received a document that was spelled right but included words that were used

incorrectly? Words such as their and there or seen and scene can easily be misused in a document,

causing a disconnect for your readers and clouding your message. The Word 2010

enhanced spelling checker now evaluates the words you use for the context in which they

appear,

which helps you ensure that your documents are as correct as possible.


Tip You can have Word 2010 check for grammar and style in your document, which includes

searching for punctuation, usage, clichés, gender-specific words, and more. To change the grammar

settings, click the File tab and then Word Options, click Proofing, and then click the Settings

button in the Writing Style area.


Start Spell Check by clicking the Review tab and clicking Spelling & Grammar in the Proofing

group. The Spelling & Grammar dialog box shows you one by one any issues that the checker

discovers so that you can enter changes as you go. The Dictionary Language setting enables

you to look up the word in another language to see whether the usage or spelling is correct.

(See Figure 4-9.)


FIGURE 4-9 Now you can check the spelling and usage of words and phrases in dictionaries from

other languages.


Tip If your spelling checker doesn’t seem to be working properly in Word 2010, make sure

you’ve set your default language and that Spell Check isn’t disabled. Here’s how: On the Review

tab, click Language in the Language group and choose Set Proofing Language. In the Language

dialog box, click your primary language and choose Set As Default. When prompted, click Yes.

Now make sure the Do Not Check Spelling Or Grammar check box is clear. If a check mark

appears,

click the option to clear the box; then click OK.


Use Language Tools, and Translate on the Fly


Many people now work in teams that span not only cities but continents. When you are

working with peers in Europe, Asia, or other continents, language differences can present

challenges. Word 2010 now includes enhanced language features that help you stay in sync

with the global workplace. Now you can translate words and phrases on the fly, and develop

documents that offer ScreenTips and Help in a variety of languages.


Translating in Real Time


Another language feature in Word 2010 enables you to translate text easily as you work in a

document. Using the Translation Language tools, you can choose to show side-by-side translations,

display the full document in a Web-based translated view, or use the Mini Translator

toolbar to translate words as you go.


Setting up the translation tools is simple. In the Language group of the Review tab, click

Translate. A list offers you four choices:


n Translate Document


n Translate Selected Text


n Mini Translator


n Choose Your Translation Language


Start with the last item first if this is the first time you’re using the Translation tools. When

you click Choose Your Translation Language, the Translation Language Options dialog box

appears so that you can choose the language you’re translating from as well as the language

you’re translating to. (See Figure 4-10.) Click your choice for each option on the Translate

Document tab; then choose the language you’re translating to on the Mini Translator tab.

Finally, click OK to save your settings.


FIGURE 4-10 Set your translation languages using the Translation Language Options dialog box.


When you choose Translate Document, a dialog box appears alerting you that the document

will be translated by the Web site WorldLingo and displayed in your browser online.

To continue

the operation, click Send and your document is translated and displayed in your

Web browser window.


To translate a specific phrase or paragraph, begin by highlighting the text you want to translate;

then click Translate and choose Translate Selected Text. The Research pane appears on

the right side of your document window, and the text you selected is translated, according


to the language you selected. You can modify the settings by choosing new options in the

Research pane.


Finally, to translate words and phrases on the fly, you can use the Mini Translator tool. This

convenient little toolbar enables you to translate text as you go by simply hovering the

mouse over the word you want to translate. (See Figure 4-11.) This can help you review text

quickly and double-check your translations.


FIGURE 4-11 The Mini Translator enables you to translate words, phrases, or blocks of text as you work.


Tip The Mini Translator tool also includes an audio feature that will read back the text you select

in your document. Simply highlight the text you want to hear, choose Mini Translator in the

Translate list, and click the Play button on the Translator tool.


Co-Author and Share Documents


Word 2010 makes it easy for you to work collaboratively with others whether they work

down the hall or on the other side of the world. Co-authoring features in Word 2010 make

it possible for multiple authors to work on a file at the same time and contact each other

in the process. And using SharePoint Workspace 2010 or Windows Live, you can save to an

online workspace, communicate with coauthors, and keep track of changes in the file without

e-mailing multiple documents back and forth or running the risk of overwriting changes

another

person on your team has made.


The co-authoring capabilities require SharePoint Foundation Services (for business clients)

or Windows Live (for personal use). When you post a document to your SharePoint

Workspace or Windows Live SkyDrive space and invite another author to share it with you,

you will be able to see indicators in the document when the other author makes changes.

(See Figure 4-12.) At each point the author makes changes, you see the author’s name and

a presence indicator that shows you the author’s online availability.


FIGURE 4-12 When you co-author a Word 2010 document, you can see who else is working on your shared

document at the same time.


Tip The instant messaging, presence, and voice call features require Office Communicator 2007

R2 and Office Communicator Server 2007 R2, Windows Live Messenger, or another instant-messaging

program that works with IMessenger.


Overview: Introducing Presence


Presence technology is all about being able to reach team members whenever they are

present online. In Office 2010 Presence is available for systems running Microsoft Office

Communicator 2007 R2, enabling you to see at a glance which of your coauthors are

available online to answer questions, chat about your project, or talk about next steps.


Office 2010 applications that support presence display a small green icon beside a

person’s

name in a status bar list when they are available for contact. When you hover

the mouse over the person’s name, a pop-up list of options for contact appears. You

can send an instant message, open a chat window, compose an e-mail message, or initiate

a phone call by clicking one of the communication options. You can also click the

menu to display the contact’s full contact information and discover additional ways of

making contact.


Working with Shared Documents


You can easily add authors to documents you’re working on and share files using SharePoint

Workspace 2010 or Windows Live SkyDrive. You first post the files you want to share and

invite authors to the SharePoint workspace or SkyDrive folder. Once you begin working with

the shared document, Backstage view gives you information about the shared file, as you see

in Figure 4-13.


Shared workspace

where the file is stored

Save status of the file

Click to send

a message

to a coauthor

Authors currently

working in the file

Notes added

to the file

Click to see other documents

in the shared workspace


FIGURE 4-13 You can add the names of coauthors in Backstage view and check documents stored in the

shared workspace for the current file.


Access Your Documents Anywhere


Picture this: You are rushing out the door to get to a meeting uptown. You had hoped to put

the finishing touches on the client report you need to share with the team, but because your

afternoon meeting ran long you were unable to finish it. Now you’re on the train and have a

few minutes to spare. Luckily, you can access Word 2010 on the Web and wrap up those last

few details.


Use Word Web 2010


By logging into Windows Live, accessing your SkyDrive folders, and opening a Word 2010

document you’ve posted there, you can access the familiar Word 2010 tools and features so

that you can complete your document on time. Log in to your account, choose SkyDrive (in

the More menu), and open your My Documents folder; then click the document you want

to work with. Click View to open the file. In the Word Web App window, you can simply review

the file (if you don’t want to make any changes). Figure 4-14 shows the Word Web App

window.


FIGURE 4-14 You can review the document, do light editing to it, and even print it from the Web.


If you click Open in Word, the Word Web App will ask for your Windows Live login information.

After you provide it, the document opens in Protected view. (Protected view is always

used when a file is downloaded from an Internet location.) Click Enable Editing to activate

editing mode, and the document opens in Word 2010. When you save the document,

the changes you made are synchronized with the online document with no further action

from you.


Check Your Document with Word Mobile 2010


Need to take a quick look at a customer document before that important meeting? Or

perhaps

you want to sign off on a report so that others on your team can share it right away.

With Word Mobile 2010, you can use the familiar Word 2010 experience to display and

search your document, make simple changes, and save and finalize the file.


With Word Mobile, you can easily open, view, edit, and copy and paste information in your

Word documents—using your smartphone. Spell Check and AutoCorrect are available to

help you make sure your edits are accurate.


The document formatting—even in tables, charts, and graphics—will be preserved on your

phone display, thanks to Office Mobile’s Text Reflow technology. You can use all the familiar

formatting basics—bullets, numbering, fonts, paragraph formats, and more.


You can also send your document from your smartphone by e-mail to a friend or colleague

or post it to your SharePoint workspace.


Word Mobile 2010 is not part of Office 2010, but the software will be available at the release

of Office 2010 for phones using Windows Mobile 6.5 or later.


61


Chapter 5


Create Smart Data Insights with

Excel 2010


In this chapter:


n Start Out with Excel 2010


n Summarize Your Data Easily


n Illustrate Information Effectively


n Show PivotTable Data Your Way


n Work Anywhere with Excel 2010


Helping others understand the information you present—whether you work with words,

numbers, pictures, or media—is a key part of success in any business environment. The big

story in Microsoft Excel 2010 includes new features that help you convey your findings in

ways others can easily understand. Sparklines are small, cell-sized charts you can add to your

worksheet to provide a visual summary of the data in selected ranges; new icon sets and improvements

to data visualization options give you greater variety in the way you present information;

SmartArt and charting enhancements offer additional flexibility; and slicers enable

you to graphically slice-and-dice your PivotTable to display just the information you want to

show at any given time.


And Excel 2010 also includes new offerings for the high-end spreadsheet user: new

formulas,

support for spreadsheets with millions (yes, millions) of rows, and the integration

of SharePoint 2010 and Excel Services, which enables you to publish worksheets and

dashboards

to your intranet or to the Web. This chapter touches on the top new features in

Excel 2010 and encourages you to give a few of them a try.


Start Out with Excel 2010


The Excel 2010 window offers you an open, visually inviting workspace that presents

everything

you need to work with multiple worksheets, enter formulas and cell values, and

change the way you view information on the screen. Figure 5-1 introduces you to the various

elements in the Excel 2010 window.


62 Part II Hit the Ground Running


Quick Access Toolbar

Navigate worksheets Worksheet area View controls

Tabs Ribbon

Minimize

The Ribbon

button


FIGURE 5-1 The Excel 2010 workspace gives you plenty of room onscreen while providing the tools you need.


Tip You can hide the display of the Ribbon to maximize your space onscreen by clicking the

Minimize The Ribbon button in the upper right area of the Excel 2010 window.


The Office 2010 Ribbon includes eight tabs, each with groups of tools related to a specific

focus: File, Home, Insert, Page Layout, Formulas, Data, Review, and View. For example, to add

a SmartArt diagram to the current worksheet, you click the Insert tab and choose SmartArt in

the Illustrations group. A group of SmartArt tools appears in the Ribbon in a contextual tab

to provide the tools you need for creating and customizing SmartArt. (See Figure 5-2.)


You’ll find many of the new tools and enhancements in Excel 2010 on the Insert tab.

Specifically, the Screenshot tool in the Illustrations group, the Sparklines group, and the Slicer

tool in the Filter group are all new. The following sections introduce you to these features in

more detail.


Chapter 5 Create Smart Data Insights with Excel 2010 63


FIGURE 5-2 Contextual tabs display tools you need only when you are working with a specific item on your

worksheet.


Summarize Your Data Easily


Your worksheets enable you to organize, track, and calculate financial information over time.

An important part of making sense of the data you gather—and sharing what you find—involves

communicating the results in a way others can easily understand. Sparklines are small,

cell-sized charts that appear within your worksheet, giving readers a quick picture of what

the numbers on the worksheet mean. Because sparklines stay with your data (unlike a chart,

which might appear in a section of the worksheet some distance from the data it reflects),

they show clearly the relationship among the data values used to create them.


You can create three kinds of sparklines in Excel 2010. The program offers you the choice of

line, column, or win/loss sparklines:


n Line sparklines show trends and changes in values over time.


n Column sparklines enable you to compare values.


n Win/loss sparklines enable you to analyze values in relation to a norm.


Step by Step: Add Sparklines to Your Worksheet


Here’s how to summarize your data easily with sparklines.


You can add sparklines at any point in your worksheet where you want to show data

trends, comparisons, or summaries. Here are the steps to add sparklines and customize

them to meet your needs:


1. Open a worksheet or create a new worksheet in Excel 2010. If you are creating a

new worksheet, enter the data you want to use as the basis for the sparklines.


2. Click and drag to select the cells that include the data you want to show in the

sparkline.


3. Click the Insert tab, and click the type of sparkline you’d like to create: Line,

Column, or Win/Loss.


4. The Create Sparklines dialog box shows the range of cells you selected in the top

data field.


5. Click in the Location Range field of the Create Sparklines dialog box, and then

click the cell on the worksheet where you want the sparkline to appear.


6. Click OK. The sparkline is added to the document.


7. Click the elements in the Show/Hide group of the Sparkline Tools Design tab to

customize the appearance of the sparkline you added. As you click your choices,

new points are added to the examples in the Style gallery, as shown here:


8. Click the Sparkline Color arrow to display the palette and set the color of the

sparkline.


9. Click the Marker Color arrow to choose the color of the markers displayed on the

sparkline.


10. After you set the sparkline formatting options as you want them, you can copy

and paste the sparklines to other cells in the worksheet. Excel will update the

references

to show the correct sparkline representation in the cell.


Note The formatting options for sparklines are group-based, which means that making changes

to one sparkline changes the format of all sparklines in the series. To change an individual sparkline

(for example, to make the color of one sparkline stand out), remove it from the group by

clicking it and choosing Ungroup in the Group area of the Sparkline Tools tab.


Tip To delete an unwanted sparkline from the worksheet, click the sparkline, click Clear, and

then click Clear Selected Sparklines in the Group area of the Sparkline Tools tab.


Illustrate Information Effectively


Especially when they are reviewing large worksheets, people who are unfamiliar with the

data you’re presenting might not be drawn instantly to the key points you want them to

understand.

To help you spotlight important data elements on your worksheets, Excel 2010

includes a number of conditional formatting features. Here are a few of the elements that

draw readers’ attention to important data and help communicate what the data represents:


n Icon sets display small icons in data cells that spotlight high, mid, and low values, for

example.


n Data bars enable you to show how values in a range of cells compare with one another.


Call Attention to Your Data with Icon Sets


When you want to call attention to a specific range of cells in your worksheet, consider using

icon sets to do it. Icon sets are small pictures that appear with the data in a cell to help the

reader evaluate what the value means. For example, a cell showing a low sales value might

display a red flag, while a cell showing a top sales value could display a green flag.


Excel 2010 includes a number of new features that enhance the capabilities of icon sets. New

icon sets include new ratings sets, such as stars and boxes, and you can customize the formatting

and display choices for icon sets so that you can create exactly the display you want.


Step by Step: Use Improved Icon Sets to Highlight Data


You can spotlight key data values easily with icon sets.


Excel 2010 includes 20 icon sets in four categories: Directional, Shapes, Indicators, and

Ratings. Now you can easily format and customize the icon sets so that they show those

viewing your worksheet what’s most important and why. Data bars now show gradients

relative to the values they display, and you can show both positive and negative values

in data bars. In short, you have more control over the visualizations you choose for your

worksheet data. Follow these steps to use an icon set to display worksheet values:


1. Open the Excel worksheet you want to use.


2. Select the individual cell or range of cells where you want to add icon sets.


3. Click Conditional Formatting in the Styles group of the Home tab.


4. Click Icon Sets, and a list of icon sets appears, as you can see here:


5. Click the icon set you want to apply to the selected cells.


6. To customize the icon set, select the cells, click Conditional Formatting in the

Styles group of the Home tab, and click Manage Rules.


7. In the Conditional Formatting Rules Manager, click Edit Rule. The Edit Formatting

Rule dialog box appears, as shown here:


8. You can change the display of an individual icon by clicking the down arrow to

the right of the icon you want to change and choosing a new icon.


9. Change the range of values represented by the icon by changing the Value and

Type settings for each icon.


10. Click OK to save your changes. The worksheet displays updates automatically.


Tip You can do much more with icon sets in Excel 2010. To learn more about the different ways

you can spotlight the data on your worksheets, see Microsoft Office 2010 Plain and Simple by

Jerry Joyce and Marianne Moon (Microsoft Press, 2010).


Data Bar Improvements


Data bars offer another type of conditional formatting element in Excel 2010 that help you

analyze data values in a range of cells. Enhancements to data bars make it possible for you

to include negative values and apply formats that make the data bars easier to understand.

(See Figure 5-3.)


FIGURE 5-3 Now in Excel 2010 you can add data bars that reflect negative as well as positive values.


Step by Step: Compare and Analyze Values with Data Bars


Data bars help you show at a glance how key data values compare to one another. You

can use data bars to display a range of values that can include both positive and negative

numbers.


1. Select the range of cells where you want to add data bars.


2. Click Conditional Formatting in the Styles group of the Home tab.


3. Click Data Bars to display the list of data bar styles you can apply to the selected

cells, as shown here. As you point to each data bar style, the selected range

previews

the choice. Click the style you want to apply.


4. Add negative value capability by clicking Conditional Formatting again and

choosing Manage Rules.


5. In the Conditional Formatting Rules Manager, click Edit Rule. In the Edit

Formatting Rule dialog box, click the Negative Value And Axis button.


6. In the Negative Value And Axis Settings dialog box, select the fill color and axis

settings you want to apply to the negative value display. You can also set the axis

color.


7. Click OK to apply your changes. The data bars appear in the selected cells,

showing

any negative values as you selected.


Tip You can change the way the data bars appear in your cells by choosing either gradient

or

solid fills. Additionally, you can customize the way the fills and borders look to create the best

look for the data displayed on your worksheet.


New SmartArt Enhancements


SmartArt diagrams give you a simple way to add professional diagrams to your worksheets,

documents, and presentations. Whether you need to create an image that links product

descriptions to the values on your worksheet, spotlights key initiatives your data reflects,

or helps new hires learn your sales tracking process, you can use SmartArt to organize and

depict

your thoughts easily and effectively.


Excel 2010 adds a new set of SmartArt graphics to the mix, enabling you to choose from

additional

layout styles and incorporate pictures easily in the diagrams you add to your

worksheet. Now expanded support for text gives you more flexibility for the descriptions you

provide so that you can let the image further explain the connections between worksheet

data and the images the diagram presents.


Use Slicers to Show Data Your Way


Using Excel 2010 you can track, analyze, and report on the information you gather about

your organization. Displaying the data you need and making decisions based on the insights

you gather is an important part of working effectively in Excel. Excel 2010 includes a new

feature called slicers, which enable you to slice your data easily and include only the elements

you want in the PivotTables and PivotCharts you create. Using slicers, you can easily add

and remove elements from the table display, which helps you compare and evaluate data

from different perspectives. What’s more, you can use the slicers you create with multiple

PivotTables and PivotCharts to showcase your data consistently in a variety of scenarios.


Step by Step: Use Slicers to Segment Data Display


Use these visual controls to move data elements in and out of your PivotTable display.


1. First create the PivotTable you want to use with the slicer you create.


2. Click the PivotTable to select it.


3. Click the Insert tab, and click Slicer in the Filter group.


4. In the Insert Slicers list box, click the field you want to use to slice the PivotTable

data. In the example shown here, Cost is used to select a specific data value to

display.


5. Click OK. The slicer appears on the worksheet.


Tip You can attach a slicer you create to another PivotTable connected to the current worksheet

by clicking the slicer and choosing PivotTable Connections in the Slicer group of the Slicer Tool

Options tab. Select the PivotTable to which you want to add the slicer and click OK.


Note You can easily change the look of the slicers you add to your worksheet by clicking the

Slicer Tool Options tab and changing the slicer caption, style colors and effects, button size and

format, and overall size of the slicer window.


Tip PowerPivot for Excel is a new add-in (previously called “Project Gemini”) available with Excel

2010 that supports extremely large worksheets of up to 2 gigabytes (GBs). PowerPivot enables

you to model and analyze data on worksheets that include literally millions of rows and to sort,

filter, and use table lookup functions on multiple tables in Excel 2010.


Work Anywhere with Excel 2010


Chances are that the worksheets you create are changed, shared, and improved over time.

Perhaps you start a draft and share it with your team, and each person takes responsibility

for updating a specific section for the final version. When all the pieces are finished, you can

review the finished version and save and distribute the file you’ve created. Along the way,

you check on worksheet changes, make suggestions, answer questions, and add data visualizations,

charts, and PivotTables that help showcase the results you want readers to understand.

Using both Excel 2010 Web App and Excel Mobile 2010, you have the ability to view

your worksheet from any point you have Web or phone access and make sure the worksheet

is developing according to plan.


Excel 2010 Web App


Using the Excel 2010 Web App enables you to view your worksheet using SharePoint

Workspace 2010 or Windows Live and work with your favorite tools and features to do light

editing, review content, and work collaboratively. The Web window, shown in Figure 5-4,

offers

the consistent look and feel of the Excel 2010 interface and enables you to view, edit,

open, format, recalculate, search, and refresh the data connections in your workbook.


Tip In Excel 2010, Excel Services is integrated with SharePoint 2010, enabling you to share your

analyses with others in your organization. If you have SharePoint Server 2010, you can share your

worksheet in Excel Services by clicking the File tab, and, in Backstage view, clicking Share. Finally,

choose Publish To Excel Services.


Excel Mobile 2010 has been designed specifically to give you a simple, intuitive interface

even on your smartphone’s small display. The fonts, bullet styles, and worksheet display make

it simple for you to navigate your worksheets and find what you need easily. What’s more,

when you make changes to your worksheet using Excel 2010 Mobile, worksheet values are

recalculated instantly—no syncing required.


With Excel Mobile, you can easily create, view, and recalculate your workbooks, and you can

add charts as needed. The worksheet on your phone will support 140 different functions, so

you won’t trade processing power for flexibility when you’re crunching numbers on the road.


FIGURE 5-4 Excel Web App enables you to view, edit, format, and work collaboratively in your worksheet.

Excel Mobile 2010.


75


Chapter 6


Manage Rich Communications with

Outlook 2010


In this chapter:


n Starting Out with Outlook 2010


n Managing Your Conversations


n Cleaning Up Your Messages


n Streamlining E-mail Tasks


n Coordinating Calendars


n Improving the Look of Your Messages


n Keeping in Touch with Outlook Mobile


Communication is at the heart of everything you do. Whether you are finishing a report for

others to review, posting a new document for human resources, wrapping up a presentation

for the sales staff, or setting and scheduling appointments with clients, being able to stay in

touch with key people is a vitally important part of your daily activities.


Today’s computer user receives close to 100 e-mail messages a day, and that volume is

steadily increasing. To manage so much e-mail effectively, you need to be able to separate

the necessary messages from the unnecessary ones. Microsoft Outlook 2010 includes a

number

of new features that enable you to easily manage the messages you receive, track

important conversations, and automate your common messaging tasks. What’s more, you

can stay up to date with all your friends and colleagues via social networks and communicate

in real time using instant messaging—all within Outlook 2010. This chapter introduces you to

the new features in Outlook 2010 that help you get control of your Inbox, communicate easily

with your team, create and use group schedules, and access Outlook from your browser.


76 Part II Hit the Ground Running


Starting Out with Outlook 2010


The Outlook 2010 window gives you all the tools you need for managing e-mail and working

with calendars, contacts, and tasks. The work area is divided into five separate panes (as

described

in the following list and shown in Figure 6-1), each providing you with a different

way to work with the information you see:


n The Navigation Pane enables you to choose what you want to do. The top of the pane

displays favorite folders, the center shows all active folders in Outlook 2010, and the

bottom area enables you to choose the view you want to see.


n The Inbox (in Mail view) lists the e-mail messages you receive, arranged according to

your selection.


n The Reading Pane enables you to read the selected e-mail message without opening it.


n The To-Do Bar lists the calendar of the current month, appointments for the current

week, and your upcoming tasks.


n The People Pane shows you any social media information available for the person

sending the current message, and it lists files, appointments, and notes related to that

person.


Navigation Pane

Inbox

Ribbon Reading Pane To-Do Bar

People Pane


FIGURE 6-1 The Outlook 2010 window provides you with different ways to work with messages,

appointments,

and tasks.


Chapter 6 Manage Rich Communications with Outlook 2010 77


Using the Outlook 2010 Ribbon


Outlook 2010 includes the familiar Ribbon, designed to give you just the tools you need for

the type of operation you’re performing. The Ribbon offers seven tabs (File, Home, Send/

Receive, Folder, View, Add-Ins, and Conferencing), giving you specific tools to manage the

volume of messages, tasks, and appointments you create and receive. The Ribbon display

changes based on the view you display. For example, Figure 6-2 shows the Home tab when

Calendar view is active.


FIGURE 6-2 The Calendar view Home tab includes groups and tools for creating arranging, managing, and

sharing calendars.


Tip In Outlook 2010, you can easily customize the Ribbon to add new groups or organize tools

so that they are available just the way you want them. Click File, choose Options, and click the

Customize Ribbon category to change the way the Ribbon is displayed.


Setting Preferences with Backstage View


You’ll also discover that Outlook 2010 shares Backstage view with the rest of Office 2010,

enabling

you to add new e-mail accounts; modify your account settings; set up automatic

replies, rules, and alerts; and specify mailbox cleanup options. (See Figure 6-3.) Backstage

view makes it easy for you to view and change settings for one or more e-mail accounts that

you use with Outlook 2010.


Tip Want to use Outlook 2010 for your various e-mail accounts? Display Backstage view,

click Account Settings, and click Add Account to add your other communications connections

(

including text messaging services) to Outlook.


FIGURE 6-3 You can add e-mail accounts, set out-of-office replies, and more from Backstage view.


Managing Your Conversations


Conversation view is one of the big improvements in Outlook 2010, enabling you to see at

a glance the important messages in a conversation thread. With Conversation view, you can

stay on top of changing information, make decisions in a flash, and opt out of conversations

that no longer require your input. In addition to gathering related messages in one convenient

thread, Conversation view makes it easy for you to categorize, remove, or clean up the

messages you don’t need, which cuts down on the clutter in your Inbox.


When you open Outlook 2010, your messages are displayed in Conversation view by

default,

with the most recent messages first. The Reading Pane shows the first message in the

selected conversation. (See Figure 6-4.)


In addition to viewing and responding to messages in Conversation view, you also can

organize

your conversations to streamline your message-management tasks. For example,

you can choose the Move tool in the Actions group of the Home tab to tell Outlook to place

the current conversation in a specific folder. When you choose the feature Always Move

Messages In This Conversation, Outlook 2010 enables you to specify the destination folder so

that all messages related to the current conversation are stored in that folder automatically.


FIGURE 6-4 Use Conversation view to track conversations and bow out when they no longer require your

attention.


Step by Step: Following E-mail Conversations


Follow these steps to use Conversation view in Outlook 2010:


1. When you first open Outlook 2010, Conversation view is displayed by default. If

you have changed to another view, return to Conversation view by clicking the

View tab and choosing Conversation in the Arrangement group.


2. In the Inbox area, click a conversation group you want to view. The group expands

to show the messages most relevant to the conversation thread, as shown here:


3. To display all messages in the thread, double-click the first message in the

conversation.

The list expands to show all the messages that have been sent in

this thread.


After you’ve read the conversation, you might want to organize it in any of the

following

ways:


n Ignore further messages in this conversation by choosing Ignore in the Delete

group of the Home tab


n Clean up the conversation and remove redundant messages by choosing

Clean Up Conversation in the Clean Up selection of the Delete group (also in

the Home tab)


n Move the conversation to a specific folder by clicking Move and choosing the

selection you want in the Actions group on the Home tab.


Cleaning Up Your Messages


Many of the e-mail messages we receive on a daily basis are unnecessary, and yet because

of the volume of messages we receive we might not organize or remove them as soon as we

read them. Outlook 2010 provides the Clean Up command to help you remove redundant

messages from your Inbox.


You will find the Clean Up tool in the Delete group of the Home tab. When you click the

tool, you are given the option of cleaning up the current conversation, cleaning up a specific

folder, or cleaning up the current folder and any subfolders it contains. Simply click the item

you want and Outlook 2010 displays a message box telling you that any redundant messages

removed will be placed in your Deleted Items folder. (See Figure 6-5.)


FIGURE 6-5 Outlook 2010 makes it easy for you to clean up conversations, folders, and subfolders and weed

out unnecessary messages.


Streamlining E-mail Tasks


Most likely, you perform many of the basic Outlook tasks regularly: you check e-mail,

respond

to e-mail, set appointments, schedule tasks, and track contact information. For this

reason, the designers of Outlook 2010 set out to save you time and streamline your tasks by

giving you the ability to do those tasks with a single click. Using Quick Steps, you can perform

common tasks with a single click of the mouse button. For example, you might forward

a message to your manager, reply to a meeting, or send a team e-mail message with a single

click.


By default, Outlook 2010 includes a set of 10 Quick Steps available in the Quick Steps group

of the Home tab. (See Figure 6-6.) You can easily set up these Quick Steps to do what you

need them to do or create your own Quick Steps based on other common e-mail tasks.


FIGURE 6-6 Quick Steps enable you to complete routine tasks with a single click of the mouse button.


Table 6-1 introduces you to each of the Quick Steps that come ready to use in Outlook 2010.


TABLE 6-1 Introducing Quick Steps


Quick Step


Description


Move to:?


Prompts you to choose a folder, and gives you the option of Move To

Folder/Mark As Read


Forward: FYI


Forwards the selected message, and adds “FYI:” to the beginning of the

subject line


Team E-Mail


Displays the Customize Quick Step window so that you can enter the

e-

mail addresses of teammates and set up the feature


Reply & Delete


Displays the Reply window, and deletes the existing message after you

click Send


Create New


Enables you to create a new Quick Step


Meeting Reply


Sends a meeting response to the sender


To Manager


Automatically sends a message to your manager


Done


Moves the current message to a folder you specify, and marks the

message

as complete


Team Meeting


Creates a new meeting request for your team


Step by Step: Create a Custom Quick Step


Quick Steps were designed to simplify your common e-mail tasks. The following steps

show you how to create a new Quick Step to fit your needs:


1. Enter a new name for the Quick Step.


2. In the Actions area, click the down arrow to the right of Choose An Action, and

select the item you want to add from the displayed list, as shown here:


3. Click Add Action.


4. Click the Shortcut Key arrow, and choose a shortcut key from the list if you want

to assign one.


5. Enter text to describe the action in the Tooltip Text text box.


6. Click Create.


Tip The Quick Contacts feature enables you to locate contacts quickly in Outlook 2010. In the

Find group on the Home tab, simply click in the Find A Contact box and type the first few characters

of the person’s name. If you are using Office Communicator, a list of contacts that match

the characters you typed appears toward the bottom of the To Do Bar. If you are not using Office

Communicator, when you press Enter, the Choose Contacts message box appears, listing all contacts

that match the characters. Choose the contact you want by clicking the name and clicking

OK. The person’s contact record is displayed so that you can review or modify it and save it.


Working with Presence and Social Media


When you are working collaboratively, being able to tell when teammates are online and

available to answer a quick question is a definite plus. Outlook 2010 provides presence and

status information for your contacts so that you can easily communicate with others in real

time. When the green presence indicator shows you that a coworker is online, you can make

a quick call, start a video conference, or take a few minutes to meet virtually—communication

that enables you to keep your project moving forward.


If you are working with Outlook Web App or using Office Communicator, you will be able to

see the presence information in the Reading Pane and in the Contacts list. Hover the mouse

over a name in the message header to display a complete contact card with pictures and

contact information. (See Figure 6-7.)


FIGURE 6-7 Outlook 2010 includes presence information for your contacts in Outlook Web App and Office

Communicator.


Tip If you are using Outlook with Microsoft Exchange 2010, the MailTips feature enables you to

double-check the e-mail messages you send. MailTips alert you when you are sending messages

to contacts outside your office, replying to a large distribution list, or sending a message with

confidential information.


The People Pane at the bottom of the Reading Pane shows you the sender’s profile picture

and gives you access to additional information about that person—her recent status update,

any files she sent you, upcoming relevant appointments, and more. You can sign up with

third-party social media sites and receive status updates and profile changes without ever

leaving Outlook 2010. (See Figure 6-8.)


FIGURE 6-8 Outlook 2010 incorporates social media features that enable you to stay in touch with friends

and colleagues through social media.


Coordinating Calendars


One of the challenges to keeping a team moving in the right direction involves finding a

time to meet when everyone can attend. The new scheduling features in Outlook 2010 make

viewing, updating, and sharing calendars easier than ever. And you can easily create Share

groups so that all scheduling information for your team is kept together in one easy-tounderstand

view.


Viewing Group Schedules


The new Schedule view enables you to easily combine a number of calendars on the screen

at one time. This makes setting appointments simple and enables you to coordinate the free

and busy time your group needs to get things done.


Step by Step: View Calendars in Schedule View


You can easily view the calendars of everyone on your team using Schedule view:


1. First, make sure that others on your team have shared their calendars with you.


2. Click Calendar.


3. In the Home tab, click Schedule View. The display shows the calendars that you

have permissions to view, along with busy and available times, as shown here:


Create a Calendar Group


If you are part of a team that works together regularly, you might want to create a calendar

group so that you can easily view all schedules together. You can create a calendar group

by clicking Calendar Groups in the Manage Calendars group on the Home tab. If you want

to save the group of calendars in the current view as a calendar group, click Save As New

Calendar Group. If you want to select a new set of calendars and create a group, choose

Create New Calendar Group. With either selection, the Create New Calendar Group dialog

box appears. (See Figure 6-9.) Type the name you want to use for the group, and click OK.


FIGURE 6-9 Create a calendar group to display all schedules for your team.


After you create the calendar group, the group name appears in the navigation pane on the

left side of the calendar window. (See Figure 6-10.) You can hide the display of the group

when it’s not needed by clearing the check box; to redisplay the calendar group, select the

check box again.


FIGURE 6-10 After you create a group calendar, Outlook 2010 adds it to your Calendars list.


Improving the Look of Your Messages


Now you can apply the professional designs available in Office 2010 themes to the e-mail

messages you create and send. Outlook 2010 includes dozens of themes you can apply to the

messages you send to clients, peers, friends, and family. When you apply an Office theme to

your message, the colors and fonts that are part of that theme are reflected in the styles you

choose to format the text in your message. Later if you choose to change the selected theme,

the styles you use will also change automatically to reflect the new styles.


The Office themes also are consistent throughout all your Office 2010 files, which means that

you can coordinate the files you send so that the message you send can have the same look

and feel as the files you attach to it.


Step by Step: Applying Office Themes


Adding an Office theme to your e-mail messages is as simple as point and click. Here’s

how to do it:


1. Open the message to which you want to apply the theme.


2. Click the Options tab.


3. Click Themes. The Themes gallery appears, as shown here:


4. Hover the mouse over themes you want to preview.


5. Click the theme you want to apply to the message.


Note You can choose different fonts and colors from those offered by a specific Office theme,

but if you later change the Office theme applied to the message, the fonts and colors you

changed will not be updated automatically.


Keeping in Touch with Outlook Mobile


In today’s mobile world, many people are accustomed to checking e-mail, receiving text

messages, and updating their calendars online. Now, using your Windows Mobile smartphone,

you can use the high-quality phone display to view your messages in Conversation

view, selecting and moving messages using touch technology, and get online access to your

calendar, contacts, tasks, and more.


Tip Let Outlook 2010 know which types of alerts you want to receive on your smartphone by

clicking File, choosing Options, and clicking the Mobile category in the Outlook Options dialog

box. Select the appropriate check boxes if you want Outlook to send calendar summaries and

reminders to your smartphone. Additionally, you can arrange to forward Outlook items to your

phone or find a text-messaging service provider and set up your phone for Short Messaging

Service (SMS) messaging.


Outlook Mobile is also available to Microsoft Exchange customers as part of the standard

licensing agreement.


89


Chapter 7


Produce Dynamic Presentations with

PowerPoint 2010


In this chapter:


n Starting Out with PowerPoint 2010


n Editing and Formatting Video


n Creating and Working with Animations


n Enhancing Your Presentation with Transitions and Themes


n Adding Sections to Your Presentation


n Managing and Sharing Your Presentation


Imagine this: You’re in a crowded board room waiting for your chance to present new ideas

to a prospective client. You and your team have been working on this presentation for weeks.

The content is just right—the approach hits the mark, and you’ve even added custom video

clips and animations to spotlight key ideas you want the client to remember.


PowerPoint 2010 gives you the ability to add and edit video in your presentation, edit

pictures

on your slides, enhance animations, choose from among improved transitions,

add great narration, compare and merge presentations, and much more. The collaborative

features in PowerPoint 2010 enable you to easily work on your presentations with a

team, communicate in real time with coworkers, and access your files anywhere—using your

browser window or your smartphone.


Starting Out with PowerPoint 2010


The PowerPoint 2010 window gives you a simple, intuitive interface that provides all the tools

you need for building effective, professional presentations. The PowerPoint Ribbon offers

tabs that include tools specific to each of nine different tasks: File, Home, Insert, Design,

Transitions, Animations, Slide Show, Review, and View. The PowerPoint work window displays

Slide view by default, which shows your current slide in the largest area of the window,

along with a segment for notes and a panel that will show all the slides you create in the

presentation.

(See Figure 7-1.)


90 Part II Hit the Ground Running


Notes View controls

Tabs Current slide Ribbon

Slide thumbnails


FIGURE 7-1 The PowerPoint 2010 window provides the tools for creating the current slide, adding notes, and

working with all slides in your presentation.


You display Backstage view in PowerPoint by clicking the File tab. The Backstage view gives

you the controls you need to work with the presentation file you’re creating. (See Figure 7-2.)

Commands in Backstage view enable you to optimize the media you include in your presentation,

set permissions for your co-authors and teammates, control version information, and

prepare the file for distribution.


Additionally, you use Backstage view to create new presentation files, print slides and

handouts,

set PowerPoint options, and choose how you want to share the presentation.


Chapter 7 Produce Dynamic Presentations with PowerPoint 2010 91


FIGURE 7-2 Backstage view enables you to set preferences for your PowerPoint files and compress and

optimize

the media files you use.


Tip If you are working with Office Communicator, you will be able to add and view authors in

the right panel of the Info display in Backstage view. If you are using Windows Live to share your

presentation, you can add authors in Backstage view but presence information will not display.


Editing and Formatting Video


Video is the big story in PowerPoint 2010. It’s no secret that video is everywhere—whether

you are interested in filming your own video clips to demonstrate a new product or service

or want to include a video from the Web for a little visual interest, you can easily incorporate

video into your PowerPoint presentation.


Now when you add a video to your presentation by choosing Video from File in the Media

group of the Insert tab, the file is embedded into the presentation itself, which makes

packaging

and presenting a snap.


Tip If you choose Video From Online Video Site, PowerPoint displays a dialog box so that you

can paste the embedded code from the site onto the slide. Using this process to include video

does not embed the file, however; it simply creates a link to the video online. This is an important

distinction to remember if you are presenting in a place that does not have an Internet connection.


The video editing features available in Video Tools Playback enable you to trim the video

without ever leaving PowerPoint. (See Figure 7-3.) When you’ve captured more video than

you need for the current presentation, having the ability to cut the clip down to size without

leaving PowerPoint is a great timesaver. You can also change the fade in and fade out values,

adjust the volume, and set playback options using the editing tools in the Video Tools

Playback tab.


FIGURE 7-3 You can easily trim your video in PowerPoint 2010 to select the best segment for your

presentation.


PowerPoint also includes video styles you can apply to the video clip in your presentation.

When you apply a style, the format remains in effect while the video plays. For example, if

you choose the Reflected Perspective Right Video Style, which angles the video slightly to the

right, the entire video clip will play at that angle.


Tip PowerPoint also shares the picture editing tools available throughout Office 2010. Simply

click a picture in your presentation and the Picture Tools Format tab appears, offering you tools

for making picture corrections, changing the color, applying artistic effects, applying picture

styles, and much more.


Step by Step: Adding and Editing Video


Follow these steps to add and edit video in PowerPoint 2010:


1. Display the PowerPoint slide where you want to add the video.


2. Click the Insert tab, and click Video in the Media group.


3. On the File tab, click Video.


4. In the Insert Video dialog box, select the video file you want to add and click

Insert. The video is placed on the slide.


5. Click the Video Tools Edit tab, and click Trim Video. Drag the beginning and end

markers to the place you want the video clip to begin and end, as shown here:


6. Test the video by clicking the Play button. Adjust the markers as needed.


7. Click OK to save your settings.


8. Change the Fade In and Fade Out settings to change the way the video begins

and ends.


You can continue to make changes and play the video by clicking the Play button

in the video player on the slide.


Tip Now you can add precision to your slides by using the dynamic alignment guides. These

guides appear automatically whenever you drag an object on the slide, helping you align the

object with other elements on your slide.


Creating and Working with Animations


PowerPoint’s improved animation features enable you to animate objects on your slide,

spotlighting

key points and adding movement to your presentation. The animations in

PowerPoint 2010 are now more realistic, creating the effect of smooth movement for the

animations

you create. (See Figure 7-4.)


FIGURE 7-4 PowerPoint 2010 now includes improved animations you can add to virtually any object on

your slide.


Tip PowerPoint 2010 includes a number of new transitions that enable you to control the way

your slides advance. The transitions you choose are important because they convey the overall

tone of your presentation—slow or fast, blocks or fades, sweeps or subtle dissolves—each

transition

contributes to the overall effect you’re creating.


When you add an animation to your slide, the Trigger tool becomes available in the Custom

Animation tab of the Animations tab. Using the Trigger feature, you can add a bookmark to

trigger the animation you want to play on the slide.


PowerPoint also includes the Animation Painter, which enables you to apply animation

settings

to other objects on your slide. This feature is similar to the Format Painter, which

enables

you to choose format settings to apply to other text in your document.


Step by Step: Adding an Animation


Here’s how to add an animation to your slide in PowerPoint 2010:


1. Display the PowerPoint slide where you want to add an animation.


2. Click the object you want to animate.


3. In the Animations tab, click Add Animation in the Custom Animation group. A

gallery of animation options appears.


4. Point to different animations to see how the animation looks on the slide. Click

the style you want.


5. You can customize the animation by choosing the options at the bottom of the

Add Animation gallery.


After you add the animation, you can fine-tune the animation’s behavior by using

the tools in the Animation, Custom Animation, and Timing groups. After you

make changes, use Preview to view your changes.


Tip PowerPoint 2010 also includes improved narration features, which means that you now can

record voiceovers that you play back during your slide show. To try the narration feature, connect

your microphone and make sure it’s working; then click Record Slide Show in the Set Up group of

the Slide Show tab.


Enhancing Your Presentation with Transitions and

Themes


If you’ve been using PowerPoint for any length of time, you’ve no doubt already discovered

slide transitions. Transitions give your presentation a professional touch by fading, dissolving,

wiping, or panning one slide into another. PowerPoint 2010 introduces great new transitions

to help you capture and keep the attention of your audience. (See Figure 7-5.) The new transitions

are easy to find and apply; and you can preview the different effects until you find

just the transition style you want. You can apply transitions to a single slide or to all slides,

and you can customize the transition by specifying the duration of the transition, deciding

whether to apply a transition sound, or choosing transition effects.


FIGURE 7-5 PowerPoint 2010 includes new transitions you can apply to your slides.


Step by Step: Applying Transitions


Here’s how to apply slide transitions in PowerPoint 2010:


1. Open the presentation to which you want to apply the transitions.


2. In the Transition To This Slide gallery, click the transition you want to try.


3. Experiment with other transitions until you find the one you want to use.


4. Click Effect Options to display the additional choices for the transition you selected,

and choose the effect you want.


5. If you want to add sound to the transition, click the Sound arrow and choose the

sound you’d like to add.


6. In the Duration field, set the number of seconds you want to allow for the transition

to be completed.


7. If you want to apply the transition settings to all slides in the presentation, click

Apply To All.


Adding Sections to Your Presentation


Now in PowerPoint 2010 you can organize your presentation into sections to enable you to

navigate through your slides in the way that fits your content best. Suppose, for example,

that your presentation introduces your audience to a new program being offered through

your human resources department. As you begin the presentation, you discover that the

group has previously seen an introductory presentation that covers all the material you introduce

in section one. Because you have organized your presentation in sections, you can easily

jump to section two of your presentation and continue with the information your audience

hasn’t seen, without missing a beat. (See Figure 7-6.)


FIGURE 7-6 Create sections and use them to navigate easily during the presentation.


Working with sections also enables you to organize long presentations so that you can work

with them easily while you’re creating and editing your work. When you add a section—by

clicking the first slide in the section you want to create, clicking Section in the Home tab, and

choosing Add Section (as shown in Figure 7-7)—the Slides view changes to highlight the new

section. Additional controls enable you to rename, collapse, expand, and remove sections

easily.


FIGURE 7-7 Add sections to your presentation to better organize and navigate longer slide shows.


Managing and Sharing Your Presentation


Because it’s likely that you will be collaborating with others on the presentations you create,

PowerPoint 2010 makes it easy for you to manage, compare, merge, and share presentations.

This reduces the likelihood that you’ll have multiple versions of the same file in circulation

and enables you to keep the project moving by communicating with other authors easily

while you work.


Merging Presentations


If you are combining changes that several reviewers have made in a single presentation, the

Compare tool in PowerPoint 2010 can simplify the process of putting it all together. The

Compare tool helps you see which changes have been made in the presentation and create

one merged file that reflects the latest version of the shared file.


The compared view shows the changes made among the versions and provides the

Revisions panel to help you see where the changes were made and what they entailed.

(See Figure 7-8.) You can click the small note icons on the slides to display information about

the specific changes made to the elements on the slide.


FIGURE 7-8 PowerPoint 2010 compares and displays changes among versions of the file.


Step by Step: Comparing Presentations


Follow these steps to use the compare and merge feature in PowerPoint 2010:


1. Open the presentation that you want to compare to another version of the file.


2. Click the Review tab, and click Compare.


3. In the Choose File To Merge With Current Presentation dialog box, navigate to

the folder with the file you want to use.


4. Select the file and click Open.


5. PowerPoint displays the merged file and shows the Revisions pane to list the

changes between the versions. Click a change in the Details pane to display a

pop-up list of changes to that element.


6. Select the check boxes of changes you want to keep. Repeat this step for all

changes in the presentation.


7. To save the merged file, press Ctrl+S. To discard the changes, close the file without

saving.


Tip PowerPoint includes co-authoring capability for users who work with SharePoint Workspace

2010 or Windows Live. Co-authoring gives you the ability to work collaboratively with authors

on the file. You can share the file by clicking the File tab to display Backstage view and then

clicking Share. You can enter author information in the Related People area of the Info panel

in Backstage view. If you are using Office Communicator, you can send an instant message to

another author while you work on a slide, which enables you to ask and answer questions in real

time while you work.


Broadcasting Your Presentation


PowerPoint 2010 enables you to broadcast a presentation to others at remote locations

whether or not they have PowerPoint installed on their computers. The Broadcast Slide Show

feature works with SharePoint Server 2010 or Windows Live. You simply choose Broadcast

Slide Show in the Start Slide Show group of the Slide Show tab and click Start Broadcast. (See

Figure 7-9.) The broadcast service sends your remote audience members the link to your presentation

so that they can log in using their Windows Live account and participate directly.


Note Broadcasting your presentation in this way displays the visual portion of your

presentation

only; no audio is transmitted. If audio is necessary for your presentation, you might

want to set up a conference call so that participants can hear your narration, ask questions, and

participate in the presentation.


FIGURE 7-9 Broadcasting a slide show.


PowerPoint 2010 gives you the choice of sending an e-mail message or an instant message

to the people who want to view the presentation. When others receive the link, they can

simply

click it to join the presentation in real-time. (See Figure 7-10.)


FIGURE 7-10 Others can view your broadcast presentation in real time whether they have PowerPoint or not.


Printing Presentation Notes


If you have written a script or presentation notes that you want to have available in your presentation,

you can print them easily using Backstage view. Simply click the File tab to display

Backstage view, and click Print. In the Print display, select the Full Page Slides setting in the

Other Settings area. A pop-up gallery of print layouts appears. (See Figure 7-11) Click Notes

Pages, and then click the right arrow below the preview document to page through your

notes.


Tip PowerPoint also includes the Create Handouts In Microsoft Word feature to enable you to

save your notes, along with the representative slides, to a Word document. To save the notes

to Backstage view, click File to display Backstage view, click Share, and click Create Handouts In

Microsoft Word. Finally, click Create Handouts.


FIGURE 7-11 You can easily print your presentation notes by choosing Notes Pages in the Print settings.


Save Your Presentation as a Video


Another new feature in PowerPoint 2010 makes it easy for you to save your presentation as

a video and share it with others. Click File to display Backstage view, and click the Share tab.

Then click Create A Video to display the available video options. Table 7-1 shows your choices

for the level of video quality.


TABLE 7-1 Video quality for presentations


Used For


Resolution


Quality


Frames Per Second


Computer & HD Displays


960 by 720


High


30


Internet & DVD


640 by 480


Medium


24


Portable Devices


320 by 240


Low


14


After you choose the video quality, click the Use Recorded Timings And Narrations option. A

range of options enables you to disallow timings and narrations, set new timings and narrations,

preview the current settings, or use the existing settings. Click the Create Video button

to start the process, and PowerPoint saves a video as a .wmf file. (See Figure 7-12)


FIGURE 7-12 Create a video of your PowerPoint presentation.


Work with the PowerPoint 2010 Web App


As part of the access-anywhere approach available in Office 2010, you can use the

PowerPoint Web App to view and edit presentations from your Web browser. The PowerPoint

Web App offers a limited set of editing tools in the familiar Ribbon interface (shown in

Figure 7-13); you also can work collaboratively with other authors using the PowerPoint Web

App and display your presentation in full-screen view.


FIGURE 7-13 PowerPoint Web App displays your presentation in the familiar Office interface.


Using PowerPoint Mobile 2010


PowerPoint Mobile 2010 enables you to view your presentation slides in the familiar Office

interface designed for the simplicity of a small mobile screen. You can use PowerPoint Mobile


2010 to review your presentation notes, easily work with slides using Slide Manager, and

page through the slides you’re presenting. And in the live presentation, you can also use

PowerPoint on your smartphone to advance your slides remotely.


Tip If you use a Tablet PC or another device with tablet features, you can take advantage of the

better inking features in PowerPoint 2010. A greater variety of inking tools—including a large

collection of pens and expanded inking options—are available for you to use. You’ll find the

inking

features in the Review tab of your tablet-enabled device.


105


Chapter 8


Organize, Store, and Share Ideas

with OneNote 2010


In this chapter:


n Starting Out with OneNote 2010


n Capturing Notes Easily


n Working with Linked Notes and Task Notes


n Finding Just the Notes You Need


n Sharing Ideas Effectively


n Accessing Your Notes Anywhere


Are you a big note-taker? Do you scribble ideas on backs of envelopes, sticky notes, scraps of

paper, and pieces of napkins? Taking notes is a good practice—and it just might turn out that

one of those notes will have the perfect answer to a problem down the road. But if you can’t

find what you’ve scribbled later, chances are that your inspiration will go to waste.


Microsoft OneNote 2010 is the electronic equivalent to a handy notebook, with a twist:

the program is designed to capture text, links, Web content, video and audio clips, articles,

drawings, and more—in whatever way you collect them. Whether you prefer to doodle your

ideas, speak into a microphone, scribble cryptic notes, or clip pieces of Web pages, OneNote

makes it easy to pull all that content together in one searchable place where you can find it

easily later. And as you continue to amass ideas that fascinate you, you can easily find and

incorporate those sparks of inspiration into your current projects.


The new features in OneNote 2010 make it easy to collect notes from Microsoft Office 2010

applications such as Word, PowerPoint, and Outlook and print the notes to your OneNote

notebook. You can also share your notebooks and track changes by author, version, recent

changes, and more. So even though you work collaboratively, you can still separate the great

ideas from the good ideas. The search feature in OneNote is now better than ever and includes

an expanded search pane, which enables you to see at a glance all the occurrences of

the search phrase that appear in your notebook.


The OneNote Web App enables you to access your notebooks from any place you have

access

to the Web, and OneNote Mobile makes it possible for you to review and do simple

editing in your notebook using your smartphone. As you begin to use OneNote regularly to

collect your thoughts and plans, you’ll realize that more and more of your great ideas are

actually making it into the work you do in Office 2010.


106 Part II Hit the Ground Running


Starting Out with OneNote 2010


The OneNote 2010 window gives you a great range of flexibility in the way you work with

the notes you create. Each tab in the Ribbon offers tools related to a specific note task:

File, Home, Insert, Share, Draw, Review, and View. (See Figure 8-1.) The various areas of the

OneNote window enable you to work with the notes you create in different ways:


n The Navigation Bar enables you to move easily among your notebooks. You can click

the expand button at the top of the Navigation Bar to display a list of all notebooks

and the pages they contain.


n Section tabs give you a simple way to store different types of information in your

notebook.

You can create subpages and sections within each section and rename the

section tabs to fit your needs.


n The page tabs display the titles of existing pages in the current section. You can click

page tabs to move among pages in a section easily.


n The OneNote page collects your notes in any way you want to enter them. Simply click

anywhere and type, write, or draw, or add a voice, video, or file object.


Navigation Bar

Unfiled Notes

Section Tabs Ribbon Search Page Tab


FIGURE 8-1 The OneNote 2010 window gives you access to your notebooks, unfiled notes, and much more.


Chapter 8 Organize, Store, and Share Ideas with OneNote 2010 107


Capturing Notes Easily


The whole idea behind OneNote is that you need one central location where you can gather

all your notes—in whatever form—so that you can organize, share, and use them easily. You

might insert pieces of interviews, maps to locations, clips of video, photos of products, meeting

notes, articles, and anything else that provides you with the information you need for the

projects you’re creating.


Today everyone suffers from information overload in one way or another, and we all find

ways to do our best to manage the data that comes our way. Developing a smart, fast method

of organizing your notes helps you be more efficient and bring an even greater range of

resources to your work. One Note 2010 includes several features that make it simple to create

and work with the information you capture in your notebooks.


Using OneNote as You Work


Chances are that as you work on a specific document, worksheet, or presentation—or even

as you’re composing an e-mail message or surfing the Web—ideas are occurring to you that

relate to the task at hand. If you’re editing a report, for example, you might think of a site

you visited last week that had some interesting statistics about the topic you’re reviewing.

Using OneNote, you can make a note to yourself to look up that site when you’re finished

editing. And you can make the note right alongside the work you’re doing in Word.


The Dock To Desktop feature in OneNote lets you easily position OneNote in a reduced-size

window alongside other open applications. This means you can take notes—or refer to notes

you’ve already taken—while you’re working on a document, worksheet, or presentation, To

dock OneNote to your desktop, click the Dock To Desktop tool in the Quick Access Toolbar in

the top left corner of the screen. The OneNote window shrinks to the current note page only,

as you see in Figure 8-2.


When you’re ready to expand the OneNote window to full screen view, click the Full Screen

icon in the Quick Access Toolbar. To return the Navigation Bar, section tabs, and page tabs to

the display, click the View tab and click Normal View.


Tip Although there’s no hard-and-fast rule for the way your notes are supposed to look in your

own personal notebook, using specific styles on your note headings can help you find the information

you need easily when you’re scanning through the pages. You can now apply Quick

Styles to your note headings by selecting the text (or clicking where you want the style to begin)

and clicking the style you want in the Styles group on the Home tab.


Dock to Desktop Full Page View


FIGURE 8-2 You can use Dock To Desktop mode to keep a OneNote page open alongside your other

application

or browser window.


Tip One new feature in OneNote 2010 enables you to recover notes you’ve previously deleted.

To restore deleted notes, click the Share tab, and in the History group, click Notebook Recycle

Bin to open the bin so that you can open the notes you want to preserve.


Create Notes Anywhere


For OneNote 2010 to be a hub for all the notes you collect, the program needs to work

seamlessly with your other Office applications. Perhaps you finished a presentation and realize

after the fact that you can use it as the basis for another project you’ll be working on next

month. You can save the presentation in your OneNote notebook for that project with just a

few simple clicks.


You can use the Print command in either Word 2010 or PowerPoint 2010 to send an entire

file—in living color—to the OneNote notebook you select. You can then clip sections, graphics,

notes, or slides; leave the entire file as is; or use the content in other documents or notebooks

you create. This technique is simple, reusable, and smart—putting your content within

easy reach for you to use in other projects down the road.


Step by Step: Printing a File to OneNote 2010


Here’s how to incorporate an entire file in your OneNote 2010 notebook:


1. Open the PowerPoint presentation or Word document you want to add to your

OneNote notebook. (This example uses a PowerPoint presentation, but the process

is the same for either application.)


2. Click the File tab to display Backstage view.


3. Click Print. In the Printer area, click Send To OneNote 2010, as shown here:


4. Click Print. The Select Location In OneNote dialog box appears, as you can see

here:


5. Click the expansion button to the left of the notebook to which you want to add

the file.


6. Click the section or page where you want the article to be placed, and click OK.

The entire file is inserted on the page you selected.


Working with Linked Notes and Task Notes


OneNote 2010 offers the Linked Notes feature in Word 2010, PowerPoint 2010, and Internet

Explorer 8. Suppose that you are writing a report in Word 2010 and you want to check something

in the notes you took at the last team meeting. While you’re working in the document,

click the View tab and then click Linked Notes. The notebook you used to gather ideas for

this document opens automatically in a panel along the right side of the Word window.

OneNote automatically saves a link to the file or Web page you are reviewing so that you

can easily return to the source of your notes later. When the OneNote window is open, you

can add, edit, move, search, or organize your notes; copy them into the Word document; or

simply

check what you wanted to review and close the file.


Note The Linked Notes feature does not appear automatically in the Internet Explorer toolbar.

To open a OneNote page while working in Internet Explorer 8, click Tools and choose Linked

Note from the Tools menu.


The first time you use the Linked Notes feature with a new file, OneNote 2010 will display the

Select Location In OneNote dialog box so that you can choose the notebook, section, and

page you want to use with the current application. Expand the notebook to display the sections

and pages; then click the OK button and the OneNote page appears in a small window

along the right side of your work area.


Tip Linked Notes works only with OneNote 2010, so if you have saved your notebook to be

compatible with OneNote 2007 users, you will need to convert the notebook to OneNote 2010

in order to use Linked Notes. A dialog box will prompt you to change the notebook properties if

Linked Notes is not currently available for your file.


OneNote 2010 is also available in Outlook 2010, enabling you to easily capture notes on

project-

related tasks you create for yourself or for members of your team. To send the Task

Notes you create to a OneNote 2010 notebook, simply create and save the task; then click

OneNote in the Actions group of the Task tab. (See Figure 8-3.)


FIGURE 8-3 You can easily send task information to a OneNote notebook.


Finding Just the Notes You Need


If you’re like most people, a percentage of the notes you take never make it into any kind of

practical use. Why? Chances are that a number of your good ideas simply get lost—stuck in

a coat pocket somewhere, left in your other briefcase, or forgotten on the table of the restaurant.

With OneNote 2010, you capture all your information in one easy-to-navigate place,

which means you can always retrieve what you need easily using OneNote’s powerful search

tools.


In OneNote 2010, the search features have been expanded so that they now go through all

types of content—including video clips, embedded objects, and more. The search navigation

pane appears as you begin to type a search word or phrase, showing you all the places in

your notes where the search characters appear. (See Figure 8-4.)


FIGURE 8-4 The expanded search pane instantly shows results as you begin to type your search phrase.


You can customize where OneNote searches information in your notebooks by clicking the

Finished: All Notebooks (Change) link at the top of the search pane, and if you want to keep

the Search Results Pane open alongside the work area, click the Open Search Results Pane

link at the bottom of the search pane.


Sharing Ideas Effectively


One of the great things about OneNote is that it serves as a creative catch-all for any type

of information you gather related to a specific project, idea, or event. No matter what your

team is working on, team members can save text notes, diagrams, sketches, audio clips, video

clips, Web links, and even doodles to the pages in your shared notebook.


OneNote 2010 includes a number of new sharing features that help you recognize easily who

has added what—and when. You will be able to search through the notebook by author,

highlight the changes you haven’t read, check note versions, and much more. You’ll find all

the tools you need for working with shared notebooks on the Share tab. (See Figure 8-5.)


FIGURE 8-5 The new Shared Notebook features in the Share tab enable you to track the changes in the

notebook

that are made by your team.


Creating a Shared Notebook


To create a new shared notebook in OneNote 2010, click the Share tab and click New Shared

Notebook in the Shared Notebook group. Backstage view appears, with Network Notebook

selected. Enter a name for the new notebook, and click Browse to select a location for the

notebook. Finally, click Create Notebook to add the new shared notebook to your files.


Tip After you’ve created a notebook, you can invite others to share the notebook with you by

displaying the Info page of Backstage view. All notebooks are listed, showing the title of the

notebook, the Settings button for each notebook, as well as the location of the notebook file and

the sharing status of the notebook. To display the properties for the notebook, click the Settings

button and click Properties.


Finding Entries by Author


Suppose that you’ve been discussing a new idea for a video clip with one of your teammates,

and she mentions that she posted the link to a video she liked on a page in your

shared OneNote notebook. How can you find the note she added to the file? The Find By

Author tool in the Shared Notebook group on the Share tab enables you to sort entries first

by person and then by date, showing the most recent posts first. In this way you can find the

author’s name, read the description of the addition as well as the date, and then click the one

you want to display it in the OneNote page view. (See Figure 8-6.)


FIGURE 8-6 Find By Author enables you to display all entries made by author, date, and description so that

you can move easily to the note you need.


Working with Page Versions


One of the challenges in working with multiple authors on a notebook is that it can be

difficult

to tell which version of the page you’re viewing. Are you adding your notes on the

most recent version of the page? OneNote 2010 includes the Page Versions feature to help


you determine that you’re working on the most recent page available so that you can be sure

all changes are incorporated in the page you’re viewing. Simply click the Share tab and click

Page Versions in the History group. (See Figure 8-7.)


FIGURE 8-7 Displaying page versions enables you to review the content added to your pages and make sure

you’re working with the most current page.


Tip You can also use page versions to undo changes that were made inadvertently. You can

return

the page to an earlier version, and changes will be merged and synched automatically.


Accessing Your Notes Anywhere


Following the work-anywhere trend set by the other applications in Office 2010,

OneNote 2010 enables you to add, update, and share notebooks on the Web or access and

make changes to your notes using your Windows Mobile smartphone. The OneNote Web

App enables you to view, share, and edit your notes pages; you can easily add notes, edit

existing notes, and capture links, screen shots, files, and more. Additionally, OneNote Mobile

fits the OneNote 2010 interface to the small smartphone display, enabling you to review,

update, and work with your notes while you’re on the go. When the product is available,

you will be able to set up OneNote Mobile to work with your Windows Mobile smartphone

by clicking File and choosing Options in Backstage view. Click the Advanced tab and scroll

down to the OneNote Mobile settings. Click the Install OneNote Mobile button to install the

mobile

version

of OneNote 2010 and set up the software for your smartphone.


117


Chapter 9


Collaborate Effectively with

SharePoint Workspace 2010


In this chapter:


n What Can You Do with SharePoint Workspace 2010?


n Starting Out with SharePoint Workspace 2010


n Setting Workspace Preferences


n Accessing Your Files Seamlessly


n Simplified Searching


n Checking Files In and Out


n Connecting with Your Team Instantly


n SharePoint with InfoPath and SharePoint Business Connectivity Services


n Using SharePoint Workspace on the Go


When you need to send a document to a teammate for review, what do you usually do?

Most people attach a document to an e-mail message and click Send. This works—somewhat

inefficiently—for a file two people share, but what happens when you have six or eight

people on your team? You could conceivably have multiple versions of the same file moving

back and forth through e-mail; how will you know when you are working on the most recent

version

of the file?


SharePoint Workspace 2010 takes all the guesswork out of collaboration by providing

you with an easy-to-use workspace in which you can post files you want to share, hold

discussions, chat in real time, and check files in and out. You can synchronize files with

SharePoint Server 2010, ensuring that your document libraries, InfoPath forms, and other

files are current and up to date. SharePoint enables you to work with your files—and each

other—as you collaborate in real time to complete your shared projects.


118 Part II Hit the Ground Running


And for those times when you want to work with files stored on the server but won’t be able

to maintain your server connection while you work, SharePoint Workspace 2010 works with

SharePoint Server 2010 to enable you to take content offline so that you can do the work

you need to do and upload the files when you reconnect. Taking your content offline is a big

benefit when you’re on the road, because you can ensure you’re working with the most recent

version of the file and integrate your changes automatically when you log back into the

server. In the meantime, you can lock the file so that other users won’t inadvertently make

changes that can be overwritten later.


What Can You Do with SharePoint Workspace 2010?


SharePoint, as the name implies, is all about sharing—sharing files, sharing discussions, sharing

folders and workspaces and contacts. SharePoint Workspace 2010 is the next incarnation

of Microsoft Office Groove, which is available both as part of Office 2010 and as a standalone

product. Because sharing files and information is a flexible process that can take many forms,

you can work with SharePoint Workspace in a number of ways:


n Create a SharePoint workspace to create a personal copy of the server workspace on

your PC and store files you need to work on. If you use SharePoint Server 2010, this

enables

you to take your content offline and synchronize it again later.


n Create a Groove workspace to collaborate with team members (who may or may not

have access to SharePoint Server 2010) so that you can share files, folders, discussions,

and more.


n Create a shared folder in your workspace so that you can give other users or computers

access to the files stored there.


SharePoint Workspace 2010 gives you the space to collaborate with your team easily and

naturally. In your team workspace, you can share documents, have discussions, chat in real

time, set appointments, leave notes for each other, and much more.


Note SharePoint Workspace 2010 is available only in the Microsoft Office 2010 Professional Plus

version. SharePoint Server 2010, which is required for the check-in and check-out features, will be

available in the first half of 2010.


Chapter 9 Collaborate Effectively with SharePoint Workspace 2010 119


Starting Out with SharePoint Workspace 2010


When you first start SharePoint Workspace 2010 from the Windows Start menu, the

Launchbar opens on the left side of the window, along with a pop-up list displaying any

unread

files that have been added to the workspace since you last logged in. (See Figure 9-1.)

The Launchbar lists any workspaces you currently belong to and also enables you to view and

work with your Contacts list.


FIGURE 9-1 SharePoint Workspace also lets you know if your workspaces have any unread files.


To display a workspace, double-click the name of the workspace in the Launchbar. The

workspace

window uses the familiar Ribbon you see in other Office 2010 applications.

(See Figure 9-2.) The default tabs include the File, Home, Workspace, and View tabs.


FIGURE 9-2 The SharePoint Workspace 2010 window gives you what you need to work collaboratively with

your colleagues.


The work area is divided into three areas. On the left side of the work area is the Content

panel, where you can choose the type of content you want to view in the space. The Content

area might show Files, Meetings, Calendar, Discussion, Notepad, Pictures, or other categories,

depending on the features that are used in the workspace.


Tip You can add tools to the Content area by clicking the Workspace tab and clicking Add in the

Tools group.


What About Groove?


If you used Microsoft Office Groove in Office 2007, you are already familiar with the

workspace

concept and know how it can be used to collaborate with team members far and

near. In Office 2010, Groove has been renamed as SharePoint Workspace 2010, so you’ll find

similar functionality with some major improvements.


You can still create Groove workspaces in SharePoint Workspaces 2010 so that you can

collaborate

with team members who don’t have access to SharePoint Server.


And now, with SharePoint Server 2010, which will be available in the first half of 2010, you will

be able to download the files or folders you need so that you can work on files while you’re

offline and then synchronize the file versions when you connect to the server once again.


Step by Step: Adding a Workspace


You can create a SharePoint or Groove workspace easily from the Launchbar.

Here’s how:


1. In the SharePoint Workspace 2010 Launchbar, click New in the Workspace group

of the Home tab.


2. Choose one of the following options:


n SharePoint Workspace, which creates a workspace on your computer

that enables you to download files from the SharePoint Server and work

on them offline


n Groove Workspace, which creates a classic Groove workspace so that

you can save files and work collaboratively with your team


n Shared Folder, which enables you to create a new folder you can share

with others


3. If you selected SharePoint Workspace, enter the server location of the space you

want to copy, as shown here:


4. If you chose Groove Workspace, click Options and make sure 2010 is selected in

the Workspace Version field (as shown here). Click Create.


5. If you chose Shared Folder, enter a name for the new folder and click OK. In the

Select A Folder For Sales Report dialog box, choose whether to create the folder

on your desktop, in another location you specify, or to use an existing folder.

After you make your choice, click OK.


Tip SharePoint workspace synchronizes only your changes, which means the entire file doesn’t

need to be copied each time you sync your files, which saves time and preserves bandwidth.


Setting Workspace Preferences


Backstage view in SharePoint Workspace 2010 provides you with various ways to set the

preferences

for different program features. (See Figure 9-3.) The Info tab enables you to

choose your preferences for the following elements:


n Change Online Connection Settings lets you choose the way the various workspaces

and communication options in your workspaces are synchronized. You can also choose

to pause the workspace or work offline.


n Alert Me To Workspace Changes enables you to customize the way in which your

workspace

alerts you when changes are made to the site. You can set the Alert level,

review roles and permissions, and set download preferences.


n Manage Account Settings makes it easy for you to set account preferences, including

whether you want SharePoint Workspace to launch when Windows starts up, how

you want your online presence to be displayed, and how you want folders to be

synchronized.


n Manage Messages And Contacts displays your message history, including all messages

you’ve sent and received, and it enables you to work with all contacts who have access

to the workspace.


FIGURE 9-3 Use Backstage view to set your workspace preferences.


Accessing Your Files Seamlessly


One of the great new features SharePoint Workspace 2010 offers is transparency. Now when

you use SharePoint Workspace 2010, you can open the files in your SharePoint and Groove

workspaces as easily as you open a file on your desktop.


To move directly to your workspace folders without launching SharePoint Workspace 2010,

click the Windows Start button and click your user name. Locate the Workspaces folder,

as shown in Figure 9-4. Open the Workspaces folder by double-clicking it and then move

directly

to your workspace to find the files you need.


FIGURE 9-4 You can access your workspace files from the folders on your computer.


Simplified Searching


Another natural integration between your SharePoint and Groove workspaces occurs in the

indexed Windows search function on your computer. Now when you search for a word or

phrase by clicking the Windows Start button and typing the phrase in the Search field, the

list of results displays any results found in the files in any of your workspaces. (See Figure 9-5.)


Tip You can synchronize any shared folder on your computer simply by right-clicking the folder

and clicking Shared Folder Synchronization. Choose the Start Synchronizing option from the

menu to begin the process.


Results from a shared folder in SharePoint Workspaces 2010


FIGURE 9-5 The indexed search feature includes results from your SharePoint and Groove workspaces.


Checking Files In and Out


Keeping your files straight is one of the challenges of working with other authors on shared

documents. SharePoint Workspaces 2010 enables you to check files in and out of SharePoint

Server 2010 so that you can ensure that your work isn’t being duplicated—or overwritten—

by others working on the same file.


Note To use the check-in and check-out features, you must have access to SharePoint Server

2010, which will be available in 2010.


You can work with files easily in SharePoint Workspace 2010 by clicking Files in the Content

pane and then selecting the file you want to check out or in. In the Home tab, click Check

Out or Check In. The file is marked so that other users on SharePoint Server will see the

availability

of the file and, if it is checked out, be blocked from accessing it.


When you check the file back in, your changes are synchronized and the file is made

available

to your teammates once again.


Tip You can move back to the original SharePoint Server site by clicking the breadcrumb

trail

in SharePoint Workspace 2010. This gives you instant access to folders, files, libraries, and other

assets

on the server site.


Synchronize Your Data from SharePoint Server to Your

Workspace


If you want to save files or folders to your PC-based workspace so that you can work

on them whenever and wherever you choose, you can download the content from

SharePoint Server 2010. Simply open your SharePoint Server 2010 site, click Site Actions,

and choose the Sync To Computer option. Click OK in the SharePoint Workspace 2010

dialog box to begin the download.


Connecting with Your Team Instantly


The Groove workspace you create in SharePoint Workspaces 2010 enables you to share files,

discuss projects, plan meetings, and much more. With a Groove workspace, you can work

collaboratively without having access to SharePoint Server 2010.


You can display and work with contact information in two different places in your SharePoint

and Groove workspaces. In the Launchbar, you can click Contacts at the bottom of the display

to display all Active, Online, and Offline contacts who have access to the current workspace.

In a workspace, scroll through the Members areas in the bottom left corner of the

window.


You can tell which contacts are currently online by the small presence icon that appears to

the left of the contact’s name. A green icon indicates that the member is online; yellow indicates

that the member is busy; red means the contact is unavailable. If a presence icon is

gray, the contact is not currently online.


When you find a member you want to contact, click the person’s name to display a contact

card. By default, a small contact card appears, as you see in Figure 9-6. You can expand the


contact card to show more information—including department, phone numbers, and other

relevant information such as organization and workspace roles—by clicking the Expand

Contact Card button in the lower right corner.


E-mail

Expand Contact

Card

Presence icon View More Options


FIGURE 9-6 The contact card initially shows a select group of contact options, but you can expand the card

to show more information.


The different option tools in the contact card enable you to send the contact an e-mail message,

begin an instant message session, make a phone call, or set up a meeting. Additionally,

with Office Communicator 2007 R2, you can share video, share your desktop, and send files.


You can also open an instant messaging window by double-clicking the contact’s name in

the Members list. You can send the message to one or many team members and attach files

to the message if you like. (See Figure 9-7.)


FIGURE 9-7 Send an instant message to one of your contacts online in the current workspace.


Note To see the online presence and social contact information of others on your team, you

need to be using Office Communicator 2007 R2.


SharePoint with InfoPath and SharePoint Business

Connectivity Services


SharePoint Server 2010 makes it simple for you to work with the variety of business applications

and services you need on a daily basis—and to do that naturally, online or offline.

Now SharePoint Server 2010 supports InfoPath forms, which means you can add, delete, or

edit data and data records on your forms and trust that they will sync automatically with the

forms and data on the server.


Additionally, users who use SharePoint Business Connectivity Services can count on using

line-of-business data in SharePoint and know that it will synchronize seamlessly with both

their line-of-business system and SharePoint Server.


For both InfoPath and SharePoint Business Connectivity Services, after the data is synchronized,

the information will also be available in SharePoint Workspace 2010.


Using SharePoint Workspace on the Go


SharePoint Workspace 2010 will also be available in a mobile counterpart (sold separately

from Office 2010) after the final release of Office 2010. With SharePoint Workspace Mobile

2010, you will be able to open your workspaces, look through your files and folders, and

review

and modify your files in a special Office screen designed for your smartphone.


After you view, edit, and save your documents, you can easily sync them back to the server

with a single touch on your phone. This process makes it easy for you to work with your

workspace files anywhere and anytime you need them.


129


Chapter 10


Create Effective Marketing Materials

with Publisher 2010


In this chapter:


n Starting Out with Publisher 2010


n Creating and Using Templates and Building Blocks


n Creating Precise Layouts


n Enhancing Typography with OpenType Features


n Working with the Improved Color Palette


n Previewing and Printing Publications


n Preparing for Commercial Printing


n Sharing Publisher Files


How do you create your marketing materials today? If you are spending a big portion of your

budget outsourcing four-color postcards, brochures, newsletters, and more, you can do the

job closer to home with Publisher 2010 and save money, time, and effort. What’s more, you

can create and save reusable content—called building blocks—that you can insert in future

materials, which helps you ensure that your messaging stays consistent no matter what kinds

of materials you create.


Improvements in Publisher 2010 make it easier than ever to create new files using both

built-

in and community-submitted templates. New layout tools help you align objects, place

captions, and position elements on the page in accurate and aesthetically pleasing ways. You

can also spruce up your photos with artistic effects, improved editing tools, and support for

OpenType features such as ligatures and stylistic sets.


Starting Out with Publisher 2010


The Microsoft Publisher 2010 window gives you plenty of room to work on screen, while

keeping the tools you need within reach. (See Figure 10-1.) The Ribbon includes seven tabs—

File, Home, Insert, Page Design, Mailings, Review, and View—and each tab contains groups

of tools related to the tab topic. On the Insert tab, for example, you’ll find Picture in the

Illustrations group, enabling you to add pictures to the current page with just a few clicks of

the mouse.


130 Part II Hit the Ground Running


Page Navigation Pane

Ribbon Work area

Scratch area View controls


FIGURE 10-1 The Publisher 2010 window includes the Ribbon and the Page Navigation pane.


The Publisher window also includes a scratch area surrounding the entire publication. The

scratch area enables you to place objects partially off the page so that you can create bleeds

(photos, backgrounds, or other graphical elements that print all the way to the edge of the

page). In Publisher 2010, you can choose to hide or display the scratch area so that you can

see the overall design, including bleeds, as well as the page as it will appear when printed.


Collapse and Expand Page Navigation Pane


The Page Navigation pane along the left side of the window displays thumbnails of the pages

in the current document, which enables you to get a sense of the document flow and overall

layout at a glance. You can use the Page Navigation pane to scroll through the different

pages in your document, checking text flow, placement of illustrations, format of headings,

and other parts of the design.


Chapter 10 Create Effective Marketing Materials with Publisher 2010 131


If you want to increase the amount of space available for the current page, you can collapse

the Page Navigation pane, which reduces the size of the displayed thumbnails. To expand the

pane, simply click the Expand button at its upper-right corner.


Use the Mini Toolbar


Now Publisher 2010 also includes the Mini Toolbar, a set of text-formatting tools that appears

when you select text in your document. When the Mini Toolbar first appears, it is transparent;

when you point to the toolbar it becomes solid, as Figure 10-2 shows. If you move the mouse

pointer away from the toolbar, it disappears altogether. In this way, the tools are within reach

if you need them, but they fade away if you don’t.


FIGURE 10-2 The Mini Toolbar displays formatting tools when you select text.


Tip If the Mini Toolbar doesn’t appear automatically when you select text in your document,

you can turn the feature on by clicking File and choosing Options. On the General tab, click the

Enable The Mini Toolbar option.


Creating and Using Templates and Building Blocks


Publisher 2010 offers dozens of built-in templates you can use to create letters, newsletters,

brochures, business cards, calendars, labels, and much more. When you choose to create a

new publication based on a template, you can use one of the templates installed with the

software or access templates available online in the Publisher community. (See Figure 10-3.)


In addition to using templates to start your publication, you can add predesigned elements

to your pages by choosing from a gallery of page parts, known as building blocks. Building

blocks are available in the Page Parts tool in the Building Blocks group of the Insert tab.

(See Figure 10-4.)


FIGURE 10-3 You can choose to begin a new publication based on an installed or online template or create

your own design on a blank page.


Tip A building block is a part of a page that you might want to use regularly in your publications.


By default, Publisher includes headings, pull quotes, sidebars, and stories in the Page Parts

gallery of the Building Blocks group on the Insert tab. You can insert the building blocks as

they are and then customize them to fit your publication, or you can create your own Page

Part and then save it as a building block. Either way, the building blocks feature can save

you time and effort and help you provide a consistent look and feel among the various

publications

you create.


FIGURE 10-4 Page Parts can save you time and add a professional touch to your page design.


Step by Step: Creating a Building Block


Here’s how to create a new building block in Publisher 2010:


1. Open the Publisher document you want to use.


2. Create and select the element you want to save as a building block. Hint: You

might want to save a page heading, report title, pull quote, table, or other

often-

used element.


3. Right-click the element you selected and choose Save As Building Block.


4. In the Create New Building Block dialog box, shown here, enter a title and

description.


5. Click the Category arrow, and choose the category that best applies to the type

of element you’ve created.


6. Click OK to save the building block.


Creating Precise Layouts


Publisher 2010 also includes dynamic layout guides to help you position elements precisely

on the page. Guides appear automatically as you drag an object—text, picture, or shape—on

the page. Turn on the display of guides by clicking Guides in the Show group of the View tab.


Vertical and horizontal guides help you ensure you’re positioning elements so that they

align with other objects on the page. Guides appear and disappear as you drag the object

so that they take up space on-screen only in the areas where you need to use them.

(See Figure 10-5.)


Horizontal

guide

Center

guide


FIGURE 10-5 Publisher 2010 provides dynamic guides that help you place objects on the page.


Enhancing Typography with OpenType Features


Both Publisher 2010 and Word 2010 are now able to make use of OpenType features such

as ligatures and stylistic sets in the fonts that offer them. Ligatures are a combination of two

letters

shown typographically as a single character in some fonts. For example, the letters


fi in some typefaces are placed close together and shown as a single character. This type of

text control is used most often in high-quality typography work.


Similarly, stylistic sets offer a variety of appearances in the selected font. The Typography

tools are found on the Text Box Tools Format tab, which appears when a text box is selected

in your Publisher document. Figure 10-6 shows some of the stylistic sets available for the

Gabriola font.


FIGURE 10-6 Publisher 2010 enables you to take advantage of professional typography features available

with some OpenType fonts.


In addition to ligatures and stylistic sets, Publisher 2010 also supports number styles,

stylistic

alternates, and swash features. Figure 10-7 shows the primary Typography tools, and

Table 10-1 provides a description of each one.


FIGURE 10-7 Publisher 2010 offers different OpenType features you can apply to fonts that support them.


TABLE 10-1 Typography features in Publisher 2010


Tool


Description


Ligatures


Enables you to choose whether to use ligatures in the document (and,

if so, what kind)


Number Style


Sets the appearance of numerals in the selected font in the current

document


Stylistic Alternates


Offers alternate characters you can use in the text in your document


Stylistic Sets


Displays a gallery so that you can choose the format style of the

selected

font


Swash


Works as a toggle, and turns on or off decorative text elements


Tip Publisher 2010 also includes Paste with Live Preview, which enables you to preview the way

an object will look before you paste it in your Publisher document.


Working with the Improved Color Palette


Publisher 2010 updated its color palette to include elements that help you keep a consistent

look and feel throughout the materials you create. Now you can stay true to the color

scheme you selected and apply a variety of tints, shades, and gradients to the text and

shapes on your pages. You’ll find the new palette on all border and fill tools—for example,

Figure 10-8 shows the color palette that appears when you click the Shape Fill tool in the

Shape Styles group of the Drawing Tools Format tab.


FIGURE 10-8 The improved color palette now displays color scheme selections and expanded color choices.


Previewing and Printing Publications


The Print feature in Publisher 2010 now enables you to preview, adjust, and print all in the

same screen in Backstage view. (See Figure 10-9.) When you click the File tab and click Print,

you see the current page of your open publication, complete with the page margins, headers

and footers, and more. You can easily choose the print options you need—for example, select

the printer you want to use, choose the print layout and paper style, and select whether

you want to print as an RGB color publication or a composite black and white.


FIGURE 10-9 The Preview And Print interface in Publisher 2010 enables you to make last-minute changes and

print, all from the same screen.


Have you ever printed a double-sided report only to find out that the image on the back of

the page made the text on the front hard to read? Publisher 2010 includes a backlight feature

that enables you to see through the page on double-sided publications so that you can

avoid that kind of situation in the future. When you choose two-sided printing in the print

options, the Decrease Transparent View and Increase Transparent View tools appear at the

upper-

right corner of the preview window. (See Figure 10-10.) To change the transparency

and display the back of the page while you’re looking at the front, drag the Transparency

slider to the right. You can also turn the page and view the transparency from another

perspective

using the Front and Back tools at the bottom of the preview area.


FIGURE 10-10 The Transparency tools become available when you choose two-sided printing.


Tip Before you finalize your design, be sure to run the Design Checker to identify and correct

design problems in the publication. You’ll find the Design Checker on the Info tab of Backstage

view.


Preparing for Commercial Printing


Publisher 2010 includes expanded support for the four-color process and spot color printing,

including CMYK composite postscript and Pantone colors (both PMS and the new Pantone

GOE color system). You’ll find the tools you need to prepare a file for commercial printing by

clicking the File tab to display Backstage view. Click Info, and click Commercial Print Settings.


Commercial Print Settings enables you to choose the color model you want to use, work

with the embedded fonts in your publication, and manage the registration of the document.

(See Figure 10-11.) When you’re ready to finalize the file, click File and in Backstage view, click

Share and choose Save For A Commercial Printer.


FIGURE 10-11 Commercial Print Settings enable you to prepare your publication for professional printing.


Sharing Publisher Files


You can share the files you create in Publisher 2010 in various ways. You can e-mail pages

from within Publisher, create a PDF/XPS document, publish the document as HTML, save the

piece for a commercial printer, or save the publication for another computer. You’ll find these

options in the Share tab of Backstage view.


Tip Before you send your Publisher document by e-mail, you can preview it by clicking File

to display Backstage view and choosing Share. Click E-mail Preview to display a version of the

document

as it will appear to the recipient.


141


Chapter 11


Make Sense of Your Data with

Access 2010


In this chapter:


n Starting Out with Access 2010


n Using Application Parts


n Applying Office Themes


n Adding New Fields


n Showing Data Bars and Conditional Formatting


n Creating Navigation Forms


n Designing Access 2010 Macros


n Working with Access 2010 and the Web


Whether you work daily with large, sophisticated databases or occasionally create small

data tables to meet a specific need, Microsoft Access 2010 enables you to gather, organize,

analyze, report on, and share your data easily and effectively. New and improved features

in Access 2010 simplify the steps to creating a database by enabling you to add application

parts that include ready-made tables and forms. You can also use Quick Start fields to insert

commonly used fields and add calculated fields to build data analysis directly into your data

tables.


On top of the simplified tasks involved in creating and analyzing your data, Access 2010

includes

new data visualizations—including new data bars and improved conditional formatting—

that can tell the story of your data at a glance. You’ll also find plenty of Web support in

Access 2010. With little effort, you can create a Web database and publish your data online

so that it’s always available at any point you have Web access.


Starting Out with Access 2010


The first thing you’ll notice as you begin to work with Access 2010 is that the application has

the friendly and familiar Office interface that is common to other Office applications you

might use. The Ribbon includes five tabs—File, Home, Create, External Data, and Database

Tools—that offer sets of tools organized according to the data tasks you’ll be performing.


142 Part II Hit the Ground Running


In addition to these five tabs, Access 2010 displays the Table Tools contextual tabs (Fields and

Table) when you work with a data table. (See Figure 11-1.)


Record navigation

Ribbon Contextual tabs

Database search View controls


FIGURE 11-1 The Access window is designed to make it easy for you to work with the data objects and views

you need.


Below the Ribbon, the Access window is divided into two main windows. The All Access

Objects pane on the left side of the screen lists the various elements—tables, reports, forms,

and more—in your current database. To open an object, you double-click it in the All Access

Objects pane; the item then opens in the work area on the right side of the window. You can

have many open objects in Access at one time, and you can change the current display by

clicking the tab of the object you want to see.


Tip You can change the elements displayed in the left pane by clicking the arrow to the right of

the pane heading. You can choose to display objects by category or by group. Click the option

you want to display and the pane changes accordingly.


Chapter 11 Make Sense of Your Data with Access 2010 143


Along the bottom of the Access window you find controls that enable you to move through

records in the current data table, search for information in the database, or choose the view

you want to use to work with your data.


In addition to the flexible, easy-to-navigate user interface, Access 2010 offers behind-thescenes

features that help you manage your data files. Backstage view pulls together all

the tools you need to create, share, and set preferences for the various files you create.

(See Figure 11-2.)


FIGURE 11-2 Use Backstage view to work with the files you create in Access 2010.


Using Application Parts


Designing every database you create from scratch takes a lot of time and effort, and now

with Access 2010 there’s no need to reinvent the wheel every time you create a new data

table. Using the application parts in Access 2010, you can add ready-made forms and tables

to your Access database. By default, Access 2010 includes a number of blank, predesigned

forms as well as Quick Start tables (Comments, Contacts, Issues, Tasks, and Users) you can

add to your database.


Step by Step: Adding an Application Part


Follow these steps to add an application part to your Access database:


1. Open the database you want to use.


2. Click the Create tab.


3. Click Application Parts. The gallery appears, as shown here:


4. Click the application part you want to add to your database, and the form or

table you selected is inserted in the All Access Objects pane on the left side of the

work area.


Tip You can easily search for Access templates to use as the basis for a new database from

Backstage view. Click File to display Backstage view and then click New. Click in the Office.com

Templates box, and type a word or phrase indicating the type of template you’d like to find.


Applying Office Themes


Now you can apply the professionally designed Office themes—which include color scheme,

font selections, and styles—to your forms and reports in Access 2010. (See Figure 11-3.) This

level of consistency enables you to create a similar design for all the documents you create


in Office 2010. For example, suppose you’re putting together a lengthy sales report that

spotlights key products, provides sales data by region, and includes case studies showing

the ways in which your products are being used by your customers. Using the same Office

theme, you can prepare the case studies in Word 2010, the financial data in Excel 2010, and

the sales reports by region in Access 2010.


FIGURE 11-3 Office themes in Access 2010.


Step by Step: Applying an Office Theme


Here’s how to apply an Office theme in Access 2010:


1. Open the database you want to use in Access.


2. Open the form or report to which you want to apply the theme.


3. Click the Home tab.


4. Click Views, and choose either Design View or Layout View.


5. In the contextual Design tab, click Themes in the Themes group.


6. Preview a theme by pointing to it; the report or form display shows you how the

theme will look when it is applied to your data.


7. Click the theme you want to use, and it is applied to the form or report.


Adding New Fields


New field features in Access 2010 enable you to reduce the amount of time you spend setting

common fields in your databases by using Quick Start fields, and they help you expand

your data processing power by adding calculated fields to your tables.


Adding Quick Start Fields


New Quick Start fields in Access 2010 enable you to add fields you use regularly to your

data tables with a simple click of the mouse. Instead of adding Address, City, State, ZIP, and

Country codes one by one, for example, you can click the Address Quick Start field to add

all the fields in one click. Access 2010 includes nine Quick Start fields by default: Address,

Category, Name, Payment Type, Phone, Priority, Start And End Dates, Status, and Tag.


To add a Quick Start field to your data table, open the data table you want to use and click

to select the field to the right of the place you want to add the field. In the Table Tools Fields

tab, click More Fields in the Add & Delete group. Scroll down to the bottom of the list to find

the Quick Start fields, and click the one you want to add to the data table. (See Figure 11-4.)


FIGURE 11-4 Find the Quick Start fields in the More Fields list.


Each Quick Start field you add has preset field options already included. For example, when

you add the Payment Type Quick Start field, the added field includes Cash, Credit Card,

Check, In Kind, and Debit selections as part of the field. You can customize the field to include

the selections you want by right-clicking the field and choosing Edit List Items. In the

Edit List Items dialog box (shown in Figure 11-5), you can modify, remove, or add values to

the list by clicking and typing the new entry. Click OK to save your changes.


Tip What should you try first in Access 2010? Jeff Conrad, author of Microsoft Access 2010 Inside

Out (Microsoft Press, 2010), recommends these three things:


n Publish and share your database to Access Services, and view your forms and reports in a

Web browser.


n Try the new navigation form to see how simple it makes creating a navigation system.


n Attach data macros to table events, and create named data macros to incorporate more

business logic in your data tables.


FIGURE 11-5 You can easily edit the list items included in a Quick Start field.


Inserting Calculated Fields


Another new field feature in Access 2010 enables you to easily create and store calculations

that enable you to analyze your data. You can then apply the calculated field throughout

your database as needed. To add a calculated field to your data table, click More Fields in the

Add & Delete group of the Table Tools Fields tab. Then choose the field type for the type of

calculated field you want to create, and Access 2010 displays the Expression Builder dialog

box so that you can choose the elements, categories, and values to use in the calculation.

(See Figure 11-6.)


FIGURE 11-6 Add calculated fields to your data table.


Tip You can change the expression you’ve used to create a calculated field by right-clicking the

field label in the data table and choosing Modify Expression. In the Expression Builder dialog

box, modify the calculation as needed and click OK.


Showing Data Bars and Conditional Formatting


Not everyone can look at a table full of data and know instantly what it means. Some of

us need a little help interpreting facts and figures in a table or on a report. For this reason,

Access 2010 includes data visualization features that enable you to include data visualizations

in your tables and reports that will help your readers understand what your data means.


Data bar visualizations are helpful when you want to compare data among the records

in your report. For example, if you want to compare the projected workshop with the

actual

attendance

data, you can let data bars show you where your marketing efforts were

successful

and where they fell short. (See Figure 11-7.)


FIGURE 11-7 Data bars work with numeric fields, enabling you to visually contrast the data you’re reporting.


Tip Conditional formatting is easier in Access 2010, thanks to the addition of the Conditional

Formatting Rules Manager. Now you can create new rules that specify conditions for the

conditional

formats and preview the effects of your changes before you apply them.


Creating Navigation Forms


When you’re working with forms and reports in Access 2010, you can simply drag fields to

where you want them to create just the type of layout you want. Access 2010 also includes a

new Navigation Forms gallery, with a number of layouts you can customize to make it easy

for others to find the forms and reports they want to view in your database.


To create a navigation form, click the Create tab and choose Navigation in the Forms group.

(See Figure 11-8.) Click the navigation form layout you want to use, and then drag the reports

and forms you want to include from the All Access Objects pane to the navigation area

of the new form. Those reviewing your information will be able to click the name of the form

or report to display the data in the Access 2010 window.


FIGURE 11-8 Use the Navigation gallery to choose the layout of the navigation form you want to create.


Designing Access 2010 Macros


Although the word macros might make your eyes glaze over if you’re not interested in

automating

the data logic and processing in your database, two improvements in Access

2010 offer good news to macro aficionados. First, new data macros enable you to add data

logic to the actual table of data rather than requiring you to work at a form level. And the

enhanced Macro Designer is now more intuitive than ever, providing a look and feel that

enables you to build macros easily by dragging items where you want them to appear and

arranging them in the proper sequence. (See Figure 11-9.)


FIGURE 11-9 The improved Macro Designer in Access 2010 makes it easy for you to build macros by selecting

and dragging the items you need to the location you choose.


Working with Access 2010 and the Web


One of the major stories in Office 2010 is the ability to access your files—documents,

presentations,

worksheets, notebooks, and databases—anywhere you have access to

the Web. Access 2010 enables you to create a Web database so that you can use it with

SharePoint Server 2010 to publish your entire database—including tables, forms, and

reports—

and view it in a browser window.


Create a Web database by starting in Backstage view. Simply click File, choose New, click

Blank Web Database, and click Create. You can then create the database as usual, adding

data tables, forms, and reports. When you are ready to publish your database to the Web,

return to Backstage view by clicking File and then click Share. Choose Publish To Access

Services, and type the necessary information for the SharePoint site that will post the file.


Tip Before you post your database to the Web, be sure to run the Compatibility Checker to look

for any data items or settings that won’t function properly online. The Compatibility Checker is

found in the Share page of Backstage view.


Adding Web Controls


Another great Web feature included in Access 2010 makes it possible for you to incorporate

Web content in the database you are creating. This might enable you, for example, to

provide

live access to Web 2.0 content from within your database.


Display the form on which you want to add the Web Browser control, and then, in the Home

tab, click View and then Layout View or Design View in the Views group. In the Controls

group, choose Web Browser, and then click and drag at the point you want the control to

appear. When you release the mouse button, the Insert Hyperlink dialog box appears so that

you can enter the Web page or choose the item you want to include in the Web Browser

control. After the element is added, you can resize the object as needed in the Access

window

by simply dragging the corner or side of the object. (See Figure 11-10.)


Tip Now it is easier to add databases to your Trusted Documents list. When you open a

database

created by someone else, a Message Bar appears at the top of the Access 2010 window.

Macros are automatically disabled until you indicate that the database is a Trusted Document. To

enable the full functionality of the database, click Enable Content.


FIGURE 11-10 Incorporate Web content in your database using the Web Browser control in Access 2010.


Using Access 2010 with SharePoint


If you work with SharePoint Server 2010, additional Web features are also available to you in

Access 2010. First, you can take a Web database into offline mode so that you can continue

to work on the data as needed; the next time you connect to the Web, any changes you

made to the offline data are automatically synchronized with the database on the server. You

can also synchronize your data manually by clicking File to display Backstage view, and in the

Info page, clicking Sync All.


You also have the ability to save your database to SharePoint Workspaces 2010 so that you

can access your data using your Web browser or smartphone.


Gathering Data with InfoPath 2010


Microsoft InfoPath is a forms-creation and data-gathering tool included with Office

2010 that helps you collect and consolidate the data you need and then share that data

with colleagues in a variety of ways. (See Figure 11-11.)


FIGURE 11-11 InfoPath offers a collection of templates you can use as the basis for your forms, or

you can begin with a blank form and create your own.


InfoPath includes a variety of form templates you can use as the basis of the new forms

you create, or you can choose to start with a blank form and add the fields yourself.

InfoPath 2010 enables you to create professional forms by dragging fields where you

want them to be and arranging them in a way that makes sense for your data. You can

also add pictures and buttons to your forms, guarantee accuracy by running the Spell

Checker, include ScreenTips to prompt people filling out your forms, and share forms

easily using SharePoint Server 2010 and SharePoint Workspace 2010. Also, thanks to

integration with SharePoint Workspace 2010, users can complete the forms you create

online or offline.


InfoPath Filler makes it easy for users to open and complete the forms you create. You

set up the way you want users to submit completed forms by choosing to receive the

form by e-mail, have the data sent to a SharePoint library or SharePoint server, or use

Web services to gather the information. You can also include your InfoPath 2010 forms

in Outlook 2010 messages, which makes it possible for you to collect information by

e-mail and store it in the database or SharePoint library you specify.


First Look: Microsoft Office 2010


155


Part III


Next Steps with Office 2010


Now that you have explored the new features in each of the core Office 2010 applications,

this part of the book helps you answer the question, “What next?” Because Office 2010 is an

integrated suite of applications, you can use the programs together gracefully to get more

out of the files you create and share. This part also spotlights the security measures you’ll

find in Office 2010 and introduces various ways you can learn more about the programs and

increase

your own proficiency.


You’ll find the following chapters in this closing part of First Look: Microsoft Office 2010:


n Chapter 12: Putting It All Together


n Chapter 13: Security in Office 2010


n Chapter 14: Training Made Easy


157


Chapter 12


Putting It All Together


In this chapter:


n Using Excel 2010 Data with Word 2010


n Sharing SmartArt Among Office 2010 Applications


n Dragging Word 2010 Content to PowerPoint 2010


n Mail Merging Word 2010 Documents in Outlook 2010


n Sharing Access 2010 Data with Other Office Applications


n Scheduling a Meeting from a Shared Document


One of the great benefits of working with the Office 2010 suite is that no matter which

applications

you use most often, they all have a similar look and feel. This means that even

if you use PowerPoint 2010 only when you need to make a presentation to the board, or

you use Publisher 2010 only when you need to create business cards, you can find your way

around the programs easily using the familiar Ribbon and Backstage view.


Office 2010 enables you to share your work among applications—and among colleagues—

more easily than ever before. A number of integrated features make it simple to use what

you create in one application seamlessly in another. That saves you time and effort, and it

guarantees consistency throughout your creations no matter what kinds of final files you

create

and share. The examples in this chapter provide just a few of the ways you can share

your data among applications—take the time to discover how you can share what you create

in an application to get more from your work in Office 2010.


Using Excel 2010 Data with Word 2010


Once upon a time, to include worksheet data in your documents, you needed to create a

table and enter the values by hand. We’ve come a long way since those early days, thankfully,

and Paste with Live Preview makes it easy not only for you to copy and paste (or drag) your

worksheet information into your document, but to paste it just the way you want it—with or

without formatting. (See Figure 12-1.)


158 Part III Next Steps with Office 2010


FIGURE 12-1 Choose the way you want data to be pasted in your document.


The paste options provide you with a variety of choices that control the way the information

is inserted into the document. Table 12-1 explains the various paste options shown in

Figure 12-1.


TABLE 12-1 Paste options


Tool Name


Description


Keep Source Formatting


Pastes the copied information using the same formatting options

that were applied in the source document


Use Destination Styles


Pastes the new information into the document using the styles

existing in the receiving document


Link & Keep Source

Formatting


Preserves the formatting of the original document, but links the

data to the original file so that changes will be reflected in the

pasted information if you update the source document


Link & Use Destination

Styles


Uses the style formatting in the receiving document by

maintaining

a link to the original file so that the data is updated

if you change the original document


Picture


Pastes the information as a picture object in the document


Keep Text Only


Pastes the data as text only, with no applied formatting


Chapter 12 Putting It All Together 159


Tip In the Paste Options list, you can click Set Default Paste to display the Advanced options and

specify the default pasting styles you want to use in the current application.


Sharing SmartArt Among Office 2010 Applications


SmartArt in Office 2010 has been enhanced to provide new support for pictures as well as

additional layouts for you to use in the different Office applications. More good news is

that you can create a SmartArt diagram once—in, for example, Word 2010—and use the

same diagram in Excel, PowerPoint, Outlook, OneNote, and even Access. Figure 12-2 shows

a drag operation where a SmartArt diagram is dragged from Word 2010 to an Excel 2010

worksheet.


FIGURE 12-2 Drag SmartArt from Word to Excel.


Tip You can also save a SmartArt diagram as a picture in one of four formats (PNG, GIF, TIFF, or

WMP) so that you can easily post it in Web content, import it into a layout program, or use it in

any other application that works with standard graphics files. Note, however, that the picture file

you save will not have the interactive diagramming features that are available when you work

with the SmartArt diagram in your Office 2010 applications.


Dragging Word 2010 Content to PowerPoint 2010


Depending on your creative style, you might be more comfortable drafting your ideas in

Word and then porting them into PowerPoint. You can easily create your outline, paragraphs,

or bulleted lists in a Word document and then drag it into PowerPoint. (See Figure 12-3.)

Again, Paste with Live Preview comes into play.


After you place the content in PowerPoint 2010, you might still have some basic formatting

to do to fit the right content on the right pages, but the process is much faster than

retyping the information you need. You can also drag notes from Word into the Notes area

of your PowerPoint slides and then print the notes pages (with text and slide images) from

within PowerPoint 2010.


FIGURE 12-3 Drag an outline from Word to PowerPoint.


Mail Merging Word 2010 Documents in Outlook 2010


Suppose that you want to send a new e-mail catalog list to all your customers. Rather than

beginning in Word 2010, drafting your document, and then connecting a contact list you

exported from Outlook 2010 and saved in Excel 2010, you can do the whole process in two

simple steps:


1. Create the document you want to send in Word 2010.


2. Mail merge the document with your Outlook contacts and send it via e-mail.


Nice, right? The new mail merge feature in Outlook 2010 enables you to easily create mail

merge projects you can use to send form letters, mailing labels, envelopes, and catalogs.

(See Figure 12-4.) To find the Outlook Mail Merge feature, click Contacts at the bottom of the

navigation pane on the left side of the Outlook 2010 window and then click Mail Merge in

the Actions group of the Home tab. The Mail Merge Contacts dialog box opens, offering you

a collection of options you can use to set up your merge.


FIGURE 12-4 Use the Outlook Mail Merge feature to simplify mail merge projects.


In the Document File area of the Mail Merge Contacts dialog box, you can create a new

document or choose Existing Document and click Browse to navigate to the document you

created in Word. Click Open to add the file to the Mail Merge Contacts dialog box, and, after

adding the contact data file, click OK to start the merge.


Sharing Access 2010 Data with Other Applications


Although the features that enable you to use Access data with other Office 2010 applications

aren’t new in this latest release, the program makes it easy for you to share your Access

data with files and messages you create in Excel 2010, Word 2010, Outlook 2010, and even

OneNote 2010. You’ll find the tools you need in the External Data tab of the Access 2010

window. (See Figure 12-5.)


Use as data

source for Word

mail merge

Export

as

e-mail

Save as

text file Export to an Access database

Create a

PDF file

Create

an XML

data

file

Save

as

Excel

workbook


FIGURE 12-5 Share Access 2010 data with Excel, Word, Outlook, and OneNote 2010.


You can easily use portions of your Access data in other applications as well. Suppose that

you’re reviewing your customer database and you see that several customers haven’t been

contacted in more than a year. You can make a note to yourself in your OneNote notebook

to follow up with those customers by simply dragging the highlighted names and e-mail

addresses to your To Do notebook. Or you can create a task in Outlook and assign the follow-

up calls to someone else on your team. By simply dragging the content, or cutting and

pasting it (using Paste with Live Preview), you can share the data in ways that enable you to

follow through on action items that might otherwise slip your mind.


Scheduling a Meeting from a Shared Document


And of course one of the biggest stories in Office 2010 is the ability you now have to share

your files, in real time, from within core applications. For example, if you co-author a Word

document and notice that one of your co-authors is working on the document while you’re

editing it, you can send her a quick instant message to ask a question about the file.


To contact co-authors while you work on a document, click the File tab and then click Info in

Backstage view. In the Author area on the right side of the view, double-click the name of the

co-author you want to contact. The contact card appears, listing various ways you can reach

the co-author. (See Figure 12-6.)


FIGURE 12-6 Contacting a co-author from within a shared document is a great new feature in Office 2010

applications.


When you click Schedule A Meeting, an Outlook appointment window appears so that you

can schedule the time and the format for the meeting. You can set up a Live Meeting, schedule

a conference call, or invite your co-author to a face-to-face meeting at a location you

specify. (See Figure 12-7.)


FIGURE 12-7 Schedule a meeting on a shared document.


Meeting scheduling is of course just one aspect of the various ways you can communicate

with co-authors who share your documents. You also can send an instant message to anyone

on your team whose presence shows them to be available; you can launch a video call or

voice-over-Internet call (if your communications client allows this). And, when instant contact

isn’t an option, you can always send an e-mail message.


165


Chapter 13


Security in Office 2010


In this chapter:


n Understanding Security in Office 2010


n Opening Files Safely


n Working with Protected View


n Password Protecting a File


n Limiting File Changes


n Setting Role-Based Permissions


n Recovering Unsaved Versions


n Working with the Trust Center


How many attached files do you receive via e-mail every day? How often do you open

documents

sent to you by people you don’t know? How many times in a week do you

forward

files along to coworkers for review or correction? Do you regularly trade files with

others both inside and outside your organization?


This chapter introduces you to the security features in Office 2010. Today it’s more important

than ever to ensure that the files you send and receive are secure, and for this reason, Office

2010 includes new security features that add layers of protection to the files you create and

share. Although much of the file checking that goes on is an invisible part of the process, you

can control many levels of protection in Office 2010 applications, specifying who you want to

have access to your files and what kinds of actions they can perform.


Understanding Security in Office 2010


Security in Office 2010 is focused on safeguarding your files, and Microsoft has accomplished

that by making Office 2010 more resilient to attack. Office 2010 has a new security workflow

with multiple layers that Office documents go through during the File Open process. This

whole security effort is designed to be invisible to you as a user, so you won’t notice any

delays

or dialog boxes when you open files you need to use.


166 Part III Next Steps with Office 2010


Opening Files Safely


One of the vulnerabilities in previous versions of Office occurred in the file-opening process

when a user went to open a file from a previous version of an Office application. Because

hackers

often design malicious files that masquerade as previous file types, this left user files

unprotected when users worked with legacy formats.


The first line of Office 2010 defense includes a new Open File Validation process that checks

to ensure files from previous versions of Office match the required format before the files will

open. This process occurs behind the scenes, but you can open files confidently knowing that

if the files open, they’ve already passed the Office validation check. If the system finds anything

that poses a risk—perhaps an unrecognized file format—the system prompts you with

a Protected View message at the top of the document window. (See Figure 13-1.)


FIGURE 13-1 Protected View lets you know that the file is potentially unsafe.


The Open File Validation process now checks every file to validate the legitimacy of the file

type before the file will open in your Word, Excel, or PowerPoint window. This process is

transparent to you—you won’t experience any delays in opening files or have to interact with

any dialog boxes in the process.


Chapter 13 Security in Office 2010 167


If you choose, however, you can specify how you want the various applications to handle the

files as they go through the Open File Validation process. You can display the File Blocking

settings by clicking the Click For More Details link in the Message Bar when Protected View

displays a message, or you can follow these steps to open the Trust Center and display the

File Blocking settings in your current application:


1. Click the File tab.


2. In Backstage view, click Options.


3. In the Options dialog box, click the Trust Center category.


4. Click the Trust Center Settings button.


5. In the Trust Center, click the File Block Settings category. The File Block Settings window

appears, as shown in Figure 13-2.


FIGURE 13-2 You can tailor the way applications open files from different formats.


By default, the file types with no check marks are opened in the application; they are not

blocked or displayed in Protected view. The action selected in the Open Behavior For

Selected File Types list that appears below the file types shows you what action is taken if a

file type is selected. Table 13-1 explains a little more about each of these behaviors.


TABLE 13-1 File block behaviors


Setting


Description


Do Not Open Selected File Types


The selected files are blocked and will not be

opened.


Open Selected File Types In Protected View


The selected file is opened in a safe mode that is

protected from other files and processes.


Open Selected File Types In Protected View

And Allow Editing


The selected file type is opened in safe mode, but

the user is allowed to edit as normal.


Working with Protected View


When you see the Protected View message in your application window, the file you tried

to open has either been blocked or has been determined to be in a file format flagged for

blocking. If you still want to see what’s in the file or find out if it is from a source you trust,

you can open the file in Protected View.


Protected View is a safe mode that enables you to display a read-only view of the document.

The file is opened in a protected space called a sandbox, where the file cannot affect your

other files or system data. After you determine that the file is acceptable, you can click Enable

Editing to open the file normally.


You also can change the way Protected View is used when questionable files are opened. The

settings for Protected View are available in the Protected View category in the Trust Center.

(See Figure 13-3.)


FIGURE 13-3 You can change the Protected View settings used to protect your computer.


Password Protecting a File


Although you’ve been able to add passwords to your Word, Excel, and PowerPoint files for a

while, in Office 2010 the password encryption rules have been changed to account for password

strength as well. You set an encrypted password for your file using Backstage view, as

you see in Figure 13-4.


Tip You can also set the password during the Save As process by clicking the Tools button,

choosing General Options, and typing the password required to open the file. If you plan to

share the file with others, you can type a separate password that you share with co-authors to

enable modification and file sharing.


FIGURE 13-4 You can set an encrypted password for your document.


Note that when you set an encrypted password for your Word, Excel, or PowerPoint file, the

password cannot be recovered if you forget the password later. For this reason, you should

keep a copy of your passwords in a safe place you can access easily.


Limiting File Changes


In addition to ensuring the files you open and work with are trustworthy, you also need to be

able to set parameters for the types of modifications that can be made to the file by others

who work with the file as well. Each of the Office 2010 applications includes protection features

that enable you to set safeguards at the file level. You’ll find all the protection features

in Backstage view, in the Info category.


Excel 2010 enables you to set several levels of protection for the current worksheet. In the

Info category of Backstage view, you can choose one of the following options to limit the

changes that can be made to the file:


n Protect Current Sheet displays the Protect Sheet dialog box, which enables you

to create

a password other users must enter in order to modify the worksheet.

Additionally, you can choose the actions you want to allow users to complete, such as

format cells, insert columns, and delete rows. (See Figure 13-5.)


n Protect Workbook Structure lets you safeguard the structure of the workbook—or the

Excel window—by prohibiting others from adding new worksheets, for example.


FIGURE 13-5 Excel 2010 enables you to limit the changes you want other users to make in the file.


Word 2010 offers several levels of restrictions that enable you to set the level of changes that

can be made in a specific document. (See Figure 13-6.) These features, which were also part

of Word 2007, allow you to limit others’ changes in the following ways:


n Formatting restrictions limit users to changing styles used in the document.


n Editing restrictions enable you to specify whether you want users to view the file as

read-only, or whether you will allow them to enter tracked changes, enter comments,

or complete forms.


In addition to these two main restrictions, Word 2010 enables you to choose the parts of the

document and indicate which users have the necessary permissions to edit those parts.


FIGURE 13-6 Word 2010 file protection enables you to block or restrict editing by type of task or by person.


PowerPoint enables you to restrict others’ ability to copy, edit, or print content in

your PowerPoint presentation. You can also mark a file as final so that others can view—but

not modify—the file.


Tip Word, Excel, and PowerPoint all give you the option of adding a digital signature to your

document to verify a document’s integrity. The digital signature feature in each of these applications

requires a signature service from a third-party vendor. You can begin the process by clicking

the Add A Digital Signature option in the Protect selection of the Info tab, and a prompt will

offer you the option of finding a signature service online.


Setting Role-Based Permissions


Another way to limit the access others have to your documents is to restrict permissions

by role. The Restrict Permission By People option in the Protect settings in the Info tab (in

Backstage view) of Word, Excel, and PowerPoint enable you to choose the group of people

who you want to give access to your document. For example, in Figure 13-7, Unrestricted

Access is still applied to the current file, but you can choose another setting to connect to

your organization’s rights management system, which defines the roles and permissions in

your system. By default, choosing one of these options displays the introductory page of

Information Rights Management, which is a free service from Microsoft that enables you to

authenticate the credentials of others who work with your files.


FIGURE 13-7 You can set multiple levels of protection in your files, including restricting permissions to a file.


Recovering Unsaved Versions


The process of retrieving unsaved copies of recent files might not be a security issue in terms

of defending against data loss or attack, but having the ability to easily retrieve these copies

can help you avoid a major headache if you forgot to save a file with business-critical data.

Now Office 2010 applications enable you to recover unsaved versions of files you’ve worked

on and retrieve the information you need.


You can find the recovered versions in Backstage view, in the Info category. Click Manage

Versions to display the list of options. (See Figure 13-8.) Click Recover Draft Versions to

display

the Open dialog box, which lists any available previous versions of the file.


Tip You can also display unsaved documents from the Recent category. Scroll to the bottom of

the Recent Documents list, and click Recover Unsaved Documents. Double-click the file you want

to view in the Open dialog box.


FIGURE 13-8 You can recover unsaved drafts and work with versions in Backstage view.


Working with the Trust Center


The Office Trust Center was introduced in Office 2007 and has been expanded and improved

in Office 2010. The Trust Center enables you to choose your specifications for the way in

which files are opened, shared, and protected, and it enables you to create lists of trusted

publishers, documents, and locations that don’t have to be authenticated each time you

receive

a document from them.


Display the Trust Center by choosing File and selecting Options in Backstage view. In the

Options window, click Trust Center at the bottom of the category list, and click the Trust

Center Settings button. (See Figure 13-9.) Table 13-2 lists each of the categories in the Trust

Center and explains how you can use those options to safeguard your files.


FIGURE 13-9 Displaying Trust Center settings.


TABLE 13-2 Office 2010 Trust Center


Category


Description


Trusted Publishers


Enables you to create a list of publishers you trust so that any content

you receive from the publisher is opened freely without restriction.


Trusted Locations


Gives you the ability to create a list of trustworthy locations—for

example,

shared folders and SharePoint workspaces.


Trusted Documents


Creates a list of documents you have specified as trusted. After a

document

is marked as trusted, macros and all content is enabled

automatically.


Add-ins


Enables you to specify whether any application add-ins must be signed

by a trusted publisher.


ActiveX Settings


Lets you choose whether ActiveX controls will be allowed to play in

regular

more or in safe mode. You also set the level of restriction for the

running of the controls.


Macro Settings


Sets whether macros are automatically disabled or enabled.


Protected View


Enables you to choose the situations in which Protected View is used.


Category


Description


Message Bar


Lets you show or hide the Message Bar.


File Block Settings


Gives you the ability to choose whether specific file types are blocked

from being open or saved.


Privacy Options


Lets you set privacy options for the current file, run the Document

Inspector, and set translation and research options.


By default, Office 2010 is set to provide a safe, reliable experience for you as you open

and share the files you create. For most settings—including ActiveX Settings and Macro

Settings—leaving the options set to the optimal level will ensure better protection for your

files and system.


177


Chapter 14


Training Made Easy


In this chapter:


n Getting Help in Office 2010


n Finding What You Need on Office Online


n Take Your Learning to the Next Level with Microsoft eLearning


n Continue Learning with Microsoft Press Books


Now that you know about all the new and improved features you’ll find throughout

Office 2010, your next step is to begin working with the program, exploring your favorite

applications,

creating new documents and presentations, and sharing what you create.

As your experience

with the program grows, you might want to learn about the specific

applications

in greater detail.


Whether you learn best from books, articles, or online courses, you’ll find that many

resources

are available to help you learn more about Office 2010. This chapter gives you a

quick introduction to a few Help changes in Office 2010 and introduces several of the key

resources available that will help you expand your Office 2010 experience.


Getting Help in Office 2010


As you get to know the various Office 2010 applications, you’ll notice right away that the

familiar tooltips are still there to help you learn about the tools and window elements.

(See Figure 14-1.) The Office 2010 Help button is also in the same place it occupied in earlier

versions of the program—on the far right side of the screen, just above the Ribbon.


The Help tab in Backstage view is a new feature that brings together all your program

information

into one convenient window. In the Help window, you’ll find information that

will help you get product information, access program help, and find what you need to get

technical

support. (See Figure 14-2.)


178 Part III Next Steps with Office 2010


FIGURE 14-1 Tooltips provide you with information about specific elements in Office 2010 application

windows.


FIGURE 14-2 The Help tab in Backstage view enables you to get support, access help, and find program

information.


Chapter 14 Training Made Easy 179


You can use the information in the Help tab of Backstage view to do the following things:


n Activate your software.


n Take a tour of basic program features.


n Check for program updates.


n Search for information in Microsoft Office help.


n Change program options.


n Contact Microsoft Support.


The product information in the right side of the Help window shows you all the programs

you have activated, and it also lists any software you are currently using for a specific trial

period.

This information will be helpful if you need to call technical support at some point

and will help the technician diagnose any problems you are having with the software.


Tip If you miss the good, old-fashioned About window that was available in previous versions of

Office, you can display it by clicking Additional Version And Copyright Information on the right

side of the Help tab in Backstage view.


Whether you click Microsoft Office Help in the Help tab to display the Help system or you

click the Help button in the right side of the application window, the results are the same: the

Help window appears. (See Figure 14-3.) Using the Help system is a simple process. It’s similar

in appearance to previous versions, but the Office 2010 Help system pulls information from

http://www.office.com, so you always have access to the most recent help information.


You can enter a word or phrase in the search box or click a category that reflects what you

want. The Help window lists specific articles that relate to your selection. Click the item you

want to view and, after reading it, answer the question “Was this information helpful?” by

clicking Yes, No, or I Don’t Know. A comment box appears so that you can add a note about

your experience.


Tip Microsoft does use the information you enter to make changes in the Help system, so if you

have a suggestion about how the help system can be improved, share it.


Enter a word or phrase to search help

Click to open Help

Click a Help category


FIGURE 14-3 The Office 2010 Help system connects automatically to Office.com so that you have access to

the most recent help articles available.


Finding What You Need on Office Online


Another great resource—whether you want to complete online tutorials or download templates,

clip art, or presentations for training—is Office Online. (See Figure 14-4.) In April 2009

alone, more than 131 million unique users visited Office Online (www.office.microsoft.com),

downloading more than 500,000 training presentations and logging more than 4 million

visits

to the training center.


FIGURE 14-4 Office Online offers a variety of downloads, tutorials, articles, and links to additional resources

and partner sites.


On Office Online, you can do the following:


n Find information about each of the Office 2010 applications.


n Visit resource centers for small business or home users.


n Take a tour of key Office 2010 features.


n Check for available updates for your Office 2010 programs.


n Learn about the different Office 2010 suites and servers.


n Find Webcasts, podcasts, demonstrations, and more information related to the

Office 2010 applications.


n Get links to Microsoft Office product support.


n Download templates, service packs, clip art, and more.


Take Your Learning to the Next Level with

Microsoft eLearning


When you’re ready to take your learning to the next level by exploring applications in depth,

you can take any one of a number of online learning courses at Microsoft eLearning

(www.microsoft.com/learning). These online learning courses give you a convenient way to

work at your own pace, prepare for an exam, and earn certifications.


Some of the learning courses are clinics that offer interactive games and self-tests, demonstrations,

and hands-on virtual labs. You can create your own learning plan with Microsoft

eLearning and save the courses in a queue to complete as you have time. Courses can be

completed online or downloaded (with a free downloadable viewer) so that you can complete

them offline on your own computer. (See Figure 14-5.) At the time of this writing, new

courses are planned for Microsoft eLearning that provide an overview of Office 2010 and

walk you through key features in a number of the core applications.


FIGURE 14-5 Microsoft eLearning offers more than 1000 online learning courses that can help you learn

more about applications and prepare for projects and certification.


Continue Learning with Microsoft Press Books


In addition to the online and in-program offerings you can use to learn more about Office

2010, you’ll find a number of great books that can help you master the various applications.

Whether you’re a new, experienced, or expert user, chances are that Microsoft Press publishes

a book that will speak to you. Here’s a list of the upcoming Office 2010 books that will

be available after the launch of Office 2010:


Office 2010


Microsoft Office 2010 Plain & Simple


Microsoft Office 2010 Step by Step


Microsoft Office 2010 Inside Out


Microsoft Office 2010 Step by Step Home & Student


Access 2010


Microsoft Office Access 2010 Step by Step


Microsoft Office Access 2010 Inside Out


Excel 2010


Microsoft Office Excel 2010: Data Analysis and Business Modeling


Microsoft Office Excel 2010 Inside Out


Microsoft Office Excel 2010 Step by Step


Microsoft Office Excel 2010 Plain & Simple


PowerPoint 2010


Microsoft Office PowerPoint 2010 Step by Step


Microsoft Office PowerPoint 2010 Plain & Simple


Beyond Bullet Points: Using Microsoft Office PowerPoint 2010 to Create Presentations That Inform, Motivate, and Inspire


Project 2010


Microsoft Office Project 2010 Inside Out


Microsoft Office Project 2010 Step by Step


Outlook 2010


Microsoft Office Outlook 2010 and OCS Inside Out


Microsoft Office Outlook 2010 and LiveMeeting Step by Step


Microsoft Office Outlook 2010 Plain & Simple


SharePoint 2010


Microsoft Office SharePoint 2010 Inside Out


Microsoft Office SharePoint Designer 2010


Microsoft Office SharePoint 2010 Step by Step


Microsoft Office SharePoint Designer 2010 Step by Step


Word 2010


Microsoft Office Word 2010 Step by Step


Microsoft Office Word 2010 Plain & Simple


Microsoft Office Word 2010 Inside Out


Visio 2010


Microsoft Office Visio 2010 Step by Step


Katherine Murray


Katherine Murray has been writing about technology since the mid-1980s, which means she’s

seen a lot of menu bars, nested dialog boxes, and new user interfaces over the years. A big

fan of the changes in Office 2007, Katherine was excited to learn about the new directions

in Office 2010 that enable her to write in coffee shops, access her chapters via the Web, and

trade notes with editors in real time. Katherine has written more than 50 books about technology

since 1988 and specializes in Microsoft Office technologies, but she’s fascinated by

any technology that enhances the way we communicate and work together.


The Abandoned Shopping Cart: Crafting a Better Customer-Monitoring Experience

.

Brick and mortar retailers can’t offer customers the shopping convenience of an e-commerce website, but they can offer a smoother shopping experience, especially when store management can physically see problems that may lead customers to leave their half-full shopping carts at the door. Having visibility into what customers are experiencing allows retail store managers to move quickly and decisively to rectify problems. They can see not only what their customers are doing, but why they’re doing it.

While many online retailers use Web analytics alone to gain visibility into customer behavior on their Websites, that visibility is limited. They can see what is happening on the site—how many customers are abandoning their shopping carts and exiting the Website, and what they were doing when they left—but they can’t see why this is happening. Reduced sales mean business goals are not being met, and, since e-commerce, or “e-tail,” has become a major source of sales for retail companies—for many, it’s the only source—it’s critical for these organizations to pay very close attention to customer experience.

Having visibility into all aspects of the customer’s Website experience greatly enhances the ability to speed problem resolution and deliver the excellent shopping experience that is critical to sales. Combining Web analytics with a user experience monitoring solution can provide this essential visibility, which allows IT to see everything the customer does on the site, as well as the way the system responds to every mouse click.

An excellent example of the benefits of user experience monitoring can be found in the online travel industry. When your company’s Website accounts for 40 percent or more of your total business sales, identifying and resolving Website performance issues fast enough to keep frustrated customers from exiting the site, and having the visibility needed to understand why customers had departed, are crucial.

For example, a leading global online travel agency decided to employ a user experience monitoring solution to improve its website performance, and, with the resulting visibility into every aspect of the customer experience plus automatic alerts to problems in real time, the company was able to resolve issues 97 percent faster. Because users now have a consistently positive Website experience, bookings have increased by 30 percent, which translates into increased revenue for the company.

Following are four tips for employing user experience monitoring to improve e-commerce Website performance and increase revenue in support business goals:

•Understand the Customer’s Entire Experience on the Website, Not Just Their Actions
To keep customers shopping, your IT team needs to know not only what the customer is doing on your site, but why they are doing it. There could be hundreds of reasons why customers abandon their online shopping carts—maybe they couldn’t get a good view of the product they want to buy, or maybe their credit card verification took too long, or they got an indecipherable error message. A solution that records and replays every step of every customer’s visit to your site, including what they put in their shopping cart—and works in tandem with your web analytics solution—will give IT the information needed to fix the problem fast.

•Look at the Entire Enterprise
Ensuring application performance and availability have never been more important, especially when those applications serve to generate revenue. Instead of monitoring the disparate components of the IT environment separately, take an application-centric approach that uses customer experience monitoring to look at performance through the application and end user perspective. Choose a monitoring solution that provides a clear view of the entire environment, with dashboard views that communicate the health of mission-critical applications so IT can quickly see and resolve issues that matter to the business before they impact customer experience.

•It’s Not About Good Performance, It’s About Peak Performance
Evidence shows that the speed of a Website is directly related to the conversion rate. With the understanding that peak performance drives revenue, you want to select a user experience monitoring solution that alerts IT to emerging issues in real time, so problems could be addressed quickly, before they affected customers. Now when operating at peak performance, you can see the company’s website increases in the number of hits and bookings, and the average transactional value.

•Go Beyond—Think About Recapturing Lost Business
Take user experience monitoring a step further by recapturing the revenue lost when customers abandoned their shopping cars and left your site. Hundreds of thousands of dollars in lost business have been recovered by online travel agencies by using a solution that automatically sends shopping details of customers who dropped off the Website to retention teams, who then were able to follow up with emails to those potential customers and facilitate new bookings.

Proactive use of experience monitoring enables IT to gain a clear understanding of the customer’s experience on the website, so quick and decisive action can be taken before the shopping cart is abandoned. If a customer does leave the site with a half-full cart, details of the customer experience can help recover lost business so that revenue and business goals continue to be met.

Getting Started with SQL Azure Development

Microsoft Windows Azure offers several choices for data storage. These include Windows Azure storage and SQL Azure. You may choose to use one or both in your particular project. Windows Azure storage currently contains three types of storage structures: tables, queues and blobs.

SQL Azure is a relational data storage service in the cloud. Some of the benefits of this offering are the ability to use a familiar relational development model that includes much of the standard SQL Server language (T-SQL), tools and utilities. Of course, working with well-understood relational structures in the cloud, such as tables, views and stored procedures, also results in increased developer productivity when working in this new platform. Other benefits include a reduced need for physical database-administration tasks to perform server setup, maintenance and security, as well as built-in support for reliability, high availability and scalability.

I won’t cover Windows Azure storage or make a comparison between the two storage modes here. You can read more about these storage options in Julie Lerman’s July 2010 Data Points column (msdn.microsoft.com/magazine/ff796231). It’s important to note that Windows Azure tables are not relational tables. The focus of this is on understanding the capabilities included in SQL Azure.

This article will explain the differences between SQL Server and SQL Azure. You need to understand the differences in detail so that you can appropriately leverage your current knowledge of SQL Server as you work on projects that use SQL Azure as a data source.

If you’re new to cloud computing you’ll want to do some background reading on Windows Azure before continuing with this article. A good place to start is the MSDN Developer Cloud Center at msdn.microsoft.com/ff380142.

Getting Started with SQL Azure

To start working with SQL Azure, you’ll first need to set up an account. If you’re an MSDN subscriber, then you can use up to three SQL Azure databases (maximum size 1GB each) for up to 16 months (details at msdn.microsoft.com/subscriptions/ee461076) as a developer sandbox. To sign up for a regular SQL Azure account (storage and data transfer fees apply) go to microsoft.com/windowsazure/offers/.

After you’ve signed up for your SQL Azure account, the simplest way to initially access it is via the Web portal at sql.azure.com. You must sign in with the Windows Live ID that you’ve associated to your Windows Azure account. After you sign in, you can create your server installation and get started developing your application.

An example of the SQL Azure Web management portal is shown in Figure 1. Here you can see a server and its associated databases. You’ll notice that there’s also a tab on the Web portal for managing the Firewall Settings for your particular SQL Azure installation.


Figure 1 Summary Information for a SQL Azure Database

As you initially create your SQL Azure server installation, it will be assigned a random string for the server name. You’ll generally also set the administrator username, password, geographic server location and firewall rules at the time of server creation. You can select the location for your SQL Azure installation at the time of server creation. You will be presented with a list of locations (datacenters) from which to choose. If your application front end is built in Windows Azure, you have the option to locate both that installation and your SQL Azure installation in the same geographic location by associating the two installations.

By default there’s no access to your server, so you’ll have to create firewall rules for all client IPs. SQL Azure uses port 1433, so make sure that port is open for your client application as well. When connecting to SQL Azure you’ll use the username@servernameformat for your username. SQL Azure supports SQL Server Authentication only; Windows Authentication is not supported. Multiple Active Result Set (MARS) connections are supported.

Open connections will time out after 30 minutes of inactivity. Also, connections can be dropped for long-running queries and transactions or excessive resource usage. Development best practices in your applications around connections are to open, use and then close those connections manually, to include retry connection logic for dropped connections and to avoid caching connections because of these behaviors. For more details about supported client protocols for SQL Azure, see Steve Hale’s blog post at blogs.msdn.com/b/sqlnativeclient/archive/2010/02/12/using-sql-server-client-apis-with-sql-azure-vversion-1-0.aspx.

Another best practice is to encrypt your connection string to prevent man-in-the-middle attacks.

You’ll be connected to the master database by default if you don’t specify a database name in the connection string. In SQL Azure the T-SQL statement USE is not supported for changing databases, so you’ll generally specify the database you want to connect to in the connection string (assuming you want to connect to a database other than master). Here’s an example of an ADO.NET connection:

Server=tcp:server.ctp.database.windows.net;

Database=<databasename>;

User ID=user@server;

Password=password;

Trusted_Connection=False;

Encrypt=true;

Setting up Databases

After you’ve successfully connected to your installation you’ll want to create one or more databases. Although you can create databases using the SQL Azure portal, you may prefer to do so using some of the other tools, such as SQL Server Management Studio 2008 R2. By default, you can create up to 149 databases for each SQL Azure server installation. If you need more databases than that, you must call the Windows Azure business desk to have this limit increased.

When creating a database you must select the maximum size. The current options for sizing (and billing) are Web or Business Edition. Web Edition, the default, supports databases of 1GB or 5GB total. Business Edition supports databases of up to 50GB, sized in increments of 10GB—in other words, 10GB, 20GB, 30GB, 40GB and 50GB.

You set the size limit for your database when you create it by using the MAXSIZE keyword. You can change the size limit or the edition (Web or Business) after the initial creation using the ALTER DATABASE statement. If you reach your size or capacity limit for the edition you’ve selected, then you’ll see the error code 40544. The database size measurement doesn’t include the master database, or any database logs. For more details about sizing and pricing, see microsoft.com/windowsazure/pricing/#sql.

It’s important to realize that when you create a new SQL Azure database, you’re actually creating three replicas of that database. This is done to ensure high availability. These replicas are completely transparent to you. The new database appears as a single unit for your purposes.

Once you’ve created a database, you can quickly get the connection string information for it by selecting the database in the list on the portal and then clicking the Connection Strings button. You can also quickly test connectivity via the portal by clicking the Test Connectivity button for the selected database. For this test to succeed you must enable the Allow Microsoft Services to Connect to this Server option on the Firewall Rules tab of the SQL Azure portal.

Creating Your Application

After you’ve set up your account, created your server, created at least one database and set a firewall rule so that you can connect to the database, you can start developing your application using this data source.

Unlike Windows Azure data storage options such as tables, queues or blobs, when you’re using SQL Azure as a data source for your project, there’s nothing to install in your development environment. If you’re using Visual Studio 2010, you can just get started—no additional SDKs, tools or anything else are needed.

Although many developers will choose to use a Windows Azure front end with a SQL Azure back end, this configuration is not required. You can use any front-end client with a supported connection library such as ADO.NET or ODBC. This could include, for example, an application written in Java or PHP. Connecting to SQL Azure via OLE DB is currently not supported.

If you’re using Visual Studio 2010 to develop your application, you can take advantage of the included ability to view or create many types of objects in your selected SQL Azure database installation directly from the Visual Studio Server Explorer. These objects are Tables, Views, Stored Procedures, Functions and Synonyms. You can also see the data associated with these objects using this viewer. For many developers, using Visual Studio 2010 as the primary tool to view and manage SQL Azure data will be sufficient. The Server Explorer View window is shown in Figure 2. Both a local installation of a database and a cloud-based instance are shown. You’ll see that the tree nodes differ slightly in the two views. For example, there’s no Assemblies node in the cloud installation because custom assemblies are not supported in SQL Azure.


Figure 2 Viewing Data Connections in Visual Studio Server Explorer

As I mentioned earlier, another tool you may want to use to work with SQL Azure is SQL Server Management Studio (SSMS) 2008 R2. With SSMS 2008 R2, you actually have access to a fuller set of operations for SQL Azure databases than in Visual Studio 2010. I find that I use both tools, depending on which operation I’m trying to complete. An example of an operation available in SSMS 2008 R2 (and not in Visual Studio 2010) is creating a new database using a T-SQL script. Another example is the ability to easily perform index operations (create, maintain, delete and so on). An example is shown in Figure 3.


Figure 3 Using SQL Server Management Studio 2008 R2 to Manage SQL Azure

Newly released in SQL Server 2008 R2 is a data-tier application, or DAC. DAC pacs are objects that combine SQL Server or SQL Azure database schemas and objects into a single entity. You can use either Visual Studio 2010 (to build) or SQL Server 2008 R2 SSMS (to extract) to create a DAC from an existing database.

If you wish to use Visual Studio 2010 to work with a DAC, then you’d start by selecting the SQL Server Data-Tier Application project type in Visual Studio 2010. Then, on the Solution Explorer, right-click your project name and click Import Data-Tier Application. A wizard opens to guide you through the import process. If you’re using SSMS, start by right-clicking on the database you want to use in the Object Explorer, click Tasks, then click Extract Data-Tier Application to create the DAC.

The generated DAC is a compressed file that contains multiple T-SQL and XML files. You can work with the contents by right-clicking the .dacpac file and then clicking Unpack. SQL Azure supports deleting, deploying, extracting and registering DAC pacs, but does not support upgrading them.

Another tool you can use to connect to SQL Azure is the latest community technology preview (CTP) release of the tool code-named “Houston.” Houston is a zero-install, Silverlight-based management tool for SQL Azure installations. When you connect to a SQL Azure installation using Houston, you specify the datacenter location (as of this writing North Central U.S., South Central U.S., North Europe, Central Europe, Asia Pacific or Southeast Asia).

Houston is in early beta and the current release (shown in Figure 4) looks somewhat like SSMS. Houston supports working with Tables, Views, Queries and Stored Procedures in a SQL Azure database installation. You can access Houston from the SQL Azure Labs site at sqlazurelabs.com/houston.aspx.


Figure 4 Using Houston to Manage SQL Azure

Another tool you can use to connect to a SQL Azure database is SQLCMD (msdn.microsoft.com/library/ee336280). Even though SQLCMD is supported, the OSQL command-line tool is not supported by SQL Azure.

Using SQL Azure

So now you’ve connected to your SQL Azure installation and have created a new, empty database. What exactly can you do with SQL Azure? Specifically, you may be wondering what the limits are on creating objects. And after those objects have been created, how do you populate those objects with data?

As I mentioned at the beginning of this article, SQL Azure provides relational cloud data storage, but it does have some subtle feature differences to an on-premises SQL Server installation. Starting with object creation, let’s look at some of the key differences between the two.

You can create the most commonly used objects in your SQL Azure database using familiar methods. The most commonly used relational objects (which include tables, views, stored procedures, indices and functions) are all available. There are some differences around object creation, though. Here’s a summary of those differences:

  • SQL Azure tables must contain a clustered index. Non-clustered indices can be subsequently created on selected tables. You can create spatial indices, but you cannot create XML indices.
  • Heap tables are not supported.
  • CLR geo-spatial types (such as Geography and Geometry) are supported, as is the HierachyID data type. Other CLR types are not supported.
  • View creation must be the first statement in a batch. Also, view (or stored procedure) creation with encryption is not supported.
  • Functions can be scalar, inline or multi-statement table-valued functions, but cannot be any type of CLR function.

    There’s a complete reference of partially supported T-SQL statements for SQL Azure on MSDN at msdn.microsoft.com/library/ee336267.

    Before you get started creating your objects, remember that you’ll connect to the master database if you don’t specify a different one in your connection string. In SQL Azure, the USE (database) statement is not supported for changing databases, so if you need to connect to a database other than the master database, then you must explicitly specify that database in your connection string, as shown earlier.

    Data Migration and Loading

    If you plan to create SQL Azure objects using an existing, on-premises database as your source data and structures, then you can simply use SSMS to script an appropriate DDL to create those objects on SQL Azure. Use the Generate Scripts Wizard and set the “Script for the database engine type” option to “for SQL Azure.”

    An even easier way to generate a script is to use the SQL Azure Migration Wizard, available as a download from CodePlex at sqlazuremw.codeplex.com. With this handy tool you can generate a script to create the objects and can also load the data via bulk copy using bcp.exe.

    You could also design a SQL Server Integration Services (SSIS) package to extract and run a DDM or DDL script. If you’re using SSIS, you’d most commonly design a package that extracts the DDL from the source database, scripts that DDL for SQL Azure and then executes that script on one or more SQL Azure installations. You might also choose to load the associated data as part of the package’s execution path. For more information about working with SSIS, see msdn.microsoft.com/library/ms141026.

    Also of note regarding DDL creation and data migration is the CTP release of SQL Azure Data Sync Services (sqlazurelabs.com). You can see this service in action in a Channel 9 video, “Using SQL Azure Data Sync Service to provide Geo-Replication of SQL Azure Databases,” at tinyurl.com/2we4d6q. Currently, SQL Azure Data Sync services works via Synchronization Groups (HUB and MEMBER servers) and then via scheduled synchronization at the level of individual tables in the databases selected for synchronization.

    You can use the Microsoft Sync Framework Power Pack for SQL Azure to synchronize data between a data source and a SQL Azure installation. As of this writing, this tool is in CTP release and is available from tinyurl.com/2ecjwku. If you use this framework to perform subsequent or ongoing data synchronization for your application, you may also wish to download the associated SDK.

    What if your source database is larger than the maximum size for the SQL Azure database installation? This could be greater than the absolute maximum of 50GB for the Business Edition or some smaller limit based on the other program options.

    Currently, customers must partition (or shard) their data manually if their database size exceeds the program limits. Microsoft has announced that it will be providing an auto-partitioning utility for SQL Azure in the future. In the meantime, it’s important to note that T-SQL table partitioning is not supported in SQL Azure. There’s a free utility called Enzo SQL Shard (enzosqlshard.codeplex.com) that you can use for partitioning your data source.

    You’ll want to take note of some other differences between SQL Server and SQL Azure regarding data loading and data access.

    Added recently is the ability to copy a SQL Azure database via the Database copy command. The syntax for a cross-server copy is as follows:

    CREATE DATABASE DB2A AS COPY OF Server1.DB1A

    The T-SQL INSERT statement is supported (with the exceptions of updating with views or providing a locking hint inside of an INSERT statement).

    Related further to data migration, T-SQL DROP DATABASE and other DDL commands have additional limits when executed against a SQL Azure installation. In addition, the T-SQL RESTORE and ATTACH DATABASE commands are not supported. Finally, the T-SQL statement EXECUTE AS (login) is not supported.

    Data Access and Programmability

    Now let’s take a look at common programming concerns when working with cloud data. First, you’ll want to consider where to set up your development environment. If you’re an MSDN subscriber and can work with a database that’s less than 1GB, then it may well make sense to 
develop using only a cloud installation (sandbox). In this way there will be no issue with migration from local to cloud. Using a regular (non-MSDN subscriber) SQL Azure account, you could develop directly against your cloud instance (most probably using a cloud-located copy of your production database). Of course, developing directly from the cloud is not practical for all situations.

    If you choose to work with an on-premises SQL Server database as your development data source, then you must develop a mechanism for synchronizing your local installation with the cloud installation. You could do that using any of the methods discussed earlier, and tools like Data Sync Services and Sync Framework are being developed with this scenario in mind.

    As long as you use only the supported features, the method for having your application switch from an on-premises SQL Server installation to a SQL Azure database is simple—you need only to change the connection string in your application.

    Regardless of whether you set up your development installation locally or in the cloud, you’ll need to understand some programmability differences between SQL Server and SQL Azure. I’ve already covered the T-SQL and connection string differences. In addition, all tables must have a clustered index at minimum (heap tables are not supported).

    As previously mentioned, the USE statement for changing databases isn’t supported. This also means that there’s no support for distributed (cross-database) transactions or queries, and linked servers are not supported.

    Other options not available when working with a SQL Azure database include:

  • Full-text indexing
  • CLR custom types (however, the built-in Geometry and Geography CLR types are supported)
  • RowGUIDs (use the uniqueidentifier type with the NEWID function instead)
  • XML column indices
  • Filestream datatype
  • Sparse columns

    Default collation is always used for the database. To make collation adjustments, set the column-level collation to the desired value using the T-SQL COLLATE statement.

    And finally, you cannot currently use SQL Profiler or the Database Tuning Wizard on your SQL Azure database.

    Some important tools that you can use with SQL Azure for tuning and monitoring include:

  • SSMS Query Optimizer to view estimated or actual query execution plan details and client statistics
  • Select Dynamic Management views to monitor health and status
  • Entity Framework to connect to SQL Azure after the initial model and mapping files have been created by connecting to a local copy of your SQL Azure database.

    Depending on what type of application you’re developing, you may be using SSAS, SSRS, SSIS or PowerPivot. You can also use any of these products as consumers of SQL Azure database data. Simply connect to your SQL Azure server and selected database using the methods already described in this article.

    It’s also important to fully understand the behavior of transactions in SQL Azure. As mentioned, only local (within the same database) transactions are supported. In addition, the only transaction-isolation level available for a database hosted on SQL Azure is READ COMMITTED SNAPSHOT. Using this isolation level, readers get the latest consistent version of data that was available when the statement STARTED.

    SQL Azure doesn’t detect update conflicts. This is also called an optimistic concurrency model, because lost updates, non-repeatable reads and phantoms can occur. Of course, dirty reads cannot occur.

    Database Administration

    Generally, when using SQL Azure, the administrator role becomes one of logical installation management. Physical management is handled by the platform. From a practical standpoint this means there are no physical servers to buy, install, patch, maintain or secure. There’s no ability to physically place files, logs, tempdb and so on in specific physical locations. Because of this, there’s no support for the T-SQL commands USE <database>, FILEGROUP, BACKUP, RESTORE or SNAPSHOT.

    There’s no support for the SQL Agent on SQL Azure. Also, there is no ability (or need) to configure replication, log shipping, database mirroring or clustering. If you need to maintain a local, synchronized copy of SQL Azure schemas and data, then you can use any of the tools discussed earlier for data migration and synchronization—they work both ways. You can also use the DATABASE COPY command.

    Other than keeping data synchronized, what are some other tasks that administrators may need to perform on a SQL Azure installation? 

    Most commonly, there will still be a need to perform logical administration. This includes tasks related to security and performance management. Additionally, you may be involved in monitoring for capacity usage and associated costs. To help you with these tasks, SQL Azure provides a public Status History dashboard that shows current service status and recent history (an example of history is shown in Figure 5) at microsoft.com/windowsazure/support/status/servicedashboard.aspx.


    Figure 5 SQL Azure Status History

    SQL Azure provides a high-security bar by default. It forces SSL encryption with all permitted (via firewall rules) client connections. Server-level logins and database-level users and roles are also secured. There are no server-level roles in SQL Azure. Encrypting the connection string is a best practice. Also, you may want to use Windows Azure certificates for additional security. For more details, see blogs.msdn.com/b/sqlazure/archive/2010/09/07/10058942.aspx.

    In the area of performance, SQL Azure includes features such as automatically killing long-running transactions and idle connections (more than 30 minutes). Although you can’t use SQL Profiler or trace flags for performance tuning, you can use SQL Query Optimizer to view query execution plans and client statistics. You can also perform statistics management and index tuning using the standard T-SQL methods.

    There’s a select list of dynamic management views (covering database, execution or transaction information) available for database administration as well. These include sys.dm_exec_connections , _requests, _sessions, _tran_database_transactions, _active_transactions and _partition_stats. For a complete list of supported dynamic management views for SQL Azure, see msdn.microsoft.com/library/ee336238.aspx#dmv.

    There are also some new views such as sys.database_usage and sys.bandwidth_usage. These show the number, type and size of the databases and the bandwidth usage for each database so that administrators can understand SQL Azure billing. A sample is shown in Figure 6. In this view, quantity is listed in KB. You can monitor space used via this command:

    SELECT SUM(reserved_page_count) * 8192

    FROM sys.dm_db_partition_stats


    Figure 6 Bandwidth Usage in SQL Query

    You can also access the current charges for the SQL Azure installation via the SQL Azure portal by clicking on the Billing link at the top-right corner of the screen.

    Learn More

    To learn more about SQL Azure, I suggest you download the Windows Azure Training Kit. This includes SQL Azure hands-on learning, white papers, videos and more. The training kit is available from microsoft.com/downloads/details.aspx?FamilyID=413E88F8-5966-4A83-B309-53B7B77EDF78.

    Also, you’ll want to read the SQL Azure Team Blog at blogs.msdn.com/b/sqlazure/ and check out the MSDN SQL Azure Developer Center at msdn.microsoft.com/windowsazure/sqlazure.

    If you want to continue to preview upcoming features for SQL Azure, be sure to visit SQL Azure Labs at sqlazurelabs.com.                                                                                


Office 365 plan comparison – Enterprise and Kiosk subscriptions (E1, E2, E3, E4, K1, K2)

Office 365 plan comparison – Enterprise and Kiosk subscriptions (E1, E2, E3, E4, K1, K2)

By: mike|March 13, 2012No Comments
Microsoft Office 365 Plans Compared

There is a lot of high level information about what features are included with each Office 365 plan. However, the details for the Office 365 plans are scattered among numerous Microsoft documents that aren’t easily found, yet alone understood. Here I’ve attempted to describe in detail, the differences between the Office 365 Kiosk and Enterprise plans. This includes the Office 365 E1, E2, E3, and E4 enterprise plans and the Office 365 K1 and K2 kiosk worker plans.

In addition, the Sharepoint Online component can be accessed by external users who can collaborate on documents and projects within Office 365 Sharepoint sites. These access licenses are called Partner Access License (PAL) and each Office 365 installation is granted 50 Partner Access Licenses by default. Currently Microsoft doesn’t enforce this limit and allows up to 1000 external users per Office 365 installation.

This article doesn’t address the Office 365 P1 plan. This plan is targeted at professionals and small businesses and is roughly equivalent to the Enterprise E3 plan, however, there are many differences within each service. These are addressed in a separate article comparing the Office 365 P1, E1 and E3 plans.

This article covers the three major services included with Office 365:

Office 365 Enterprise and Kiosk plans – Sharepoint Online – (E1, E2, E3, E4, K1, K2 Plans)
Office 365 Enterprise and Kiosk plans – Exchange Online – (E1, E2, E3, E4, K1, K2 Plans)
Office 365 Enterprise and Kiosk plans – Lync Online – (E1, E2, E3, E4, K1, K2 Plans)
Note: Microsoft lowered pricing on their enterprise plans on March 14th, 2012. Those changes are:


Office 365 New Pricing – Office 365 Plans E1, E2, E3, E4, K1, and K2
SKU Previous Cost New Cost Reduction
Office 365 K2 $10.00 $8.00 20%
Office 365 E1 $10.00 $8.00 20%
Office 365 E2 $16.00 $14.00 13%
Office 365 E3 $24.00 $20.00 17%
Office 365 E4 $27.00 $22.00 19%
SharePoint Storage (GB) $2.50 $0.20 92%
Exchange Advanced Archiving $3.50 $3.00 14%
Notes:
This pricing applies to new customers only. Customers that are under contract will still pay the same rate that their contract states. Rates will be updated when the contract is renewed.
If a current customers purchases additional seats, the new seats will be subject to the new pricing.

These Office 365 subscription plans are targeted at business of all size that require maximum flexibility in there online e-mail and collaboration service.

Office 365 Sharepoint Online Features for the Enterprise and Kiosk Plans


Office 365 Plan Comparison – Office 365 Plans E1, E2, E3, E4, K1, and K2
Sharepoint Online Features
Feature
Office 365 K1 and K2 Plans SharePoint Online Kiosk 1 and Kiosk 2
Office 365 E1 and E2 Plans SharePoint Online 1
Office 365 E3 and E4 Plans SharePoint Online 2
Office 365 Partner Access License (PAL)
(external partners)
Can access all team sites by default?
Yes
Yes
Yes
No1
My Site
No
Yes
Yes
No
Enterprise Features (Access, Business Connectivity Services (BCS), InfoPath Forms, Excel and Visio Services)
Yes3
No
Yes2
Yes2
Office Web Apps
K1 – View only
K2 – View and edit
E1 – View only
E2 – View and edit
View and edit
View only
Adds storage to the company’s overall pooled quota?
No
Yes. 500MB per user subscription license
No
Can be an administrator of tenant, site or site collection?
No
Yes
Yes
No
1 – External partners can only access the sites they have been invited to by delegated site collection owners. 2 – Can view and upload Visio diagrams, view and build external lists, build and visit Access-based webpages, build and view embedded Excel graphs and create/publish, fill in and submit InfoPath forms. 3 – Kiosk workers have read-only rights except they can edit web-based and InfoPath Forms only.

Office 365 Partner Access License (PAL)

The Office 365 Partner Access License grants access to features like another Office 365 Plan. Below is an excerpt from the “Microsoft SharePoint Online for Enterprises Service Description”:

External sharing: The external sharing capabilities in SharePoint Online enable a company to simply invite external users in to view, share, and collaborate on their sites. Once a SharePoint Online Administrator enables external sharing, a site collection administrator can activate external sharing for the site they manage, and then invite external users to collaborate on sites, lists, and document libraries. An external user has access rights to only the site collection they are invited into. Please also note the external user use rights as explained above.

Note
Every Office 365 SharePoint Online customer (at the tenant level, not per subscription) includes 50 Partner Access Licenses (PALs) that can be leveraged for external sharing. Customers are not currently required to obtain additional PALs for external sharing beyond 50 users with a limit of 1000 until the next major update of the Office 365 service at which time Microsoft may choose to make it available as a paid add-on.
Microsoft supports invited external users signing in to the service using a Microsoft Online Services ID.
External sharing also supports Windows Live ID, including @Live.com, @Hotmail.com and @MSN.com user names, plus regional derivations of LiveID user names.
EasiID, the portion of LiveID that allows external users to associate their business email address (ex: user@contoso.com) to the LiveID system, is not supported at this time.

Office 365 Sharepoint Online “Server Resources” quota

From a development perspective SharePoint Online offers a flexible, robust framework for customizing and developing solutions in Office 365. The development features and patterns used to develop for SharePoint Online are a subset of those available in SharePoint 2010 on-premises.

Note
While SharePoint Online offers many opportunities to building customized solutions, the service does not yet support Full Trust Coded (FTC) solutions or what is sometimes referred to as farm-level solutions. The SharePoint Online development patterns and practices are currently targeted at site collection level solutions.
“Server Resources” quota, what are used to determine amount of processing power available to Sandboxed Solutions, is determined by the number of licensed user seats in a company’s tenancy. To calculate server resource quota in Office 365, you can use the following equation: (#seats×200) + 300. For example, in a typical 25 seat license, the available server resources quota would be 5300.
Neither Kiosk 1 (K1) or Kiosk 2 (K2) add to the overall total server resources quota
Companies cannot purchase server resources as a standalone add-on

SharePoint Online key features and specifications

These are common for all Office 365 plans that include Sharepoint Online.

Feature Description
Storage (pooled) 10 gigabytes (GB) base customer storage plus 500 megabytes (MB) per enterprise user
Storage per Kiosk Worker Zero (0). Licensed Kiosk Workers do not bring additional storage allocation.
Storage per external user Zero (0). Licensed external users do not bring additional storage allocation.
Additional storage (per GB per month); no minimum purchase. $2.50USD/GB/month
Site collection storage quotas Up to 100 gigabytes (GB) per site collection
My Site storage allocation (does not count against tenant’s overall storage pool) 500 megabytes (MB) of personal storage per My Site (once provisioned)
*Note: the storage amount on individual’s My Site storage cannot be adjusted.
Site collections (#) per tenant Up to 300 (non-My Site site collections)
Total storage per tenant Up to 5 terabyte (TB) per tenant
File upload limit 250 megabytes (MB) per file
External Users (PALs) 50 PALs are included per tenant. Current “Feature Preview” allows for usage rights of up to 1000 external users without requiring additional PALs. Microsoft reserves the right to charge for additional PALs beyond 50 at the time the next major Office 365 update.
Microsoft Office support Microsoft Access 2010 Microsoft Excel® 2007 and 2010 Microsoft InfoPath® 2010
Outlook 2007 and 2010
Microsoft OneNote 2010
PowerPoint 2007 and 2010 Microsoft SharePoint Designer 2010 Word 2007 and 2010
SharePoint Workspace 2010
Project Professional 2010
Browser support Internet Explorer 7 Internet Explorer 8 Internet Explorer 9 Firefox 3 and higher Safari 3.1.2 on Macintosh OS X 10.5 Chrome
Mobile device support Windows Phone 7.5 codenamed “Mango” or later Windows Mobile® 6.1 or later Nokia S60 3.0 or later
Apple iPhone 3.0 or later
Blackberry 4.2 or later
Android 1.5 or later

Office 365 Exchange Online Features for the Enterprise and Kiosk Plans

There are significant differences between the Office 365 kiosk and enterprise plans for Exchange Online. The Kiosk version has limited connectivity versus the enterprise plans. The primary benefit of the Office 365 E3 and E4 plans for Exchange Online is unlimited storage, the legal hold feature, and voicemail integration.

Office 365 Plan Comparison – Office 365 Plans E1, E2, E3, E4, K1, and K2
Exchange Online Features
Feature
Office 365 K1 and K2 Plans
Exchange Online
Kiosk
Office 365 E1 and E2 Plans
Exchange Online
(Plan 1)
Office 365 E3 and E4 Plans
Exchange Online
(Plan 2)
Office 365 Partner Access License (PAL)
(external partners)
Mailbox size
500 megabytes (MB)
25 gigabytes (GB)*
Unlimited**
Office 365 Partner Access License (PAL) users have not access to Exchange online freatures.
Outlook Web App
(regular and light versions)
Yes
Yes
Yes
POP
Yes
Yes
Yes
IMAP
No
Yes
Yes
Outlook Anywhere (MAPI)
No
Yes
Yes
Microsoft Exchange ActiveSync®
No
Yes
Yes
Exchange Web Services
No***
Yes
Yes
Inbox rules
No
Yes
Yes
Delegate access
No (cannot access other users’ mailboxes, shared mailboxes, or resource mailboxes)
Yes
Yes
Instant messaging interoperability in OWA
No
Yes (requires Lync Online or Microsoft Lync Server 2010)
SMS notifications
No
Yes
Yes
Custom retention policies
Yes
Yes
Yes
Multi-mailbox search
Yes
Yes
Yes
Personal archive
No
Yes
Yes
Voicemail
No
No
Yes
Legal hold
No
No
No
*25 GB of storage apportioned across the user’s primary mailbox and personal archive **25 GB of storage in the user’s primary mailbox, plus unlimited storage in the user’s personal archive. Refer to the personal archive section of this document for further information regarding unlimited storage in the archive ***Direct access to Kiosk user mailboxes via Exchange Web Services is not permitted. However, line of business applications can use Exchange Web Services impersonation to access Kiosk user mailboxes

Office 365 E3 and E4 Plans – Unlimited Personal Archive

In Office 365, a personal archive can only be used to store one user’s messaging data. In the Office 365 E1 and Office 365 E2 plan each user receives 25 gigabytes (GB) of total storage which includes both the user’s primary mailbox and personal archive. This effectively limits the personal archive for an Office 365 E1 and E2 plan user to less than 25 GB.

An Office 365 E3 plan and Office 365 E4 plan user has 25 GB for their primary mailbox, plus unlimited storage in the personal archive. For Office 365 E3 and E4 plan users, the personal archive has a default quota of 100 GB. This is generally large enough for reasonable use, including importing a user’s historical email. In the unlikely event that a user reaches this quota, Office 365 support can increase the quota.

To change the Single Item Recovery period for a mailbox, an administrator must contact Office 365 support. The Office 365 E1 and E2 plans support Single Item Recovery period of up to 30 days. The Office 365 E3 plan and Office 365 E4 plan both support a Single Item Recovery period of any length.

Office 365 Lync Online Features for the Enterprise and Kiosk Plans

This table comparing Office 365 plans for Lync Online is a little overkill because the Kiosk plans don’t include Lync and external users don’t have Lync rights either. On top of that all Office 365 E plans include Lync Online Plan 2.

Feature
Office 365 K1 and K2 Plans
Office 365 E1 and E2 Plans
Lync Online
(Plan 2)
Office 365 E2 and E3 Plans
Lync Online
(Plan 2)
Office 365 Partner Access License (PAL)
(external partners)
Instant messaging (IM) and presence
Office 365 Kiosk K1 and K2 plans have no access to Lync Online features of Office 365.
Yes
Yes
Office 365 Partner Access License (PAL) users have not access to Exchange online freatures.
Lync-to-Lync audio/video calling (1-to-1)
Yes
Yes
Lync federation (IM/presence/audio/video)
Yes
Yes
Click-to-communicate in Office
Yes
Yes
Authenticated attendee in Lync meetings*
Yes
Yes
Microsoft Exchange ActiveSync®
Yes
Yes
Online Meetings
Yes (up to 250 attendees)
Initiate ad-hoc and scheduled online meetings
Yes
Yes
Initiate multiparty (3 or more users) Lync audio/video sessions
Yes
Yes
Initiate interactive data sharing (screen/application/whiteboard)
Yes
Yes
Interop with third-party dial-in audio conferencing services
Yes
Yes
*Unauthenticated attendees who join scheduled Lync meetings do not require a Lync Online license.


References:

The information in this article comparing Office 365 subscription plans was gleaned from the following Microsoft documents:

Office 365 Microsoft Sharepoint Online for Enterprises Service Description (Updated 12/6/2011)
Office 365 Microsoft Exchange Online for Enterprises Service Description (Updated 11/18/2011)
Office 365 Microsoft Lync Online for Enterprises Service Description (Updated 7/29/2011)

Microsoft Office 365for professionals and small businesses(Plan P1) Service Description


Microsoft Office 365


Microsoft Office 365
for professionals and small businesses
(Plan P1)


Service Description


Note: This document is provided for informational purposes only, and Microsoft makes no warranties, express or implied, with respect to this document or the information contained in it.

Published: February 2012
Updated: May 29, 2012

For the latest information, please see http://www.microsoft.com/online.


The information contained in this document represents the current view of Microsoft Corporation on the issues discussed as of the date of publication and is subject to change at any time without notice to you. This document is provided “as-is.” Information and views expressed in this document, including URL and other Internet Web site references, may change without notice. You bear the risk of using it. MICROSOFT MAKES NO WARRANTIES, EXPRESS OR IMPLIED, IN THIS DOCUMENT.

This document does not provide you with any legal rights to any intellectual property in any Microsoft product. You may copy and use this document for your internal, reference purposes. This document is confidential and proprietary to Microsoft. It is disclosed and can be used only pursuant to a non-disclosure agreement.

The descriptions of other companies’ products in this document, if any, are provided only as a convenience to you. Any such references should not be considered an endorsement or support by Microsoft. Microsoft cannot guarantee their accuracy, and the products may change over time. Also, the descriptions are intended as brief highlights to aid understanding, rather than as thorough coverage. For authoritative descriptions of these products, please consult their respective manufacturers.

Microsoft may have patents, patent applications, trademarks, copyrights, or other intellectual property rights covering subject matter in this document. Except as expressly provided in any written license agreement from Microsoft, the furnishing of this document does not give you any license to these patents, trademarks, copyrights, or other intellectual property.

All trademarks are the property of their respective companies.

©2012 Microsoft Corporation. All rights reserved.

Microsoft, ActiveSync, Backstage, Entourage, Excel, Forefront, Hotmail, InfoPath, Internet Explorer, Lync, MSN Messenger, OneNote, Outlook, PowerPoint, RoundTable, SharePoint, Silverlight, SkyDrive, SQL Server, Visual Studio, Windows, Windows Live, Windows Mobile, Windows Phone, Windows Server, and Windows Vista are either registered trademarks or trademarks of Microsoft Corporation in the United States and/or other countries.

The names of actual companies and products mentioned herein may be the trademarks of their respective owners.

Contents    

Contents    2

Introduction    2

1. Why Office 365 for Your Organization    2

1.1 Virtually Anytime, Anywhere Access    2

1.2 Easy to Use    2

1.3 Improved Collaboration    2

1.4 Security and Reliability    2

2. Overview of Services Provided by Office 365    2

2.1 Email, Calendar, and Contacts    2

2.2 Team Sites and Public Website    2

2.3 Office Web Apps    2

2.4 Instant Messaging and Online Meetings    2

3. Requirements for Using Office 365    2

3.1 System Requirements    2

3.2 Using Office Desktop Applications    2

3.3 Using Mobile Devices    2

4. Office 365 Security    2

5. Email, Calendar, and Contacts    2

5.1 Access Your Email, Calendar, and Contacts    2

5.2 Functionality of Your Outlook Email, Calendar, and Contacts    2

5.3 Large, Easy-to-Use Mailboxes    2

5.4 Professional Email Addresses    2

5.5 Automatically Update Your Email, Calendar, and Contacts across Devices    2

5.6 See Colleagues’ Availability from Your Outlook Calendar    2

5.7 Antivirus and Anti-Spam Filtering    2

5.8 Reduce Inbox Overload with Conversation View    2

5.9 Set Out-of-Office Replies    2

5.10 Recover Deleted Items    2

5.11 Access Other Email Accounts through Office 365    2

5.12 Personal Archive    2

5.13 Additional Features    2

6. Team Sites and Public Websites    2

6.1 Public-Facing Website    2

6.2 Manage Important Documents    2

6.3 Plenty of Space for Your Documents and Sites    2

6.4 External Sharing    2

6.5 Microsoft Office Integration    2

6.7 Familiar Look and Feel    2

6.8 Data Is Highly Secure    2

7. Office Web Apps    2

7.1 Never Be without the Tools You Need    2

7.2 Ensure Consistent Document Views    2

7.3 Edit Content with Confidence    2

7.4 Work Easily with Others    2

8. Instant Messaging and Online Meetings    2

8.1 Find and Connect with Colleagues and Customers    2

8.2 Easily Conduct Professional Online Presentations or Spontaneous Online Meetings    2

8.3 Interoperability with 3rd Party Dial-in Audio Conferencing Services    2

8.4 View Presence Status and Click-to-Communicate In Microsoft Office Applications    2

8.5 Communicate with Other Office 365 and Windows Live Users    2

8.6 Presence with Microsoft Outlook and Other Office Applications    2

8.7 Presence with Exchange Online    2

9. Additional Office 365 Service Details    2

9.1 Administering Office 365    2

9.2 Getting Help    2

9.3 Additional Self-help Resources    2

9.4 Countries Where Office 365 (Plan P1) Is Available    2

9.5 Languages    2

9.6 Licensing    2

9.7 Buying your Office 365 Subscription    2

9.8 Microsoft Office 365 Marketplace    2

9.9 Service Level Agreement    2

9.10 Data Center Locations    2

Appendix A: Exchange Online Detailed Feature Summary    2

Appendix B: SharePoint Online Detailed Feature Summary    2


Introduction


Office 365 for professionals and small businesses (Plan P1).
is a set of web-enabled tools that lets you access your email, important documents, contacts, and calendars from virtually anywhere and on almost any device. Designed for organizations with one to 25 employees (with a technical limit of 50 users maximum), the service brings together online versions of the best business-grade communications and collaboration tools from Microsoft plus Microsoft Office Web Apps at a price that small businesses can afford. Office 365 works seamlessly with the programs you already know and use — Microsoft Outlook, Microsoft Word, Microsoft Excel, and Microsoft PowerPoint. This is the much-anticipated cloud service that gives small businesses the capabilities and efficiencies to grow and target more rapid success.


Powerful security features from Microsoft Corporation help protect your data, and it will be backed with a 99.9 percent financially-backed uptime guarantee. Office 365 was designed to be easy enough for small businesses to run without specialized IT knowledge.

1. Why Office 365 for Your Organization

1.1 Virtually Anytime, Anywhere Access

Office 365 helps you access your email, important documents, contacts, and calendar on nearly any device from almost anywhere. It frees you to work where and when you choose, allowing you to respond to important requests right away, no matter where you are. Because you can use your mobile device to access email and documents, you won’t have to hurry back to the office (or look for a WIFI hot spot if you are using your computer). When traveling, you can access your email and even edit online documents from most popular web browsers.

1.2 Easy to Use

Office 365 is easy to try, simple to learn, and straightforward to use. It works seamlessly with the programs you know and use most, including Outlook, Word, Excel, OneNote and PowerPoint. With Office 365, you can choose which tools to use.

1.3 Improved Collaboration

With Office 365, you can create a password-protected portal to share large, hard-to-email files both inside and outside your organization, giving you a single location to find the very latest versions of files or documents, no matter how many people are working on them.

1.4 Security and Reliability

Powerful security features from Microsoft help protect your data. Office 365 is backed with a 99.9-percent uptime, financially backed guarantee. Office 365 helps safeguard your data with enterprise-grade reliability, disaster recovery capabilities, data centers in multiple locations, and a strict privacy policy. It also helps protect your email environment with up-to-date antivirus and anti-spam solutions.

2. Overview of Services Provided by Office 365

2.1 Email, Calendar, and Contacts

Powered by Microsoft Exchange Online

Office 365 provides you access to email, calendar, and contacts from virtually anywhere at any time on desktops, laptops, and mobile devices—while helping to protect against malicious software and spam.

  • Easily manage your email with 25-gigabyte (GB) mailboxes and send emails up to 25 megabytes (MB) in size
  • Work from almost anywhere with automatically updated email, calendar, and contacts across devices you use most, including PCs, Macintosh computers, iPhone, Android phones, Blackberry smartphones, Microsoft Windows Mobile®, and Windows® Phones
  • Connect with Microsoft Outlook 2010 or Office Outlook 2007 and use all of the rich Outlook functionality you already know and use, whether you are connected to the Internet at home, or in the office, or you are working offline
  • Access your email, calendar, and contacts from nearly any web browser while enjoying a rich, familiar Outlook experience with Outlook Web App
  • Use your existing domain name to create professional email addresses powered by Exchange Online (for example, mark@contoso.com)
  • Easily schedule meetings by sharing calendars and viewing them side by side, seeing your colleagues’ availability, and suggested meeting times from your calendar
  • Help protect your organization from spam and viruses with Microsoft Forefront® Online Protection for Exchange, which includes multiple filters and virus-scanning engines

2.2 Team Sites and Public Website

Powered by Microsoft SharePoint® Online

SharePoint Online helps you create sites to share documents and information with colleagues and customers. It lets you:

  • Work together effectively by sharing team documents and tracking project milestones to keep everyone in sync
  • Keep your team’s important documents online so the latest versions are always at hand
  • Provide all team members with online access to critical business information whenever and wherever they need it
  • Easily protect critical business information by controlling who can access, read, and share documents and information
  • Market your small business using a simple public-facing website with a custom domain name (for example, www.contoso.com)
  • Publish, share and edit Access database applications on your Team Site

2.3 Office Web Apps

Hosted on Microsoft SharePoint Online

Office Web Apps are convenient online companions to Word, Excel, PowerPoint, and OneNote® that offer you an easy way to access, view, and edit documents directly from your web browser.

  • Work with others simultaneously in Excel spreadsheets and in OneNote notebooks while seeing who is editing what parts of the document
  • Access and view Office documents from your mobile device
  • Ensure that viewers experience great fidelity between documents viewed with the Office Web Apps and those viewed in the desktop Office applications

2.4 Instant Messaging and Online Meetings

Powered by Microsoft Lync Online

Microsoft Lync™ Online helps you find and quickly connect with the right person from within the Office applications you already use.

  • Find and connect with colleagues and customers from virtually anywhere via rich presence, instant messaging (IM), audio/video calls, and online meetings
  • Use the Presence indicator to see when coworkers and partners are online and available
  • Make PC-to-PC audio and video calls with colleagues and customers
  • Conduct rich online meetings—including audio, video, and web conferencing—with people both inside and outside your organization
  • Share your desktop, online whiteboards, and presentations with colleagues and partners inside and outside of your organization
  • Click-to-Communicate with other users of Office 365 and Windows Live™ Messenger

3. Requirements for Using Office 365

3.1 System Requirements

Office 365 works effectively with many combinations of browsers, operating systems, and supporting software. Please refer to System Requirements for Office 365 to view the latest software requirements.

3.2 Using Office Desktop Applications

For the best experience with Office 365, a set of software updates must be applied to each PC. These updates are required for all workstations that use rich clients (such as Microsoft Office 2010) and connect to Office 365 services. To apply these updates, each user should run the Office desktop set-up program, which can be found on the Office 365 home page.

3.3 Using Mobile Devices

You can access the Email, Team Sites, and Instant Messaging capabilities of Office 365 from a variety of phones and mobile devices.

Exchange ActiveSync technology synchronizes mailbox data between mobile devices and Exchange Online, so users can access their email, calendar, contacts, and tasks on the go. Exchange Online also provides better data security features on mobile devices with password enforcement and remote data wiping capabilities.

Team Sites (powered by SharePoint Online) give you a central place to share documents and information with colleagues and customers. Team Sites can render on many devices (including Web-enabled mobile phones) using a simplified text-only format.

The Lync Mobile client lets you send and receive instant messages from your mobile device.Lync Mobile clients are available for the leading smart phone platforms, including Windows Phone, iPhone, Android, and Nokia Symbian.

4. Office 365 Security

Powerful security features from Microsoft help protect your data
with security standards that exceed what many businesses can provide for themselves. With high reliability, disaster recovery capabilities, data centers in multiple locations, and a strict privacy policy, your data is more secure. Availability to the services will be backed with a 99.9-percent uptime, financially backed Service Level Agreement (SLA) when the service is released for general availability. The service includes:

  • Access secure features: Exchange Online is accessed through 128-bit Secure Sockets Layer (SSL) or TLS encryption
  • Intrusion monitoring: Microsoft continuously monitors the Office 365 systems for any unusual or suspicious activity. If Microsoft detects such activity, it investigates and responds appropriately
  • Security audits: Microsoft regularly assesses the Office 365 Services infrastructure to ensure that the latest compliance policies and antivirus signatures are installed, along with high-level configuration settings and required security updates. The Office 365 services have:
    • Achieved ISO 27001 certification
    • Completed SAS70 Type I and II audits
    • Added controls that assist customers in complying with certain regulatory requirements
  • High availability: Office 365 has a 99.9-percent scheduled uptime. If a customer’s service is affected, Office 365 offers a service credit subject to the terms and conditions of the SLA.
  • Business continuity: Redundant network architecture is hosted at geographically dispersed Microsoft data centers to handle unscheduled service outages. Data centers act as backups for each other: If one fails, the affected customers are transferred to another data center with limited interruption of service.

5. Email, Calendar, and Contacts

Powered by Microsoft Exchange Online

Key Features and Benefits

Office 365 messaging services, powered by Exchange Online, provide you with a 25 GB mailbox, contacts, and calendar that is available almost any time and from almost anywhere. Read and reply to your email directly from almost any major smartphone, including iPhone, Android, Nokia, Blackberry, and Windows Phone, or use almost any Macintosh computer or PC.

The following details provide a look at some of the key benefits and capabilities of the messaging services provided by Office 365.

5.1 Access Your Email, Calendar, and Contacts

Microsoft Outlook Web App is a web-based version of Outlook that provides the familiar, rich functionality and experience you are accustomed to from the desktop version of Microsoft Outlook. If you are limited by low bandwidth, Outlook Web App is optimized so it minimizes data and bandwidth use. Cross-browser support for Safari, Firefox, Chrome, and Internet Explorer ensures that wherever you are connected to the Internet—at home, at the office, or on the road—you can access your email through Outlook Web App.

Users can access Outlook Web App from a link on the Office 365 Portal.


Figure 1: Access your email from a broad range of browsers with Outlook Web App

5.2 Functionality of Your Outlook Email, Calendar, and Contacts

Office 365 is the only set of services designed to be fully compatible with Microsoft Outlook. Exchange Online works with Outlook 2010 or Office Outlook 2007, making it easier to use the familiar desktop application.

5.3 Large, Easy-to-Use Mailboxes

Exchange Online provides you with 25 GB of mailbox storage. This removes the need to archive email locally with PST files and allows real-time access to your messages from Outlook, a browser or a mobile device. Emails have a size limit of 25 MB, allowing you to send large files, including videos and PowerPoint slides.

5.4 Professional Email Addresses

Use your existing domain name to create professional email addresses powered by Exchange Online (for example, mark@contoso.com). Adding your domain to Office 365 means that you can have your own domain name on email addresses, Lync Online accounts, distribution lists and your public website. When adding a domain, you can also choose to continue to host your public website with another provider.

5.5 Automatically Update Your Email, Calendar, and Contacts across Devices

You can access your email, contacts, and calendar from mobile devices that incorporate Exchange ActiveSync® technology. These devices maintain a connection with the service, receiving any new or updated emails messages, calendar items, contacts or tasks as soon as they arrive on the service. Mobile access is available from a wide range of
devices including iPhone, Android, Nokia, Blackberry, and Windows Phone.

5.6 See Colleagues’ Availability from Your Outlook Calendar

Exchange Online lets you access a consistent calendar from your multiple devices, share your calendar with people inside and outside your company, view multiple calendars side by side, and use the scheduling assistant to view availability and schedule meetings with people inside and outside your company.

5.7 Antivirus and Anti-Spam Filtering

All messages sent through the Exchange Online service are automatically scanned for viruses and malware to help safeguard your data. Exchange Online uses Forefront Online Protection for Exchange—an enterprise-level email filtering technology—to help protect your incoming and outgoing messages. The service uses proprietary anti-spam technology to help achieve high accuracy rates and uses multiple, complementary antivirus engines. Additionally, internal messages are scanned to protect you from viruses that may be sent through email messages within your organization. Antivirus and anti-spam protections are preconfigured and automatically updated, so there are no steps necessary for setting up, configuring, or maintaining the filtering technology.

5.8 Reduce Inbox Overload with Conversation View

By grouping conversations together, you can view messages in context and narrow the number of relevant messages in your inbox. Messages within the conversation are grouped, no matter where the message exists within the mailbox, which helps you and your employees be more productive.

5.9 Set Out-of-Office Replies

With the Exchange Out-of-office feature, you can see if someone is out of office before sending an email message or scheduling an appointment. You can schedule out-of-office messages in advance with specific start and end times. You can configure separate out-of-office messages for users in your company and for external users such as your customers or partners. Junk email and mailing list awareness prevents external out-of-office messages from being sent to extended mailing lists and spammers. You can also format out-of-office messages as rich HTML messages with hyperlinks rather than as plain text. Exchange Online also gives you the ability to set out-of-office messages from mobile devices that support this Exchange ActiveSync feature.

5.10 Recover Deleted Items

Exchange Online enables you to restore items that have been deleted from any email folder—including the Deleted Items folder—in case you accidentally delete an important item. These items are kept in a Recoverable Items folder for 14 days before being permanently removed. You can recover these items yourself using the Recover Deleted Items feature in Outlook Web App or Outlook.

5.11 Access Other Email Accounts through Office 365

You can connect to as many as five email accounts from Outlook Web App, letting you send, receive, and read email messages from those connected accounts in one place.

  • Windows Live Hotmail: You don’t need to turn on POP or IMAP access for a Windows Live Hotmail® account. If you have folders in your Hotmail account, these folders are copied to your account in Outlook Web App along with the email messages downloaded from your Hotmail account.
  • Gmail: Allow POP access from your Gmail account to download mail from the Gmail account to Outlook Web App.
  • Yahoo Mail Plus, Comcast, AOL: These services give you POP access automatically and don’t support IMAP access.
  • IMAP Access: Outlook Web App supports IMAP access for most services, except Gmail. With IMAP access, your folders and mail items within those folders are downloaded to Outlook Web App the same way you see them in your other account. If your other account allows IMAP access, ensure IMAP access is turned on before you connect to the account.

5.12 Personal Archive

Exchange Online offers archiving through the personal archive capabilities of Exchange 2010 to help you store historical data that you rarely access. A personal archive is a specialized mailbox that appears alongside your primary mailbox folders in Outlook or Outlook Web App similar to a personal folder. You can access the archive in the same way you access your normal mailbox. In addition, you can search both your personal archive and primary mailbox.

Outlook 2010 and Outlook Web App provides you with the full features of the personal archive, as well as related features like retention policies which can help you organize and clean up your mailbox.

Outlook 2007 provides basic support for the personal archive, but not all features are available in Outlook 2007. For example, with Outlook 2007, you cannot apply retention policies to items in your mailbox.

Administrators can use the Exchange Control Panel to enable the personal archive feature for specific users in your company.

Size of the Personal Archive

Each personal archive can only be used to store one person’s messaging data. You receive 25 GB in storage which can be used across both your primary mailbox and personal archive.

Importing Data to the Personal Archive

You can import historical data to personal archives in the following four ways:    

  • Import data from a .pst file using Outlook’s Import and Export wizard
  • Drag email messages from .pst files into the archive
  • Drag email messages from your primary mailbox into the archive
  • Set retention policies to automatically move certain email messages from your primary mailbox, based on the age of the messages

5.13 Additional Features

  • Global Address List: A Global Address List gives companies a common directory of all email-enabled users, distribution groups, and external contacts, helping to ensure that users can access the most recent contact information.
  • Resource Mailboxes: Use Outlook or Outlook Web App to schedule use of shared resources, such as a conference room. After setting up the room alias (ex. ConfRm1@contoso.com), users can reserve the room by adding the conference room email alias to meeting requests.
  • Distribution Groups: Distribution groups make it easy to send messages to multiple people. Unlike personal distribution groups that individuals create in Outlook, these distribution groups are available to all users through their Global Address List in Outlook.
  • Integrated Instant Messaging and Presence: Outlook Web App has instant messaging capabilities integrated into the web client, connected to Lync Online. Using the colorful status indicator of another person, users can see who is online and quickly decide if they should send an e-mail or just fire off a quick IM to get a fast response.
  • Message Delivery Status Reports: Flexible message tracking capability to search for message delivery status on e-mail sent to or from users in Exchange Online. A web-based user interface also allows administrators to search for delivery reports by subject and within the last two weeks.


For a detailed feature summary of Exchange Online, see Appendix A.

6. Team Sites and Public Websites

Powered by Microsoft SharePoint® Online

Key Features and Benefits

Office 365 makes it easy for you to share documents with colleagues, customers, and even trusted business partners. SharePoint Online is designed to work with familiar Office applications. It’s easy to create Office documents and save directly to SharePoint Online or co-author documents with Office Web Apps. Information workers can access important documents offline or from familiar mobile devices and set document-level permissions to protect sensitive content. With one click, it’s possible to communicate in real-time with colleagues and customers from within SharePoint sites.

The following sections provide information about some of the key benefits and capabilities of Team Sites and the public-facing website in Office 365.

6.1 Public-Facing Website

You can easily create a well-designed, public-facing website and apply a custom domain name (for example, www.contoso.com) using the built-in Site Designer tool. The built-in Site Designer tool provides many out-of-the-box templates you can use to personalize your site. Public sites built using SharePoint Online are excellent for small businesses that need a simple and attractive site.

6.2 Manage Important Documents

When a single document has multiple contributors, versioning and control issues can quickly become problematic. SharePoint Online provides your Team Sites with built-in document check-in
and check-out capabilities that work directly in Microsoft Office 2007, Microsoft Office 2010, and Office Professional Plus. In addition, two or more people can co-author a document using Microsoft Office 2010 and Office Professional Plus or Office Web Apps.

SharePoint Online document libraries can be configured so that revision numbers for documents are automatically updated every time a user checks in a document. You can also easily return to any previous version. Document collaboration in SharePoint Online is a well-developed, flexible feature that you can adjust to meet your specific requirements.

6.3 Plenty of Space for Your Documents and Sites

Each subscription to Office 365 comes with a SharePoint Online site collection that can host multiple sub-sites starting with 10 GB of storage plus 500 MB for each subscriber. For example, if you have 10 users, you would have 15 GB total of storage. This is in addition to the 25 GB each user gets for his or her email.

6.4 External Sharing

You can share documents and information easily with trusted business partners. A team site gives your organization a single location to find the latest versions of files or documents. You can access your team sites and the documents they contain from your web browser and your mobile device and work directly with documents from your Office desktop applications. SharePoint Online allows you to share documents and information more securely with colleagues and customers inside or outside your company. Major benefits of SharePoint Online team sites include:

  • Manage and share important documents to help teams work together
  • Track key project milestones and schedules with shared-calendars
  • Create, edit, and review documents and proposals in real-time
  • Share documents and information easily with trusted business partners
  • Manage important meeting notes and project delivery schedules
  • Enable real-time communication with colleagues right from within SharePoint
  • Apply your own unique look and feel to team sites with custom theming and branding

6.5 Microsoft Office Integration

Microsoft Office and SharePoint Online now work better together. In addition to document collaboration and management, new capabilities now enable co-authoring—two or more users can simultaneously work on the same document. With Outlook 2010 or Office Outlook 2007, you can view or edit calendars and contact lists that are stored on SharePoint Online sites and create and manage sites for organizing meetings.

Some highlights of the new functionality in Microsoft Office 2010 and Microsoft Office Professional Plus that interoperate with SharePoint Online include:

  • Backstage View: The Microsoft Office Backstage™ view allows you to manage your documents and related data—you can create, save and send documents, inspect documents for hidden metadata or personal information, and set options such as turning on or off AutoComplete suggestions.
  • Document Co-Authoring: With new co-authoring capabilities, multiple users can edit the same document at the same time, even if they are in different locations. They can even communicate as they work directly from within the desktop application.
  • Outlook: Gain read/write access to SharePoint Online items such as calendars, tasks, contacts, and documents. See complete views of calendars and tasks across multiple lists and sites.
  • Outlook Alerts: You can stay updated on changes to documents and list items on SharePoint sites by receiving notifications of changes as alerts and Really Simple Syndication (RSS).
  • Hosted Access Databases: You can easily publish Access 2010 databases from your desktop up to SharePoint Online using Access Services. You now have a way to create Web-based Access databases that are easily accessible as any other site to your broader peer group.

6.7 Familiar Look and Feel

Microsoft understands the value of keeping a consistent look and feel to its menus across different applications. When using SharePoint Online, you will find the familiar Ribbon featured in Office 2007 and Office 2010. The Ribbon has the features and the functionality you expect, saving you the time and frustration you may experience working with different online services.

Figure 2: Familiar look and feel with the SharePoint Online Ribbon

6.8 Data Is Highly Secure

All documents that you or your colleagues add to SharePoint Online are scanned for malware using multiple scanning engines. You can control who can access your documents stored in your password-protected sites, and you can further control access within SharePoint Online to designate who can view and edit documents and information.


For a detailed feature summary of SharePoint Online, see Appendix B.

7. Office Web Apps

Hosted on Microsoft SharePoint Online

Key Features and Benefits

Office Web Apps help you work with Office documents directly in a browser when you are away from the office or at a shared PC.
Office Web Apps are convenient online companions to Word, Excel, PowerPoint, and OneNote that give you the freedom to view and edit your Office documents from virtually anywhere with a supported browser and to view your documents on a supported mobile device.

The following sections provide information about some of the key benefits and capabilities of Office Web Apps provided by Office 365.

7.1 Never Be without the Tools You Need

If you are away from your office or home, and you find yourself using a computer that doesn’t have Microsoft Office installed, you can use the Office Web Apps to view and edit documents in Word, Excel, PowerPoint, and OneNote. Microsoft SharePoint Online team sites use the Office Web Apps to allow you to access, view, edit, save, and share your stored files from almost any computer with an Internet connection. You can even access and view PowerPoint, Word, and Excel content from a browser on mobile devices.

7.2 Ensure Consistent Document Views

You spend a lot time making your content look its best and you want to know that those who view your content are seeing what you intended. Office Web Apps provides professional, high-fidelity viewing of Word, Excel, PowerPoint, and OneNote files. You can take advantage of the rich features in Microsoft Office on your desktops to create content and then share those files online with great document fidelity and consistent formatting.

7.3 Edit Content with Confidence

When you create documents with Microsoft Office on your desktop, you might use rich content and advanced features such as graphics, images, tables of content, and cross-references to add impact to important information. Keep document formatting intact as you edit between the Office Web Apps and the corresponding desktop application.

7.4 Work Easily with Others

Office Web Apps makes it simple to collaborate on documents with people who use different platforms or different versions of Microsoft Office or simply don’t have Office installed on their computer. When you give someone access to your Office documents on SharePoint Online, they can view Microsoft Office documents through a supported Web browser using the Office Web Apps.


8. Instant Messaging and Online Meetings

Powered by Microsoft Lync Online

Key Features and Benefits

Microsoft Lync Online is a next-generation online communications service that connects people in new ways anytime from virtually anywhere. Lync Online provides rich and intuitive communications capabilities including presence, IM, audio/video calling, and an online meeting experience that supports audio, video, and web conferencing.

Lync Online transforms interactions with colleagues, customers, and partners from today’s hit-and-miss communications to a more collaborative, engaging, and effective experience that can help your business function more efficiently and cost effectively.

The following sections provide information about some of the key benefits and capabilities of Lync Online provided by Office 365.

8.1 Find and Connect with Colleagues and Customers

Businesses often face communications problems because people must repeatedly attempt to reach each other by phone or email. The problem gets worse when people communicate across geographies and time zones. Lync Online enables you to know when a colleague or partner is available to communicate and enables you to choose the proper communications method (IM, audio/video call, and/or data sharing) in order to resolve critical business discussion or make time-sensitive decisions.

Figure 4: Lync Online meeting with PC audio, video conferencing, and screen sharing

8.2 Easily Conduct Professional Online Presentations or Spontaneous Online Meetings

With Lync Online, you can have more effective interactions with colleagues and partners by escalating IM sessions into spontaneous online meetings including audio, video, and screen sharing in just a few clicks. You can also conduct professional online presentations with external customers, partners, and colleagues that include data, video, and audio with the ability to control content, annotate, and use a virtual whiteboard.

External attendees can join online meetings to view or share a screen and IM through a web browser. Alternatively, attendees can download and install the free Lync attendee software, which provides full fidelity PC-audio, video, and content sharing capabilities.

8.3 Interoperability with 3rd Party Dial-in Audio Conferencing Services

Dial-in audio conferencing is the ability to dial into a scheduled Lync meeting/conference from fixed-lines or mobile phones. This capability is not provided natively in Lync Online, but can be achieved through leading third-party audio conferencing services. See the Office 365 marketplace listings for more information about this optional interoperability.

8.4 View Presence Status and Click-to-Communicate In Microsoft Office Applications

Collaborating with others can be challenging if your job requires constant use of business productivity applications. Lync Online connects presence and real-time collaboration capabilities with the Microsoft Outlook messaging and collaboration client. This enables higher productivity by allowing you to collaborate using the familiar programs you and your colleagues already use.

8.5 Communicate with Other Office 365 and Windows Live Users

The federation feature of Lync Online establishes trusted relationships between your organization and one or more external organizations. This allows your people to see user presence and communicate across organizational boundaries. Public IM connectivity (PIC) allows your organization to more securely connect its existing base of enterprise-enabled IM users to trusted contacts using public IM services that can be provided by Windows Live Messenger.

All federated communications are encrypted between the IM systems using access proxy servers. Microsoft does not control encryption after messages are passed to the federated partner’s network (if the partner is federated with an on-premises Lync Server or third-party network).

IM federation requires the consent and proper configuration of both parties of the federation relationship. Once the federation is set up by both sides, users in each company can start seeing presence and communicating with users in the other company. Table 2 shows how federation affects IM, presence, and PC-to-PC audio and video.

Table 2: Federation features by link type


IM and Presence

PC-to-PC Audio and Video

Other companies using Office 365/Lync Online

Yes

Yes

Lync Server 2010 or Office Communications Server on-premises (any version)

Yes

Yes

Windows Live Messenger

Yes

Yes

Works with Office

8.6 Presence with Microsoft Outlook and Other Office Applications

Lync Online can connect presence with Microsoft Office 2007 or Office 2010. You can instantly find and communicate with people from within Office Outlook. This connection occurs wherever you see a colored presence indicator that represents a person’s presence status. You can then click the presence icon and initiate a communications using Lync (this feature is called “click-to-communicate”).

8.7 Presence with Exchange Online

Lync Online connects presence with Exchange Online. This includes presence status in Outlook, presence status changes based on Exchange calendar information, IM, and presence in Outlook Web App, out-of-office messages in the Lync client, and click-to-communicate via Lync Communicator from Outlook.


9. Additional Office 365 Service Details

9.1 Administering Office 365

Office 365 is easy to set up and use. Because it was designed for organizations without IT staff, you can focus on your business rather than learning how to navigate menus and reading unfamiliar technical words. Administration is performed using an intuitive, web-based portal accessible only to those you designate.

As an owner of your organization’s account, you are considered a Global Administrator. Global Administrators can create new user accounts, assign administrative roles to others, and configure the different services included in Office 365. You do not need any special technical expertise to be an administrator for Office 365 for professionals and small businesses.

Figure 5: Office 365 Administration Website


9.2 Getting Help

Customers who purchase Microsoft Office 365 for professionals and small businesses have the Microsoft Office 365 Community (www.community.office365.com) available as the primary way to have technical and billing issues resolved. Telephone support for any technical questions is not provided in the cost of the subscription.

The Office 365 Community

The Microsoft Office 365 Community is a single destination for self-help support information and community discussion. The Microsoft Office 365 Community has the latest information to help customers find answers to a variety of technical, billing and service questions via support forums, wikis, and blogs.

The Office 365 Community is a public website (community.office365.com) and is available 24 hours a day, 7 days a week. The support forums are staffed and moderated by Microsoft Support Agents. Anyone can view and read  the support forums, wikis, and blogs related to Microsoft Office 365. We encourage customers, Microsoft Partners and Microsoft Most Valuable Professionals (MVPs) to engage with the community and contribute to the ongoing discussions. To actively post and reply to discussions within the Community, an individual must register and sign in with a Microsoft Office 365 ID or with a Windows Live™ ID (Hotmail, MSN, Windows Live).

Community Resources

From the Community home page you can access the following resources:

  • Forums are intended to provide Community participants with an online destination where they can post technical support questions and discuss topics related to the Office 365 service. Forums include categories dedicated to each of the individual online services as well as individual topics that our customers find valuable.
  • Wikis include wiki pages created by Microsoft employees and authenticated Community members. This collaborative site encompasses the latest collective content about specific Microsoft Office 365 technical scenarios. Each individual wiki page typically includes links to websites, webcasts, troubleshooting videos, frequently asked questions (FAQ) pages, documents, and downloads about that specific technical scenario. Historical tracking of every revision date and author alias is provided along with the ability to compare versions.
  • Blogs are a good resource for obtaining current information about Microsoft Office 365 online services and for learning about the benefits of Microsoft Office 365 features and functions. Within the Community portal for Microsoft Office 365 are two basic types of blogs: the Microsoft Office 365 Blog and  the Microsoft Office 365 Technical Blog.
  • Microsoft Office 365 Blog focuses on the latest news and product information about Microsoft Office 365. The target audience is people interested in Microsoft Office 365. Sample topics include product insights, new product announcements, customer interviews, and a guest blog series.
  • Microsoft Office 365 Technical Blog helps existing customers with technical tasks or in troubleshooting common issues. The target audience consists of people using, selling, supporting, and developing applications for Microsoft Office 365. Sample topics include troubleshooting videos, technical webcasts, announcements about product feature updates, and showcasing of Microsoft partner technical solutions.


Help with Your Bill

Although community is the primary support vehicle for Office 365 for professionals and small businesses, customers can get help with billing issues by submitting a ticket from the Support Overview page in the Office 365 portal.  Customer billing support will respond as appropriate depending on the severity of the issue by calling the customer, e-mailing FAQs, or pointing to community support.

9.3 Additional Self-help Resources

Virtual Support Agent

The Virtual Support Agent is an automated support agent that provides online support around the clock, interacting in a natural, conversational style. It is located on the Microsoft Office 365 Support Overview page. Customers use a text-chat interface to type questions in their own words and receive immediate responses. The automated agent has access to a variety of databases built on current content about Microsoft Office 365.

Technical Support Videos

The growing library of English-language-only instructional troubleshooting videos has been developed based on the most commonly asked questions from customers.

To view these videos, go to the Community site and search for videos. Customers are encouraged to submit a request for a video through the Community portal. Customers can also navigate to the Microsoft Office 365 YouTube and Showcase channels.

Learn Through Social Media

Following Microsoft Office 365 on Facebook, Twitter, and LinkedIn provides a way for customers and partners to become more educated about Microsoft Office 365. This fast and easy way of learning about Microsoft Office 365 allows customers to listen to what others are saying and be able to add their own comments and tweets. Microsoft support professionals monitor the Microsoft-related Facebook and Twitter activity to assist with any support-related inquiries.

To find the most current Facebook feeds along with the most recent Tweets, go to the bottom of the Community home page to hear the daily discussions among customers and partners.

9.4 Countries Where Office 365 (Plan P1) Is Available

Office 365 is available in 38 countries: Australia, Austria, Belgium, Canada, Colombia, Costa Rica, Cyprus, Czech Republic, Denmark, Finland, France, Germany, Greece, Hong Kong, Hungary, India, Ireland, Israel, Italy, Japan, Luxembourg, Malaysia, Mexico, Netherlands, New Zealand, Norway, Peru, Poland, Portugal, Puerto Rico, Romania, Singapore, Spain, Sweden, Switzerland, Trinidad & Tobago, United States, and UK.

9.5 Languages

Table 3 summarizes the languages supported the Office 365 platform and related components.

Table 3: Supported languages for components related to Office 365

Component

Supported languages

Office 365 Portal

English, Japanese, German, French, Italian, traditional Chinese, simplified Chinese, Danish, Dutch, Finnish, Norwegian (Bokmal), Spanish, Swedish, Brazilian, Portuguese, Czech, Greek, Hungarian, Polish, Romanian

Help content

English, Japanese, German, French, Italian, traditional Chinese, simplified Chinese, Danish, Dutch, Finnish, Norwegian (Bokmal), Spanish Swedish, Brazilian, Portuguese, Czech, Greek, Hungarian, Polish, Romanian

Community

English, Japanese, German, French, Italian, Spanish, traditional Chinese, Korean, Russian

Office desktop set up

English, Japanese, German, French, Italian, traditional Chinese, simplified Chinese, Danish, Dutch, Finnish, Norwegian (Bokmal), Spanish Swedish, Brazilian, Portuguese, Czech, Greek, Hungarian, Polish, Romanian


9.6 Licensing

Office 365 for professionals and small businesses (Plan P1) is designed for 1 to 25 users, but you may purchase up to 50 users. You can add or remove users at any time, but you cannot add more than 50 users.

Office 365 for professionals and small businesses is not available under Microsoft Volume Licensing. Subscriptions are available on a month-to-month basis and automatically renew each month. You can cancel at any time with no early termination fee.

Office Professional Plus can be licensed separately from Office 365 for professionals and small businesses.

9.7 Buying your Office 365 Subscription

Office 365 for professionals and small businesses gives you the option to sign up for a 30 day trial period or to sign up for a paid subscription. Before signing up, you will be required to sign the Microsoft Online Subscription Agreement (MOSA).

The trial is a free period so you can experience Office 365 without having to purchase a subscription. The trial provides the full functionality of Plan P, with the exception that it is limited to 10 users. Customers have a couple of options at the end or during the trial period:

  • Convert an existing trial to paid subscription: If you choose to convert your trial subscription to a paid subscription of the same plan, end users on your trial subscription are automatically transferred (with their data) to the paid subscription.

    Figure 6: Click from within Office 365 to purchase during the 30-day trial period

  • Purchase a new paid subscription: If you choose to purchase a new paid subscription unrelated (different plan) to your trial subscription, you will need to manually assign users to the paid subscription. Purchasing a new paid subscription will not automatically move their data.

Your subscription term will begin on the day you convert to or purchase the paid plan subscription. Your first bill will occur on the first day of your subscription and subsequent bills will occur on the same day of each subsequent month. Your subscription will auto-renew each month unless you cancel.


Canceling your Office 365 Subscription

You can cancel your Office 365 subscription at any time without a penalty. Cancelation is available through the portal under the manage subscriptions tab.

After cancelation the subscription/service is in an active state until the end of the month. At the end of the month that the subscription is canceled, the account enters a 7-day grace period. During the grace period, a warning message is displayed in the portal but end users can continue to access the service. After the 7-day grace period the service goes into a 90-day disabled state. During the disabled state the end users cannot access the service. The administrator can access the service and retrieve data.

Visit www.Office365.com for the latest pricing information.

9.8 Microsoft Office 365 Marketplace

The Microsoft Office 365 Marketplace is specifically designed to help customers find trusted Microsoft Office 365 experts as well as applications and services that enhance and easily integrate with the Microsoft Office 365 suite of products. For example, customers can find a partner to purchase a custom domain to associate with their Office 365 website and email or audio conferencing providers to add dial-in phone numbers to Lync online meetings. Partners can also help migrate data and set up Office 365 services, so customers can get up and running more quickly.

Visit the Microsoft Office 365 Marketplace at http://office365.pinpoint.microsoft.com.

9.9 Service Level Agreement

Microsoft Online Services guarantees 99.9 percent uptime for all paid Office 365 subscriptions. These service levels are financially backed. That means, if Microsoft does not meet the terms of the Service Level Agreement (SLA), you are eligible to receive service credits equal to a percentage off your total monthly bill.

The following are the service credit tiers for SLA violation:

Monthly Uptime Percentage

Service Credit

< 99.9%

25%

< 99%

50%

< 95%

100%


9.10 Data Center Locations

Microsoft data centers are strategically located throughout the world to provide more secure and seamless, around-the-clock access to your data. Data is replicated to a secondary backup data center within the region to help protect against failures across entire data centers. When your company signs up for Office 365, its hosted environment is automatically provisioned in the appropriate data center based on your company’s address. All users for the company are hosted from the same region.

Appendix A: Exchange Online Detailed Feature Summary

This section presents overviews of Exchange Online features and specifications.

Feature

Description        

Mailbox size

25 GB

Message size limits (max email size)

25 MB

Recipient limits

1500 recepients/day for each cloud-based mailbox

Deleted item recovery

14 Days

Deleted mailbox recovery

30 Days

CLIENT ACCESS


Outlook 2010 support

Yes

Office Outlook 2007 support

Yes

Outlook Anywhere (RPC over HTTPS)

Yes

Outlook Web App Premium experience

Internet Explorer 7+, Safari 3+, Firefox, Chrome

Outlook Web App Light experience

Most other browsers not supported in the Outlook Web App Premium experience

Outlook Web App: session time-out

6 hours

WebReady document viewing

Yes

Instant messaging and presence integrated into web email client

Yes, with Lync Online

Macintosh support (rich client)

Outlook 2011 for Mac

IMAP

Yes

POP

Yes

MOBILITY


Mobile Devices

Windows Mobile and Windows Phone, Nokia E and N series devices, Palm devices, Apple iPhone and iPad, and Blackberry (using Blackberry Internet Service)

Remote device wipe (implementation varies by mobile device manufacturer)

Yes

Disable Exchange ActiveSync access

Yes

Mobile device allow/block/quarantine

Yes

Mobile SMS sync (through Exchange ActiveSync)

Yes

SMS (text messaging) notifications

Yes

EMAIL/INBOX


“Send on behalf of” and “send as”

Yes

Shared mailboxes

Yes

Inbox rules

Yes

Tasks

Yes

Conversation view and actions (such as ignore conversation)

Yes

Connected accounts (aggregate mail from multiple external email accounts)

Yes

CONTACTS/DIRECTORY


Personal contacts

Yes

Personal distribution groups

Yes

Offline Address Book

No

Global Address List (GAL) photos

Yes

External contacts (in GAL)

Yes

CALENDAR


Out-of-office auto replies

Yes

Federated calendar sharing

Yes

Side-by-side calendar view in web client

Yes

SECURITY


Anti-spam (AS)

Forefront Online Protection for Exchange

Antivirus (AV)

Forefront Online Protection for Exchange AV for inbound/oubound, Forefront AV internal

COMPLIANCE/ARCHIVING


Disclaimers

No

Personal archive

Yes

ADMINISTRATION


Administration through a web-based interface (Exchange Control Panel)

Yes

APPLICATION ACCESS/CUSTOMIZATION


Application connectivity through web services

Yes

SMTP relay

Yes

Outlook Web App Web Parts

Yes

Outlook add-ins and Outlook MAPI

Yes


Appendix B: SharePoint Online Detailed Feature Summary

This section presents overviews of SharePoint Online features and specifications.

SharePoint Online feature overview

Feature

Description


Storage

10 GB with additional 500 MB per user

Buy additional storage

No

Max Org Users

50

Partner Access Licenses (External Sharing)

Yes – up to 500 external users/month

File upload limit

250 MB

Works with Microsoft Office 2010

Access 2010

Excel 2010

Outlook 2010

OneNote 2010

PowerPoint 2010

Microsoft SharePoint Designer 2010

Word 2010

SharePoint Workspace 2010

Browser support

Internet Explorer 7

Internet Explorer 8

Firefox 3

Safari 3.1.2 on Macintosh OS X 10.5

Mobile device support

Windows Mobile 6.5.x

Nokia E series and N series devices

Apple iPhone 2.0

Team Sites

Yes

Simple Public-Facing Website

Basic public site included, vanity URLs (custom domains) are supported

Site Designer

Yes

Sandbox Solutions (Partially Trusted Code)

Yes

Access Services

Yes

Office Web Apps

Available (both read and write access); View only for invited external users


Features of Microsoft SharePoint

Feature

Access Services

Accessibility

Audience Targeting

Basic Sorting

Best Bets

Blogs

Browser-Based Customizations

Client Object Model (OM)

Cross-Browser Support

Discussions

Duplicate Detection

Enterprise Scale Search

External Sharing – Partner Access

Improved Governance

Integration with Lync Online and Exchange Online

Language Integrated Query (LINQ) for SharePoint

Large List Scalability and Management

Microsoft Visual Studio® 2010 SharePoint Developer Tools (to build and package Sandbox Solutions)

Mobile Connectivity & Search

Multilingual User Interface

Multiple Team Site Templates

Office and Office Web Apps intergation

Out-of-the-Box Web Parts

Permissions Management

Phonetics and Nickname Search

Photos and Presence

Recently Authored Content

Ribbon and Dialog Framework

Sandboxed Solutions

Search Scopes

Service Application Platform

SharePoint Designer

SharePoint Lists

SharePoint Ribbon and Fluent UI

SharePoint Service Architecture

SharePoint Workspace

Silverlight Web Part

Simple Public-Facing Website

Single Site Collection Search

Support for Accessibility Standards

View in Browser within Search Results

Wikis

Windows 7 Support

Workflow

Workflow Models

Enterprise-oriented SharePoint capabilities such as My Sites, Custom-code Workflows, InfoPath Forms Services, Excel Services, Visio Services, Business Connectivity Services, Advanced Web Analytics, and full-trust code are not included in Office 365 Plan P1.


PATTERNS OF PARALLEL PROGRAMMING

PATTERNS OF PARALLEL PROGRAMMING


UNDERSTANDING AND APPLYING PARALLEL PATTERNS

WITH THE .NET FRAMEWORK 4 AND VISUAL C#


Stephen Toub

Parallel Computing Platform

Microsoft Corporation


Abstract


This document provides an in-depth tour of support in the Microsoft® .NET Framework 4 for parallel programming.

This includes an examination of common parallel patterns and how they’re implemented without and with this

new support, as well as best practices for developing parallel components utilizing parallel patterns.


Last Upd ated:


July 1, 2010


This material is provided for informational purposes only. Microsoft makes no warranties, express or implied.

©2010 Microsoft Corporation.


T A B L E O F C O N T E N T S


Introduction ……………………………………………………………………………………………………………………………………………….3

Delightfully Parallel Loops ……………………………………………………………………………………………………………………………4

Fork/Join ………………………………………………………………………………………………………………………………………………….36

Passing Data……………………………………………………………………………………………………………………………………………..49

Producer/Consumer ………………………………………………………………………………………………………………………………….53

Aggregations …………………………………………………………………………………………………………………………………………….67

MapReduce………………………………………………………………………………………………………………………………………………75

Dependencies …………………………………………………………………………………………………………………………………………..77

Data Sets of Unknown Size …………………………………………………………………………………………………………………………88

Speculative Processing ………………………………………………………………………………………………………………………………94

Laziness ……………………………………………………………………………………………………………………………………………………97

Shared State …………………………………………………………………………………………………………………………………………..105

Conclusion ……………………………………………………………………………………………………………………………………………..118


Patterns of Parallel Programming Page 2


I N T R O D U C T I O N I N T R O D U C T I O N

Patterns are everywhere, yielding software development best practices and helping to seed new generations of

developers with immediate knowledge of established directions on a wide array of problem spaces. Patterns

represent successful (or in the case of anti-patterns, unsuccessful) repeated and common solutions developers

have applied time and again in particular architectural and programming domains. Over time, these tried and true

practices find themselves with names, stature, and variations, helping further to proliferate their application and

to jumpstart many a project.


Patterns don’t just manifest at the macro level. Whereas design patterns typically cover architectural structure or

methodologies, coding patterns and building blocks also emerge, representing typical ways of implementing a

specific mechanism. Such patterns typically become ingrained in our psyche, and we code with them on a daily

basis without even thinking about it. These patterns represent solutions to common tasks we encounter

repeatedly.


Of course, finding good patterns can happen only after many successful and failed attempts at solutions. Thus for

new problem spaces, it can take some time for them to gain a reputation. Such is where our industry lies today

with regards to patterns for parallel programming. While developers in high-performance computing have had to

develop solutions for supercomputers and clusters for decades, the need for such experiences has only recently

found its way to personal computing, as multi-core machines have become the norm for everyday users. As we

move forward with multi-core into the manycore era, ensuring that all software is written with as much parallelism

and scalability in mind is crucial to the future of the computing industry. This makes patterns in the parallel

computing space critical to that same future.


“In general, a ‘multi-core’ chip refers to eight or fewer homogeneous cores in one

microprocessor package, whereas a ‘manycore’ chip has more than eight possibly

heterogeneous cores in one microprocessor package. In a manycore system, all cores

share the resources and services, including memory and disk access, provided by the

operating system.” –The Manycore Shift, (Microsoft Corp., 2007)


In the .NET Framework 4, a slew of new support has been added to handle common needs in parallel

programming, to help developers tackle the difficult problem that is programming for multi-core and manycore.

Parallel programming is difficult for many reasons and is fraught with perils most developers haven’t had to

experience. Issues of races, deadlocks, livelocks, priority inversions, two-step dances, and lock convoys typically

have no place in a sequential world, and avoiding such issues makes quality patterns all the more important. This

new support in the .NET Framework 4 provides support for key parallel patterns along with building blocks to help

enable implementations of new ones that arise.


To that end, this document provides an in-depth tour of support in the .NET Framework 4 for parallel

programming, common parallel patterns and how they’re implemented without and with this new support, and

best practices for developing parallel components in this brave new world.


This document only minimally covers the subject of asynchrony for scalable, I/O-bound applications: instead, it

focuses predominantly on applications of CPU-bound workloads and of workloads with a balance of both CPU and

I/O activity. This document also does not cover Visual F# in Visual Studio 2010, which includes language-based

support for several key parallel patterns.


Patterns of Parallel Programming Page 3


D E L I G H T F U L L Y P A R A L L E L L O O P S D E L I G H T F U L L Y P A R A L L E L L O O P S

Arguably the most well-known parallel pattern is that befitting “Embarrassingly Parallel” algorithms. Programs that

fit this pattern are able to run well in parallel because the many individual operations being performed may

operate in relative independence, with few or no dependencies between operations such that they can be carried

out in parallel efficiently. It’s unfortunate that the “embarrassing” moniker has been applied to such programs, as

there’s nothing at all embarrassing about them. In fact, if more algorithms and problem domains mapped to the

embarrassing parallel domain, the software industry would be in a much better state of affairs. For this reason,


many folks have started using alternative names for this pattern, such as “conveniently parallel,” “pleasantly

parallel,” and “delightfully parallel,” in order to exemplify the true nature of these problems. If you find yourself

trying to parallelize a problem that fits this pattern, consider yourself fortunate, and expect that your

parallelization job will be much easier than it otherwise could have been, potentially even a “delightful” activity.


A significant majority of the work in many applications and algorithms is done through loop control constructs.

Loops, after all, often enable the application to execute a set of instructions over and over, applying logic to

discrete entities, whether those entities are integral values, such as in the case of a for loop, or sets of data, such

as in the case of a for each loop. Many languages have built-in control constructs for these kinds of loops,

Microsoft Visual C#® and Microsoft Visual Basic® being among them, the former with for and foreach keywords,

and the latter with For and For Each keywords. For problems that may be considered delightfully parallel, the

entities to be processed by individual iterations of the loops may execute concurrently: thus, we need a

mechanism to enable such parallel processing.


I M P L E M E N T I N G A P A R A L L E L L O O P I N G C O N S T R U C T


As delightfully parallel loops are such a predominant pattern, it’s really important to understand the ins and outs

of how they work, and all of the tradeoffs implicit to the pattern. To understand these concepts further, we’ll build

a simple parallelized loop using support in the .NET Framework 3.5, prior to the inclusion of the more

comprehensive parallelization support introduced in the .NET Framework 4.


First, we need a signature. To parallelize a for loop, we’ll implement a method that takes three parameters: a

lower-bound, an upper-bound, and a delegate for the loop body that accepts as a parameter an integral value to

represent the current iteration index (that delegate will be invoked once for each iteration). Note that we have

several options for the behavior of these parameters. With C# and Visual Basic, the vast majority of for loops are

written in a manner similar to the following:


C#


for (int i = 0; i < upperBound; i++)

{


// … loop body here


}


Visual Basic


For i As Integer = 0 To upperBound


‘ … loop body here


Next


Contrary to what a cursory read may tell you, these two loops are not identical: the Visual Basic loop will execute

one more iteration than will the C# loop. This is because Visual Basic treats the supplied upper-bound as inclusive,


Patterns of Parallel Programming Page 4


whereas we explicitly specified it in C# to be exclusive through our use of the less-than operator. For our purposes

here, we’ll follow suit to the C# implementation, and we’ll have the upper-bound parameter to our parallelized

loop method represent an exclusive upper-bound:


C#


public static void MyParallelFor(

int inclusiveLowerBound, int exclusiveUpperBound, Action<int> body);


Our implementation of this method will invoke the body of the loop once per element in the range

[inclusiveLowerBound,exclusiveUpperBound), and will do so with as much parallelization as it can muster. To

accomplish that, we first need to understand how much parallelization is possible.


Wisdom in parallel circles often suggests that a good parallel implementation will use one thread per core. After

all, with one thread per core, we can keep all cores fully utilized. Any more threads, and the operating system will

need to context switch between them, resulting in wasted overhead spent on such activities; any fewer threads,


and there’s no chance we can take advantage of all that the machine has to offer, as at least one core will be


guaranteed to go unutilized. This logic has some validity, at least for certain classes of problems. But the logic is

also predicated on an idealized and theoretical concept of the machine. As an example of where this notion may

break down, to do anything useful threads involved in the parallel processing need to access data, and accessing

data requires trips to caches or main memory or disk or the network or other stores that can cost considerably in

terms of access times; while such activities are in flight, a CPU may be idle. As such, while a good parallel

implementation may assume a default of one-thread-per-core, an open mindedness to other mappings can be

beneficial. For our initial purposes here, however, we’ll stick with the one-thread-per core notion.


With the .NET Framework, retrieving the number of logical processors is achieved

using the System.Environment class, and in particular its ProcessorCount property.

Under the covers, .NET retrieves the corresponding value by delegating to the

GetSystemInfo native function exposed from kernel32.dll.


This value doesn’t necessarily correlate to the number of physical processors or even

to the number of physical cores in the machine. Rather, it takes into account the

number of hardware threads available. As an example, on a machine with two

sockets, each with four cores, each with two hardware threads (sometimes referred

to as hyperthreads), Environment.ProcessorCount would return 16.


Starting with Windows 7 and Windows Server 2008 R2, the Windows operating

system supports greater than 64 logical processors, and by default (largely for legacy

application reasons), access to these cores is exposed to applications through a new

concept known as “processor groups.” The .NET Framework does not provide

managed access to the processor group APIs, and thus Environment.ProcessorCount

will return a value capped at 64 (the maximum size of a processor group), even if the

machine has a larger number of processors. Additionally, in a 32-bit process,

ProcessorCount will be capped further to 32, in order to map well to the 32-bit mask

used to represent processor affinity (a requirement that a particular thread be

scheduled for execution on only a specific subset of processors).


Patterns of Parallel Programming Page 5


Once we know the number of processors we want to target, and hence the number of threads, we can proceed to

create one thread per core. Each of those threads will process a portion of the input range, invoking the supplied

Action<int> delegate for each iteration in that range. Such processing requires another fundamental operation of

parallel programming, that of data partitioning. This topic will be discussed in greater depth later in this document;

suffice it to say, however, that partitioning is a distinguishing concept in parallel implementations, one that

separates it from the larger, containing paradigm of concurrent programming. In concurrent programming, a set of

independent operations may all be carried out at the same time. In parallel programming, an operation must first

be divided up into individual sub-operations so that each sub-operation may be processed concurrently with the

rest; that division and assignment is known as partitioning. For the purposes of this initial implementation, we’ll

use a simple partitioning scheme: statically dividing the input range into one range per thread.


Here is our initial implementation:


C#


public static void MyParallelFor(

int inclusiveLowerBound, int exclusiveUpperBound, Action<int> body)

{


// Determine the number of iterations to be processed, the number of

// cores to use, and the approximate number of iterations to process

// in each thread.


int size = exclusiveUpperBound -inclusiveLowerBound;

int numProcs = Environment.ProcessorCount;

int range = size / numProcs;


// Use a thread for each partition. Create them all,

// start them all, wait on them all.


var threads = new List<Thread>(numProcs);

for (int p = 0; p < numProcs; p++)

{


int start = p * range + inclusiveLowerBound;

int end = (p == numProcs -1) ?

exclusiveUpperBound : start + range;

threads.Add(new Thread(() => {

for (int i = start; i < end; i++) body(i);


}));

}

foreach (var thread in threads) thread.Start();

foreach (var thread in threads) thread.Join();


}


There are several interesting things to note about this implementation. One is that for each range, a new thread is

utilized. That thread exists purely to process the specified partition, and then it terminates. This has several

positive and negative implications. The primary positive to this approach is that we have dedicated threading

resources for this loop, and it is up to the operating system to provide fair scheduling for these threads across the

system. This positive, however, is typically outweighed by several significant negatives. One such negative is the

cost of a thread. By default in the .NET Framework 4, a thread consumes a megabyte of stack space, whether or

not that space is used for currently executing functions. In addition, spinning up a new thread and tearing one

down are relatively costly actions, especially if compared to the cost of a small loop doing relatively few iterations

and little work per iteration. Every time we invoke our loop implementation, new threads will be spun up and torn

down.


Patterns of Parallel Programming Page 6


There’s another, potentially more damaging impact: oversubscription. As we move forward in the world of multicore

and into the world of manycore, parallelized components will become more and more common, and it’s quite


likely that such components will themselves be used concurrently. If such components each used a loop like the


above, and in doing so each spun up one thread per core, we’d have two components each fighting for the

machine’s resources, forcing the operating system to spend more time context switching between components.

Context switching is expensive for a variety of reasons, including the need to persist details of a thread’s execution

prior to the operating system context switching out the thread and replacing it with another. Potentially more

importantly, such context switches can have very negative effects on the caching subsystems of the machine.

When threads need data, that data needs to be fetched, often from main memory. On modern architectures, the

cost of accessing data from main memory is relatively high compared to the cost of running a few instructions over

that data. To compensate, hardware designers have introduced layers of caching, which serve to keep small

amounts of frequently-used data in hardware significantly less expensive to access than main memory. As a thread

executes, the caches for the core on which it’s executing tend to fill with data appropriate to that thread’s

execution, improving its performance. When a thread gets context switched out, the caches will shift to containing

data appropriate to that new thread. Filling the caches requires more expensive trips to main memory. As a result,

the more context switches there are between threads, the more expensive trips to main memory will be required,

as the caches thrash on the differing needs of the threads using them. Given these costs, oversubscription can be a

serious cause of performance issues. Luckily, the new concurrency profiler views in Visual Studio 2010 can help to

identify these issues, as shown here:


In this screenshot, each horizontal band represents a thread, with time on the x-axis. Green is execution time, red

is time spent blocked, and yellow is time where the thread could have run but was preempted by another thread .

The more yellow there is, the more oversubscription there is hurting performance.


To compensate for these costs associated with using dedicated threads for each loop, we can resort to pools of

threads. The system can manage the threads in these pools, dispatching the threads to access work items queued

for their processing, and then allowing the threads to return to the pool rather than being torn down. This

addresses many of the negatives outlined previously. As threads aren’t constantly being created and torn down,

the cost of their life cycle is amortized over all the work items they process. Moreover, the manager of the thread

pool can enforce an upper-limit on the number of threads associated with the pool at any one time, placing a limit

on the amount of memory consumed by the threads, as well as on how much oversubscription is allowed.


Ever since the .NET Framework 1.0, the System.Threading.ThreadPool class has provided just such a thread pool,

and while the implementation has changed from release to release (and significantly so for the .NET Framework 4),

the core concept has remained constant: the .NET Framework maintains a pool of threads that service work items

provided to it. The main method for doing this is the static QueueUserWorkItem. We can use that support in a

revised implementation of our parallel for loop:


Patterns of Parallel Programming Page 7


C#


public static void MyParallelFor(


int inclusiveLowerBound, int exclusiveUpperBound, Action<int> body)


{


// Determine the number of iterations to be processed, the number of


// cores to use, and the approximate number of iterations to process in


// each thread.


int size = exclusiveUpperBound -inclusiveLowerBound;


int numProcs = Environment.ProcessorCount;


int range = size / numProcs;


// Keep track of the number of threads remaining to complete.


int remaining = numProcs;


using (ManualResetEvent mre = new ManualResetEvent(false))


{


// Create each of the threads.


for (int p = 0; p < numProcs; p++)


{


int start = p * range + inclusiveLowerBound;


int end = (p == numProcs -1) ?


exclusiveUpperBound : start + range;


ThreadPool.QueueUserWorkItem(delegate {


for (int i = start; i < end; i++) body(i);


if (Interlocked.Decrement(ref remaining) == 0) mre.Set();


});


}


// Wait for all threads to complete.


mre.WaitOne();


}

}


This removes the inefficiencies in our application related to excessive thread creation and tear down, and it

minimizes the possibility of oversubscription. However, this inefficiency was just one problem with the

implementation: another potential problem has to do with the static partitioning we employed. For workloads that

entail the same approximate amount of work per iteration, and when running on a relatively “quiet”

machine

(meaning a machine doing little else besides the target workload), static partitioning represents an effective and

efficient way to partition our data set. However, if the workload is not equivalent for each iteration, either due to

the nature of the problem or due to certain partitions completing more slowly due to being preempted by other

significant work on the system, we can quickly find ourselves with a load imbalance. The pattern of a loadimbalance

is very visible in the following visualization as rendered by the concurrency profiler in Visual Studio

2010.


Patterns of Parallel Programming Page 8


In this output from the profiler, the x-axis is time and the y-axis is the number of cores utilized at that time in the

application’s executions. Green is utilization by our application, yellow is utilization by another application, red is

utilization by a system process, and grey is idle time. This trace resulted from the unfortunate assignment of

different amounts of work to each of the partitions; thus, some of those partitions completed processing sooner

than the others. Remember back to our assertions earlier about using fewer threads than there are cores to do

work? We’ve now degraded to that situation, in that for a portion of this loop’s execution, we were executing with

fewer cores than were available.


By way of example, let’s consider a parallel loop from 1 to 12 (inclusive on both ends), where each iteration does N

seconds of work with N defined as the loop iteration value (that is, iteration #1 will require 1 second of

computation, iteration #2 will require two seconds, and so forth). All in all, this loop will require ((12*13)/2) == 78

seconds of sequential processing time. In an ideal loop implementation on a dual core system, we could finish this

loop’s processing in 39 seconds. This could be accomplished by having one core process iterations 6, 10, 11, and

12, with the other core processing the rest of the iterations.


123456789101112

However, with the static partitioning scheme we’ve employed up until this point, one core will be assigned the

range [1,6] and the other the range [7,12].


123456789101112

Patterns of Parallel Programming Page 9


As such, the first core will have 21 seconds worth of work, leaving the latter core 57 seconds worth of work. Since


the loop isn’t finished until all iterations have been processed, our loop’s processing time is limited by the


maximum processing time of each of the two partitions, and thus our loop completes in 57 seconds instead of the

aforementioned possible 39 seconds. This represents an approximate 50 percent decrease in potential

performance, due solely to an inefficient partitioning. Now you can see why partitioning has such a fundamental

place in parallel programming.


Different variations on static partitioning are possible. For example, rather than assigning ranges, we could use a

form of round-robin, where each thread has a unique identifier in the range [0,# of threads), and where each


thread processes indices from the loop where the index mod the number of threads matches the thread’s


identifier. For example, with the iteration space [0,12) and with four threads, thread #0 would process iteration

values 0, 3, 6, and 9; thread #1 would process iteration values 1, 4, 7, and 10; and so on. If we were to apply this

kind of round-robin partitioning to the previous example, instead of one thread taking 21 seconds and the other

taking 57 seconds, one thread would require 36 seconds and the other 42 seconds, resulting in a much smaller

discrepancy from the optimal runtime of 38 seconds.


123456789101112

To do the best static partitioning possible, you need to be able to accurately predict ahead of time how long all the

iterations will take. That’s rarely feasible, resulting in a need for a more dynamic partitioning, where the system

can adapt to changing workloads quickly. We can address this by shifting to the other end of the partitioning

tradeoffs spectrum, with as much load-balancing as possible.


Spectrum of Partitioning

TradeoffsFully

StaticFully

DynamicMore Load-BalancingLess Synchronization

To do that, rather than pushing to each of the threads a given set of indices to process, we can have the threads

compete for iterations. We employ a pool of the remaining iterations to be processed, which initially starts filled

with all iterations. Until all of the iterations have been processed, each thread goes to the iteration pool, removes

an iteration value, processes it, and then repeats. In this manner, we can achieve in a greedy fashion an

approximation for the optimal level of load-balancing possible (the true optimum could only be achieved with a

priori knowledge of exactly how long each iteration would take). If a thread gets stuck processing a particular long

iteration, the other threads will compensate by processing work from the pool in the meantime. Of course, even

with this scheme you can still find yourself with a far from optimal partitioning (which could occur if one thread

happened to get stuck with several pieces of work significantly larger than the rest), but without knowledge of how

much processing time a given piece of work will require, there’s little more that can be done.


Patterns of Parallel Programming Page 10


Here’s an example implementation that takes load-balancing to this extreme. The pool of iteration values is

maintained as a single integer representing the next iteration available, and the threads involved in the processing

“remove items” by atomically incrementing this integer:


C#


public static void MyParallelFor(

int inclusiveLowerBound, int exclusiveUpperBound, Action<int> body)

{


// Get the number of processors, initialize the number of remaining

// threads, and set the starting point for the iteration.


int numProcs = Environment.ProcessorCount;

int remainingWorkItems = numProcs;


int nextIteration = inclusiveLowerBound;


using (ManualResetEvent mre = new ManualResetEvent(false))

{


// Create each of the work items.


for (int p = 0; p < numProcs; p++)


{

ThreadPool.QueueUserWorkItem(delegate

{


int index;


while ((index = Interlocked.Increment(

ref nextIteration) -1) < exclusiveUpperBound)


{


body(index);

}

if (Interlocked.Decrement(ref remainingWorkItems) == 0)


mre.Set();

});

}


// Wait for all threads to complete.


mre.WaitOne();

}

}


This is not a panacea, unfortunately. We’ve gone to the other end of the spectrum, trading quality load-balancing

for additional overheads. In our previous static partitioning implementations, threads were assigned ranges and

were then able to process those ranges completely independently from the other threads. There was no need to

synchronize with other threads in order to determine what to do next, because every thread could determine

independently what work it needed to get done. For workloads that have a lot of work per iteration, the cost of

synchronizing between threads so that each can determine what to do next is negligible. But for workloads that do

very little work per iteration, that synchronization cost can be so expensive (relatively) as to overshadow the actual

work being performed by the loop. This can make it more expensive to execute in parallel than to execute serially.


Consider an analogy: shopping with some friends at a grocery store. You come into

the store with a grocery list, and you rip the list into one piece per friend, such that

every friend is responsible for retrieving the elements on his or her list. If the amount

of time required to retrieve the elements on each list is approximately the same as on

every other list, you’ve done a good job of partitioning the work amongst your team,

and will likely find that your time at the store is significantly less than if you had done


Patterns of Parallel Programming Page 11


all of the shopping yourself. But now suppose that each list is not well balanced, with

all of the items on one friend’s list spread out over the entire store, while all of the

items on another friend’s list are concentrated in the same aisle. You could address

this inequity by assigning out one element at a time. Every time a friend retrieves a

food item, he or she brings it back to you at the front of the store and determines in

conjunction with you which food item to retrieve next. If a particular food item takes

a particularly long time to retrieve, such as ordering a custom cut piece of meat at

the deli counter, the overhead of having to go back and forth between you and the

merchandise may be negligible. For simply retrieving a can from a shelf, however, the

overhead of those trips can be dominant, especially if multiple items to be retrieved

from a shelf were near each other and could have all been retrieved in the same trip

with minimal additional time. You could spend so much time (relatively) parceling out

work to your friends and determining what each should buy next that it would be

faster for you to just grab all of the food items in your list yourself.


Of course, we don’t need to pick one extreme or the other. As with most patterns, there are variations on themes.

For example, in the grocery store analogy, you could have each of your friends grab several items at a time, rather

than grabbing one at a time. This amortizes the overhead across the size of a batch, while still having some amount

of dynamism:


C#


public static void MyParallelFor(

int inclusiveLowerBound, int exclusiveUpperBound, Action<int> body)

{


// Get the number of processors, initialize the number of remaining

// threads, and set the starting point for the iteration.


int numProcs = Environment.ProcessorCount;

int remainingWorkItems = numProcs;

int nextIteration = inclusiveLowerBound;

const int batchSize = 3;


using (ManualResetEvent mre = new ManualResetEvent(false)) {


// Create each of the work items.


for (int p = 0; p < numProcs; p++) {

ThreadPool.QueueUserWorkItem(delegate {

int index;


while ((index = Interlocked.Add(

ref nextIteration, batchSize) -batchSize)

< exclusiveUpperBound)


{


// In a real implementation, we’d need to handle


// overflow on this arithmetic.


int end = index + batchSize;

if (end >= exclusiveUpperBound) end = exclusiveUpperBound;


for (int i = index; i < end; i++) body(i);

}

if (Interlocked.Decrement(ref remainingWorkItems) == 0)


mre.Set();

});

}


// Wait for all threads to complete


mre.WaitOne();


Patterns of Parallel Programming Page 12


}

}


No matter what tradeoffs you make between overheads and load-balancing, they are tradeoffs. For a particular

problem, you might be able to code up a custom parallel loop algorithm mapping to this pattern that suits your

particular problem best. That could result in quite a bit of custom code, however. In general, a good solution is one

that provides quality results for most problems, minimizing overheads while providing sufficient load-balancing,

and the .NET Framework 4 includes just such an implementation in the new System.Threading.Tasks.Parallel class.


P A R A L L E L . F O R


As delightfully parallel problems represent one of the most common patterns in parallel programming, it’s natural

that when support for parallel programming is added to a mainstream library, support for delightfully parallel

loops is included. The .NET Framework 4 provides this in the form of the static Parallel class in the new

System.Threading.Tasks namespace in mscorlib.dll. The Parallel class provides just three methods, albeit each

with several overloads. One of these methods is For, providing multiple signatures, one of which is almost identical

to the signature for MyParallelFor shown previously:


C#


public static ParallelLoopResult For(

int fromInclusive, int toExclusive, Action<int> body);


As with our previous implementations, the For method accepts three parameters: an inclusive lower-bound, an

exclusive upper-bound, and a delegate to be invoked for each iteration. Unlike our implementations, it also returns

a ParallelLoopResult value type, which contains details on the completed loop; more on that later.


Internally, the For method performs in a manner similar to our previous implementations. By default, it uses work

queued to the .NET Framework ThreadPool to execute the loop, and with as much parallelism as it can muster, it

invokes the provided delegate once for each iteration. However, Parallel.For and its overload set provide a whole

lot more than this:


.

Exception handling. If one iteration of the loop throws an exception, all of the threads participating in the

loop attempt to stop processing as soon as possible (by default, iterations currently executing will not be

interrupted, but the loop control logic tries to prevent additional iterations from starting). Once all

processing has ceased, all unhandled exceptions are gathered and thrown in aggregate in an

AggregateException instance. This exception type provides support for multiple “inner exceptions,”

whereas most .NET Framework exception types support only a single inner exception. For more

information about AggregateException, see http://msdn.microsoft.com/magazine/ee321571.aspx.

.

Breaking out of a loop early. This is supported in a manner similar to the break keyword in C# and the

Exit For construct in Visual Basic. Support is also provided for understanding whether the current

iteration should abandon its work because of occurrences in other iterations that will cause the loop to

end early. This is the primary reason for the ParallelLoopResult return value, shown in the Parallel.For

signature, which helps a caller to understand if a loop ended prematurely, and if so, why.

.

Long ranges. In addition to overloads that support working with Int32-based ranges, overloads are

provided for working with Int64-based ranges.

.

Thread-local state. Several overloads provide support for thread-local state. More information on this

support will be provided later in this document in the section on aggregation patterns.


Patterns of Parallel Programming Page 13


.

Configuration options. Multiple aspects of a loop’s execution may be controlled, including limiting the

number of threads used to process the loop.

.

Nested parallelism. If you use a Parallel.For loop within another Parallel.For loop, they coordinate with

each other to share threading resources. Similarly, it’s ok to use two Parallel.For loops concurrently, as

they’ll work together to share threading resources in the underlying pool rather than both assuming th ey

own all cores on the machine.

.

Dynamic thread counts. Parallel.For was designed to accommodate workloads that change in complexity

over time, such that some portions of the workload may be more compute-bound than others. As such, it

may be advantageous to the processing of the loop for the number of threads involved in the processing

to change over time, rather than being statically set, as was done in all of our implementations shown

earlier.

.

Efficient load balancing. Parallel.For supports load balancing in a very sophisticated manner, much more

so than the simple mechanisms shown earlier. It takes into account a large variety of potential workloads

and tries to maximize efficiency while minimizing overheads. The partitioning implementation is based on

a chunking mechanism where the chunk size increases over time. This helps to ensure quality load

balancing when there are only a few iterations, while minimizing overhead when there are many. In

addition, it tries to ensure that most of a thread’s iterations are focused in the same region of the

iteration space in order to provide high cache locality.


Parallel.For is applicable to a wide-range of delightfully parallel problems, serving as an implementation of this

quintessential pattern. As an example of its application, the parallel programming samples for the .NET Framework

4 (available at http://code.msdn.microsoft.com/ParExtSamples) include a ray tracer. Here’s a screenshot:


Ray tracing is fundamentally a delightfully parallel problem. Each individual pixel in the image is generated by firing

an imaginary ray of light, examining the color of that ray as it bounces off of and through objects in the scene, and

storing the resulting color. Every pixel is thus independent of every other pixel, allowing them all to be processed

in parallel. Here are the relevant code snippets from that sample:


C#


void RenderSequential(Scene scene, Int32[] rgb)


{

Camera camera = scene.Camera;

for (int y = 0; y < screenHeight; y++)

{


int stride = y * screenWidth;

for (int x = 0; x < screenWidth; x++)


Patterns of Parallel Programming Page 14


{

Color color = TraceRay(

new Ray(camera.Pos, GetPoint(x, y, camera)), scene, 0);

rgb[x + stride] = color.ToInt32();

}

}

}


void RenderParallel(Scene scene, Int32[] rgb)

{

Camera camera = scene.Camera;


Parallel.For(0, screenHeight, y =>


{

int stride = y * screenWidth;

for (int x = 0; x < screenWidth; x++)

{


Color color = TraceRay(

new Ray(camera.Pos, GetPoint(x, y, camera)), scene, 0);

rgb[x + stride] = color.ToInt32();

}

});

}


Notice that there are very few differences between the sequential and parallel implementation, limited only to

changing the C# for and Visual Basic For language constructs into the Parallel.For method call.


P A R A L L E L . F O R E A C H


A for loop is a very specialized loop. Its purpose is to iterate through a specific kind of data set, a data set made up

of numbers that represent a range. The more generalized concept is iterating through any data set, and constructs

for such a pattern exist in C# with the foreach keyword and in Visual Basic with the For Each construct.


Consider the following for loop:


C#


for(int i=0; i<10; i++)

{


// … Process i.


}


Using the Enumerable class from LINQ, we can generate an IEnumerable<int> that represents the same range, and

iterate through that range using a foreach:


C#


foreach(int i in Enumerable.Range(0, 10))


{


// … Process i.


}


We can accomplish much more complicated iteration patterns by changing the data returned in the enumerable.

Of course, as it is a generalized looping construct, we can use a foreach to iterate through any enumerable data

set. This makes it very powerful, and a parallelized implementation is similarly quite powerful in the parallel realm.

As with a parallel for, a parallel for each represents a fundamental pattern in parallel programming.


Patterns of Parallel Programming Page 15


Implementing a parallel for each is similar in concept to implementing a parallel for. You need multiple threads to

process data in parallel, and you need to partition the data, assigning the partitions to the threads doing the

processing. In our dynamically partitioned MyParallelFor implementation, the data set remaining was represented

by a single integer that stored the next iteration. In a for each implementation, we can store it as an

IEnumerator<T> for the data set. This enumerator must be protected by a critical section so that only one thread

at a time may mutate it. Here is an example implementation:


C#


public static void MyParallelForEach<T>(

IEnumerable<T> source, Action<T> body)


{

int numProcs = Environment.ProcessorCount;

int remainingWorkItems = numProcs;


using (var enumerator = source.GetEnumerator())


{

using (ManualResetEvent mre = new ManualResetEvent(false))

{


// Create each of the work items.


for (int p = 0; p < numProcs; p++)


{

ThreadPool.QueueUserWorkItem(delegate

{


// Iterate until there’s no more work.


while (true)

{


// Get the next item under a lock,

// then process that item.


T nextItem;

lock (enumerator)

{


if (!enumerator.MoveNext()) break;


nextItem = enumerator.Current;

}

body(nextItem);


}

if (Interlocked.Decrement(ref remainingWorkItems) == 0)

mre.Set();

});

}


// Wait for all threads to complete.


mre.WaitOne();

}

}

}


As with the MyParallelFor implementations shown earlier, there are lots of implicit tradeoffs being made in this

implementation, and as with the MyParallelFor, they all come down to tradeoffs between simplicity, overheads,

and load balancing. Taking locks is expensive, and this implementation is taking and releasing a lock for each

element in the enumerable; while costly, this does enable the utmost in load balancing, as every thread only grabs

one item at a time, allowing other threads to assist should one thread run into an unexpectedly expensive

element. We could tradeoff some cost for some load balancing by retrieving multiple items (rather than just one)

while holding the lock. By acquiring the lock, obtaining multiple items from the enumerator, and then releasing the


Patterns of Parallel Programming Page 16


lock, we amortize the cost of acquisition and release over multiple elements, rather than paying the cost for each

element. This benefit comes at the expense of less load balancing, since once a thread has grabbed several items,

it is responsible for processing all of those items, even if some of them happen to be more expensive than the bulk

of the others.


We can decrease costs in other ways, as well. For example, the implementation shown previously always uses the

enumerator’s MoveNext/Current support, but it might be the case that the source input IEnumerable<T> also

implements the IList<T> interface, in which case the implementation could use less costly partitioning, such as that

employed earlier by MyParallelFor:


C#


public static void MyParallelForEach<T>(IEnumerable<T> source, Action<T> body)


{

IList<T> sourceList = source as IList<T>;

if (sourceList != null)

{


// This assumes the IList<T> implementation’s indexer is safe


// for concurrent get access.


MyParallelFor(0, sourceList.Count, i => body(sourceList[i]));

}


else


{


// …


}

}


As with Parallel.For, the .NET Framework 4’s Parallel class provides support for this pattern, in the form of the

ForEach method. Overloads of ForEach provide support for many of the same things for which overloads of For

provide support, including breaking out of loops early, sophisticated partitioning, and thread count dynamism. The

simplest overload of ForEach provides a signature almost identical to the signature shown above:


C#


public static ParallelLoopResult ForEach<TSource>(

IEnumerable<TSource> source, Action<TSource> body);


As an example application, consider a Student record that contains a settable GradePointAverage property as well

as a readable collection of Test records, each of which has a grade and a weight. We have a set of such student

records, and we want to iterate through each, calculating each student’s grades based on the associated tests.

Sequentially, the code looks as follows:


C#


foreach (var student in students)

{

student.GradePointAverage =

student.Tests.Select(test => test.Grade * test.Weight).Sum();

}


To parallelize this, we take advantage of Parallel.ForEach:


C#


Parallel.ForEach(students, student =>


{


Patterns of Parallel Programming Page 17


student.GradePointAverage =

student.Tests.Select(test => test.Grade * test.Weight).Sum();


});


P R O C E S S I N G N O N -I N T E G R A L R A N G E S


The Parallel class in the .NET Framework 4 provides overloads for working with ranges of Int32 and Int64 values.

However, for loops in languages like C# and Visual Basic can be used to iterate through non-integral ranges.


Consider a type Node<T> that represents a linked list:


C#


class Node<T>


{

public Node<T> Prev, Next;

public T Data;


}


Given an instance head of such a Node<T>, we can use a for loop to iterate through the list:


C#


for(Node<T> i = head; i != null; i = i.Next)

{


// … Process node i.


}


Parallel.For does not contain overloads for working with Node<T>, and Node<T> does not implement

IEnumerable<T>, preventing its direct usage with Parallel.ForEach. To compensate, we can use C# iterators to

create an Iterate method which will yield an IEnumerable<T> to iterate through the Node<T>:


C#


public static IEnumerable<Node<T>> Iterate(Node<T> head)


{

for (Node<T> i = head; i != null; i = i.Next)

{


yield return i;

}

}


With such a method in hand, we can now use a combination of Parallel.ForEach and Iterate to approximate a

Parallel.For implementation that does work with Node<T>:


C#


Parallel.ForEach(Iterate(head), i =>

{


// … Process node i.


});


This same technique can be applied to a wide variety of scenarios. Keep in mind, however, that the

IEnumerator<T> interface isn’t thread-safe, which means that Parallel.ForEach needs to take locks when accessing

the data source. While ForEach internally uses some smarts to try to amortize the cost of such locks over the


Patterns of Parallel Programming Page 18


processing, this is still overhead that needs to be overcome by more work in the body of the ForEach in order for

good speedups to be achieved.


Parallel.ForEach has optimizations used when working on data sources that can be indexed into, such as lists and

arrays, and in those cases the need for locking is decreased (this is similar to the example implementation shown

previously, where MyParallelForEach was able to use MyParallelFor in processing an IList<T>). Thus, even though

there is both time and memory cost associated with creating an array from an enumerable, performance may

actually be improved in some cases by transforming the iteration space into a list or an array, which can be done

using LINQ. For example:


C#


Parallel.ForEach(Iterate(head).ToArray(), i =>

{


// … Process node i.


});


The format of a for construct in C# and a For in Visual Basic may also be generalized into a generic Iterate method:


C#


public static IEnumerable<T> Iterate<T>(

Func<T> initialization, Func<T, bool> condition, Func<T, T> update)

{


for (T i = initialization(); condition(i); i = update(i))

{

yield return i;

}

}


While incurring extra overheads for all of the delegate invocations, this now also provides a generalized

mechanism for iterating. The Node<T> example can be re-implemented as follows:


C#


Parallel.ForEach(Iterate(() => head, i => i != null, i => i.Next), i =>

{


// … Process node i.


});


B R E A K I N G O U T O F L O O P S E A R L Y


Exiting out of loops early is a fairly common pattern, one that doesn’t go away when parallelism is introduced. To

help simplify these use cases, the Parallel.For and Parallel.ForEach methods support several mechanisms for

breaking out of loops early, each of which has different behaviors and targets different requirements.


PLANNED EXIT


Patterns of Parallel Programming Page 19


Several overloads of Parallel.For and Parallel.ForEach pass a ParallelLoopState instance to the body delegate.

Included in this type’s surface area are four members relevant to this discussion: methods Stop and Break, and

properties IsStopped and LowestBreakIteration.


When an iteration calls Stop, the loop control logic will attempt to prevent additional iterations of the loop from

starting. Once there are no more iterations executing, the loop method will return successfully (that is, without an

exception). The return type of Parallel.For and Parallel.ForEach is a ParallelLoopResult value type: if Stop caused

the loop to exit early, the result’s IsCompleted property will return false.


C#


ParallelLoopResult loopResult =

Parallel.For(0, N, (int i, ParallelLoopState loop) =>

{


// …


if (someCondition)

{


loop.Stop();

return;


}


// …


});

Console.WriteLine(“Ran to completion: ” + loopResult.IsCompleted);


For long running iterations, the IsStopped property enables one iteration to detect when another iteration has

called Stop in order to bail earlier than it otherwise would:


C#


ParallelLoopResult loopResult =

Parallel.For(0, N, (int i, ParallelLoopState loop) =>

{


// …


if (someCondition)


{

loop.Stop();

return;


}


// …


while (true)

{


if (loop.IsStopped) return;


// …


}

});


Break is very similar to Stop, except Break provides additional guarantees. Whereas Stop informs the loop control

logic that no more iterations need be run, Break informs the control logic that no iterations after the current one

need be run (for example, where the iteration number is higher or where the data comes after the current

element in the data source), but that iterations prior to the current one still need to be run. It doesn’t guarantee

that iterations after the current one haven’t already run or started running, though it will try t o avoid more starting

after the current one. Break may be called from multiple iterations, and the lowest iteration from which Break was

called is the one that takes effect; this iteration number can be retrieved from the ParallelLoopState’s

LowestBreakIteration property, a nullable value. ParallelLoopResult offers a similar LowestBreakIteration

property.


Patterns of Parallel Programming Page 20


This leads to a decision matrix that can be used to interpret a ParallelLoopResult:


.

IsCompleted == true


o

All iterations were processed.

o

If IsCompleted == true, LowestBreakIteration.HasValue will be false.

.

IsCompleted == false && LowestBreakIteration.HasValue == false

o

Stop was used to exit the loop early

.

IsCompleted == false && LowestBreakIteration.HasValue == true

o

Break was used to exit the loop early, and LowestBreakIteration.Value contains the lowest

iteration from which Break was called.

Here is an example of using Break with a loop:


C#


var output = new TResult[N];

var loopResult = Parallel.For(0, N, (int i, ParallelLoopState loop) =>

{


if (someCondition)

{


loop.Break();

return;


}


output[i] = Compute(i);

});

long completedUpTo = N;

if (!loopResult.IsCompleted && loopResult.LowestBreakIteration.HasValue)

{


completedUpTo = loopResult.LowestBreakIteration.Value;

}


Stop is typically useful for unordered search scenarios, where the loop is looking for something and can bail as

soon as it finds it. Break is typically useful for ordered search scenarios, where all of the data up until some point in

the source needs to be processed, with that point based on some search criteria.


UNPLANNED EXIT


The previously mentioned mechanisms for exiting a loop early are based on the body of the loop performing an

action to bail out. Sometimes, however, we want an entity external to the loop to be able to request that the loop

terminate; this is known as cancellation.


Cancellation is supported in parallel loops through the new System.Threading.CancellationToken type introduced

in the .NET Framework 4. Overloads of all of the methods on Parallel accept a ParallelOptions instance, and one of

the properties on ParallelOptions is a CancellationToken. Simply set this CancellationToken property to the

CancellationToken that should be monitored for cancellation, and provide that options instance to the loop’s


invocation. The loop will monitor the token, and if it finds that cancellation has been requested, it will again stop

launching more iterations, wait for all existing iterations to complete, and then throw an

OperationCanceledException.


C#


private CancellationTokenSource _cts = new CancellationTokenSource();


Patterns of Parallel Programming

Page 21


// …


var options = new ParallelOptions { CancellationToken = _cts.Token };


try


{


Parallel.For(0, N, options, i =>


{


// …


});


}


catch(OperationCanceledException oce)


{


// … Handle loop cancellation.


}


Stop and Break allow a loop itself to proactively exit early and successfully, and cancellation allows an external

entity to the loop to request its early termination. It’s also possible for something in the loop’s body to go wrong,

resulting in an early termination of the loop that was not expected.


In a sequential loop, an unhandled exception thrown out of a loop causes the looping construct to immediately

cease. The parallel loops in the .NET Framework 4 get as close to this behavior as is possible while still being

reliable and predictable. This means that when an exception is thrown out of an iteration, the Parallel methods

attempt to prevent additional iterations from starting, though already started iterations are not forcibly

terminated. Once all iterations have ceased, the loop gathers up any exceptions that have been thrown, wraps

them in a System.AggregateException, and throws that aggregate out of the loop.


As with Stop and Break, for cases where individual operations may run for a long time (and thus may delay the

loop’s exit), it may be advantageous for iterations of a loop to be able to check whether other iterations have

faulted. To accommodate that, ParallelLoopState exposes an IsExceptional property (in addition to the

aforementioned IsStopped and LowestBreakIteration properties), which indicates whether another iteration has

thrown an unhandled exception. Iterations may cooperatively check this property, allowing a long-running

iteration to cooperatively exit early when it detects that another iteration failed.


While this exception logic does support exiting out of a loop early, it is not the recommended mechanism for doing

so. Rather, it exists to assist in exceptional cases, cases where breaking out early wasn’t an intentional part of the

algorithm. As is the case with sequential constructs, exceptions should not be relied upon for control flow.


Note, too, that this exceptions behavior isn’t optional. In the face of unhandled exceptions, there’s no way to tell

the looping construct to allow the entire loop to complete execution, just as there’s no built-in way to do that with

a serial for loop. If you wanted that behavior with a serial for loop, you’d likely end up writing code like the

following:


C#


var exceptions = new Queue<Exception>();


for (int i = 0; i < N; i++)


{

try

{

// … Loop body goes here.

}

catch (Exception exc) { exceptions.Enqueue(exc); }


}


if (exceptions.Count > 0) throw new AggregateException(exceptions);


Patterns of Parallel Programming Page 22


If this is the behavior you desire, that same manual handling is also possible using Parallel.For:


C#


var exceptions = new ConcurrentQueue<Exception>();

Parallel.For(0, N, i =>


{


try


{


// … Loop body goes here.


}


catch (Exception exc) { exceptions.Enqueue(exc); }

});

if (!exceptions.IsEmpty) throw new AggregateException(exceptions);


EMPLOYING MULTIPLE EX IT STRATEGIES


It’s possible that multiple exit strategies could all be employed together, concurrently; we’re dealing with

parallelism, after all. In such cases, exceptions always win: if unhandled exceptions have occurred, the loop will

always propagate those exceptions, regardless of whether Stop or Break was called or whether cancellation was

requested.


If no exceptions occurred but the CancellationToken was signaled and either Stop or Break was used, there’s a

potential race as to whether the loop will notice the cancellation prior to exiting. If it does, the loop will exit with

an OperationCanceledException. If it doesn’t, it will exit due to the Stop/Break as explained previously.


However, Stop and Break may not be used together. If the loop detects that one iteration called Stop while

another called Break, the invocation of whichever method ended up being invoked second will result in an

exception being thrown. This is enforced due to the conflicting guarantees provided by Stop and Break.


For long running iterations, there are multiple properties an iteration might want to check to see whether it should

bail early: IsStopped, LowestBreakIteration, IsExceptional, and so on. To simplify this, ParallelLoopState also

provides a ShouldExitCurrentIteration property, which consolidates all of those checks in an efficient manner. The

loop itself checks this value prior to invoking additional iterations.


P A R A L L E L E N U M E R A B L E . F O R A L L


Parallel LINQ (PLINQ), exposed from System.Core.dll in the .NET Framework 4, provides a parallelized

implementation of all of the .NET Framework standard query operators. This includes Select (projections), Where

(filters), OrderBy (sorting), and a host of others. PLINQ also provides several additional operators not present in its

serial counterpart. One such operator is AsParallel, which enables parallel processing of a LINQ-to-Objects query.

Another such operator is ForAll.


Partitioning of data has already been discussed to some extent when discussing Parallel.For and Parallel.ForEach,

and merging will be discussed in greater depth later in this document. Suffice it to say, however, that to process an

input data set in parallel, portions of that data set must be distributed to each thread partaking in the processing,


Patterns of Parallel Programming Page 23


and when all of the processing is complete, those partitions typically need to be merged back together to form the

single output stream expected by the caller:


C#


List<InputData> inputData = …;

foreach (var o in inputData.AsParallel().Select(i => new OutputData(i)))

{


ProcessOutput(o);

}


Both partitioning and merging incur costs, and in parallel programming, we strive to avoid such costs as they’re

pure overhead when compared to a serial implementation. Partitioning can’t be avoided if data must be processed

in parallel, but in some cases we can avoid merging, such as if the work to be done for each resulting item can be

processed in parallel with the work for every other resulting item. To accomplish this, PLINQ provides the ForAll

operator, which avoids the merge and executes a delegate for each output element:


C#


List<InputData> inputData = …;

inputData.AsParallel().Select(i => new OutputData(i)).ForAll(o =>

{


ProcessOutput(o);

});


A N T I -P A T T E R N S


Superman has his kryptonite. Matter has its anti-matter. And patterns have their anti-patterns. Patterns prescribe

good ways to solve certain problems, but that doesn’t mean they’re not without potential pitfalls. There are

several potential problems to look out for with Parallel.For, Parallel.ForEach, and ParallelEnumerable.ForAll.


S H A R E D D A T A


The new parallelism constructs in the .NET Framework 4 help to alleviate most of the boilerplate code you’d

otherwise have to write to parallelize delightfully parallel problems. As you saw earlier, the amount of code

necessary just to implement a simple and naïve MyParallelFor implementation is vexing, and the amount of code

required to do it well is reams more. These constructs do not, however, automatically ensure that your code is

thread-safe. Iterations within a parallel loop must be independent, and if they’re not independent, you must

ensure that the iterations are safe to execute concurrently with each other by doing the appropriate

synchronization.


I T E R A T I O N V A R I A N T S


In managed applications, one of the most common patterns used with a for/For loop is iterating from 0 inclusive to

some upper bound (typically exclusive in C# and inclusive in Visual Basic). However, there are several variations on

this pattern that, while not nearly as common, are still not rare.


DOWNWARD ITERATION


Patterns of Parallel Programming Page 24


It’s not uncommon to see loops iterating down from an upper-bound exclusive to 0 inclusive:


C#


for(int i=upperBound-1; i>=0; –i) { /*…*/ }


Such a loop is typically (though not always) constructed due to dependencies between the iterations; after all, if all

of the iterations are independent, why write a more complex form of the loop if both the upward and downward

iteration have the same results?


Parallelizing such a loop is often fraught with peril, due to these likely dependencies between iterations. If there

are no dependencies between iterations, the Parallel.For method may be used to iterate from an inclusive lower

bound to an exclusive upper bound, as directionality shouldn’t matter: in the extreme case of parallelism, on a

machine with upperBound number of cores, all iterations of the loop may execute concurrently, and direction is

irrelevant.


When parallelizing downward-iterating loops, proceed with caution. Downward iteration is often a sign of a less

than delightfully parallel problem.


STEPP ED ITERATION


Another pattern of a for loop that is less common than the previous cases, but still is not rare, is one involving a

step value other than one. A typical for loop may look like this:


C#


for (int i = 0; i < upperBound; i++) { /*…*/ }


But it’s also possible for the update statement to increase the iteration value by a different amount: for example to

iterate through only the even values between the bounds:


C#


for (int i = 0; i < upperBound; i += 2) { /*…*/ }


Parallel.For does not provide direct support for such patterns. However, Parallel can still be used to implement

such patterns. One mechanism for doing so is through an iterator approach like that shown earlier for iterating

through linked lists:


C#


private static IEnumerable<int> Iterate(


int fromInclusive, int toExclusive, int step)


{


for (int i = fromInclusive; i < toExclusive; i += step) yield return i;


}


A Parallel.ForEach loop can now be used to perform the iteration. For example, the previous code snippet for

iterating the even values between 0 and upperBound can be coded as:


C#


Parallel.ForEach(Iterate(0, upperBound, 2), i=> { /*…*/ });


Patterns of Parallel Programming Page 25


As discussed earlier, such an implementation, while straightforward, also incurs the additional costs of forcing the

Parallel.ForEach to takes locks while accessing the iterator. This drives up the per-element overhead of

parallelization, demanding that more work be performed per element to make up for the increased overhead in

order to still achieve parallelization speedups.


Another approach is to do the relevant math manually. Here is an implementation of a ParallelForWithStep loop

that accepts a step parameter and is built on top of Parallel.For:


C#


public static void ParallelForWithStep(

int fromInclusive, int toExclusive, int step, Action<int> body)


{

if (step < 1)

{


throw new ArgumentOutOfRangeException(“step”);

}

else if (step == 1)

{


Parallel.For(fromInclusive, toExclusive, body);

}


else // step > 1


{

int len = (int)Math.Ceiling((toExclusive -fromInclusive) / (double)step);

Parallel.For(0, len, i => body(fromInclusive + (i * step)));


}

}


This approach is less flexible than the iterator approach, but it also involves significantly less overhead. Threads are

not bottlenecked serializing on an enumerator; instead, they need only pay the cost of a small amount of math

plus an extra delegate invocation per iteration.


V E R Y S M A L L L O O P B O D I E S


As previously mentioned, the Parallel class is implemented in a manner so as to provide for quality load balancing

while incurring as little overhead as possible. There is still overhead, though. The overhead incurred by Parallel.For

is largely centered around two costs:


1)

Delegate invocations. If you squint at previous examples of Parallel.For, a call to Parallel.For looks a lot

like a C# for loop or a Visual Basic For loop. Don’t be fooled: it’s still a method call. One consequence of

this is that the “body” of the Parallel.For “loop” is supplied to the method call as a delegate. Invoking a

delegate incurs approximately the same amount of cost as a virtual method call.


2)

Synchronization between threads for load balancing. While these costs are minimized as much as

possible, any amount of load balancing will incur some cost, and the more load balancing employed, the

more synchronization is necessary.


For medium to large loop bodies, these costs are largely negligible. But as the size of the loop’s body decreases,

the overheads become more noticeable. And for very small bodies, the loop can be completely dominated by this

overhead’s cost. To support parallelization of very small loop bodies requires addressing both #1 and #2 above.

One pattern for this involves chunking the input into ranges, and then instead of replacing a sequential loop with a

parallel loop, wrapping the sequential loop with a parallel loop.


Patterns of Parallel Programming

Page 26


The System.Concurrent.Collections.Partitioner class provides a Create method overload that accepts an integral

range and returns an OrderablePartitioner<Tuple<Int32,Int32>> (a variant for Int64 instead of Int32 is also

available):


C#


public static OrderablePartitioner<Tuple<long, long>> Create(

long fromInclusive, long toExclusive);


Overloads of Parallel.ForEach accept instances of Partitioner<T> and OrderablePartitioner<T> as sources, allowing

you to pass the result of a call to Partitioner.Create into a call to Parallel.ForEach. For now, think of both

Partitioner<T> and OrderablePartitioner<T> as an IEnumerable<T>.


The Tuple<Int32,Int32> represents a range from an inclusive value to an exclusive value. Consider the following

sequential loop:


C#


for (int i = from; i < to; i++)

{


// … Process i.


}


We could use a Parallel.For to parallelize it as follows:


C#


Parallel.For(from, to, i =>

{


// … Process i.


});


Or, we could use Parallel.ForEach with a call to Partitioner.Create, wrapping a sequential loop over the range

provided in the Tuple<Int32, Int32>, where the inclusiveLowerBound is represented by the tuple’s Item1 and

where the exclusiveUpperBound is represented by the tuple’s Item2:


C#


Parallel.ForEach(Partitioner.Create(from, to), range =>


{


for (int i = range.Item1; i < range.Item2; i++)


{


// … process i


}


});


While more complex, this affords us the ability to process very small loop bodies by eschewing some of the

aforementioned costs. Rather than invoking a delegate for each body invocation, we’re now amortizing the cost of

the delegate invocation across all elements in the chunked range. Additionally, as far as the parallel loop is

concerned, there are only a few elements to be processed: each range, rather than each index. This implicitly

decreases the cost of synchronization because there are fewer elements to load-balance.


While Parallel.For should be considered the best option for parallelizing for loops, if performance measurements

show that speedups are not being achieved or that they’re smaller than expected, you can try an approach like the

one shown using Parallel.ForEach in conjunction with Partitioner.Create.


Patterns of Parallel Programming Page 27


T O O F I N E -G R A I N E D , T O O C O A R S E G R A I N E D


The previous anti-pattern outlined the difficulties that arise from having loop bodies that are too small. In addition


to problems that implicitly result in such small bodies, it’s also possible to end up in this situation by decomposing


the problem to the wrong granularity.

Earlier in this section, we demonstrated a simple parallelized ray tracer:


C#


void RenderParallel(Scene scene, Int32[] rgb)

{

Camera camera = scene.Camera;


Parallel.For(0, screenHeight, y =>


{

int stride = y * screenWidth;

for (int x = 0; x < screenWidth; x++)

{


Color color = TraceRay(

new Ray(camera.Pos, GetPoint(x, y, camera)), scene, 0);

rgb[x + stride] = color.ToInt32();

}

});

}


Note that there are two loops here, both of which are actually safe to parallelize:


C#


void RenderParallel(Scene scene, Int32[] rgb)


{


Camera camera = scene.Camera;


Parallel.For(0, screenHeight, y =>


{

int stride = y * screenWidth;


Parallel.For(0, screenWidth, x =>


{

Color color = TraceRay(

new Ray(camera.Pos, GetPoint(x, y, camera)), scene, 0);

rgb[x + stride] = color.ToInt32();

});

});

}


The question then arises: why and when someone would choose to parallelize one or both of these loops? There

are multiple, competing principles. On the one hand, the idea of writing parallelized software that scales to any

number of cores you throw at it implies that you should decompose as much as possible, so that regardless of the

number of cores available, there will always be enough work to go around. This principle suggests both loops

should be parallelized. On the other hand, we’ve already seen the performance implications that can result if

there’s not enough work inside of a parallel loop to warrant its parallelization, implying that only the outer loop

should be parallelized in order to maintain a meaty body.


Patterns of Parallel Programming Page 28


The answer is that the best balance is found through performance testing. If the overheads of parallelization are

minimal as compared to the work being done, parallelize as much as possible: in this case, that would mean

parallelizing both loops. If the overheads of parallelizing the inner loop would degrade performance on most

systems, think twice before doing so, as it’ll likely be best only to parallelize the outer loop/


There are of course some caveats to this (in parallel programming, there are caveats to everything; there are

caveats to the caveats). Parallelization of only the outer loop demands that the outer loop has enough work to

saturate enough processors. In our ray tracer example, what if the image being ray traced was very wide and short,

such that it had a small height? In such a case, there may only be a few iterations for the outer loop to parallelize,

resulting in too coarse-grained parallelization, in which case parallelizing the inner loop could actually be

beneficial, even if the overheads of parallelizing the inner loop would otherwise not warrant its parallelization.


Another option to consider in such cases is flattening the loops, such that you end up with one loop instead of two.


This eliminates the cost of extra partitions and merges that would be incurred on the inner loop’s parallelization:


C#


void RenderParallel(Scene scene, Int32[] rgb)

{


int totalPixels = screenHeight * screenWidth;


Camera camera = scene.Camera;

Parallel.For(0, totalPixels, i =>

{


int y = i / screenWidth, x = i % screenWidth;


Color color = TraceRay(

new Ray(camera.Pos, GetPoint(x, y, camera)), scene, 0);

rgb[i] = color.ToInt32();

});

}


If in doing such flattening the body of the loop becomes too small (which given the cost of TraceRay in this

example is unlikely), the pattern presented earlier for very small loop bodies may also be employed:


C#


void RenderParallel(Scene scene, Int32[] rgb)


{

int totalPixels = screenHeight * screenWidth;

Camera camera = scene.Camera;


Parallel.ForEach(Partitioner.Create(0, totalPixels), range =>


{


for (int i = range.Item1; i < range.Item2; i++)


{

int y = i / screenWidth, x = i % screenWidth;

Color color = TraceRay(


new Ray(camera.Pos, GetPoint(x, y, camera)), scene, 0);

rgb[i] = color.ToInt32();

}

});

}


N O N -T H R E A D -S A F E I L I S T < T > I M P L E M E N T A T I O N S


Patterns of Parallel Programming Page 29


Both PLINQ and Parallel.ForEach query their data sources for several interface implementations. Accessing an

IEnumerable<T> incurs significant cost, due to needing to lock on the enumerator and make virtual methods calls

to MoveNext and Current for each element. In contrast, getting an element from an IList<T> can be done without

locks, as elements of an IList<T> are independent. Thus, both PLINQ and Parallel.ForEach automatically use a

source’s IList<T> implementation if one is available.


In most cases, this is the right decision. However, in very rare cases, an implementation of IList<T> may not be

thread-safe for reading due to the get accessor for the list’s indexer mutating shared state. There are two

predominant reasons why an implementation might do this:


1.

The data structures stores data in a non-indexible manner, such that it must traverse the data structure

to find the requested index. In such a case, the data structure may try to amortize the cost of access by

keeping track of the last element accessed, assuming that accesses will occur in a largely sequential

manner, making it cheaper to start a search from the previously accessed element than starting from

scratch. Consider a theoretical linked list implementation as an example. A linked list does not typically

support direct indexing; rather, if you want to access the 42nd element of the list, you need to start at the

beginning, prior to the head, and move to the next element 42 times. As an optimization, the list could

maintain a reference to the most recently accessed element. If you accessed element 42 and then

element 43, upon accessing 42 the list would cache a reference to the 42nd element, thus making access

to 43 a single move next rather than 43 of them from the beginning. If the implementation doesn’t take

thread-safety into account, these mutations are likely not thread-safe.

2.

Loading the data structure is expensive. In such cases, the data can be lazy-loaded (loaded on first

access) to defer or avoid some of the initialization costs. If getting data from the list forces initialization,

then mutations could occur due to indexing into the list.

There are only a few, obscure occurrences of this in the .NET Framework. One

example is System.Data.Linq.EntitySet<TEntity>. This type implements

IList<TEntity> with support for lazy loading, such that the first thing its indexer’s get

accessor does is load the data into the EntitySet<TEntity> if loading hasn’t already

occurred.


To work around such cases if you do come across them, you can force both PLINQ and Parallel.ForEach to use the

IEnumerable<T> implementation rather than the IList<T> implementation. This can be achieved in two ways:


1)

Use System.Collections.Concurrent.Partitioner’s Create method. There is an overload specific to

IEnumerable<T> that will ensure this interface implementation (not one for IList<T>) is used.

Partitioner.Create returns an instance of a Partitioner<T>, for which there are overloads on

Parallel.ForEach and in PLINQ.


C#


// Will use IList<T> implementation if source implements it.

IEnumerable<T> source = …;

Parallel.ForEach(source, item => { /*…*/ });


// Will use source’s IEnumerable<T> implementationž

IEnumerable<T> source = …;

Parallel.ForEach(Partitioner.Create(source), item => { /*…*/ });


Patterns of Parallel Programming

Page 30


2)

Append onto the data source a call to Enumerable.Select. The Select simply serves to prevent PLINQ and

Parallel.ForEach from finding the original source’s IList<T> implementation.


C#


// Will use IList<T> implementation if source implements it.

IEnumerable<T> source = …;

Parallel.ForEach(source, item => { /*…*/ });


// Will only provide an IEnumerable<T> implementation.

IEnumerable<T> source = …;

Parallel.ForEach(source.Select(t => t), item => { /*…*/ });


P A R A L L E L . F O R E A C H O V E R A P A R A L L E L Q U E R Y < T >


PLINQ’s ParallelEnumerable type operates in terms of ParallelQuery<T> objects. Such objects are returned from

the AsParallel extension method, and all of PLINQ’s operators consume and generate instances of

ParallelQuery<T>. ParallelQuery<T> is itself an IEnumerable<T>, which means it can be iterated over and may be

consumed by anything that understands how to work with an IEnumerable<T>.


Parallel.ForEach is one such construct that works with IEnumerable<T>. As such, it may be tempting to write code

that follows a pattern similar to the following:


C#


var q = from d in data.AsParallel() … select d;

Parallel.ForEach(q, item => { /* Process item. */ });


While this works correctly, it incurs unnecessary costs. In order for PLINQ to stream its output data into an

IEnumerable<T>, PLINQ must merge the data being generated by all of the threads involved in query processing so

that the multiple sets of data can be consumed by code expecting only one. Conversely, when accepting an input

IEnumerable<T>, Parallel.ForEach must consume the single data stream and partition it into multiple data streams

for processing in parallel. Thus, by passing a ParallelQuery<T> to a Parallel.ForEach, in the .NET Framework 4 the

data from the PLINQ query will be merged and will then be repartitioned by the Parallel.ForEach. This can be

costly.


PLINQ QueryPartitionPartitionPartition..

IEnumerable<T>

Parallel.ForEachPartitionPartitionPartition..

Instead, PLINQ’s ParallelEnumerable.ForAll method should be used. Rewriting the previous code as follows will

avoid the spurious merge and repartition:


Patterns of Parallel Programming

Page 31


C#


var q = (from d in data.AsParallel() … select d);

q.ForAll(item => { /* Process item. */ });


This allows the output of all partitions to be processed in parallel, as discussed in the previous section on

ParallelEnumerable.ForAll.


PLINQ QueryPartitionPartitionPartition..

Action<TSource>

Action<TSource>

Action<TSource>

Action<TSource>

T H R E A D A F F I N I T Y IN A C C E S S I N G S O U R C E D A T A


Both Parallel.ForEach and ParallelEnumerable.ForAll rely on each of the threads participating in the loop to pull

data from the source enumerator. While both ForEach and ForAll ensure that the enumerator is accessed in a

thread-safe manner (only one thread at a time will use MoveNext and Current, and will do so atomically with

respect to other threads in the loop), it’s still the case that multiple threads may use MoveNext over time. In

general, this shouldn’t be a problem. However, in some rare cases the implementation of MoveNext may have

thread affinity, meaning that for correctness purposes it should always be accessed from the same thread, and

perhaps even from a specific thread. An example of this could be if MoveNext were accessing a user interface (UI)

control in Windows Forms or Windows Presentation Foundation in order to retrieve its data, or if the control were

pulling data from the object model of one of the Microsoft Office applications. While such thread affinity is not

recommended, avoiding it may not be possible.


In such cases, the consuming implementation needs to change to ensure that the data source is only accessed by

the thread making the call to the loop. That can be achieved with a producer/consumer pattern (many more

details on that pattern are provided later in this document), using code similar in style to the following:


C#


static void ForEachWithEnumerationOnMainThread<T>(

IEnumerable<T> source, Action<T> body)


{

var collectedData = new BlockingCollection<T>();

var loop = Task.Factory.StartNew(() =>


Parallel.ForEach(collectedData.GetConsumingEnumerable(), body));


try


{


foreach (var item in source) collectedData.Add(item);

}

finally { collectedData.CompleteAdding(); }

loop.Wait();


Patterns of Parallel Programming Page 32


}


The Parallel.ForEach executes in the background by pulling the data from a shared collection that is populated by

the main thread enumerating the data source and copying its contents into the shared collection. This solves the

issue of thread affinity with the data source by ensuring that the data source is only accessed on the main thread.

If, however, all access to the individual elements must also be done only on the main thread, parallelization is

infeasible.


P A R A L L E L L O O P S F O R I /O -B O U N D W O R K L O A D S I N S C A L A B L E A P P L I C A T I O N S


It can be extremely tempting to utilize the delightfully parallel looping constructs in the .NET Framework 4 for I/Obound

workloads. And in many cases, it’s quite reasonable to do so as a quick-and-easy approach to getting up and

running with better performance.


Consider the need to ping a set of machines. We can do this quite easily using the

System.Net.NetworkInformation.Ping class, along with LINQ:


C#


var addrs = new[] { addr1, addr2, …, addrN };

var pings = from addr in addrs

select new Ping().Send(addr);

foreach (var ping in pings)

Console.WriteLine(“{0}: {1}”, ping.Status, ping.Address);


By adding just a few characters, we can easily parallelize this operation using PLINQ:


C#


var pings = from addr in addrs.AsParallel()

select new Ping().Send(addr);

foreach (var ping in pings)

Console.WriteLine(“{0}: {1}”, ping.Status, ping.Address);


Rather than using a single thread to ping these machines one after the other, this code uses multiple threads to do

so, typically greatly decreasing the time it takes to complete the operation. Of course, in this case, the work I’m

doing is not at all CPU-bound, and yet by default PLINQ uses a number of threads equal to the number of logical

processors, an appropriate heuristic for CPU-bound workloads but not for I/O-bound. As such, we can utilize

PLINQ’s WithDegreeOfParallelism method to get the work done even faster by using more threads (assuming

there are enough addresses being pinged to make good use of all of these threads):


C#


var pings = from addr in addrs.AsParallel().WithDegreeOfParallelism(16)

select new Ping().Send(addr);

foreach (var ping in pings)

Console.WriteLine(“{0}: {1}”, ping.Status, ping.Address);


For a client application on a desktop machine doing just this one operation, using threads in this manner typically

does not lead to any significant problems. However, if this code were running in an ASP.NET application, it could be


Patterns of Parallel Programming Page 33


deadly to the system. Threads have a non-negligible cost, a cost measurable in both the memory required for their

associated data structures and stack space, and in the extra impact it places on the operating system and its

scheduler. When threads are doing real work, this cost is justified. But when threads are simply sitting around

blocked waiting for an I/O operation to complete, they’re dead weight. Especially in Web applications, where

thousands of users may be bombarding the system with requests, that extra and unnecessary weight can bring a

server to a crawl. For applications where scalability in terms of concurrent users is at a premium, it’s imperative

not to write code like that shown above, even though it’s really simple to write. There are other solutions,

however.


WithDegreeOfParallelism changes the number of threads required to execute and

complete the PLINQ query, but it does not force that number of threads into

existence. If the number is larger than the number of threads available in the

ThreadPool, it may take some time for the ThreadPool thread-injection logic to inject

enough threads to complete the processing of the query . To force it to get there

faster, you can employ the ThreadPool.SetMinThreads method.


The System.Threading.Tasks.Task class will be discussed later in this document. In short, however, note that a

Task instance represents an asynchronous operation. Typically these are computationally-intensive operations, but

the Task abstraction can also be used to represent I/O-bound operations and without tying up a thread in the

process. As an example of this, the samples available at http://code.msdn.microsoft.com/ParExtSamples include

extension methods for the Ping class that provide asynchronous versions of the Send method to return a

Task<PingReply>. Using such methods, we can rewrite our previous method as follows:


C#


var pings = (from addr in addrs


select new Ping().SendTask(addr, null)).ToArray();


Task.WaitAll(pings);


foreach (Task<PingReply> ping in pings)


Console.WriteLine(“{0}: {1}”, ping.Result.Status, ping.Result.Address);


This new solution will asynchronously send a ping to all of the addresses, but no threads (other than the main

thread waiting on the results) will be blocked in the process; only when the pings complete will threads be utilized

briefly to process the results, the actual computational work. This results in a much more scalable solution, one

that may be used in applications that demand scalability. Note, too, that taking advantage of

Task.Factory.ContinueWhenAll (to be discussed later), the code can even avoid blocking the main iteration thread,

as illustrated in the following example:


C#


var pings = (from addr in addrs

select new Ping().SendTask(addr, null)).ToArray();


Task.Factory.ContinueWhenAll(pings, _ =>


{


Task.WaitAll(pings);

foreach (var ping in pings)

Console.WriteLine(“{0}: {1}”, ping.Result.Status, ping.Result.Address);


});


Patterns of Parallel Programming Page 34


The example here was shown utilizing the Ping class, which implements the Event-based Asynchronous Pattern

(EAP). This pattern for asynchronous operation was introduced in the .NET Framework 2.0, and is based on .NET

events that are raised asynchronously when an operation completes.


A more prevalent pattern throughout the .NET Framework is the Asynchronous Programming Model (APM)

pattern, which has existed in the .NET Framework since its inception. Sometimes referred to as the “begin/end”

pattern, this pattern is based on a pair of methods: a “begin” method that starts the asynchronous operation, and

an “end” method that joins with it, retrieving any results of the invocation or the exception from the operation .


To help integrate with this pattern, the aforementioned Task class can also be used to wrap an APM invocation,

which can again help with the scalability, utilizing the Task.Factory.FromAsync method. This support can then be

used to build an approximation of asynchronous methods, as is done in the Task.Factory.Iterate extension method

available in the samples at samples available at http://code.msdn.microsoft.com/ParExtSamples. For more

information, see http://blogs.msdn.com/pfxteam/9809774.aspx. Through its asynchronous workflow functionality,

F# in Visual Studio 2010 also provides first-class language support for writing asynchronous methods. For more

information, see http://msdn.microsoft.com/en-us/library/dd233182(VS.100).aspx. The incubation language

Axum, available for download at http://msdn.microsoft.com/en-us/devlabs/dd795202.aspx, also includes firstclass

language support for writing asynchronous methods.


Patterns of Parallel Programming Page 35


F O R K / J O I N F O R K / J O I N

The patterns employed for delightfully parallel loops are really a subset of a larger set of patterns centered around

“fork/join.” In fork/join patterns, work is “forked” such that several pieces of work are launched asynchronously .

That forked work is later joined with in order to ensure that all of the processing has completed, and potentially to

retrieve the results of that processing if it wasn’t utilized entirely for side-effecting behavior. Loops are a prime

example of this: we fork the processing of loop iterations, and we join such that the parallel loop invocation only

completes when all concurrent processing is done.


The new System.Threading.Tasks namespace in the .NET Framework 4 contains a significant wealth of support for

fork/join patterns. In addition to the Parallel.For, Parallel.ForEach, and PLINQ constructs already discussed, the

.NET Framework provides the Parallel.Invoke method, as well as the new Task and Task<TResult> types. The new

System.Threading.CountdownEvent type also helps with fork/join patterns, in particular for when dealing with

concurrent programming models that don’t provide built-in support for joins.


C O U N T I N G D O W N


A primary component of fork/join pattern implementations is keeping track of how much still remains to be

completed. We saw this in our earlier MyParallelFor and MyParallelForEach implementations, with the loop

storing a count for the number of work items that still remained to be completed, and a ManualResetEvent that

would be signaled when this count reached 0. Support for this pattern is codified into the new

System.Threading.CountdownEvent type in the .NET Framework 4. Below is a code snippet from earlier for

implementing the sample MyParallelFor, now modified to use CountdownEvent.


C#


static void MyParallelFor(

int fromInclusive, int toExclusive, Action<int> body)


{

int numProcs = Environment.ProcessorCount;

int nextIteration = fromInclusive;


using (CountdownEvent ce = new CountdownEvent(numProcs))


{

for (int p = 0; p < numProcs; p++)

{


ThreadPool.QueueUserWorkItem(delegate


{

int index;

while ((index = Interlocked.Increment(


ref nextIteration) -1) < toExclusive)

{

body(index);

}


ce.Signal();


});

}


ce.Wait();


}

}


Patterns of Parallel Programming Page 36


Using CountdownEvent frees us from having to manage a count manually. Instead, the event is initialized with the

expected number of signals, each thread signals the event when the thread completes its processing, and the main

thread waits on the event for all signals to be received.


C O U N T I N G U P A N D D O W N


Counting down is often employed in parallel patterns, but so is incorporating some amount of counting up . If the

remaining count represents the number of work items to be completed, and we end up adding more work items

after setting the initial count, the count will need to be increased.


Here is an example of implementing a MyParallelForEach that launches one asynchronous work item per element

to be processed. Since we don’t know ahead of time how many elements there will be, we add a count of 1 for

each element before launching it, and when the work item completes we signal the event.


C#


static void MyParallelForEach<T>(IEnumerable<T> source, Action<T> body)

{


using (CountdownEvent ce = new CountdownEvent(1))


{

foreach (var item in source)

{


ce.AddCount(1);


ThreadPool.QueueUserWorkItem(state =>


{

try { body((T)state); }

finally { ce.Signal(); }


}, item);

}


ce.Signal();


ce.Wait();

}

}


Note that the event is initialized with a count of 1. This is a common pattern in these scenarios, as we need to

ensure that the event isn’t set prior to all work items completing. If the count instead started at 0, and the first

work item started and completed prior to our adding count for additional elements, the CountdownEvent would

transition to a set state prematurely. By initializing the count to 1, we ensure that the event has no chance of

reaching 0 until we remove that initial count, which is done in the above example by calling Signal after all

elements have been queued.


P A R A L L E L . I N V O K E


As shown previously, the Parallel class provides support for delightfully parallel loops through the Parallel.For and

Parallel.ForEach methods. Parallel also provides support for patterns based on parallelized regions of code, where

every statement in a region may be executed concurrently. This support, provided through the Parallel.Invoke

method, enables a developer to easily specify multiple statements that should execute in parallel, and as with

Parallel.For and Parallel.ForEach, Parallel.Invoke takes care of issues such as exception handling, synchronous

invocation, scheduling, and the like:


Patterns of Parallel Programming Page 37


C#


Parallel.Invoke(


() => ComputeMean(),


() => ComputeMedian(),


() => ComputeMode());


Invoke itself follows patterns internally meant to help alleviate overhead. As an example, if you specify only a few

delegates to be executed in parallel, Invoke will likely spin up one Task per element. However, if you specify many

delegates, or if you specify ParallelOptions for how those delegates should be invoked, Invoke will likely instead

choose to execute its work in a different manner. Looking at the signature for Invoke, we can see how this might

happen:


C#


static void Invoke(params Action[] actions);


Invoke is supplied with an array of delegates, and it needs to perform an action for each one, potentially in

parallel. That sounds like a pattern to which ForEach can be applied, doesn’t it? In fact, we could implement a

MyParallelInvoke using the MyParallelForEach we previously coded:


C#


static void MyParallelInvoke(params Action[] actions)

{


MyParallelForEach(actions, action => action());

}


We could even use MyParallelFor:


C#


static void MyParallelInvoke(params Action[] actions)


{


MyParallelFor(0, actions.Length, i => actions[i]());


}


This is very similar to the type of operation Parallel.Invoke will perform when provided with enough delegates.

The overhead of a parallel loop is more than that of a few tasks, and thus when running only a few delegates, it

makes sense for Invoke to simply use one task per element. But after a certain threshold, it’s more efficient to use

a parallel loop to execute all of the actions, as the cost of the loop is amortized across all of the delegate

invocations.


O N E T A S K P E R E L E M E N T


Parallel.Invoke represents a prototypical example of the fork/join pattern. Multiple operations are launched in


parallel and then joined with such that only when they’re all complete will the entire operation be considered


complete. If we think of each individual delegate invocation from Invoke as being its own asynchronous operation,

we can use a pattern of applying one task per element, where in this case the element is the delegate:


C#


static void MyParallelInvoke(params Action[] actions)


{

var tasks = new Task[actions.Length];

for (int i = 0; i < actions.Length; i++)


Patterns of Parallel Programming Page 38


{


tasks[i] = Task.Factory.StartNew(actions[i]);


}


Task.WaitAll(tasks);


}


This same pattern can be applied for variations, such as wanting to invoke in parallel a set of functions that return

values, with the MyParallelInvoke method returning an array of all of the results. Here are several different ways

that could be implemented, based on the patterns shown thus far (do note these implementations each have

subtle differences in semantics, particularly with regards to what happens when an individual function fails with an

exception):


C#


// Approach #1: One Task per element


static T[]MyParallelInvoke<T>(params Func<T>[] functions)

{

var tasks = (from function in functions


select Task.Factory.StartNew(function)).ToArray();

Task.WaitAll(tasks);

return tasks.Select(t => t.Result).ToArray();


}


// Approach #2: One Task per element, using parent/child Relationships


static T[] MyParallelInvoke<T>(params Func<T>[] functions)


{

var results = new T[functions.Length];

Task.Factory.StartNew(() =>

{


for (int i = 0; i < functions.Length; i++)


{

int cur = i;

Task.Factory.StartNew(


() => results[cur] = functions[cur](),

TaskCreationOptions.AttachedToParent);


}

}).Wait();

return results;


}


// Approach #3: Using Parallel.For


static T[] MyParallelInvoke<T>(params Func<T>[] functions)


{

T[] results = new T[functions.Length];

Parallel.For(0, functions.Length, i =>

{


results[i] = functions[i]();

});

return results;


}


// Approach #4: Using PLINQ


static T[] MyParallelInvoke<T>(params Func<T>[] functions)

{

return functions.AsParallel().Select(f => f()).ToArray();

}


Patterns of Parallel Programming Page 39


As with the Action-based MyParallelInvoke, for just a handful of delegates the first approach is likely the most

efficient. Once the number of delegates increases to a plentiful amount, however, the latter approaches of using

Parallel.For or PLINQ are likely more efficient. They also allow you to easily take advantage of additional

functionality built into the Parallel and PLINQ APIs. For example, placing a limit on the degree of parallelism

employed with tasks directly requires a fair amount of additional code. Doing the same with either Parallel or

PLINQ requires only minimal additions. For example, if I want to use at most two threads to run the operations, I

can do the following:


C#


static T[] MyParallelInvoke<T>(params Func<T>[] functions)

{

T[] results = new T[functions.Length];


var options = new ParallelOptions { MaxDegreeOfParallelism = 2 };

Parallel.For(0, functions.Length, options, i =>

{


results[i] = functions[i]();

});

return results;


}


For fork/join operations, the pattern of creating one task per element may be particularly useful in the following

situations:


1)

Additional work may be started only when specific subsets of the original elements have completed

processing. As an example, in the Strassen’s matrix multiplication algorithm, two matrices are multiplied

by splitting each of the matrices into four quadrants. Seven intermediary matrices are generated based on

operations on the eight input submatrices. Four output submatrices that make up the larger output

matrix are computed from the intermediary seven. These four output matrices each only require a subset

of the previous seven, so while it’s correct to wait for all of the seven prior to computing the following

four, some potential for parallelization is lost as a result.


2)

All elements should be given the chance to run even if one invocation fails. With solutions based on

Parallel and PLINQ, the looping and query constructs will attempt to stop executing as soon as an

exception is encountered; this can be solved using manual exception handling with the loop, as

demonstrated earlier, however by using Tasks, each operation is treated independently, and such custom


code isn’t needed.


R E C U R S I V E D E C O M P O S I T I O N


One of the more common fork/join patterns deals with forks that themselves fork and join. This recursive nature is

known as recursive decomposition, and it applies to parallelism just as it applies to serial recursive

implementations.


Consider a Tree<T> binary tree data structure:


C#


class Tree<T>


{


public T Data;


public Tree<T> Left, Right;


}


Patterns of Parallel Programming

Page 40


A tree walk function that executes an action for each node in the tree might look like the following:


C#


static void Walk<T>(Tree<T> root, Action<T> action)


{

if (root == null) return;

action(root.Data);

Walk(root.Left, action);

Walk(root.Right, action);


}


Parallelizing this may be accomplished by fork/join’ing on at least the two recursive calls, if not also on the action

invocation:


C#


static void Walk<T>(Tree<T> root, Action<T> action)


{


if (root == null) return;


Parallel.Invoke(


() => action(root.Data),


() => Walk(root.Left, action),


() => Walk(root.Right, action));


}


The recursive calls to Walk themselves fork/join as well, leading to a logical tree of parallel invocations. This can of

course also be done using Task objects directly:


C#


static void Walk<T>(Tree<T> root, Action<T> action)


{

if (root == null) return;

var t1 = Task.Factory.StartNew(() => action(root.Data));

var t2 = Task.Factory.StartNew(() => Walk(root.Left, action));

var t3 = Task.Factory.StartNew(() => Walk(root.Right, action));

Task.WaitAll(t1, t2, t3);


}


We can see all of these Tasks in Visual Studio using the Parallel Tasks debugger window, as shown in the following

screenshot:


Patterns of Parallel Programming Page 41


We can further take advantage of parent/child relationships in order to see the associations between these Tasks

in the debugger. First, we can modify our code by forcing all tasks to be attached to a parent, which will be the

Task currently executing when the child is created. This is done with the TaskCreationOptions.AttachedToParent

option:


C#


static void Walk<T>(Tree<T> root, Action<T> action)


{

if (root == null) return;

var t1 = Task.Factory.StartNew(() => action(root.Data),


TaskCreationOptions.AttachedToParent);

var t2 = Task.Factory.StartNew(() => Walk(root.Left, action),

TaskCreationOptions.AttachedToParent);

var t3 = Task.Factory.StartNew(() => Walk(root.Right, action),

TaskCreationOptions.AttachedToParent);

Task.WaitAll(t1, t2, t3);

}


Re-running the application, we can now see the following parent/child hierarchy in the debugger:


C O N T I N U A T I O N C H A I N I N G


The previous example of walking a tree utilizes blocking semantics, meaning that a particular level won’t complete

until its children have completed. Parallel.Invoke, and the Task Wait functionality on which it’s based, attempt

what’s known as inlining, where rather than simply blocking waiting for another thread to execute a Task, the

waiter may be able to run the waitee on the current thread, thereby improving resource reuse, and improving

performance as a result. Still, there may be some cases where tasks are not inlinable, or where the style of

development is better suited towards a more asynchronous model. In such cases, task completions can be chained.


As an example of this, we’ll revisit the Walk method. Rather than returning void, the Walk method can return a

Task. That Task can represent the completion of all child tasks. There are two primary ways to accomplish this. One

way is to take advantage of Task parent/child relationships briefly mentioned previously. With parent/child

relationships, a parent task won’t be considered completed until all of its children have completed.


Patterns of Parallel Programming Page 42


C#


static Task Walk<T>(Tree<T> root, Action<T> action)

{


return Task.Factory.StartNew(() =>

{


if (root == null) return;

Walk(root.Left, action);

Walk(root.Right, action);

action(root.Data);


}, TaskCreationOptions.AttachedToParent);


}


Every call to Walk creates a new Task that’s attached to its parent and immediately returns that Task. That Task,

when executed, recursively calls Walk (thus creating Tasks for the children) and executes the relevant action. At

the root level, the initial call to Walk will return a Task that represents the entire tree of processing and that won’t

complete until the entire tree has completed.


Another approach is to take advantage of continuations:


C#


static Task Walk<T>(Tree<T> root, Action<T> action)


{


if (root == null) return _completedTask;


Task t1 = Task.Factory.StartNew(() => action(root.Data));


Task<Task> t2 = Task.Factory.StartNew(() => Walk(root.Left, action));


Task<Task> t3 = Task.Factory.StartNew(() => Walk(root.Right, action));


return Task.Factory.ContinueWhenAll(


new Task[] { t1, t2.Unwrap(), t3.Unwrap() },


tasks => Task.WaitAll(tasks));


}


As we’ve previously seen, this code uses a task to represent each of the three operations to be performed at each


node: invoking the action for the node, walking the left side of the tree, and walking the right side of the tree .

However, we now have a predicament, in that the Task returned for walking each side of the tree is actually a

Task<Task> rather than simply a Task. This means that the result will be signaled as completed when the Walk call

has returned, but not necessarily when the Task it returned has completed. To handle this, we can take advantage

of the Unwrap method, which converts a Task<Task> into a Task, by “unwrapping” the internal Task into a toplevel

Task that represents it (another overload of Unwrap handles unwrapping a Task<Task<TResult>> into a

Task<TResult>). Now with our three tasks, we can employ the ContinueWhenAll method to create and return a

Task that represents the total completion of this node and all of its descendants. In order to ensure exceptions are


propagated correctly, the body of that continuation explicitly waits on all of the tasks; it knows they’re completed


by this point, so this is simply to utilize the exception propagation logic in WaitAll.


The parent-based approach has several advantages, including that the Visual Studio

2010 Parallel Tasks toolwindow can highlight the parent/child relationship involved,

showing the task hierarchy graphically during a debugging session, and exception

handling is simplified, as all exceptions will bubble up to the root parent. However,

the continuation approach may have a memory benefit for deep hierarchies or long chains

of tasks, since with the parent/child relationships, running children prevent

the parent nodes from being garbage collected.


Patterns of Parallel Programming Page 43


To simplify this, you can consider codifying this into an extension method for easier implementation:


C#


static Task ContinueWhenAll(

this TaskFactory factory, params Task[] tasks)

{

return factory.ContinueWhenAll(

tasks, completed => Task.WaitAll(completed));

}


With that extension method in place, the previous snippet may be rewritten as:


C#


static Task Walk<T>(Tree<T> root, Action<T> action)


{


if (root == null) return _completedTask;


var t1 = Task.Factory.StartNew(() => action(root.Data));


var t2 = Task.Factory.StartNew(() => Walk(root.Left, action));


var t3 = Task.Factory.StartNew(() => Walk(root.Right, action));


return Task.Factory.ContinueWhenAll(t1, t2.Unwrap(), t3.Unwrap());


}


One additional thing to notice is the _completedTask returned if the root node is null. Both WaitAll and

ContinueWhenAll will throw an exception if the array of tasks passed to them contains a null element. There are

several ways to work around this, one of which is to ensure that a null element is never provided. To do that, we

can return a valid Task from Walk even if there is no node to be processed. Such a Task should be already

completed so that little additional overhead is incurred. To accomplish this, we can create a single Task using a

TaskCompletionSource<TResult>, resolve the Task into a completed state, and cache it for all code that needs a

completed Task to use:


C#


private static Task _completedTask = ((Func<Task>)(() => {

var tcs = new TaskCompletionSource<object>();

tcs.SetResult(null);

return tcs.Task;


}))();


A N T I -P A T T E R N S


F A L S E S H A R I N G


Data access patterns are important for serial applications, and they’re even more important for parallel


applications. One serious performance issue that can arise in parallel applications occurs where unexpected

sharing happens at the hardware level.


For performance reasons, memory systems use groups called cache lines, typically of 64 bytes or 128 bytes. A

cache line, rather than an individual byte, is moved around the system as a unit, a classic example of chunky

instead of chatty communication. If multiple cores attempt to access two different bytes on the same cache line,


there’s no correctness sharing conflict, but only one will be able to have exclusive access to the cache line at the


Patterns of Parallel Programming Page 44


hardware level, thus introducing the equivalent of a lock at the hardware level that wasn’t otherwise present in

the code. This can lead to unforeseen and serious performance problems.


As an example, consider the following method, which uses a Parallel.Invoke to initialize two arrays to random

values:


C#


void WithFalseSharing()

{


Random rand1 = new Random(), rand2 = new Random();

int[] results1 = new int[20000000], results2 = new int[20000000];


Parallel.Invoke(

() => {

for (int i = 0; i < results1.Length; i++)


results1[i] = rand1.Next();

},

() => {


for (int i = 0; i < results2.Length; i++)

results2[i] = rand2.Next();

});

}


The code initializes two distinct System.Random instances and two distinct arrays, such that each thread involved

in the parallelization touches its own non-shared state. However, due to the way these two Random instances

were allocated, they’re likely on the same cache line in memory. Since every call to Next modifies the Random

instance’s internal state, multiple threads will now be contending for the same cache line, leading to seriously

impacted performance. Here’s a version that addresses the issue:


C#


void WithoutFalseSharing()


{

int[] results1, results2;

Parallel.Invoke(


() => {


Random rand1 = new Random();

results1 = new int[20000000];


for (int i = 0; i < results1.Length; i++)


results1[i] = rand1.Next();

},

() => {


Random rand2 = new Random();

results2 = new int[20000000];


for (int i = 0; i < results2.Length; i++)

results2[i] = rand2.Next();

});

}


On my dual-core system, when comparing the performance of these two methods, the version with false sharing

typically ends up running slower than the serial equivalent, whereas the version without false sharing typically

ends up running almost twice as fast as the serial equivalent.


False sharing is a likely source for investigation if you find that parallelized code operating with minimal

synchronization isn’t obtaining the parallelized performance improvements you expected. More information is

available in the MSDN Magazine article .NET Matters: False Sharing.


Patterns of Parallel Programming Page 45


R E C U R S I O N W I T H O U T T H R E S H O L D S


In a typical introductory algorithms course, computer science students learn about various algorithms for sorting,

often culminating in quicksort. Quicksort is a recursive divide-and-conquer algorithm, where the input array to be

sorted is partitioned into two contiguous chunks, one with values less than a chosen pivot and one with values

greater than or equal to a chosen pivot. Once the array has been partitioned, the quicksort routine may be used

recursively to sort each chunk. The recursion ends when the size of a chunk is one element, since one element is

implicitly sorted.


Students learn that quicksort has an average algorithmic complexity of O(N log N), which for large values of N is

much faster than other algorithms like insertion sort which have a complexity of O(N2). They also learn, however,

that big-O notation focuses on the limiting behavior of functions and ignores constants, because as the value of N

grows, the constants aren’t relevant. Yet when N is small, those constants can actually make a difference.


It turns out that constants involved in quicksort are larger than those involved in insertion sort, and as such, for

small values of N, insertion sort is often faster than quicksort. Due to quicksort’s recursive nature, even if the

operation starts out operating on a large N, at some point in the recursion the value of N for that particular call is

small enough that it’s actually better to use insertion sort. Thus, many quality implementations of quicksort won’t

stop the recursion when a chunk size is one, but rather will choose a higher value, and when that threshold is

reached, the algorithm will switch over to a call to insertion sort to sort the chunk, rather than continuing with the

recursive quicksort routine.


As has been shown previously, quicksort is a great example for recursive decomposition with task-based

parallelism, as it’s easy to recursively sort the left and right partitioned chunks in parallel, as shown in the following

example:


C#


static void QuickSort<T>(T[] data, int fromInclusive, int toExclusive)

where T : IComparable<T>

{

if (toExclusive -fromInclusive <= THRESHOLD)

InsertionSort(data, fromInclusive, toExclusive);


else


{

int pivotPos = Partition(data, fromInclusive, toExclusive);

Parallel.Invoke(


() => QuickSort(data, fromInclusive, pivotPos),

() => QuickSort(data, pivotPos, toExclusive));

}

}


You’ll note, however, that in addition to the costs associated with the quicksort algorithm itself, we now have

additional overheads involved with creating tasks for each half of the sort. If the computation is completely

balanced, at some depth into the recursion we will have saturated all processors. For example, on a dual-core


machine, the first level of recursion will create two tasks, and thus theoretically from that point forward we’re

saturating the machine and there’s no need to continue to bear the overhead of additional tasks. This implies that

we now may benefit from a second threshold: in addition to switching from quicksort to insertion sort at some

threshold, we now also want to switch from parallel to serial at some threshold. That threshold may be defined in

a variety of ways.


Patterns of Parallel Programming Page 46


As with the insertion sort threshold, a simple parallel threshold could be based on the amount of data left to be

processed:


C#


static void QuickSort<T>(T[] data, int fromInclusive, int toExclusive)

where T : IComparable<T>


{


if (toExclusive -fromInclusive <= THRESHOLD)

InsertionSort(data, fromInclusive, toExclusive);


else


{


int pivotPos = Partition(data, fromInclusive, toExclusive);


if (toExclusive -fromInclusive <= PARALLEL_THRESHOLD)


{


// NOTE: PARALLEL_THRESHOLD is chosen to be greater than THRESHOLD.


QuickSort(data, fromInclusive, pivotPos);


QuickSort(data, pivotPos, toExclusive);


}


else Parallel.Invoke(

() => QuickSort(data, fromInclusive, pivotPos),

() => QuickSort(data, pivotPos, toExclusive));


}

}


Another simple threshold may be based on depth. We can initialize the depth to the max depth we want to recur

to in parallel, and decrement the depth each time we recur… when it reaches 0, we fall back to serial.


C#


static void QuickSort<T>(T[] data, int fromInclusive, int toExclusive, int depth)

where T : IComparable<T>

{


if (toExclusive -fromInclusive <= THRESHOLD)

InsertionSort(data, fromInclusive, toExclusive);


else


{


int pivotPos = Partition(data, fromInclusive, toExclusive);


if (depth > 0)


{


Parallel.Invoke(

() => QuickSort(data, fromInclusive, pivotPos, depth-1),

() => QuickSort(data, pivotPos, toExclusive, depth-1));


}


else


{


QuickSort(data, fromInclusive, pivotPos, 0);

QuickSort(data, pivotPos, toExclusive, 0);

}


}


}


If you assume that the parallelism will be completely balanced due to equal work resulting from all partition

operations, you might then base the initial depth on the number of cores in the machine:


C#


QuickSort(data, 0, data.Length, Math.Log(Environment.ProcessorCount, 2));


Patterns of Parallel Programming Page 47


Alternatively, you might provide a bit of extra breathing room in case the problem space isn’t perfectly balanced:


C#


QuickSort(data, 0, data.Length, Math.Log(Environment.ProcessorCount, 2) + 1);


Of course, the partitioning may result in very unbalanced workloads. And quicksort is just one example of an

algorithm; many other algorithms that are recursive in this manner will frequently result in very unbalanced

workloads.


Another approach is to keep track of the number of outstanding work items, and only “go parallel” when the


number of outstanding items is below a threshold. An example of this follows:


C#


class Utilities


{


static int CONC_LIMIT = Environment.ProcessorCount * 2;

volatile int _invokeCalls = 0;


public void QuickSort<T>(T[] data, int fromInclusive, int toExclusive)

where T : IComparable<T>

{

if (toExclusive -fromInclusive <= THRESHOLD)

InsertionSort(data, fromInclusive, toExclusive);


else


{

int pivotPos = Partition(data, fromInclusive, toExclusive);


if (_invokeCalls < CONC_LIMIT)


{


Interlocked.Increment(ref _invokeCalls);


Parallel.Invoke(

() => QuickSort(data, fromInclusive, pivotPos),

() => QuickSort(data, pivotPos, toExclusive));


Interlocked.Decrement(ref _invokeCalls);


}


else


{

QuickSort(data, fromInclusive, pivotPos);

QuickSort(data, pivotPos, toExclusive);


}

}

}

}


Here, we’re keeping track of the number of Parallel.Invoke calls active at any one time. When the number is below

a predetermined limit, we recur using Parallel.Invoke; otherwise, we recur serially. This adds the additional

expense of two interlocked operations per recursive call (and is only an approximation, as the _invokeCalls field is

compared to the threshold outside of any synchronization), forcing synchronization where it otherwise wasn’t

needed, but it also allows for more load-balancing. Previously, once a recursive path was serial, it would remain

serial. With this modification, a serial path through QuickSort may recur and result in a parallel path.


Patterns of Parallel Programming Page 48


P A S S I N G D A T A P A S S I N G D A T A

There are several common patterns in the .NET Framework for passing data to asynchronous work.


C L O S U R E S


Since support for them was added to C# and Visual Basic, closures represent the easiest way to pass data into

background operations. By creating delegates that refer to state outside of their scope, the compiler transforms

the accessed variables in a way that makes them accessible to the delegates, “closing over” those variables. This

makes it easy to pass varying amounts of data into background work:


C#


int data1 = 42;

string data2 = “The Answer to the Ultimate Question of ” +


“Life, the Universe, and Everything”;

Task.Factory.StartNew(()=>

{


Console.WriteLine(data2 + “: ” + data1);

});


For applications in need of the utmost in performance and scalability, it’s important to keep in mind that under the

covers the compiler may actually be allocating an object in which to store the variables (in the above example,

data1 and data2) that are accessed by the delegate.


S T A T E O B J E C T S


Dating back to the beginning of the .NET Framework, many APIs that spawn asynchronous work accept a state

parameter and pass that state object into the delegate that represents the body of work. The

ThreadPool.QueueUserWorkItem method is a quintessential example of this:


C#


public static bool QueueUserWorkItem(WaitCallback callBack, object state);


public delegate void WaitCallback(object state);


We can take advantage of this state parameter to pass a single object of data into the WaitCallback:


C#


ThreadPool.QueueUserWorkItem(state => {

Console.WriteLine((string)state);

}, data2);


The Task class in the .NET Framework 4 also supports this pattern:


C#


Task.Factory.StartNew(state => {

Console.WriteLine((string)state);

}, data2);


Patterns of Parallel Programming Page 49


Note that in contrast to the closures approach, this typically does not cause an extra object allocation to handle

the state, unless the state being supplied is a value type (value types must be boxed to supply them as the object

state parameter).


To pass in multiple pieces of data with this approach, those pieces of data must be wrapped into a single object . In

the past, this was typically a custom class to store specific pieces of information. With the .NET Framework 4, the

new Tuple<> classes may be used instead:


C#


Tuple<int,string> data = Tuple.Create(data1, data2);


Task.Factory.StartNew(state => {


Tuple<int,string> d = (Tuple<int,string>)state;


Console.WriteLine(d.Item2 + “: ” + d.Item1);


}, data);


As with both closures and working with value types, this requires an object allocation to support the creation of

the tuple to wrap the data items. The built-in tuple types in the .NET Framework 4 also support a limited number

of contained pieces of data.


S T A T E O B J E C T S W I T H M E M B E R M E T H O D S


Another approach, similar to the former, is to pass data into asynchronous operations by representing the work to

be done asynchronously as an instance method on a class. This allows data to be passed in to that method


implicitly through the “this” reference.


C#


class Work


{

public int Data1;

public string Data2;

public void Run()

{


Console.WriteLine(Data1 + “: ” + Data2);

}

}


// …


Work w = new Work();

w.Data1 = 42;

w.Data2 = “The Answer to the Ultimate Question of ” +


“Life, the Universe, and Everything”;

Task.Factory.StartNew(w.Run);


As with the previous approaches, this approach requires an object allocation for an object (in this case, of class

Work) to store the state. Such an allocation is still required if Work is a struct instead of a class; this is because the

creation of a delegate referring to Work must reference the object on which to invoke the instance method Run,

and that reference is stored as an object, thus boxing the struct.


As such, which of these approaches you choose is largely a matter of preference. The closures approach typically

leads to the most readable code, and it allows the compiler to optimize the creation of the state objects. For

example, if the anonymous delegate passed to StartNew doesn’t access any local state, the compiler may be able

to avoid the object allocation to store the state, as it will already be stored as accessible instance or static fields.


Patterns of Parallel Programming Page 50


A N T I -P A T T E R N S


C L O S I N G O V E R I N A P P R O P R I A T E L Y S H A R E D D A T A


Consider the following code, and hazard a guess for what it outputs:


C#


static void Main()


{


for (int i = 0; i < 10; i++)


{


ThreadPool.QueueUserWorkItem(delegate { Console.WriteLine(i); });


}


}


If you guessed that this outputs the numbers 0 through 9 inclusive, you’d likely be wrong. While that might be the

output, more than likely this will actually output ten “10”s. The reason for this has to do with the language’s rules

for scoping and how it captures variables into anonymous methods, which here were used to represent the work

provided to QueueUserWorkItem. The variable i is shared by both the main thread queuing the work items and

the ThreadPool threads printing out the value of i. The main thread is continually updating the value of i as it

iterates from 0 through 9, and thus each output line will contain the value of i at whatever moment the

Console.WriteLine call occurs on the background thread. (Note that unlike the C# compiler, the Visual Basic

compiler kindly warns about this issue: “warning BC42324: Using the iteration variable in a lambda expression may

have unexpected results. Instead, create a local variable within the loop and assign it the value of the iteration

variable.”)


This phenomenon isn’t limited to parallel programming, though the prominence of anonymous methods and

lambda expressions in the the .NET Framework parallel programming model does exacerbate the issue. For a serial

example, consider the following code:


C#


static void Main()


{

var actions = new List<Action>();

for (int i = 0; i < 10; i++)


actions.Add(() => Console.WriteLine(i));

actions.ForEach(action => action());

}


This code will reliably output ten “10”s, as by the time the Action delegates are invoked, the value of i is already

10, and all of the delegates are referring to the same captured i variable.


To address this issue, we can create a local copy of the iteration variable in scope inside the loop (as was

recommended by the Visual Basic compiler). This will cause each anonymous method to gain its own variable,

rather than sharing them with other delegates. The sequential code shown earlier can be fixed with a small

alteration:


C#


static void Main()

{


Patterns of Parallel Programming Page 51


var actions = new List<Action>();

for (int i = 0; i < 10; i++)

{


int tmp = i;


actions.Add(() => Console.WriteLine(tmp));

}

actions.ForEach(action => action());


}


This will reliably print out the sequence “0” through “9” as expected. The parallel code can be fixed in a similar

manner:


C#


static void Main()


{

for (int i = 0; i < 10; i++)

{


int tmp = i;

ThreadPool.QueueUserWorkItem(delegate { Console.WriteLine(tmp); });

}

}


This will also reliably print out the values “0” through “9”, although the order in which they’re printed is not


guaranteed.


Another similar case where closure semantics can lead you astray is if you’re in the habit of declaring your


variables at the top of your function, and then using them later on. For example:


C#


static void Main(string[] args)

{


int j;

Parallel.For(0, 10000, i =>

{


int total = 0;

for (j = 1; j <= 10000; j++) total += j;

});


}


Due to closure semantics, the j variable will be shared by all iterations of the parallel loop, thus wreaking havoc on

the inner serial loop. To address this, the variable declarations should be moved as close to their usage as possible:


C#


static void Main(string[] args)


{

Parallel.For(0, 10000, i =>

{


int total = 0;

for (int j = 1; j <= 10000; j++) total += j;

});

}


Patterns of Parallel Programming Page 52


P R O D U C E R / C O N S U M E R P R O D U C E R / C O N S U M E R

The real world revolves around the “producer/consumer” pattern. Individual entities are responsible for certain

functions, where some entities generate material that ends up being consumed by others. In some cases, those

consumers are also producers for even further consumers. Sometimes there are multiple producers per consumer,

sometimes there are multiple consumers per producer, and sometimes there’s a many-to-many relationship. We

live and breathe producer/consumer, and the pattern similarly has a very high value in parallel computing.


Often, producer/consumer relationships are applied to parallelization when there’s no ability to parallelize an

individual operation, but when multiple operations may be carried out concurrently, with one having a

dependency on the other. For example, consider the need to both compress and encrypt a particular file. This can

be done sequentially, with a single thread reading in a chunk of data, compressing it, encrypting the compressed

data, writing out the encrypted data, and then repeating the process for more chunks until the input file has been

completely processed. Depending on the compression and encryption algorithms utilized, there may not be the


ability to parallelize an individual compression or encryption, and the same data certainly can’t be compressed


concurrently with it being encrypted, as the encryption algorithm must run over the compressed data rather than

over the uncompressed input. Instead, multiple threads may be employed to form a pipeline. One thread can read

in the data. That thread can hand the read data off to another thread that compresses it, and in turn hands the

compressed data off to a third thread. The third thread can then encrypt it, and pass it off to a fourth thread,

which writes the encrypted data to the output file. Each processing “agent”, or “actor”, in this scheme is serial in

nature, churning its input into output, and as long as the hand-offs between agents don’t introduce any reordering

operations, the output data from the entire process will emerge in the same order the associated data was input .


Those hand-offs can be managed with the new BlockingCollection<> type, which provides key support for this

pattern in the .NET Framework 4.


P I P E L I N E S


Hand-offs between threads in a parallelized system require shared state: the producer needs to put the o utput

data somewhere, and the consumer needs to know where to look to get its input data. More than just having

access to a storage location, however, there is additional communication that’s necessary. A consumer is often

prevented from making forward progress until there’s some data to be consumed. Additionally, in some systems, a

producer needs to be throttled so as to avoid producing data much faster than consumers can consume it. In both

of these cases, a notification mechanism must also be incorporated. Additionally, with multiple producers and

multiple consumers, participants must not trample on each other as they access the storage location.


We can build a simple version of such a hand-off mechanism using a Queue<T> and a SemaphoreSlim:


C#


class BlockingQueue<T>


{

private Queue<T> _queue = new Queue<T>();

private SemaphoreSlim _semaphore = new SemaphoreSlim(0, int.MaxValue);


public void Enqueue(T data)


{

if (data == null) throw new ArgumentNullException(“data”);

lock (_queue) _queue.Enqueue(data);

_semaphore.Release();


Patterns of Parallel Programming Page 53


}


public T Dequeue()


{


_semaphore.Wait();


lock (_queue) return _queue.Dequeue();


}


}


Here we have a very simple “blocking queue” data structure. Producers call Enqueue to add data into the queue,

which adds the data to an internal Queue<T> and notifies consumers using a semaphore that another element of

data is available. Similarly, consumers use Dequeue to wait for an element of data to be available and then remove

that data from the underlying Queue<T>. Note that because multiple threads could be accessing the data structure

concurrently, a lock is used to protect the non-thread-safe Queue<T> instance.


Another similar implementation makes use of Monitor’s notification capabilities instead of using a semaphore:


C#


class BlockingQueue<T>

{

private Queue<T> _queue = new Queue<T>();


public void Enqueue(T data)


{

if (data == null) throw new ArgumentNullException(“data”);

lock (_queue)

{


_queue.Enqueue(data);

Monitor.Pulse(_queue);

}

}


public T Dequeue()


{

lock (_queue)

{


while (_queue.Count == 0) Monitor.Wait(_queue);

return _queue.Dequeue();

}

}

}


Such implementations provide basic support for data hand-offs between threads, but they also lack several

important things. How do producers communicate that there will be no more elements produced? With this

blocking behavior, what if a consumer only wants to block for a limited amount of time before doing something

else? What if producers need to be throttled, such that if the underlying Queue<T> is full they’re blocked from

adding to it? What if you want to pull from one of several blocking queues rather than from a single one? What if

semantics others than first-in-first-out (FIFO) are required of the underlying storage? What if producers and

consumers need to be canceled? And so forth.


All of these questions have answers in the new .NET Framework 4

System.Collections.Concurrent.BlockingCollection<T> type in System.dll. It provides the same basic behavior as

shown in the naïve implementation above, sporting methods to add to and take from the collection. But it also


Patterns of Parallel Programming Page 54


supports throttling both consumers and producers, timeouts on waits, support for arbitrary underlying data

structures, and more. It also provides built-in implementations of typical coding patterns related to

producer/consumer in order to make such patterns simple to utilize.


As an example of a standard producer/consumer pattern, consider the need to read in a file, transform each line

using a regular expression, and write out the transformed line to a new file. We can implement that using a Task to

run each step of the pipeline asynchronously, and BlockingCollection<string> as the hand-off point between each

stage.


C#


static void ProcessFile(string inputPath, string outputPath)


{

var inputLines = new BlockingCollection<string>();

var processedLines = new BlockingCollection<string>();


// Stage #1


var readLines = Task.Factory.StartNew(() =>

{


try


{


foreach (var line in File.ReadLines(inputPath)) inputLines.Add(line);

}

finally { inputLines.CompleteAdding(); }


});


// Stage #2


var processLines = Task.Factory.StartNew(() =>

{


try


{

foreach(var line in inputLines.GetConsumingEnumerable()

.Select(line => Regex.Replace(line, @”\s+”, “, “)))

{

processedLines.Add(line);


}

}

finally { processedLines.CompleteAdding(); }


});


// Stage #3


var writeLines = Task.Factory.StartNew(() =>

{

File.WriteAllLines(outputPath, processedLines.GetConsumingEnumerable());

});


Task.WaitAll(readLines, processLines, writeLines);

}


With this basic structure coded up, we have a lot of flexibility and room for modification. For example, what if we

discover from performance testing that we’re reading from the input file much faster than the processing and

outputting can handle it? One option is to limit the speed at which the input file is read, which can be done by

modifying how the inputLines collection is created:


Patterns of Parallel Programming Page 55


C#


var inputLines = new BlockingCollection<string>(boundedCapacity:20);


By adding the boundedCapacity parameter (shown here for clarity using named parameter functionality, which is

now supported by both C# and Visual Basic in Visual Studio 2010), a producer attempting to add to the collection

will block until there are less than 20 elements in the collection, thus slowing down the file reader. Alternatively,

we could further parallelize the solution. For example, let’s assume that through testing you found the real

problem to be that the processLines Task was heavily compute bound. To address that, you could parallelize it

using PLINQ in order to utilize more cores:


C#


foreach(var line in inputLines.GetConsumingEnumerable()


.AsParallel().AsOrdered()


.Select(line => Regex.Replace(line, @”\s+”, “, “)))


Note that by specifying “.AsOrdered()” after the “.AsParallel()”, we’re ensuring that PLINQ maintains the same

ordering as in the sequential solution.


D E C O R A T O R T O P I P E L I N E


The decorator pattern is one of the original Gang Of Four design patterns. A decorator is an object that has the

same interface as another object it contains. In object-oriented terms, it is an object that has an “is-a” and a “hasa”

relationship with a specific type. Consider the CryptoStream class in the System.Security.Cryptography

namespace. CryptoStream derives from Stream (it “is-a” Stream), but it also accepts a Stream to its constructor

and stores that Stream internally (it “has-a” stream); that underlying stream is where the encrypted data is stored.

CryptoStream is a decorator.


With decorators, we typically chain them together. For example, as alluded to in the introduction to this section on

producer/consumer, a common need in software is to both compress and encrypt data. The .NET Framework

contains two decorator stream types to make this feasible: the CryptoStream class already mentioned, and the

GZipStream class. We can compress and encrypt an input file into an output file with code like the following:


C#


static void CompressAndEncrypt(string inputFile, string outputFile)


{

using (var input = File.OpenRead(inputFile))

using (var output = File.OpenWrite(outputFile))

using (var rijndael = new RijndaelManaged())

using (var transform = rijndael.CreateEncryptor())

using (var encryptor =


new CryptoStream(output, transform, CryptoStreamMode.Write))

using (var compressor =

new GZipStream(encryptor, CompressionMode.Compress, true))

input.CopyTo(compressor);

}


The input file stream is copied to a GZipStream, which wraps a CryptoStream, which wraps the output stream. The

data flows from one stream to the other, with its data modified along the way.


Patterns of Parallel Programming Page 56


Both compression and encryption are computationally intense operations, and as such it can be beneficial to

parallelize this operation. However, given the nature of the problem, it’s not just as simple as running both the

compression and encryption in parallel on the input stream, since the encryption operates on the output of the

compression. Instead, we can form a pipeline, with the output of the compression being fed as the input to the

encryption, such that while the encryption is processing data block N, the compression routine can have already

moved on to be processing N+1 or greater. To make this simple, we’ll implement it with another decorator, a

TransferStream. The idea behind this stream is that writes are offloaded to another thread, which sequentially

writes to the underlying stream all of the writes to the transfer stream. That way, when code calls Write on the

transfer stream, it’s not blocked waiting for the whole chain of decorators to complete their processing: Write


returns immediately after queuing the work, and the caller can go on to do additional work. A simple

implementation of TransferStream is shown below (relying on a custom Stream base type, which simply

implements the abstract Stream class with default implementations of all abstract members, in order to keep the

code shown here small), taking advantage of both Task and BlockingCollection:


C#


public sealed class TransferStream : AbstractStreamBase


{

private Stream _writeableStream;

private BlockingCollection<byte[]> _chunks;

private Task _processingTask;


public TransferStream(Stream writeableStream)

{


// … Would validate arguments here


_writeableStream = writeableStream;

_chunks = new BlockingCollection<byte[]>();

_processingTask = Task.Factory.StartNew(() =>

{


foreach (var chunk in _chunks.GetConsumingEnumerable())

_writeableStream.Write(chunk, 0, chunk.Length);

}, TaskCreationOptions.LongRunning);

}


public override bool CanWrite { get { return true; } }


public override void Write(byte[] buffer, int offset, int count)

{


// … Would validate arguments here


var chunk = new byte[count];

Buffer.BlockCopy(buffer, offset, chunk, 0, count);

_chunks.Add(chunk);


}


public override void Close()


{

_chunks.CompleteAdding();

try { _processingTask.Wait(); }

finally { base.Close(); }


}

}


The constructor stores the underlying stream to be written to. It then sets up the necessary components of the

parallel pipeline. First, it creates a BlockingCollection<byte[]> to store all of the data chunks to be written. Then, it


Patterns of Parallel Programming Page 57


launches a long-running Task that continually pulls from the collection and writes each chunk out to the underlying

stream. The Write method copies the provided input data into a new array which it enqueues to the

BlockingCollection; by default, BlockingCollection uses a queue data structure under the covers, maintaining first-

in-first-out (FIFO) semantics, so the data will be written to the underlying stream in the same order it’s added to

the collection, a property important for dealing with streams which have an implicit ordering. Finally, closing the

stream marks the BlockingCollection as complete for adding, which will cause the consuming loop in the Task

launched in the constructor to cease as soon as the collection is empty, and then waits for the Task to complete;

this ensures that all data is written to the underlying stream before the underlying stream is closed, and it

propagates any exceptions that may have occurred during processing.


With our TransferStream in place, we can now use it to parallelize our compression/encryption snippet shown

earlier:


C#


static void CompressAndEncrypt(string inputFile, string outputFile)


{

using (var input = File.OpenRead(inputFile))

using (var output = File.OpenWrite(outputFile))

using (var rijndael = new RijndaelManaged())

using (var transform = rijndael.CreateEncryptor())

using (var encryptor =


new CryptoStream(output, transform, CryptoStreamMode.Write))


using (var threadTransfer = new TransferStream(encryptor))


using (var compressor =

new GZipStream(threadTransfer, CompressionMode.Compress, true))

input.CopyTo(compressor);


}


With those simple changes, we’ve now modified the operation so that both the compression and the encryption

may run in parallel. Of course, it’s important to note here that there are implicit limits on how much speedup I can

achieve from this kind of parallelization. At best the code is doing only two elements of work concurrently,

overlapping the compression with encryption, and thus even on a machine with more than two cores, the best

speedup I can hope to achieve is 2x. Note, too, that I could use additional transfer streams in order to read

concurrently with compressing and to write concurrently with encrypting, as such:


C#


static void CompressAndEncrypt(string inputFile, string outputFile)


{

using (var input = File.OpenRead(inputFile))

using (var output = File.OpenWrite(outputFile))


using (var t2 = new TransferStream(output))


using (var rijndael = new RijndaelManaged())

using (var transform = rijndael.CreateEncryptor())

using (var encryptor =


new CryptoStream(t2, transform, CryptoStreamMode.Write))

using (var t1 = new TransferStream(encryptor))


using (var compressor =

new GZipStream(t1, CompressionMode.Compress, true))

using (var t0 = new TransferStream(compressor))

input.CopyTo(t0);

}


Benefits of doing this might manifest if I/O is a bottleneck.


Patterns of Parallel Programming Page 58


I P R O D U C E R C O N S U M E R C O L L E C T I O N <T>


As mentioned, BlockingCollection<T> defaults to using a queue as its storage mechanism, but arbitrary storage

mechanisms are supported. This is done utilizing a new interface in the .NET Framework 4, passing an instance of

an implementing type to the BlockingCollection’s constructor:


C#


public interface IProducerConsumerCollection<T> :


IEnumerable<T>, ICollection, IEnumerable


{


bool TryAdd(T item);


bool TryTake(out T item);


T[] ToArray();


void CopyTo(T[] array, int index);


}


public class BlockingCollection<T> : //…


{


//…


public BlockingCollection(


IProducerConsumerCollection<T> collection);


public BlockingCollection(


IProducerConsumerCollection<T> collection, int boundedCapacity);


//…


}


Aptly named to contain the name of this pattern, IProducerConsumerCollection<T> represents a collection used in

producer/consumer implementations, where data will be added to the collection by producers and taken from it

by consumers. Hence, the primary two methods on the interface are TryAdd and TryTake, both of which must be

implemented in a thread-safe and atomic manner.


The .NET Framework 4 provides three concrete implementations of this interface:

ConcurrentQueue<T>, ConcurrentStack<T>, and ConcurrentBag<T>.

ConcurrentQueue<T> is the implementation of the interface used by default by

BlockingCollection<T>, providing first-in-first-out (FIFO) semantics.

ConcurrentStack<T> provides last-in-first-out (LIFO) behavior, and

ConcurrentBag<T> eschews ordering guarantees in favor of improved performance

in various use cases, in particular those in which the same thread will be acting as

both a producer and a consumer.


In addition to BlockingCollection<T>, other data structures may be built around IProducerConsumerCollection<T>.

For example, an object pool is a simple data structure that’s meant to allow object reuse. We could build a

concurrent object pool by tying it to a particular storage type, or we can implement one in terms of

IProducerConsumerCollection<T>.


C#


public sealed class ObjectPool<T>


{


private Func<T> _generator;


private IProducerConsumerCollection<T> _objects;


Patterns of Parallel Programming Page 59


public ObjectPool(Func<T> generator)

: this(generator, new ConcurrentQueue<T>()) { }


public ObjectPool(


Func<T> generator, IProducerConsumerCollection<T> storage)


{


if (generator == null) throw new ArgumentNullException(“generator”);


if (storage == null) throw new ArgumentNullException(“storage”);


_generator = generator;


_objects = storage;


}


public T Get()


{


T item;


if (!_objects.TryTake(out item)) item = _generator();


return item;


}


public void Put(T item) { _objects.TryAdd(item); }

}


By parameterizing the storage in this manner, we can adapt our ObjectPool<T> based on use cases and the

associated strengths of the collection implementation. For example, for doing a graphics-intensive UI application,

we may want to render to buffers on background threads and then “bitblip” those buffers onto the UI on the UI

thread. Given the likely size of these buffers, rather than continually allocating large objects and forcing the

garbage collector to clean up after me, we can pool them. In this case, a ConcurrentQueue<T> is a likely choice for

the underlying storage. Conversely, if the pool were being used in a concurrent memory allocator to cache objects

of varying sizes, I don’t need the FIFO-ness of ConcurrentQueue<T>, and I would be better off with a data

structure that minimizes synchronization between threads; for this purpose, ConcurrentBag<T> might be ideal.


Under the covers, ConcurrentBag<T> utilizes a list of instances of T per thread. Each

thread that accesses the bag is able to add and remove data in relative isolation from

other threads accessing the bag. Only when a thread tries to take data out and its

local list is empty will it go in search of items from other threads (the implementation

makes the thread-local lists visible to other threads for only this purpose). This might

sound familiar: ConcurrentBag<T> implements a pattern very similar to the workstealing

algorithm employed by the the .NET Framework 4 ThreadPool.


While accessing the local list is relatively inexpensive, stealing from another thread’s


list is relatively quite expensive. As a result, ConcurrentBag<T> is best for situations

where each thread only needs its own local list the majority of the time . In the object

pool example, to assist with this it could be worthwhile for every thread to initially

populate the pool with some objects, such that when it later gets and puts objects, it

will be dealing predominantly with its own queue.


Patterns of Parallel Programming Page 60


P R O D U C E R / C O N S U M E R E V E R Y W H E R E


If you’ve written a Windows-based application, it’s extremely likely you’ve used the producer/consumer pattern,

potentially without even realizing it. Producer/consumer has many prominent implementations.


T H R E A D P O O L S


If you’ve used a thread pool, you’ve used a quintessential implementation of the producer/consumer pattern . A

thread pool is typically engineered around a data structure containing work to be performed. Every thread in the

pool monitors this data structure, waiting for work to arrive. When work does arrive, a thread retrieves the work,

processes it, and goes back to wait for more. In this capacity, the work that’s being produced is consumed by the

threads in the pool and executed. Utilizing the BlockingCollection<T> type we’ve already seen, it’s straightforward

to build a simple, no-frills thread pool:


C#


public static class SimpleThreadPool


{


private static BlockingCollection<Action> _work =


new BlockingCollection<Action>();


static SimpleThreadPool()


{


for (int i = 0; i < Environment.ProcessorCount; i++)


{


new Thread(() =>


{


foreach (var action in _work.GetConsumingEnumerable())


{


action();


}


}) { IsBackground = true }.Start();


}


}


public static void QueueWorkItem(Action workItem) { _work.Add(workItem); }

}


In concept, this is very similar to how the ThreadPool type in the .NET Framework 3.5 and earlier operated. In the

.NET Framework 4, the data structure used to store the work to be executed is more distributed. Rather than

maintaining a single global queue, as is done in the above example, the ThreadPool in .NET Framework 4 maintains

not only a global queue but also a queue per thread. Work generated outside of the pool goes into the global

queue as it always did, but threads in the pool can put their generated work into the thread-local queues rather

than into the global queues. When threads go in search of work to be executed, they first examine their local

queue, and only if they don’t find anything there, they then check the global queue. If the global queue is found to

be empty, the threads are then also able to check the queues of their peers, “stealing” work from other threads in


order to stay busy. This work-stealing approach can provide significant benefits in the form of both minimized

contention and synchronization between threads (in an ideal workload, threads can spend most of their time

working on their own local queues) as well as cache utilization. (You can approximate this behavior with the

SimpleThreadPool by instantiating the BlockingCollection<Action> with an underlying ConcurrentBag<Action>

rather than utilizing the default ConcurrentQueue<Action>.)


Patterns of Parallel Programming Page 61


In the previous paragraph, we said that “threads in the pool can put their generated

work into the thread-local queues,” not that they necessarily do. In fact, the

ThreadPool.QueueUserWorkItem method is unable to take advantage of this workstealing

support. The functionality is only available through Tasks, for which it is

turned on by default. This behavior can be disabled on a per-Task basis using

TaskCreationOptions.PreferFairness.


By default, Tasks execute in the ThreadPool using these internal work-stealing queues. This functionality isn’t

hardwired into Tasks, however. Rather, the functionality is abstracted through the TaskScheduler type. Tasks

execute on TaskSchedulers, and the .NET Framework 4 comes with a built-in TaskScheduler that targets this

functionality in the ThreadPool; this implementation is what’s returned from the TaskScheduler.Default property,

and as this property’s name implies, this is the default scheduler used by Tasks. As with anything where someone

talks about a “default,” there’s usually a mechanism to override the default, and that does in fact exist for Task

execution. It’s possible to write custom TaskScheduler implementations to execute Tasks in whatever manner is

needed by the application.


TaskScheduler itself embodies the concept of producer/consumer. As an abstract class, it provides several abstract

methods that must be overridden and a few virtual methods that may be. The primary abstract method is called

QueueTask, and is used by the rest of the .NET Framework infrastructure, acting as the producer, to queue tasks

into the scheduler. The scheduler implementation then acts as the consumer, executing those tasks in whatever

manner it sees fit. We can build a very simple, no frills TaskScheduler, based on the previously shown

SimpleThreadPool, simply by delegating from QueueTask to QueueWorkItem, using a delegate that executes the

task:


C#


public sealed class SimpleThreadPoolTaskScheduler : TaskScheduler


{

protected override void QueueTask(Task task)

{


SimpleThreadPool.QueueWorkItem(() => base.TryExecuteTask(task));

}


protected override bool TryExecuteTaskInline(

Task task, bool taskWasPreviouslyQueued)

{

return base.TryExecuteTask(task);

}


protected override IEnumerable<Task> GetScheduledTasks()

{

throw new NotSupportedException();

}

}


We can then produce tasks to be run on an instance of this scheduler:


C#


var myScheduler = new SimpleThreadPoolTaskScheduler();

var t = new Task(() => Console.WriteLine(“hello, world”));

t.Start(myScheduler);


Patterns of Parallel Programming Page 62


The TaskFactory class, a default instance of which is returned from the static Task.Factory property, may also be

instantiated with a TaskScheduler instance. This then allows us to easily utilize all of the factory methods while

targeting a custom scheduler:


C#


var factory = new TaskFactory(new SimpleThreadPoolTaskScheduler());

factory.StartNew(() => Console.WriteLine(“hello, world”));


U I M A R S H A L I N G


If you’ve written a responsive Windows-based application, you’ve already taken advantage of the

producer/consumer pattern. With both Windows Forms and Windows Presentation Foundation (WPF), UI controls

must only be accessed from the same thread that created them, a form of thread affinity. This is problematic for

several reasons, one of the most evident having to do with UI responsiveness. To write a response application, it’s

typically necessary to offload work from the UI thread to a background thread, in order to allow that UI thread to

continue processing Windows messages that cause the UI to repaint, to respond to mouse input, and so on. That

processing occurs with code referred to as a Windows message loop. While the work is executing in the

background, it may need to update visual progress indication in the UI, and when it completes, it may need to

refresh the UI in some manner. Those interactions often require the manipulation of controls that were created on

the UI thread, and as a result, the background thread must marshal calls to those controls to the UI thread.


Both Windows Forms and WPF provide mechanisms for doing this. Windows Forms provides the instance Invoke

method on the Control class. This method accepts a delegate, and marshals the execution of that delegate to the

right thread for that Control, as demonstrated in the following Windows-based application that updates a label on

the UI thread every second:


C#


using System;

using System.Drawing;

using System.Threading;

using System.Windows.Forms;


static class Program


{

[STAThread]

static void Main(string[] args)

{


var form = new Form();

var lbl = new Label()

{


Dock = DockStyle.Fill,


TextAlign = ContentAlignment.MiddleCenter

};

form.Controls.Add(lbl);

var handle = form.Handle;


ThreadPool.QueueUserWorkItem(_ =>


{

while (true)

{


lbl.Invoke((Action)delegate

{


Patterns of Parallel Programming Page 63


lbl.Text = DateTime.Now.ToString();

});

Thread.Sleep(1000);


}

});


form.ShowDialog();

}

}


The Invoke call is synchronous, in that it won’t return until the delegate has completed execution. There is also a

BeginInvoke method, which runs the delegate asynchronously.


This mechanism is itself a producer/consumer implementation. Windows Forms maintains a queue of delegates to

be processed by the UI thread. When Invoke or BeginInvoke is called, it puts the delegate into this queue, and

sends a Windows message to the UI thread. The UI thread’s message loop eventually processes this message,

which tells it to dequeue a delegate from the queue and execute it. In this manner, the thread calling Invoke or

BeginInvoke is the producer, the UI thread is the consumer, and the data being produced and consumed is the

delegate.


The particular pattern of producer/consumer employed by Invoke has a special

name, “rendezvous,” which is typically used to signify multiple threads that meet to

exchange data bidirectionally. The caller of Invoke is providing a delegate and is

potentially getting back the result of that delegate’s invocation. The UI thread is

receiving a delegate and is potentially handing over the delegate’s result. Neither

thread may progress past the rendezvous point until the data has been fully

exchanged.


This producer/consumer mechanism is available for WPF as well, through the Dispatcher class, which similarly

provides Invoke and BeginInvoke methods. To abstract away this functionality and to make it easier to write

components that need to marshal to the UI and that must be usable in multiple UI environments, the .NET

Framework provides the SynchronizationContext class. SynchronizationContext provides Send and Post methods,

which map to Invoke and BeginInvoke, respectively. Windows Forms provides an internal

SynchronizationContext-derived type called WindowsFormsSynchronizationContext, which overrides Send to call

Control.Invoke and which overrides Post to call Control.BeginInvoke. WPF provides a similar type. With this in

hand, a library can be written in terms of SynchronizationContext, and can then be supplied with the right

SynchronziationContext at runtime to ensure it’s able to marshal appropriately to the UI in the current

environment.


SynchronizationContext may also be used for other purposes, and in fact there are

other implementations of it provided in the .NET Framework for non-UI related

purposes. For this discussion, however, we’ll continue to refer to

SynchronizationContext pertaining only to UI marshaling.


To facilitate this, the static SynchronizationContext.Current property exists to help code grab a reference to a

SynchronizationContext that may be used to marshal to the current thread. Both Windows Forms and WPF set

this property on the UI thread to the relevant SynchronizationContext instance. Code may then get the value of


Patterns of Parallel Programming Page 64


this property and use it to marshal work back to the UI. As an example, I can rewrite the previous example by using

SynchronizationContext.Send rather than explicitly using Control.Invoke:


C#


[STAThread]

static void Main(string[] args)

{


var form = new Form();

var lbl = new Label()

{


Dock = DockStyle.Fill,


TextAlign = ContentAlignment.MiddleCenter

};

form.Controls.Add(lbl);

var handle = form.Handle;


var sc = SynchronizationContext.Current;


ThreadPool.QueueUserWorkItem(_ =>


{

while (true)

{


sc.Send(delegate

{


lbl.Text = DateTime.Now.ToString();


}, null);


Thread.Sleep(1000);

}

});


form.ShowDialog();

}


As mentioned in the previous section, custom TaskScheduler types may be implemented to supply custom

consumer implementations for Tasks being produced. In addition to the default implementation of TaskScheduler

that targets the .NET Framework ThreadPool’s internal work-stealing queues, the .NET Framework 4 also includes

the TaskScheduler.FromCurrentSynchronizationContext method, which generates a TaskScheduler that targets

the current synchronization context. We can then take advantage of that functionality to further abstract the

previous example:


C#


[STAThread]

static void Main(string[] args)

{


var form = new Form();

var lbl = new Label()

{


Dock = DockStyle.Fill,


TextAlign = ContentAlignment.MiddleCenter

};

form.Controls.Add(lbl);

var handle = form.Handle;


var ui = new TaskFactory(

TaskScheduler.FromCurrentSynchronizationContext());


ThreadPool.QueueUserWorkItem(_ =>


Patterns of Parallel Programming Page 65


{

while (true)

{


ui.StartNew(() => lbl.Text = DateTime.Now.ToString());

Thread.Sleep(1000);

}

});


form.ShowDialog();

}


This ability to execute Tasks in various contexts also integrates very nicely with continuations and dataflow, for

example:


C#


Task.Factory.StartNew(() =>

{


// Run in the background a long computation which generates a result


return DoLongComputation();

}).ContinueWith(t =>

{


// Render the result on the UI


RenderResult(t.Result);

}, TaskScheduler.FromCurrentSynchronizationContext());


S Y S T E M E V E N T S


The Microsoft.Win32.SystemEvents class exposes a plethora of static events for being notified about happenings

in the system, for example:


C#


public static event EventHandler DisplaySettingsChanged;

public static event EventHandler DisplaySettingsChanging;

public static event EventHandler EventsThreadShutdown;

public static event EventHandler InstalledFontsChanged;

public static event EventHandler PaletteChanged;

public static event PowerModeChangedEventHandler PowerModeChanged;

public static event SessionEndedEventHandler SessionEnded;

public static event SessionEndingEventHandler SessionEnding;

public static event SessionSwitchEventHandler SessionSwitch;

public static event EventHandler TimeChanged;

public static event TimerElapsedEventHandler TimerElapsed;

public static event UserPreferenceChangedEventHandler UserPreferenceChanged;

public static event UserPreferenceChangingEventHandler UserPreferenceChanging;


The Windows operating system notifies applications of the conditions that lead to most of these events through

Windows messages, as discussed in the previous section. To receive these messages, the application must make

sure it has a window to which the relevant messages can be broadcast, and a message loop running to process

them. Thus, if you subscribe to one of these events, even in an application without UI, SystemEvents ensures that

a broadcast window has been created and that a thread has been created to run a message loop for it. That thread

then waits for messages to arrive and consumes them by translating them into the proper .NET Framework objects

and invoking the relevant event. When you register an event handler with an event on SystemEvents, in a strong

sense you’re then implementing the consumer side of this multithreaded, producer/consumer implementation.


Patterns of Parallel Programming Page 66


A G G R E G A T I O N S A G G R E G A T I O N S

Combining data in one way or another is very common in applications, and aggregation is an extremely common

need in parallel applications. In parallel systems, work is divided up, processed in parallel, and the results of these

intermediate computations are then combined in some manner to achieve a final output.


In some cases, no special work is required for the last step. For example, if a parallel for loop iterates from 0 to N,

and the ith result is stored into the resulting array’s ith slot, the aggregation of results into the output array can be

done in parallel with no additional work: the locations in the output array may all be written to independently, and

no two parallel iterations will attempt to store into the same index.


In many cases, however, special work is required to ensure that the results are aggregated safely. There are several

common patterns for achieving such aggregations.


O U T P U T T I N G A S E T O F R E S U L T S


A common coding pattern in sequential code is of the following form, where some input data is processed, and the

results are stored into an output collection:


C#


var output = new List<TOutput>();

foreach (var item in input)

{


var result = Compute(item);

output.Add(result);

}


If the size of the input collection is known in advance, this can be converted into an instance of the

aforementioned example, where the results are stored directly into the corresponding slots in the output:


C#


var output = new TOutput[input.Count];

for (int i = 0; i < input.Count; i++)

{


var result = Compute(input[i]);

output[i] = result;


}


This then makes parallelization straightforward, at least as it pertains to aggregation of the results:


C#


var output = new TOutput[input.Count];


Parallel.For(0, input.Count, i =>


{


var result = Compute(input[i]);

output[i] = result;

});


However, this kind of transformation is not always possible. In cases where the input size is not known or where

the input collection may not be indexed into, an output collection is needed that may be modified from multiple


Patterns of Parallel Programming Page 67


threads. This may be done using explicit synchronization to ensure the output collection is only modified by a

single thread at a time:


C#


var output = new List<TOutput>();


Parallel.ForEach(input, item =>


{


var result = Compute(item);


lock (output) output.Add(result);


});


If the amount of computation done per item is significant, the cost of this locking is likely to be negligible.

However, as the amount of computation per item decreases, the overhead of taking and releasing a lock becomes

more relevant, and contention on the lock increases as more threads are blocked waiting to acquire it

concurrently. To decrease these overheads and to minimize contention, the new thread-safe collections in the

.NET Framework 4 may be used. These collections reside in the System.Collections.Concurrent namespace, and

are engineered to be scalable, minimizing the impact of contention. Some of these collections are implemented

with lock-free techniques, while others are implemented using fine-grained locking.


Amongst these new collections, there’s no direct corollary to the List<T> type. However, there are several

collections that address many of the most common usage patterns for List<T>. If you reexamine the previous code


snippet, you’ll notice that the output ordering from the serial code is not necessarily maintained in the parallel


version. This is because the order in which the data is stored into the output list is no longer based solely on the

order of the data in the input, but also on the order in which the parallel loop chooses to process the elements,

how partitioning occurs, and how long each element takes to process. Once we’ve accepted this issue and have

coded the rest of the application to not rely on the output ordering, our choices expand for what collection to use

to replace the list. Here I’ll use the new ConcurrentBag<T> type:


C#


var output = new ConcurrentBag<TOutput>();

Parallel.ForEach(input, item =>

{


var result = Compute(item);

output.Add(result);

});


All of the synchronization necessary to ensure the consistency of the output data structure is handled internally by

the ConcurrentBag.


O U T P U T T I N G A S I N G L E R E S U L T


Many algorithms output a single result, rather than a single collection. For example, consider the following serial

routine to estimate the value of Pi:


C#


const int NUM_STEPS = 100000000;


static double SerialPi()

{


double sum = 0.0;

double step = 1.0 / (double)NUM_STEPS;


Patterns of Parallel Programming Page 68


for (int i = 0; i < NUM_STEPS; i++)

{


double x = (i + 0.5) * step;

double partial = 4.0 / (1.0 + x * x);

sum += partial;


}

return step * sum;

}


The output of this operation is a single double value. This value is the sum of millions of independent operations,

and thus should be parallelizable. Here is a naïve parallelization:


C#


static double NaiveParallelPi()


{


double sum = 0.0;


double step = 1.0 / (double)NUM_STEPS;


object obj = new object();


Parallel.For(0, NUM_STEPS, i =>


{

double x = (i + 0.5) * step;

double partial = 4.0 / (1.0 + x * x);

lock (obj) sum += partial;


});


return step * sum;

}


We say “naïve” here, because while this solution is correct, it will also be extremely slow. Every iteration of the

parallel loop does only a few real cycles worth of work, made up of a few additions, multiplications, and divisions,

and then takes a lock to accumulate that iteration’s result into the overall result. The cost of that lock will

dominate all of the other work happening in the parallel loop, largely serializing it, such that parallel version will

likely run significantly slower than the sequential.


To fix this, we need to minimize the amount of synchronization necessary. That can be achieved by maintaining

local sums. We know that certain iterations will never be in conflict with each other, namely those running on the

same underlying thread (since a thread can only do one thing at a time), and thus we can maintain a local sum per

thread or task being used under the covers in Parallel.For. Given the prevalence of this pattern, Parallel.For

actually bakes in support for it. In addition to passing to Parallel.For a delegate for the body, you can also pass in a

delegate that represents an initialization routine to be run on each task used by the loop, and a delegate that

represents a finalization routine that will be run at the end of the task when no more iterations will be executed in

it.


C#


public static ParallelLoopResult For<TLocal>(

int fromInclusive, int toExclusive,

Func<TLocal> localInit,

Func<int, ParallelLoopState, TLocal, TLocal> body,

Action<TLocal> localFinally);


The result of the initialization routine is passed to the first iteration run by that task, the output of that iteration is

passed to the next iteration, the output of that iteration is passed to the next, and so on, until finally the last

iteration passes its result to the localFinally delegate.


Patterns of Parallel Programming Page 69


Parallel.ForTask 1localInitIteration AIteration BIteration N…

localFinallyTask NlocalInitIteration AIteration BIteration N…

localFinally…

In this manner, a partial result can be built up on each task, and only combined with the partials from other tasks

at the end. Our Pi example can thusly be implemented as follows:


C#


static double ParallelPi()


{

double sum = 0.0;

double step = 1.0 / (double)NUM_STEPS;

object obj = new object();

Parallel.For(0, NUM_STEPS,


() => 0.0,

(i, state, partial) =>

{


double x = (i + 0.5) * step;


return partial + 4.0 / (1.0 + x * x);

},

partial => { lock (obj) sum += partial; });


return step * sum;

}


The localInit delegate returns an initialized value of 0.0. The body delegate calculates its iteration’s result, adds it

to the partial result it was passed in (which either directly from the result of localInit or from the previous iteration

on the same task), and returns the updated partial. The localFinally delegate takes the completed partial, and only

then synchronizes with other threads to combine the partial sum into the total sum.


Earlier in this document we saw the performance ramifications of having a very small delegate body. This Pi

calculation is an example of that case, and thus we can likely achieve better performance using the batching

pattern described previously.


C#


static double ParallelPartitionerPi()

{


double sum = 0.0;


Patterns of Parallel Programming Page 70


double step = 1.0 / (double)NUM_STEPS;

object obj = new object();


Parallel.ForEach(Partitioner.Create(0, NUM_STEPS),


() => 0.0,


(range, state, partial) =>


{

for (int i = range.Item1; i < range.Item2; i++)

{


double x = (i + 0.5) * step;


partial += 4.0 / (1.0 + x * x);

}

return partial;


},

partial => { lock (obj) sum += partial; });

return step * sum;

}


P L I N Q A G G R E G A T I O N S


Any time you find yourself needing to aggregate, think PLINQ. For many problems, aggregation is one of several

areas in which PLINQ excels, with a plethora of aggregation support built-in.


T O A R R A Y / T O L I S T / T O D I C T I O N A R Y / T O L O O K UP


As does LINQ to Objects, PLINQ provides four “To*” methods that may be used to aggregate all of the output from

a query into a single data structure. PLINQ internally handles all of the relevant synchronization. For example, here

is the previous example of storing all results into a List<T>:


C#


var output = new List<TOutput>();

foreach (var item in input)

{


var result = Compute(item);

output.Add(result);


}


This may be converted to a LINQ implementation as follows:


C#


var output = input

.Select(item => Compute(item))

.ToList();


And then it can be parallelized with PLINQ:


C#


var output = input.AsParallel()

.Select(item => Compute(item))

.ToList();


In fact, not only does PLINQ handle all of the synchronization necessary to do this aggregation safely, it can also be

used to automatically regain the ordering we lost in our parallelized version when using Parallel.ForEach:


Patterns of Parallel Programming Page 71


C#


var output = input.AsParallel().AsOrdered()

.Select(item => Compute(item))

.ToList();


S I N G L E -V A L U E A G G R E G A T I O N S


Just as LINQ and PLINQ are useful for aggregating sets of output, they are also quite useful for aggregating down to

a single value, with operators including but not limited to Average, Sum, Min, Max, and Aggregate. As an example,

the same Pi calculation can be done using LINQ:


C#


static double SerialLinqPi()


{

double step = 1.0 / (double)NUM_STEPS;

return Enumerable.Range(0, NUM_STEPS).Select(i =>

{


double x = (i + 0.5) * step;

return 4.0 / (1.0 + x * x);

}).Sum() * step;

}


With a minimal modification, PLINQ can be used to parallelize this:


C#


static double ParallelLinqPi()


{

double step = 1.0 / (double)NUM_STEPS;

return ParallelEnumerable.Range(0, NUM_STEPS).Select(i =>

{


double x = (i + 0.5) * step;

return 4.0 / (1.0 + x * x);

}).Sum() * step;

}


This parallel implementation does scale nicely as compared to the serial LINQ version. However, if you test the

serial LINQ version and compare its performance against the previously shown serial for loop version, you’ll find

that the serial LINQ version is significantly more expensive; this is largely due to all of the extra delegate

invocations involved in its execution. We can create a hybrid solution that utilizes PLINQ to creation partitions and

sum partial results but creates the individual partial results on each partition using a for loop:


C#


static double ParallelPartitionLinqPi()


{

double step = 1.0 / (double)NUM_STEPS;

return Partitioner.Create(0, NUM_STEPS).AsParallel().Select(range =>

{


double partial = 0.0;

for (int i = range.Item1; i < range.Item2; i++)

{


double x = (i + 0.5) * step;

partial += 4.0 / (1.0 + x * x);


Patterns of Parallel Programming Page 72


}

return partial;

}).Sum() * step;

}


A G G R E G A T E


Both LINQ and PLINQ may be used for arbitrary aggregations using the Aggregate method. Aggregate has several

overloads, including several unique to PLINQ that provide more support for parallelization. PLINQ assumes that the

aggregation delegates are both associative and commutative; this limits the kinds of operations that may be

performed, but also allows PLINQ to optimize its operation in ways that wouldn’t otherwise be possible if it

couldn’t make these assumptions.


The most advanced PLINQ overload of Aggregate is very similar in nature and purpose to the Parallel.ForEach

overload that supports localInit and localFinally delegates:


C#


public static TResult Aggregate<TSource, TAccumulate, TResult>(


this ParallelQuery<TSource> source,


Func<TAccumulate> seedFactory,


Func<TAccumulate, TSource, TAccumulate> updateAccumulatorFunc,


Func<TAccumulate, TAccumulate, TAccumulate> combineAccumulatorsFunc,


Func<TAccumulate, TResult> resultSelector);


The seedFactory delegate is the logical equivalent of localInit, executed once per partition to provide a seed for

the aggregation accumulator on that partition. The updateAccumulatorFunc is akin to the body delegate, provided

with the current value of the accumulator and the current element, and returning the updated accumulator value

based on incorporating the current element. The combineAccumulatorsFunc is logically equivalent to the

localFinally delegate, combining the results from multiple partitions (unlike localFinally, which is given the current

task’s final value and may do with it what it chooses, this delegate accepts two accumulator values and returns the

aggregation of the two). And finally, the resultSelector takes the total accumulation and processes it into a result

value. In many scenarios, TAccumulate will be TResult, and this resultSelector will simply return its input.


As a concrete case for where this aggregation operator is useful, consider a common pattern: the need to take the

best N elements output from a query. An example of this might be in a spell checker. Given an input word list,

compare the input text against each word in the dictionary and compute a distance metric between the two. We

then want to select out the best results to be displayed to the user as options. One approach to implementing this

with PLINQ would be as follows:


C#


var bestResults = dictionaryWordList

.Select(word => new { Word = word, Distance = GetDistance(word, text) })


.TakeTop(p => -p.Distance, NUM_RESULTS_TO_RETURN)


.Select(p => p.Word)

.ToList();


In the previous example, TakeTop is implemented as:


C#


public static IEnumerable<TSource> TakeTop<TSource, TKey>(

this ParallelQuery<TSource> source,


Patterns of Parallel Programming Page 73


Func<TSource, TKey> keySelector,


int count)


{


return source.OrderBy(keySelector).Take(count);


}


The concept of “take the top N” here is implemented by first sorting all of the result using OrderBy and then taking

the first N results. This may be overly expensive, however. For a large word list of several hundred thousand

words, we’re forced to sort the entire result set, and sorting has relatively high computational complexity. If we’re

only selecting out a handful of results, we can do better. For example, in a sequential implementation we could

simply walk the result set, keeping track of the top N along the way. We can implement this in parallel by walking

each partition in a similar manner, keeping track of the best N from each partition. An example implementation of

this approach is included in the Parallel Extensions samples at http://code.msdn.microsoft.com/ParExtSamples,

and the relevant portion is shown here:


C#


public static IEnumerable<TSource> TakeTop<TSource, TKey>(

this ParallelQuery<TSource> source,

Func<TSource, TKey> keySelector,

int count)


{

return source.Aggregate(


// seedFactory


() => new SortedTopN<TKey,TSource>(count),


// updateAccumulatorFunc


(accum, item) =>


{

accum.Add(keySelector(item), item);

return accum;


},


// combineAccumulatorsFunc


(accum1, accum2) =>


{

foreach (var item in accum2) accum1.Add(item);

return accum1;


},


// resultSelector


(accum) => accum.Values);

}


The seedFactory delegate, called once for each partition, generates a new data structure to keep track of the top

count items added to it. Up until count items, all items added to the collection get stored. Beyond that, every time

a new item is added, it’s compared against the least item currently stored, and if it’s greater than it, the least item

is bumped out and the new item is stored in its place. The updateAccumulatorFunc simply adds the current item

to the data structure accumulator (according to the rules of only maintaining the top N). The

combineAccumulatorsFunc combines two of these data structures by adding all of the elements from one to the

other and then returning that end result. And the resultSelector simply returns the set of values from the ultimate

resulting accumulator.


Patterns of Parallel Programming Page 74


M A P R E D U C E M A P R E D U C E

The “MapReduce” pattern was introduced to handle large-scale computations across a cluster of servers, often

involving massive amounts of data. The pattern is relevant even for a single multi-core machine, however. Here is a

description of the pattern’s core algorithm:


“The computation takes a set of input key/value pairs, and produces a set of output key/value pairs. The


user of the MapReduce library expresses the computation as two functions: Map and Reduce.


Map, written by the user, takes an input pair and produces a set of intermediate key/value pairs. The

MapReduce library groups together all intermediate values associated with the same intermediate key I

and passes them to the Reduce function.


The Reduce function, also written by the user, accepts an intermediate key I and a set of values for that

key. It merges together these values to form a possibly smaller set of values. Typically just zero or one

output value is produced per Reduce invocation. The intermediate values are supplied to the user’s

Reduce function via an iterator.”


Dean, J. and Ghemawat, S. 2008. MapReduce: simplified data processing on large clusters. Commun. ACM

51, 1 (Jan. 2008), 107-113. DOI= http://doi.acm.org/10.1145/1327452.1327492


I M P L E M E N T I N G M A P R E D U C E W I T H P L I N Q


The core MapReduce pattern (and many variations on it) is easily implemented with LINQ, and thus with PLINQ. To

see how, we’ll break apart the description of the problem as shown previously.


The description of the Map function is that it takes a single input value and returns a set of mapped values: this is

the purpose of LINQ’s SelectMany operator, which is defined as follows:


C#


public static IEnumerable<TResult> SelectMany<TSource, TResult>(

this IEnumerable<TSource> source,

Func<TSource, IEnumerable<TResult>> selector);


Moving on, the MapReduce problem description highlights that results are then grouped according to an

intermediate key. That grouping operation is the purpose of the LINQ GroupBy operator:


C#


public static IEnumerable<IGrouping<TKey, TSource>> GroupBy<TSource, TKey>(

this IEnumerable<TSource> source,

Func<TSource, TKey> keySelector);


Finally, a reduction is performed by a function that takes each intermediate key and a set of values for that key,

and produces any number of outputs per key. Again, that’s the purpose of SelectMany.


We can put all of this together to implement MapReduce in LINQ:


C#


public static IEnumerable<TResult> MapReduce<TSource, TMapped, TKey, TResult>(

this IEnumerable<TSource> source,


Patterns of Parallel Programming Page 75


Func<TSource, IEnumerable<TMapped>> map,

Func<TMapped, TKey> keySelector,

Func<IGrouping<TKey, TMapped>, IEnumerable<TResult>> reduce)


{


return source.SelectMany(map)

.GroupBy(keySelector)

.SelectMany(reduce);


}


Parallelizing this new combined operator with PLINQ is as simply as changing the input and output types to work

with PLINQ’s ParallelQuery<> type instead of with LINQ’s IEnumerable<>:


C#


public static ParallelQuery<TResult> MapReduce<TSource, TMapped, TKey, TResult>(

this ParallelQuery<TSource> source,

Func<TSource, IEnumerable<TMapped>> map,

Func<TMapped, TKey> keySelector,

Func<IGrouping<TKey, TMapped>, IEnumerable<TResult>> reduce)


{


return source.SelectMany(map)

.GroupBy(keySelector)

.SelectMany(reduce);


}


U S I N G M A P R E D U C E


The typical example used to demonstrate a MapReduce implementation is a word counting routine, where a

bunch of documents are parsed, and the frequency of all of the words across all of the documents is summarized .

For this example, the map function takes in an input document and outputs all of the wor ds in that document. The

grouping phase groups all of the identical words together, such that the reduce phase can then count the words in

each group and output a word/count pair for each grouping:


C#


var files = Directory.EnumerateFiles(dirPath, “*.txt”).AsParallel();


var counts = files.MapReduce(

path => File.ReadLines(path).SelectMany(line => line.Split(delimiters)),

word => word,

group => new[] { new KeyValuePair<string, int>(group.Key, group.Count()) });


The tokenization here is done in a naïve fashion using the String.Split function, which accepts the list of characters

to use as delimiters. For this example, that list was generated using another LINQ query that generates an array of

all of the ASCII white space and punctuation characters:


C#


static char[] delimiters =

Enumerable.Range(0, 256).Select(i => (char)i)

.Where(c => Char.IsWhiteSpace(c) || Char.IsPunctuation(c))

.ToArray();


Patterns of Parallel Programming Page 76


D E P E N D E N C I E S D E P E N D E N C I E S

A dependency is the Achilles heel of parallelism. A dependency between two operations implies that one operation

can’t run until the other operation has completed, inhibiting parallelism. Many real-world problems have implicit

dependencies, and thus it’s important to be able to accommodate them and extract as much parallelism as is

possible. With the producer/consumer pattern, we’ve already explored one key solution to specific kinds of

dependencies. Here we’ll examine others.


D I R E C T E D A C Y C L I C G R A P H S


It’s very common in real-world problems to see patterns where dependencies between components form a

directed acyclic graph (DAG). As an example of this, consider compiling a solution of eight code projects. Some

projects have references to other projects, and thus depend on those projects being built first. The dependencies

are as follows:


.

Components 1, 2, and 3 depend on nothing else in the solution.


.

Component 4 depends on 1.


.

Component 5 depends on 1, 2, and 3.


.

Component 6 depends on 3 and 4.


.

Component 7 depends on 5 and 6 and has no dependencies on it.


.

Component 8 depends on 5 and has no dependencies on it.


This set of dependencies forms the following DAG (as rendered by the new Architecture tools in Visual Studio

2010):


If building each component is represented as a Task, we can take advantage of continuations to express as much

parallelism as is possible:


C#


var f = Task.Factory;

var build1 = f.StartNew(() => Build(project1));

var build2 = f.StartNew(() => Build(project2));


Patterns of Parallel Programming Page 77


var build3 = f.StartNew(() => Build(project3));

var build4 = f.ContinueWhenAll(new[] { build1 },

_ => Build(project4));

var build5 = f.ContinueWhenAll(new[] { build1, build2, build3 },

_ => Build(project5));

var build6 = f.ContinueWhenAll(new[] { build3, build4 },

_ => Build(project6));

var build7 = f.ContinueWhenAll(new[] { build5, build6 },

_ => Build(project7));

var build8 = f.ContinueWhenAll(new[] { build5 },

_ => Build(project8));

Task.WaitAll(build1, build2, build3, build4, build5, build6, build7, build8);


With this code, we immediately queue up work items to build the first three projects. As those projects complete,

projects with dependencies on them will be queued to build as soon as all of their dependencies are satisfied.


I T E R A T I N G I N L O C K S T EP


A common pattern in many algorithms is to have a series of operations that need to be done, from 0 to N, where

step i+1 can’t realistically be processed until step i has completed. This often occurs in image processing

algorithms, where processing one scan line of the image depends on the previous scan line having already been

processed. This also frequently occurs in analysis of a system over time, where each iteration represents another

step forward in time, and the world at iteration i+1 depends on the state of the world after iteration i.


An example of the latter is in simple modeling of the dissipation of heat across a metal plate, exemplified by the

following sequential code:


C#


float[,] SequentialSimulation(int plateSize, int timeSteps)

{


// Initial plates for previous and current time steps, with

// heat starting on one side


var prevIter = new float[plateSize, plateSize];

var currIter = new float[plateSize, plateSize];

for (int y = 0; y < plateSize; y++) prevIter[y, 0] = 255.0f;


// Run simulation


for (int step = 0; step < timeSteps; step++)


{

for (int y = 1; y < plateSize -1; y++)

{


for (int x = 1; x < plateSize -1; x++)

{

currIter[y, x] =


((prevIter[y, x -1] +

prevIter[y, x + 1] +

prevIter[y -1, x] +

prevIter[y + 1, x]) * 0.25f);


}

}

Swap(ref prevIter, ref currIter);


}


// Return results


Patterns of Parallel Programming Page 78


return prevIter;

}


private static void Swap<T>(ref T one, ref T two)


{


T tmp = one; one = two; two = tmp;


}


On close examination, you’ll see that this can actually be expressed as a DAG, since the cell [y,x] for time step i+1

can be computed as soon as the cells [y,x-1], [y,x+1], [y-1,x], and [y+1,x] from time step i are completed. However,

attempting this kind of parallelization can lead to significant complications. For one, the amount of computation

required per cell is very small, just a few array accesses, additions, and multiplications; creating a new Task for

such an operation is respectively a lot of overhead. Another significant complication is around memory

management. In the serial scheme shown, we only need to maintain two plate arrays, one storing the previous

iteration and one storing the current. Once we start expressing the problem as a DAG, we run into issues of

potentially needing plates (or at least portions of plates) for many generations.


An easier solution is simply to parallelize one or more of the inner loops, but not the outer loop . In effect, we can

parallelize each step of the simulation, just not all time steps of the simulation concurrently:


C#


// Run simulation


for (int step = 0; step < timeSteps; step++)

{


Parallel.For(1, plateSize -1, y =>


{

for (int x = 1; x < plateSize -1; x++)

{


currIter[y, x] =


((prevIter[y, x -1] +

prevIter[y, x + 1] +

prevIter[y -1, x] +

prevIter[y + 1, x]) * 0.25f);


}

});

Swap(ref prevIter, ref currIter);


}


Typically, this approach will be sufficient. For some kinds of problems, however, it can be more efficient (largely for

reasons of cache locality) to ensure that the same thread processes the same sections of iteration space on each

time step. We can accomplish that by using Tasks directly, rather than by using Parallel.For. For this heated plate

example, we spin up one Task per processor and assign each a portion of the plate’s size; each Task is responsible

for processing that portion at each time step. Now, we need some way of ensuring that each Task does not go on

to process its portion of the plate at iteration i+1 until all tasks have completed processing iteration i. For that

purpose, we can use the System.Threading.Barrier class that’s new to the .NET Framework 4:


C#


// Run simulation


int numTasks = Environment.ProcessorCount;

var tasks = new Task[numTasks];


var stepBarrier = new Barrier(numTasks, _ => Swap(ref prevIter, ref currIter));


int chunkSize = (plateSize -2) / numTasks;

for (int i = 0; i < numTasks; i++)


Patterns of Parallel Programming Page 79


{

int yStart = 1 + (chunkSize * i);

int yEnd = (i == numTasks -1) ? plateSize -1 : yStart + chunkSize;


tasks[i] = Task.Factory.StartNew(() =>


{

for (int step = 0; step < timeSteps; step++)

{


for (int y = yStart; y < yEnd; y++)


{

for (int x = 1; x < plateSize -1; x++)

{


currIter[y, x] =


((prevIter[y, x -1] +

prevIter[y, x + 1] +

prevIter[y -1, x] +

prevIter[y + 1, x]) * 0.25f);


}

}


stepBarrier.SignalAndWait();


}

});

}


Task.WaitAll(tasks);


Each Task calls the Barrier’s SignalAndWait method at the end of each time step, and the Barrier ensures that no

tasks progress beyond this point in a given iteration until all tasks have reached this point for that iteration .

Further, because we need to swap the previous and current plates at the end of every time step, we register that

swap code with the Barrier as a post-phase action delegate; the Barrier will run that code on one thread once all

Tasks have reached the Barrier in a given iteration and before it releases any Tasks to the next iteration.


D Y N A M I C P R O G R A M M I N G


Not to be confused with dynamic languages or with Visual Basic’s and C#’s for dynamic invocation, “dynamic

programming” in computer science is a classification for optimization algorithms that break down problems

recursively into smaller problems, caching (or “memoizing”) the results of those subproblems for future use, rather

than recomputing them every time they’re needed. Common dynamic programming problems include longest

common subsequence, matrix-chain multiplication, string edit distance, and sequence alignment. Dynamic

programming problems are ripe with dependencies, but these dependencies can be bested and typically don’t

prevent parallelization.


To demonstrate parallelization of a dynamic programming program, consider a simple implementation of the

Levenshtein edit distance algorithm:


C#


static int EditDistance(string s1, string s2)


{

int[,] dist = new int[s1.Length + 1, s2.Length + 1];

for (int i = 0; i <= s1.Length; i++) dist[i, 0] = i;

for (int j = 0; j <= s2.Length; j++) dist[0, j] = j;


for (int i = 1; i <= s1.Length; i++)

{

for (int j = 1; j <= s2.Length; j++)


Patterns of Parallel Programming Page 80


{


dist[i, j] = (s1[i -1] == s2[j -1]) ?


dist[i -1, j -1] :


1 +

Math.Min(dist[i -1, j],


Math.Min(dist[i, j -1],


dist[i -1, j -1]));


}


}


return dist[s1.Length, s2.Length];


}


This algorithm builds up a distance matrix, where the [i,j] entry represents the number of operations it would take

to transform the first i characters of string s1 into the first j characters of s2; an operation is defined as a single

character substitution, insertion, or deletion. To see how this works in action, consider computing the distance

between two strings, going from “PARALLEL” to “STEPHEN”. We start by initializing the first row to the values 0

through 8… these represent deletions (going from “P” to “” requires 1 deletion, going from “PA” to “” requires 2

deletions, going from “PAR” to “” requires 3 deletions, and so on). We also initialize the first column to the values

0 through 7… these represent additions (going from “” to “STEP” requires 4 additions, going from “” to “STEPHEN”


requires 7 additions, and so on).


P A R A L L E L

0 1 2 3 4 5 6 7 8

S 1

T 2

E 3

P 4

H 5

E 6

N 7


Now starting from cell [1,1] we walk down each column, calculating each cell’s value in order. Let’s call the two

strings s1 and s2. A cell’s value is based on two potential options:


1.

The two characters corresponding with that cell are the same. The value for this cell is the same as the

value for the diagonally previous cell, which represents comparing each of the two strings without the

current letter (for example, if we already know the value for comparing “STEPH” and “PARALL”, the value

for “STEPHE” and “PARALLE” is the same, as we added the same letter to the end of both strings, and thus

the distance doesn’t change).

2.

The two characters corresponding with that cell are different. The value for this cell is the minimum of

three potential operations: a deletion, a substitution, or an insertion. These are represented by adding 1

to the value retrieved from the cells immediately above, diagonally to the upper-left, and to the left.

As an exercise, try filling in the table. The completed table for “PARALLEL” and “STEPHEN” is as follows:


Patterns of Parallel Programming

Page 81


P A R A L L E L

0 1 2 3 4 5 6 7 8

S 1 1 2 3 4 5 6 7 8

T 2 2 2 3 4 5 6 7 8

E 3 3 3 3 4 5 6 6 7

P 4 3 4 4 4 5 6 7 7

H 5 4 4 5 5 5 6 7 8

E 6 5 5 5 6 6 6 6 7

N 7 6 6 6 6 7 7 7 7


As you filled it in, you should have noticed that the numbers were filled in almost as if a wavefront were moving

through the table, since a cell [i,j] can be filled in as soon as the three cells [i-1,j-1], [i-1,j], and [i,j-1] are completed

(and in fact, the completion of the cell above and to the left implies that the diagonal cell was also completed) .

From a parallel perspective, this should sound familiar, harkening back to our discussion of DAGs. We could, in fact,

parallelize this problem using one Task per cell and multi-task continuations, but as with previous examples on


dependencies, there’s very little work being done per cell, and the overhead of creating a task for each cell would


significantly outweigh the value of doing so.


You’ll notice, however, that there are macro versions of these micro problems: take any rectangular subset of the

cells in the grid, and that rectangular subset can be completed when the rectangular block above it and to its left

have completed. This presents a solution: we can block the entire matrix up into rectangular regions, run the

algorithm over each block, and use continuations for dependencies between blocks. This amortizes the cost of the

parallelization with tasks across all of the cells in each block, making a Task worthwhile as long as the block is big

enough.


Since the macro problem is the same as the micro, we can write one routine to work with this general pattern,

dubbed the “wavefront” pattern; we can then write a small routine on top of it to deal with blockin g as needed.


Here’s an implementation based on Tasks and continuations:


C#


static void Wavefront(

int numRows, int numColumns, Action<int, int> processRowColumnCell)

{


// … Would validate arguments here


// Store the previous row of tasks as well as the previous task

// in the current row.


Task[] prevTaskRow = new Task[numColumns];

Task prevTaskInCurrentRow = null;

var dependencies = new Task[2];


// Create a task for each cell.


for (int row = 0; row < numRows; row++)

{


Patterns of Parallel Programming Page 82


prevTaskInCurrentRow = null;

for (int column = 0; column < numColumns; column++)

{


// In-scope locals for being captured in the task closures.


int j = row, i = column;


// Create a task with the appropriate dependencies.


Task curTask;

if (row == 0 && column == 0)

{


// Upper-left task kicks everything off,

// having no dependencies.


curTask = Task.Factory.StartNew(() =>


processRowColumnCell(j, i));

}

else if (row == 0 || column == 0)

{


// Tasks in the left-most column depend only on the task

// above them, and tasks in the top row depend only on

// the task to their left.


var antecedent = column == 0 ?


prevTaskRow[0] : prevTaskInCurrentRow;

curTask = antecedent.ContinueWith(p =>

{


p.Wait(); // Necessary only to propagate exceptions.

processRowColumnCell(j, i);

});

}


else // row > 0 && column > 0


{


// All other tasks depend on both the tasks above

// and to the left.


dependencies[0] = prevTaskInCurrentRow;

dependencies[1] = prevTaskRow[column];

curTask = Task.Factory.ContinueWhenAll(dependencies, ps =>

{


Task.WaitAll(ps); // Necessary to propagate exceptions

processRowColumnCell(j, i);

});

}


// Keep track of the task just created for future iterations.


prevTaskRow[column] = prevTaskInCurrentRow = curTask;

}

}


// Wait for the last task to be done.


prevTaskInCurrentRow.Wait();

}


While a non-trivial amount of code, it’s

actually quite straightforward. We maintain an array of Tasks represented

the previous row, and a Task represented the previous Task in the current row. We start by launching a Task to

process the initial Task in the [0,0] slot, since it has no dependencies. We then walk each cell in each row, creating

a continuation Task for each cell. In the first row or the first column, there is just one dependency, the previous

cell in that row or the previous cell in that column, respectively. For all other cells, the continuation is based on the


Patterns of Parallel Programming Page 83


previous cell in both the current row and the current column. At the end, we just wait for the last Task to

complete.


With that code in place, we now need to support blocks, and we can layer another Wavefront function on top to

support that:


C#


static void Wavefront(

int numRows, int numColumns,

int numBlocksPerRow, int numBlocksPerColumn,

Action<int, int, int, int> processBlock)


{


// … Would validate arguments here


// Compute the size of each block.


int rowBlockSize = numRows / numBlocksPerRow;

int columnBlockSize = numColumns / numBlocksPerColumn;


Wavefront(numBlocksPerRow, numBlocksPerColumn, (row, column) =>


{

int start_i = row * rowBlockSize;

int end_i = row < numBlocksPerRow -1 ?


start_i + rowBlockSize : numRows;


int start_j = column * columnBlockSize;

int end_j = column < numBlocksPerColumn -1 ?

start_j + columnBlockSize : numColumns;


processBlock(start_i, end_i, start_j, end_j);


});

}


This code is much simpler. The function accepts the number of rows and number of columns, but also the number

of blocks to use. The delegate now accepts four values, the starting and ending position of the block for both row

and column. The function validates parameters, and then computes the size of each block. From there, it delegates

to the Wavefront overload we previously implemented. Inside the delegate, it uses the provided row and column

number along with the block size to compute the starting and ending row and column positions, and then passes

those values down to the user-supplied delegate.


With this Wavefront pattern implementation in place, we can now parallelize our EditDistance function with very

little additional code:


C#


static int ParallelEditDistance(string s1, string s2)


{

int[,] dist = new int[s1.Length + 1, s2.Length + 1];

for (int i = 0; i <= s1.Length; i++) dist[i, 0] = i;

for (int j = 0; j <= s2.Length; j++) dist[0, j] = j;


int numBlocks = Environment.ProcessorCount * 2;


Wavefront(s1.Length, s2.Length, numBlocks, numBlocks,

(start_i, end_i, start_j, end_j) =>


{

for (int i = start_i + 1; i <= end_i; i++)


Patterns of Parallel Programming Page 84


{

for (int j = start_j + 1; j <= end_j; j++)

{


dist[i, j] = (s1[i -1] == s2[j -1]) ?

dist[i -1, j -1] :

1 + Math.Min(dist[i -1, j],


Math.Min(dist[i, j -1],

dist[i -1, j -1]));

}

}

});


return dist[s1.Length, s2.Length];

}


For small strings, the parallelization overheads will outweigh any benefits. But for large strings, this parallelization

approach can yield significant benefits.


F O L D A N D S C A N


Sometimes a dependency is so significant, there is seemingly no way around it. One such example of this is a “fold”

operation. A fold is typically of the following form:


C#


b[0] = a[0];


for (int i = 1; i < N; i++)


{


b[i] = f(b[i -1], a[i]);


}


As an example, if the function f is addition and the input array is 1,2,3,4,5, the result of the fold will be 1,3,6,10,15.

Each iteration of the fold operation is entirely dependent on the previous iteration, leaving little room for

parallelism. However, as with aggregations, we can make an accommodation: if we guarantee that the f function is

associative, that enables enough wiggle room to introduce some parallelism (many operations are associative,

including the addition operation used as an example). With this restriction on the operation, it’s typically called a

“scan,” or sometimes “prefix scan.”


There are several ways a scan may be parallelized. An approach we’ll show here is based on blocking. Consider

wanting to parallel scan the input sequence of the numbers 1 through 20 using the addition operator on a quadcore

machine. We can split the input into four blocks, and then in parallel, scan each block individually. Once that

step has completed, we can pick out the top element from each block, and do a sequential, exclusive scan on just

those four entries; in an exclusive scan, element b[i] is what element b[i-1] would have been in a regular (inclusive)

scan, with b[0] initialized to 0. The result of this exclusive scan is that, for each block, we now have the

accumulated value for the entry just before the block, and thus we can fold that value in to each element in the

block. For that latter fold, again each block may be processed in parallel.


Patterns of Parallel Programming Page 85


1 2 3 4 56 7 8 9 1011 12 13 14 1516 17 18 19 201 3 6 10 156 13 21 30 4011 23 36 50 6516 33 51 70 90ScanScanScanScan1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20Logically partition into blocks15 40 65 900 15 55 120Exclusive Scan1 3 6 10 1521 28 36 45 5566 78 91 105 120136 153 171 190 210Logically Gather Upper EntriesInclusive Scan Entry into Block

Here is an implementation of this algorithm. As with the heated plate example shown previously, we’re using one

Task per block with a Barrier to synchronize all tasks across the three stages:


1. Scan each block in parallel.

2. Do the exclusive scan of the upper value from each block serially.

3. Scan the exclusive scan results into the blocks in parallel.

One important thing to note about this parallelization is that it incurs significant overhead .

In the sequential scan implementation, we’re executing the combiner function f

approximately N times, where N is the number of entries. In the parallel implementation,

we’re executing f approximately 2N times. As a result, while the operation may be

parallelized, at least two cores are necessary just to break even.


While there are several ways to enforce the serial nature of the second step, here we’re utilizing the Barrier’s postphase

action delegate (the complete implementation is available at

http://code.msdn.microsoft.com/ParExtSamples):


C#


public static void InclusiveScanInPlaceParallel<T>(

T[] arr, Func<T, T, T> function)


{


Patterns of Parallel Programming Page 86


int procCount = Environment.ProcessorCount;

T[] intermediatePartials = new T[procCount];

using (var phaseBarrier = new Barrier(procCount,


_ => ExclusiveScanInPlaceSerial(

intermediatePartials, function, 0, intermediatePartials.Length)))

{


// Compute the size of each range.


int rangeSize = arr.Length / procCount, nextRangeStart = 0;


// Create, store, and wait on all of the tasks.


var tasks = new Task[procCount];

for (int i = 0; i < procCount; i++, nextRangeStart += rangeSize)

{


// Get the range for each task, then start it.


int rangeNum = i;

int lowerRangeInclusive = nextRangeStart;

int upperRangeExclusive = i < procCount -1 ?


nextRangeStart + rangeSize : arr.Length;

tasks[rangeNum] = Task.Factory.StartNew(() =>

{


// Phase 1: Prefix scan assigned range.


InclusiveScanInPlaceSerial(arr, function,

lowerRangeInclusive, upperRangeExclusive, 1);

intermediatePartials[rangeNum] = arr[upperRangeExclusive -1];


// Phase 2: One thread should prefix scan intermediaries.


phaseBarrier.SignalAndWait();


// Phase 3: Incorporate partials.


if (rangeNum != 0)

{


for (int j = lowerRangeInclusive;

j < upperRangeExclusive;

j++)


{

arr[j] = function(

intermediatePartials[rangeNum], arr[j]);

}

}


});

}

Task.WaitAll(tasks);


}

}


This demonstrates that parallelization may be achieved where dependences would otherwise appear to be an


obstacle that can’t be mitigated.


Patterns of Parallel Programming Page 87


D A T A S E T S O F U N K N O W N S I Z E D A T A S E T S O F U N K N O W N S I Z E

Most of the examples described in this document thus far center around data sets of known sizes: input arrays,

input lists, and so forth. In many real-world problems, however, the size of the data set to be processed isn’t

known in advance. This may be because the data is coming in from an external source and hasn’t all arrived yet, or

it may because the data structure storing the data doesn’t keep track of the size or doesn’t store the data in a

manner amenable to the size being relevant. Regardless of the reason, it’s important to be able to parallelize such

problems.


S T R E A M I N G D A T A


Data feeds are becoming more and more important in all areas of computing. Whether it’s a feed of ticker data

from a stock exchange, a sequence of network packets arriving at a machine, or a series of mouse clicks being

entered by a user, such data can be an important input to parallel implementations.


Parallel.ForEach and PLINQ are the two constructs discussed thus far that work on data streams, in the form of

enumerables. Enumerables, however, are based on a pull-model, such that both Parallel.ForEach and PLINQ are

handed an enumerable from which they continually “move next” to get the next element. This is seemingly

contrary to the nature of streaming data, where it hasn’t all arrived yet, and comes in more of a “push” fashion

rather than “pull”. However, if we think of this pattern as a producer/consumer pattern, where the streaming data

is the producer and the Parallel.ForEach or PLINQ query is the consumer, a solution from the .NET Framework 4

becomes clear: we can use BlockingCollection. BlockingCollection’s GetConsumingEnumerable method provides

an enumerable that can be supplied to either Parallel.ForEach or PLINQ. ForEach and PLINQ will both pull data

from this enumerable, which will block the consumers until data is available to be processed. Conversely, as

streaming data arrives in, that data may be added to the collection so that it may be picked up by the consumers.


C#


private BlockingCollection<T> _streamingData = new BlockingCollection<T>();


// Parallel.ForEach


Parallel.ForEach(_streamingData.GetConsumingEnumerable(),


item => Process(item));


// PLINQ


var q = from item in _streamingData.GetConsumingEnumerable().AsParallel()


select item;


There are several caveats to be aware of here, both for Parallel.ForEach and for PLINQ. Parallel.ForEach and PLINQ

work on slightly different threading models in the .NET Framework 4. PLINQ uses a fixed number of threads to

execute a query; by default, it uses the number of logical cores in the machine, or it uses the value passed to

WithDegreeOfParallelism if one was specified. Conversely, Parallel.ForEach may use a variable number of threads,

based on the ThreadPool’s support for injecting and retiring threads over time to best accommodate current

workloads. For Parallel.ForEach, this means that it’s continually monitoring for new threads to be available to it,

taking advantage of them when they arrive, and the ThreadPool is continually trying out injecting new threads into

the pool and retiring threads from the pool to see whether more or fewer threads is beneficial. However, when

passing the result of calling GetConsumingEnumerable as the data source to Parallel.ForEach, the threads used by

the loop have the potential to block when the collection becomes empty. And a blocked thread may not be


Patterns of Parallel Programming Page 88


released by Parallel.ForEach back to the ThreadPool for retirement or other uses. As such, with the code as shown

above, if there are any periods of time where the collection is empty, the thread count in the process may steadily

grow; this can lead to problematic memory usage and other negative performance implications. To address this,

when using Parallel.ForEach in a streaming scenario, it’s best to place an explicit limit on the number of threads

the loop may utilize: this can be done using the ParallelOptions type, and specifically its MaxDegreeOfParallelism

field:


C#


var options = new ParallelOptions { MaxDegreeOfParallelism = 4 };

Parallel.ForEach(_streamingData.GetConsumingEnumerable(), options,


item => Process(item));


By adding the bolded code above, the loop is now limited to at most four threads, avoiding the potential for

significant thread consumption. Even if the collection is empty for a long period of time, the loop can block only

four threads at most.


PLINQ has a different set of caveats. It already uses a fixed number of threads, so thread injection isn’t a concern.

Rather, in the .NET Framework 4, PLINQ has an internally hardwired limit on the number of data elements in an

input data source that are supported: 231, or 2,147,483,648. This means that PLINQ should only be used for

streaming scenarios where fewer than this number of elements will be processed. In most scenarios, this limit

should not be problematic. Consider a scenario where each element takes one millisecond to process. It would

take at least 24 days at that rate of processing to exhaust this element space. If this limit does prove troublesome,

however, in many cases there is a valid mitigation. The limit of 231 elements is per execution of a query, so a

potential solution is to simply restart the query after a certain number of items has been fed into the query.

Consider a query of the form:


C#


_streamingData.GetConsumingEnumerable().AsParallel()


.OtherOperators()


.ForAll(x => Process(x));


We need two things, a loop around the query so that when one query ends, we start it over again, and an operator

that only yields the first N elements from the source, where N is chosen to be less than the 231 limit. LINQ already

provides us with the latter, in the form of the Take operator. Thus, a workaround would be to rewrite the query as

follows:


C#


while (true)

{


_streamingData.GetConsumingEnumerable().Take(2000000000).AsParallel()

.OtherOperators()

.ForAll(x => Process(x));


}


An additional caveat for PLINQ is that not all operators may be used in a streaming query, due to how those

operators behave. For example, OrderBy performs a sort and releases items in sorted order. OrderBy has no way

of knowing whether the items it has yet to consume from the source are less than the smallest item seem thus far,

and thus it can’t release any elements until it’s seen all elements from the source. With an “infinite” source, as is

the case with a streaming input, that will never happen.


Patterns of Parallel Programming Page 89


P A R A L L E L W H I L E N O T E M P T Y


There’s a fairly common pattern that emerges when processing some data structures: the processing of an


element yields additional work to be processed. We can see this with the tree-walk example shown earlier in this


document: processing one node of the tree may yield additional work to be processed in the form of that node’s


children. Similarly in processing a graph data structure, processing a node may yield additional work to be

processed in the form of that node’s neighbors.


Several parallel frameworks include a construct focused on processing these kinds of workloads. No such construct

is included in the .NET Framework 4, however it’s straightforward to build one. There are a variety of ways such a

solution may be coded. Here’s one:


C#


public static void ParallelWhileNotEmpty<T>(

IEnumerable<T> initialValues, Action<T, Action<T>> body)


{

var from = new ConcurrentQueue<T>(initialValues);

var to = new ConcurrentQueue<T>();


while (!from.IsEmpty)


{

Action<T> addMethod = v => to.Enqueue(v);

Parallel.ForEach(from, v => body(v, addMethod));

from = to;

to = new ConcurrentQueue<T>();


}

}


This solution is based on maintaining two lists of data: the data currently being processed (the “from” queue), and

the data generated by the processing of the current data (the “to” queue). The initial values to be processed are

stored into the first list. All those values are processed, and any new values they create are added to the second

list. Then the second list is processed, and any new values that are produced go into a new list (or alternatively the

first list cleared out). Then that list is processed, and… so on. This continues until the next list to be processed has

no values available.


With this in place, we can rewrite our tree walk implementation shown previously:


C#


static void Walk<T>(Tree<T> root, Action<T> action)


{

if (root == null) return;

ParallelWhileNotEmpty(new[] { root }, (item, adder) =>

{


if (item.Left != null) adder(item.Left);

if (item.Right != null) adder(item.Right);

action(item.Data);


});

}


Patterns of Parallel Programming Page 90


A N T I -P A T T E R N S


B L O C K I N G D E P E N D E N C I E S B E T W E E N P A R T I T I O N E D C H U N K S


As mentioned, there are several ways ParallelWhileNotEmpty could be implemented. Another approach to

implementing ParallelWhileNotEmpty combines two parallel patterns we’ve previously seen in this document:

counting up and down, and streaming. Simplistically, we can use a Parallel.ForEach over a BlockingCollection’s

GetConsumingEnumerable, and allow the body of the ForEach to add more items into the BlockingCollection. The

only thing missing, then, is the ability to mark the collection as complete for adding, which we only want to do

after the last element has been processed (since the last element may result in more elements being added). To

accomplish that, we keep track of the number of elements remaining to complete processing; every time the

adder operation is invoked, we increase this count, and every time we complete the processing of an item we

decrease it. If the act of decreasing it causes it to reach 0, we’re done, and we can mark the collection as complete

for adding so that all threads involved in the ForEach will wake up.


C#


// WARNING: THIS METHOD HAS A BUG


static void ParallelWhileNotEmpty<T>(

IEnumerable<T> source, Action<T, Action<T>> body)


{

var queue = new ConcurrentQueue<T>(source);

if (queue.IsEmpty) return;


var remaining = new CountdownEvent(queue.Count);

var bc = new BlockingCollection<T>(queue);

Action<T> adder = item => {


remaining.AddCount();


bc.Add(item);

};

var options = new ParallelOptions {


MaxDegreeOfParallelism = Environment.ProcessorCount

};

Parallel.ForEach(bc.GetConsumingEnumerable(), options, item =>

{


try { body(item, adder); }

finally {

if (remaining.Signal()) bc.CompleteAdding();

}

});

}


Unfortunately, this implementation has a devious bug in it, one that will likely result in deadlock close to the end of

its execution such that ParallelWhileNotEmpty will never return. The issue has to do with partitioning.

Parallel.ForEach uses multiple threads to process the supplied data source (in this case, the result of calling

bc.GetConsumingEnumerable), and as such the data from that source needs to be dispensed to those threads. By

default, Parallel.ForEach does this by having its threads take a lock, pull some number of elements from the

source, release the lock, and then process those items. This is a performance optimization for the general case,

where the number of trips back to the data source and the number of times the lock must be acquired and

released is minimized. However, it’s then also very important that the processing of elements not have

dependencies between them.


Patterns of Parallel Programming Page 91


Consider a very simple example:


C#


var mres = new ManualResetEventSlim();

Parallel.ForEach(Enumerable.Range(0, 10), i =>

{


if (i == 7) mres.Set();

else mres.Wait();

});


Theoretically, this code could deadlock. All iterations have a dependency on iteration #7 executing, and yet the

same thread that executed one of the other iterations may be the one destined to execute #7. To see this, consider

a potential partitioning of the input data [0,10), where every thread grabs two elements at a time:


0123456789

Here, the same thread grabbed both elements 6 and 7. It then processes 6, which immediately blocks waiting for

an event that will only be set when 7 is processed, but 7 won’t ever be processed, because the thread that would

process it is blocked processing 6.


Back to our ParallelWhileNotEmpty example, a similar issue exists there but is less obvious. The last element to be

processed marks the BlockingCollection as complete for adding, which will cause any threads waiting on the

empty collection to wake up, aware that no more data will be coming. However, threads are pulling multiple data

elements from the source on each go around, and are not processing the elements from that chunk until the chunk

contains a certain number of elements. Thus, a thread may grab what turns out to be the last element, but then

continues to wait for more elements to arrive before processing it; however, only when that last element is


processed will the collection signal to all waiting threads that there won’t be any more data, and we have a


deadlock.


We can fix this by modifying the partitioning such that every thread only goes for one element at a time. That has

the downside of resulting in more overhead per element, since each element will result in a lock being taken, but it

has the serious upside of not resulting in deadlock. To control that, we can supply a custom partitioner that

provides this functionality. The parallel programming samples for the .NET Framework 4, available for download at

http://code.msdn.microsoft.com/ParExtSamples includes a ChunkPartitioner capable of yielding a single element

at a time. Taking advantage of that, we get the following fixed solution:


C#


static void ParallelWhileNotEmpty<T>(

IEnumerable<T> source, Action<T, Action<T>> body)


{

var queue = new ConcurrentQueue<T>(source);

if (queue.IsEmpty) return;


var remaining = new CountdownEvent(queue.Count);


var bc = new BlockingCollection<T>(queue);


Patterns of Parallel Programming Page 92


Action<T> adder = t => {

remaining.AddCount();

bc.Add(t);


};

var options = new ParallelOptions {


MaxDegreeOfParallelism = Environment.ProcessorCount

};

Parallel.ForEach(ChunkPartitioner.Create(bc.GetConsumingEnumerable(), 1),


options, item =>


{

try { body(item, adder); }

finally {


if (remaining.Signal()) bc.CompleteAdding();

}

});

}


Patterns of Parallel Programming Page 93


S P E C U L A T I V E P R O C E S S I N G S P E C U L A T I V E P R O C E S S I N G

Speculation is the pattern of doing something that may not be needed in case it actually is needed. This is

increasing relevant to parallel computing, where we can take advantage of multiple cores to do more things in

advance of their actually being needed. Speculation trades off throughput for reduced latency, by utilizing

resources to do more work in case that extra work could pay dividends.


T H E R E C A N B E O N L Y O N E


There are many scenarios where multiple mechanisms may be used to compute a result, but how long each

mechanism will take can’t be predicted in advance. With serial computing, you’re forced to pick one and hope that

it’s the fastest. With parallel computing, we can theoretically run them all in parallel: once we have a winner, we

can stop running the rest of the operations.


We can encapsulate this functionality into a SpeculativeInvoke operation. SpeculativeInvoke will take a set of

functions to be executed, and will start executing them in parallel until at least one returns.


C#


public static T SpeculativeInvoke<T>(params Func<T>[] functions);


As mentioned earlier in the section on parallel loops, it’s possible to implement Invoke in terms of ForEach… we

can do the same here for SpeculativeInvoke:


C#


public static T SpeculativeInvoke<T>(params Func<T>[] functions)


{


return SpeculativeForEach(functions, function => function());


}


Now all we need is a SpeculativeForEach.


S P E C U L A T I V E F O R E A C H U S I N G P A R A L L E L . F O R E A CH


With ForEach, the goal is to process every item. With SpeculativeForEach, the goal is to get just one result,

executing as many items as we can in parallel in order to get just one to return.


C#


public static TResult SpeculativeForEach<TSource, TResult>(

IEnumerable<TSource> source,

Func<TSource, TResult> body)


{

object result = null;

Parallel.ForEach(source, (item, loopState) =>

{


result = body(item);


loopState.Stop();

});

return (TResult)result;


}


Patterns of Parallel Programming Page 94


We take advantage of Parallel.ForEach’s support for breaking out of a loop early, using ParallelLoopState.Stop.

This tells the loop to try not to start any additional iterations. When we get a result from an iteration, we store it,

request that the loop stop as soon as possible, and when the loop is over, return the result. A

SpeculativeParallelFor could be implemented in a very similar manner.


Note that we store the result as an object, rather than as a TResult. This is to

accommodate value types. With multiple iterations executing in parallel, it’s possible

that multiple iterations may try to write out a result concurrently. With reference

types, this isn’t a problem, as the CLR ensures that all of the data in a reference is

written atomically. But with value types, we could potentially experience “torn

writes,” where portions of the results from multiple iterations get written, resulting in

an incorrect result.


As noted, when an iteration completes it does not terminate other currently running iterations, it only works to

prevent additional iterations from starting. If we want to update the implementation to also make it possible to

cancel currently running iterations, we can take advantage of the .NET Framework 4 CancellationToken type. The

idea is that we’ll pass a CancellationToken into all functions, and the functions themselves may monitor for

cancellation, breaking out early if cancellation was experienced.


C#


public static TResult SpeculativeForEach<TSource, TResult>(

IEnumerable<TSource> source,

Func<TSource, CancellationToken, TResult> body)


{


var cts = new CancellationTokenSource();


object result = null;

Parallel.ForEach(source, (item, loopState) =>

{


try


{

result = body(item, cts.Token);

loopState.Stop();


cts.Cancel();

}

catch (OperationCanceledException) { }


});

return (TResult)result;

}


S P E C U L A T I V E F O R E A C H U S I N G P L I N Q


We can also achieve this kind of speculative processing utilizing PLINQ. The goal of SpeculativeForEach is to select

the result of the first function to complete, an operation which maps very nicely to PLINQ’s Select and First

operators. We can thus re-implement SpeculativeForEach with very little PLINQ-based code:


C#


public static TResult SpeculativeForEach<TSource, TResult>(

IEnumerable<TSource> source, Func<TSource, TResult> body)


{


Patterns of Parallel Programming Page 95


if (body == null) throw new ArgumentNullException(“body”);

return source.AsParallel().Select(i => body(i)).First();


}


F O R T H E F U T U R E


The other large classification of speculative processing is around anticipation: an application can anticipate a need,

and do some computation based on that guess. Prefetching, common in hardware and operating systems, is an

example of this. Based on past experience and heuristics, the system anticipates that the program is going to need

a particular resource and thus preloads that resource so that it’s available by the time it’s needed. If the system

guessed correctly, the end result is improved perceived performance.


Task<TResult> in the .NET Framework 4 makes it very straightforward to implement this kind of logic. When the

system anticipates a particular computation’s result may be needed, it launches a Task<TResult> to compute the

result.


C#


var cts = new CancellationTokenSource();


Task<int> dataForThefuture = Task.Factory.StartNew(

() => ComputeSomeResult(), cts.Token);


If it turns out that result is not needed, the task may be canceled.


C#


// Cancel it and make sure we are made aware of any exceptions

// that occurred.


cts.Cancel();


dataForTheFuture.ContinueWith(t => LogException(dataForTheFuture),

TaskContinuationOptions.OnlyOnFaulted);


If it turns out it is needed, its Result may be retrieved.


C#


// This will return the value immediately if the Task has already


// completed, or will wait for the result to be available if it’s


// not yet completed.


int result = dataForTheFuture.Result;


Patterns of Parallel Programming Page 96


L A Z I N E S S L A Z I N E S S

Programming is one of few professional areas where laziness is heralded. As we write software, we look for ways

to improve performance, or at least to improve perceived performance, and laziness helps in both of these

regards.


Lazy evaluation is all about delaying a computation such that it’s not evaluated until it’s needed . In doing so, we

may actually get away with never evaluating it at all, since it may never be needed. And other times, we can make

the cost of evaluating lots of computations “pay-for-play” by only doing those computations when they’re needed

and not before. (In a sense, this is the opposite of speculative computing, where we may start computations

asynchronously as soon as we think they may be needed, in order to ensure the results are available if they’re

needed.)


Lazy evaluation is not something at all specific to parallel computing. LINQ is heavily based on a lazy evaluation

model, where queries aren’t executed until MoveNext is called on an enumerator for the query. Many types lazilyload

data, or lazily initialize properties. Where parallelization comes into play is in making it possible for multiple

threads to access lazily-evaluated data in a thread-safe manner.


E N C A P S U L A T I N G L A Z I N E S S


Consider the extremely common pattern for lazily-initializing some property on a type:


C#


public class MyLazy<T> where T : class

{

private T _value;


public T Value

{


get


{

if (_value == null) _value = Compute();

return _value;


}

}


private static T Compute() { /*…*/ }

}


Here, the _value field needs to be initialized to the result of some function Compute. _value could have been

initialized in the constructor of MyLazy<T>, but that would have forced the user to incur the cost of computing

_value, even if the Value property is never accessed. Instead, the Value property’s get accessor checks to see

whether _value has been initialized, and if it hasn’t, initializes it before returning _value. The initialization check

happens by comparing _value to null, hence the class restriction on T, since a struct may never be null.


Unfortunately, this pattern breaks down if the Value property may be accessed from multiple threads

concurrently. There are several common patterns for dealing with this predicament. The first is through locking:


Patterns of Parallel Programming Page 97


C#


public class MyLazy<T> where T : class

{


private object _syncObj = new object();


private T _value;


public T Value


{


get


{


lock (_syncObj)

{


if (_value == null) _value = Compute();

return _value;


}


}

}


private static T Compute() { /*…*/ }

}


Now, the Value property is thread-safe, such that only one thread at a time will execute the body of the get

accessor. Unfortunately, we also now force every caller of Value to accept the cost of taking a lock, even if Value

has already previously been initialized. To work around that, there’s the classic double-checked locking pattern:


C#


public class MyLazy<T> where T : class


{

private object _syncObj = new object();

private volatile T _value;


public T Value

{


get


{


if (_value == null)


{

lock(_syncObj)

{


if (_value == null) _value = Compute();

}

}


return _value;


}


private static T Compute() { /*…*/ }

}


This is starting to get complicated, with much more code having to be written than was necessary for the initial

non-thread-safe version. Moreover, we haven’t factored in the complications of exception handling, supporting

value types in addition to reference types (and having to deal with potential “torn reads” and “torn writes”), cases

where null is a valid value, and more. To simplify this, all aspects of the pattern, including the synchronization to

ensure thread-safety, have been codified into the new .NET Framework 4 System.Lazy<T> type. We can re-write

the code using Lazy<T> as follows:


Patterns of Parallel Programming Page 98


C#


public class MyLazy<T>

{


private Lazy<T> _value = new Lazy<T>(Compute);

public T Value { get { return _value.Value; } }

private static T Compute() { /*…*/ }


}


Lazy<T> supports the most common form of thread-safe initialization through a simple-to-use interface. If more

control is needed, the static methods on System.Threading.LazyInitializer may be employed.


The double-checked locking pattern supported by Lazy<T> is also supported by LazyInitializer, but through a single

static method:


C#


public static T EnsureInitialized<T>(

ref T target, ref bool initialized,

ref object syncLock,

Func<T> valueFactory);


This overload allows the developer to specify the target reference to be initialized as well as a Boolean value that

signifies whether initialization has been completed. It also allows the developer to explicitly specify the monitor

object to be used for synchronization.


Being able to explicitly specify the synchronization object allows multiple

initialization routines and fields to be protected by the same lock.


We can use this method to re-implement our previous examples as follows:


C#


public class MyLazy<T> where T : class


{

private object _syncObj = new object();

private bool _initialized;

private T _value;


public T Value

{


get


{

return LazyInitializer.EnsureInitialized(

ref _value, ref _initialized, ref _syncObj, Compute);

}

}


private static T Compute() { /*…*/ }

}


This is not the only pattern supported by LazyInitializer, however. Another less-common thread-safe initialization

pattern is based on the principle that the initialization function is itself thread-safe, and thus it’s okay for it to be

executed concurrently with itself. Given that property, we no longer need to use a lock to ensure that only one


Patterns of Parallel Programming Page 99


thread at a time executes the initialization function. However, we still need to maintain the invariant that the value

being initialized is only initialized once. As such, while the initialization function may be run multiple times

concurrently in the case of multiple threads racing to initialize the value, one and only one of the resulting values

must be published for all threads to see. If we were writing such code manually, it might look as follows:


C#


public class MyLazy<T> where T : class

{

private volatile T _value;


public T Value

{


get


{

if (_value == null)

{


T temp = Compute();


Interlocked.CompareExchange(ref _value, temp, null);

}

return _value;


}

}


private static T Compute() { /*…*/ }

}


LazyInitializer provides an overload to support this pattern as well:


C#


public static T EnsureInitialized<T>(

ref T target, Func<T> valueFactory) where T : class;


With this method, we can re-implement the same example as follows:


C#


public class MyLazy<T> where T : class

{

private T _value;


public T Value

{


get


{

return LazyInitializer.EnsureInitialized(ref _value, Compute);

}

}


private static T Compute() { /*…*/ }

}


It’s worth noting that in these cases, if the Compute function returns null, _value will be set to null, which is

indistinguishable from Compute never having been run, and as a result the next time Value’s get accessor is

invoked, Compute will be executed again.


Patterns of Parallel Programming Page 100


A S Y N C H R O N O U S L A Z I N E S S


Another common pattern centers around a need to lazily-initialize data asynchronously and to receive notification

when the initialization has completed. This can be accomplished by marrying two types we’ve already seen:

Lazy<T> and Task<TResult>.


Consider an initialization routine:


C#


T Compute();


We can create a Lazy<T> to provide the result of this function:


C#


Lazy<T> data = new Lazy<T>(Compute);


However, now when we access data.Value, we’re blocked waiting for the Compute operation to complete.

Instead, for asynchronous lazy initialization, we’d like to delay the computation until we know we’ll need it, but

once we do we also don’t want to block waiting for it to complete. That latter portion should hint at using a

Task<TResult>:


C#


Task<T> data = Task<T>.Factory.StartNew(Compute);


Combining the two, we can use a Lazy<Task<T>> to get both the delayed behavior and the asynchronous behavior:


C#


var data = new Lazy<Task<T>>(() => Task<T>.Factory.StartNew(Compute));


Now when we access data.Value, we get back a Task<T> that represents the running of Compute. No matter how

many times we access data.Value, we’ll always get back the same Task, even if accessed from multiple threads

concurrently, thanks to support for the thread-safety patterns built into Lazy<T>. This means that only one

Task<T> will be launched for Compute. Moreover, we can now use this result as we would any other Task<T>,

including registering continuations with it (using ContinueWith) in order to be notified when the computation is

complete:


C#


data.Value.ContinueWith(t => UseResult(t.Result));


This approach can also be combined with multi-task continuations to lazily-initialize multiple items, and to only do


work with those items when they’ve all completed initialization:


C#


private Lazy<Task<T>> _data1 = new Lazy<Task<T>>(() =>

Task<T>.Factory.StartNew(Compute1));


private Lazy<Task<T>> _data2 = new Lazy<Task<T>>(() =>

Task<T>.Factory.StartNew(Compute2));


private Lazy<Task<T>> _data3 = new Lazy<Task<T>>(() =>

Task<T>.Factory.StartNew(Compute3));


//…


Patterns of Parallel Programming Page 101


Task.Factory.ContinueWhenAll(


new [] { _data1.Value, _data2.Value, _data3.Value },


tasks => UseResults(_data1.Value.Result, _data2.Value.Result,


_data3.Value.Result));


Such laziness is also useful for certain patterns of caching, where we want to maintain a cache of these lazilyinitialized

values. Consider a non-thread-safe cache like the following:


C#


public class Cache<TKey, TValue>


{

private readonly Func<TKey, TValue> _valueFactory;

private readonly Dictionary<TKey, TValue> _map;


public Cache(Func<TKey, TValue> valueFactory)


{

if (valueFactory == null) throw new ArgumentNullException(“loader”);

_valueFactory = valueFactory;

_map = new Dictionary<TKey, TValue>();


}


public TValue GetValue(TKey key)

{

if (key == null) throw new ArgumentNullException(“key”);


TValue val;

if (!_map.TryGetValue(key, out val))

{


val = _valueFactory(key);


_map.Add(key, val);

}

return val;


}

}


The cache is initialized with a function that produces a value based on a key supplied to it. Whenever the value of a

key is requested from the cache, the cache returns the cached value for the key if one is available in the internal

dictionary, or it generates a new value using the cache’s _valueFactory function, stores that value for later, and

returns it.


We now want an asynchronous version of this cache. Just like with our asynchronous laziness functionality, we can

represent this as a Task<TValue> rather than simply as a TValue. Multiple threads will be accessing the cache

concurrently, so we want to use a ConcurrentDictionary<TKey,TValue> instead of a Dictionary<TKey,TValue>

(ConcurrentDictionary<> is a new map type available in the .NET Framework 4, supporting multiple readers and

writers concurrently without corrupting the data structure).


C#


public class AsyncCache<TKey, TValue>

{


private readonly Func<TKey, Task<TValue>> _valueFactory;

private readonly ConcurrentDictionary<TKey, Lazy<Task<TValue>>> _map;


public AsyncCache(Func<TKey, Task<TValue>> valueFactory)

{


Patterns of Parallel Programming Page 102


if (valueFactory == null) throw new ArgumentNullException(“loader”);

_valueFactory = valueFactory;

_map = new ConcurrentDictionary<TKey, Lazy<Task<TValue>>>();


}


public Task<TValue> GetValue(TKey key)


{

if (key == null) throw new ArgumentNullException(“key”);

return _map.GetOrAdd(key,


k => new Lazy<Task<TValue>>(() => _valueFactory(k))).Value;

}

}


The function now returns a Task<TValue> instead of just TValue, and the dictionary stores Lazy<Task<TValue>>

rather than just TValue. The latter is done so that if multiple threads request the value for the same key

concurrently, only one task for that value will be generated.


Note the GetOrAdd method on ConcurrentDictionary. This method was added in recognition of a very common

coding pattern with dictionaries, exemplified in the earlier synchronous cache example. It’s quite common to want

to check a dictionary for a value, returning that value if it could be found, otherwise creating a new value, adding

it, and returning it, as exemplified in the following example:


C#


public static TValue GetOrAdd<TKey, TValue>(

this Dictionary<TKey, TValue> dictionary,

TKey key, Func<TKey, TValue> valueFactory)


{

TValue value;

if (!dictionary.TryGetValue(key, out value))

{


value = valueFactory(key);


dictionary.Add(key, value);

}

return value;


}


This pattern has been codified into ConcurrentDictionary in a thread-safe manner in the form of the GetOrAdd

method. Similarly, another coding pattern that’s quite common with dictionaries is around checking for an existing

value in the dictionary, updating that value if it could be found or adding a new one if it couldn’t .


C#


public static TValue AddOrUpdate<TKey, TValue>(

this Dictionary<TKey, TValue> dictionary,

TKey key,

Func<TKey, TValue> addValueFactory,

Func<TKey, TValue, TValue> updateValueFactory)


{

TValue value;

value = dictionary.TryGetValue(key, out value) ?


updateValueFactory(key, value) : addValueFactory(key);

dictionary[key] = value;

return value;


}


Patterns of Parallel Programming Page 103


This pattern has been codified into ConcurrentDictionary in a thread-safe manner in the form of the AddOrUpdate

method.


Patterns of Parallel Programming Page 104


S H A R E D S T A T E S H A R E D S T A T E

Dealing with shared state is arguably the most difficult aspect of building parallel applications and is one of the

main sources of both correctness and performance problems. There are several ways of dealing with shared state,

including synchronization, immutability, and isolation. With synchronization, the shared state is protected by

mechanisms of mutual exclusion to ensure that the data remains consistent in the face of multiple threads

accessing and modifying it. With immutability, shared data is read-only, and without being modified, there’s no

danger in sharing it. With isolation, sharing is avoided, with threads utilizing their own isolated state that’s not


available to other threads.


I S O L A T I O N & T H R E A D -L O C A L S T A T E


Thread-local state is a very common mechanism for supporting isolation, and there are several reasons why you

might want to use thread-local state. One is to pass information out-of-band between stack frames. For example,

the System.Transactions.TransactionScope class is used to register some ambient information for the current

thread, such that operations (for example, commands against a database) can automatically enlist in the ambient

transaction. Another use of thread-local state is to maintain a cache of data per thread rather than having to

synchronize on a shared data source. For example, if multiple threads need random numbers, each thread can

maintain its own Random instance, accessing it freely and without concern for another thread accessing it

concurrently; an alternative would be to share a single Random instance, locking on access to it.


Thread-local state is exposed in the .NET Framework 4 in three different ways. The first way, and the most

efficient, is through the ThreadStaticAttribute. By applying [ThreadStatic] to a static field of a type, that field

becomes a thread-local static, meaning that rather than having one field of storage per AppDomain (as you would

with a traditional static), there’s one field of storage per thread per AppDomain.


Hearkening back to our randomness example, you could imagine trying to initialize a ThreadStatic Random field as

follows:


C#


[ThreadStatic]

static Random _rand = new Random(); // WARNING: buggy


static int GetRandomNumber()


{


return _rand.Next();


}


Unfortunately, this won’t work as expected. The C# and Visual Basic compilers extract initialization for

static/Shared members into a static/Shared constructor for the containing type, and a static constructor is only run

once. As such, this initialization code will only be executed for one thread in the system, leaving the rest of the

threads with _rand initialized to null. To account for this, we need to check prior to accessing _rand to ensure it’s

been initialized, invoking the initialization code on each access if it hasn’t been:


C#


[ThreadStatic]

static Random _rand;


static int GetRandomNumber()


Patterns of Parallel Programming Page 105


{


if (_rand == null) _rand = new Random();


return _rand.Next();


}


Any thread may now call GetRandomNumber, and any number of threads may do so concurrently; each will end

up utilizing its own instance of Random. Another issue with this approach is that, unfortunately, [ThreadStatic]

may only be used with statics. Applying this attribute to an instance member is a no-op, leaving us in search of

another mechanism for supporting per-thread, per-instance state.


Since the original release of the .NET Framework, thread-local storage has been supported in a more general form

through the Thread.GetData and Thread.SetData static methods. The Thread.AllocateDataSlot and

Thread.AllocateNamedDataSlot static methods may be used to create a new LocalDataStoreSlot, representing a

single object of storage. The GetData and SetData methods can then be used to get and set that object for the

current thread. Re-implementing our previous Random example could be done as follows:


C#


static LocalDataStoreSlot _randSlot = Thread.AllocateDataSlot();


static int GetRandomNumber()


{

Random rand = (Random)Thread.GetData(_randSlot);

if (rand == null)

{


rand = new Random();


Thread.SetData(_randSlot, rand);

}

return rand.Next();


}


However, since our thread-local storage is now represented as an object (LocalDataStoreSlot) rather than as a

static field, we can use this mechanism to achieve the desired per-thread, per-instance data:


C#


public class MyType


{

private LocalDataStoreSlot _rand = Thread.AllocateDataSlot();


public int GetRandomNumber()


{

Random r = (Random)Thread.GetData(_rand);

if (r == null)

{


r = new Random();


Thread.SetData(_rand, r);

}

return r.Next();


}

}


While flexible, this approach also has downsides. First, Thread.GetData and Thread.SetData work with type Object

rather than with a generic type parameter. In the best case, the data being stored is a reference type, and we only

need to cast to retrieve data from a slot, knowing in advance what kind of data is stored in that slot . In the worst

case, the data being stored is a value type, forcing an object allocation every time the data is modified, as the value


Patterns of Parallel Programming Page 106


type gets boxed when passed into the Thread.SetData method. Another issue is around performance. The

ThreadStaticAttribute approach has always been significantly faster than the Thread.GetData/SetData approach,

and while both mechanisms have been improved for the .NET Framework 4, the ThreadStaticAttribute approach is

still an order of magnitude faster. Finally, with Thread.GetData/SetData, the reference to the storage and the

capability for accessing that storage are separated out into individual APIs, rather than being exposed in a

convenient manner that combines them in an object-oriented manner.


To address these shortcomings, the .NET Framework 4 introduces a third thread-local storage mechanism:

ThreadLocal<T>. ThreadLocal<T> addresses the shortcomings outlined:


.

ThreadLocal<T> is generic. It’s Value property is typed as T and the data is stored in a generic manner.

This eliminates the need to cast when accessing the value, and it eliminates the boxing that would

otherwise occur if T were a value type.


.

The constructor for ThreadLocal<T> optionally accepts a Func<T> delegate. This delegate can be used to

initialize the thread-local value on every accessing thread. This alleviates the need to explicitly check on

every access to ThreadLocal<T>.Value whether it’s been initialized yet.


.

ThreadLocal<T> encapsulates both the data storage and the mechanism for accessing that storage. This

simplifies the pattern of accessing the storage, as all that’s required is to utilize the Value property.

.

ThreadLocal<T>.Value is fast. ThreadLocal<T> has a sophisticated implementation based on

ThreadStaticAttribute that makes the Value property more efficient than Thread.GetData/SetData.


ThreadLocal<T> is still not as fast as ThreadStaticAttribute, so if ThreadStaticAttribute fits your needs well and if

access to thread-local storage is a bottleneck on your fast path, it should still be your first choice. Additionally, a

single instance of ThreadLocal<T> consumes a few hundred bytes, so you need to consider how many of these you

want active at any one time.


Regardless of what mechanism for thread-local storage you use, if you need thread-local storage for several

successive operations, it’s best to work on a local copy so as to avoid accessing thread-local storage as much as

possible. For example, consider adding two vectors stored in thread-local storage:


C#


const int VECTOR_LENGTH = 1000000;

private ThreadLocal<int[]> _vector1 =

new ThreadLocal<int[]>(() => new int[VECTOR_LENGTH]);

private ThreadLocal<int[]> _vector2 =

new ThreadLocal<int[]>(() => new int[VECTOR_LENGTH]);


// …


private void DoWork()


{

for(int i=0; i<VECTOR_LENGTH; i++)

{


_vector2.Value[i] += _vector1.Value[i];

}

}


While the cost of accessing ThreadLocal<T>.Value has been minimized as best as possible in the implementation, it

still has a non-negligible cost (the same is true for accessing ThreadStaticAttribute). As such, it’s much better to

rewrite this code as follows:


Patterns of Parallel Programming

Page 107


C#


private void DoWork()

{


int [] vector1 = _vector1.Value;

int [] vector2 = _vector2.Value;

for(int i=0; i<VECTOR_LENGTH; i++)

{


vector2[i] += vector1[i];

}

_vector2.Value = vector2;


}


Returning now to our previous example of using a thread-local Random, we can take advantage of ThreadLocal<T>

to implement this support in a much more concise manner:


C#


public class MyType

{


private ThreadLocal<Random> _rand =


new ThreadLocal<Random>(() => new Random());


public int GetRandomNumber() { return _rand.Value.Next(); }

}


Earlier in this document, it was mentioned that the ConcurrentBag<T> data structure

maintains a list of instances of T per thread. This is achieved internally using

ThreadLocal<>.


S Y N C H R O N I Z A T I O N


In most explicitly-threaded parallel applications, no matter how much we try, we end up with some amount of

shared state. Accessing shared state from multiple threads concurrently requires that either that shared state be

immutable or that the application utilize synchronization to ensure the consistency of the data.


R E L I A B L E L O C K A C Q U I S I T I O N


By far, the most prevalent pattern for synchronization in the .NET Framework is in usage of the lock keyword in C#

and the SyncLock keyword in Visual Basic. Compiling down to usage of Monitor under the covers, this pattern

manifests as follows:


C#


lock (someObject)

{


// … critical region of code


}


Patterns of Parallel Programming Page 108


This code ensures that the work inside the critical region is executed by at most one thread at a time. In C# 3.0 and

earlier and Visual Basic 9.0 and earlier, the above code was compiled down to approximately the equivalent of the

following:


C#


var lockObj = someObject;


Monitor.Enter(lockObj);


try


{


// … critical region of code


}


finally


{


Monitor.Exit(lockObj);


}


This code ensures that even in the case of exception, the lock is released when the critical region is done. Or at

least it’s meant to. A problem emerges due to asynchronous exceptions: external influences may cause exceptions

to occur on a block of code even if that exception is not explicitly stated in the code. In the extreme case, a thread

abort may be injected into a thread between any two instructions, though not within a finally block except in

extreme conditions. If such an abort occurred after the call to Monitor.Enter but prior to entering the try block,

the monitor would never be exited, and the lock would be “leaked.” To help prevent against this, the just-in-time

(JIT) compiler ensures that, as long as the call to Monitor.Enter is the instruction immediately before the try block,

no asynchronous exception will be able to sneak in between the two. Unfortunately, it’s not always the case that

these instructions are immediate neighbors. For example, in debug builds, the compiler uses nop instructions to

support setting breakpoints in places that breakpoints would not otherwise be feasible. Worse, it’s often the case

that developers want to enter a lock conditionally, such as with a timeout, and in such cases there are typically

branching instructions between the call and entering the try block:


C#


if (Monitor.TryEnter(someObject, 1000))

{


try


{


// … critical region of code


}


finally


{


Monitor.Exit(someObject);

}


}

else { /*…*/ }


To address this, in the .NET Framework 4 new overloads of Monitor.Enter (and Monitor.TryEnter) have been

added, supporting a new pattern of reliable lock acquisition and release:


C#


public static void Enter(object obj, ref bool lockTaken);


This overload guarantees that the lockTaken parameter is initialized by the time Enter returns, even in the face of

asynchronous exceptions. This leads to the following new, reliable pattern for entering a lock:


Patterns of Parallel Programming Page 109


C#


bool lockTaken = false;


try


{


Monitor.Enter(someObject, ref lockTaken);


// … critical region of code


}


finally


{


if (lockTaken) Monitor.Exit(someObject);


}


In fact, code similar to this is what the C# and Visual Basic compilers output in the .NET Framework 4 for the lock

and SyncLock construct. This pattern applies equally to TryEnter, with only a slight modification:


C#


bool lockTaken = false;

try


{

Monitor.TryEnter(someObject, 1000, ref lockTaken);

if (lockTaken)

{


// … critical region of code


}

else { /*…*/ }


}


finally


{

if (lockTaken) Monitor.Exit(someObject);

}


Note that the new System.Threading.SpinLock type also follows this new pattern, and in fact provides only the

reliable overloads:


C#


public struct SpinLock


{


public void Enter(ref bool lockTaken);


public void TryEnter(ref bool lockTaken);


public void TryEnter(TimeSpan timeout, ref bool lockTaken);


public void TryEnter(int millisecondsTimeout, ref bool lockTaken);


// …


}


With these methods, SpinLock is then typically used as follows:


C#


private static SpinLock _lock = new SpinLock(enableThreadOwnerTracking: false);


// …


bool lockTaken = false;

try


{

_lock.Enter(ref lockTaken);


// … very small critical region here


}


Patterns of Parallel Programming Page 110


finally


{


if (lockTaken) _lock.Exit(useMemoryBarrier: false);

}


Alternatively, SpinLock may be used with TryEnter as follows:


C#


bool lockTaken = false;


try


{


_lock.TryEnter(ref lockTaken);


if (lockTaken)


{


// … very small critical region here


}


else { /*…*/ }


}


finally


{


if (lockTaken) _lock.Exit(useMemoryBarrier:false);


}


The concept of a spin lock is that rather than blocking, it continually iterates through a loop (“spinning”), until the

lock is available. This can lead to benefits in some cases, where contention on the lock is very infrequent, and

where if there is contention, the lock will be available in very short order. This then allows the application to avoid

costly kernel transitions and context switches, instead iterating through a loop a few times. When used at incorrect

times, however, spin locks can lead to significant performance degradation in an application.


The constructor to SpinLock accepts an enableThreadOwnerTracking parameter,

which default to true. This causes the SpinLock to keep track of which thread

currently owns the lock, and can be useful for debugging purposes. This does,

however, have an effect on the lock’s behavior when the lock is misused . SpinLock is

not reentrant, meaning that a thread may only acquire the lock once. If thread

holding the lock tries to enter it again, and if enableThreadOwnerTracking is true,

the call to Enter will throw an exception. If enableThreadOwnerTracking is false,

however, the call will deadlock, spinning forever.


In general, if you need a lock, start with Monitor. Only if after performance testing do you find that Monitor isn’t

fitting the bill should SpinLock be considered. If you do end up using a SpinLock, inside the protected region you

should avoid blocking or calling anything that may block, trying to acquire another lock, calling into unknown code

(including calling virtual methods, interface methods, or delegates), and allocating memory. You should be able to

count the number of instructions executed under a spin lock on two hands, with the total amount of CPU

utilization in the protected region amounting to only tens of cycles.


MIXING EXCEPTIONS W I TH LOCKS


As described, a lot of work has gone into ensuring that locks are properly released, even if exceptions occur within

the protected region. This, however, isn’t always the best behavior.


Patterns of Parallel Programming Page 111


Locks are used to make non-atomic sets of actions appear atomic, and that’s often needed due to multiple

statements making discrete changes to shared state. If an exception occurs inside of a critical region, that

exception may leave shared data in an inconsistent state. All of the work we’ve done to ensure reliable lock release

in the face of exceptions now leads to a problem: another thread may acquire the lock and expect state to be


consistent, but find that it’s not.


In these cases, we have a decision to make: is it better to allow threads to access potentially inconsistent state, or

is it better to deadlock (which would be achievable by not releasing the lock, but by “leaking” it instead)? The

answer really depends on the case in question.


If you decide that leaking a lock is the best solution, instead of using the aforementioned patterns the following

may be employed:


C#


Monitor.Enter(someObject);


// … critical region


Monitor.Exit(someObject);


Now if an exception occurs in the critical region, the lock will not be exited, and any other threads that attempt to

acquire this lock will deadlock. Of course, due to the reentrancy supported by Monitor in the .NET Framework, if

this same thread later attempts to enter the lock, it will succeed in doing so.


A V O I D I N G D E A D L O C K S


Of all of the problems that may result from incorrect synchronization, deadlocks are one of the most well -known.

There are four conditions required for a deadlock to be possible:


1.

Mutual exclusion. Only a limited number of threads may utilize a resource concurrently.

2.

Hold and wait. A thread holding a resource may request access to other resources and wait until it gets

them.

3.

No preemption. Resources are released only voluntarily by the thread holding the resource.

4.

Circular wait. There is a set of {T1, …, TN} threads, where T1 is waiting for a resource held by T2, T2 is

waiting for a resource held by T3, and so forth, up through TN waiting for a resource held by T1.

If any one of these conditions doesn’t hold, deadlock isn’t possible. Thus, in order to avoid deadlock, we need to

ensure that we avoid at least one of these. The most common and actionable condition to avoid in real-world code

is #4, circular waits, and we can attack this condition in a variety of ways. One approach involves detecting that a

cycle is about to occur. We can maintain a store of what threads hold what locks, and if a thread makes an attempt

to acquire a lock that would lead to a cycle, we can prevent it from doing so; an example of this graph analysis is

codified in the “.NET Matters: Deadlock Monitor” article at http://msdn.microsoft.com/enus/

magazine/cc163352.aspx. There is another example in the article “No More Hangs: Advanced Techniques To

Avoid And Detect Deadlocks In .NET Apps” by Joe Duffy at http://msdn.microsoft.com/enus/

magazine/cc163618.aspx. That same article by Joe Duffy also includes an example of another approach: lock

leveling. In lock leveling, locks are assigned numerical values, and the system tracks the smallest value lock held by


Patterns of Parallel Programming

Page 112


a thread, only allowing the thread to acquire locks with smaller values than the smallest value it already holds; this

prevents the potential for a cycle.


In some cases, we can avoid cycles simply by sorting the locks utilized in some consistent way, and ensuring that if

multiple locks need to be taken, they’re taken in sorted order (this is, in effect, a lock leveling scheme). We can see

a simple example of this in an implementation of the classic “dining philosophers” problem.


The dining philosophers problem was posited by Tony Hoare, based on previous examples from Edsger Dijkstra in

the 1960s. The basic idea is that five philosophers sit around a table. Every philosopher has a plate of pasta, and

between every pair of philosophers is a fork. To eat the pasta, a philosopher must pick up and use the forks on

both sides of him; thus, if a philosopher’s neighbor is eating, the philosopher can’t. Philosophers alternate

between thinking and eating, typically for random periods of time.


We can represent each fork as a lock, and a philosopher must acquire both locks in order to eat. This would result

in a solution like the following:


C#


// WARNING: THIS METHOD HAS A BUG


const int NUM_PHILOSOPHERS = 5;

object[] forks = new object[NUM_PHILOSOPHERS];

var philosophers = new Task[NUM_PHILOSOPHERS];

for (int i = 0; i < NUM_PHILOSOPHERS; i++)

{


int id = i;

philosophers[i] = Task.Factory.StartNew(() =>

{


Patterns of Parallel Programming Page 113


var rand = new Random(id);

while (true)

{


// Think


Thread.Sleep(rand.Next(100, 1000));


// Get forks


object leftFork = forks[id];

object rightFork = forks[(id + 1) % NUM_PHILOSOPHERS];

Monitor.Enter(leftFork);

Monitor.Enter(rightFork);


// Eat


Thread.Sleep(rand.Next(100, 1000));


// Put down forks


Monitor.Exit(rightFork);

Monitor.Exit(leftFork);

}


}, TaskCreationOptions.LongRunning);

}

Task.WaitAll(philosophers);


Unfortunately, this implementation is problematic. If every philosopher were to pick up his left fork at the same

time, all of the forks would be off the table. Each philosopher would then attempt to pick up the right fork and

would need to wait indefinitely. This is a classic deadlock, following the exact circular wait condition previously

described.


To fix this, we can eliminate the cycle by ensuring that a philosopher first picks up the lower numbered fork and

then the higher numbered fork, even if that means picking up the right fork first:


C#


while (true)

{


// Think


Thread.Sleep(rand.Next(100, 1000));


// Get forks in sorted order to avoid deadlock


int firstForkId = id, secondForkId = (id + 1) % NUM_PHILOSOPHERS;

if (secondForkId < firstForkId) Swap(ref firstForkId, ref secondForkId);

object firstFork = forks[firstForkId];

object secondFork = forks[secondForkId];

Monitor.Enter(firstFork);

Monitor.Enter(secondFork);


// Eat


Thread.Sleep(rand.Next(100, 1000));


// Put down forks


Monitor.Exit(secondFork);

Monitor.Exit(firstFork);

}


Another solution is to circumvent the second deadlock requirement, hold and wait, by utilizing the operating

system kernel’s ability to acquire multiple locks atomically. To accomplish that, we need to forego usage of


Patterns of Parallel Programming Page 114


Monitor, and instead utilize one of the .NET Framework synchronization primitives derived from WaitHandle, such

as Mutex. When we want to acquire both forks, we can then utilize WaitHandle.WaitAll to acquire both forks

atomically. Using WaitAll, we block until we’ve acquired both locks, and no other thread will see us holding one

lock but not the other.


C#


const int NUM_PHILOSOPHERS = 5;


Mutex[] forks = Enumerable.Range(0, NUM_PHILOSOPHERS)

.Select(i => new Mutex())

.ToArray();


var philosophers = new Task[NUM_PHILOSOPHERS];

for (int i = 0; i < NUM_PHILOSOPHERS; i++)

{


int id = i;

philosophers[i] = Task.Factory.StartNew(() =>

{


var rand = new Random(id);

while (true)

{


// Think


Thread.Sleep(rand.Next(100, 1000));


// Get forks together atomically


var leftFork = forks[id];

var rightFork = forks[(id + 1) % NUM_PHILOSOPHERS];

WaitHandle.WaitAll(new[] { leftFork, rightFork });


// Eat


Thread.Sleep(rand.Next(100, 1000));


// Put down forks; order of release doesn’t matter


leftFork.ReleaseMutex();

rightFork.ReleaseMutex();

}


}, TaskCreationOptions.LongRunning);

}

Task.WaitAll(philosophers);


The .NET Framework 4 parallel programming samples at http://code.msdn.microsoft.com/ParExtSamples contain

several example implementations of the dining philosophers problem.


A N T I -P A T T E R N S


L O C K ( T H I S ) A N D L O C K ( T Y P E O F ( S O M E T Y P E ))


Especially in code written early in the .NET Framework’s lifetime, it was common to see synchronization done in


instance members with code such as:


C#


void SomeMethod()


{

lock (this)

{


Patterns of Parallel Programming


Page 115


// … critical region here


}


}


It was also common to see synchronization done in static members with code such as:


C#


static void SomeMethod()


{


lock(typeof(MyType))


{


// … critical region here


}


}


In general, this pattern should be avoided. Good object-oriented design results in implementation details

remaining private through non-public state, and yet here, the locks used to protect that state are exposed. With

these lock objects then public, it becomes possible for an external entity to accidentally or maliciously interfere

with the internal workings of the implementation, as well as make common multithreading problems such as

deadlocks more likely. (Additionally, Type instances can be domain agile, and a lock on a type in one AppDomain

may seep into another AppDomain, even if the state being protected is isolated within the AppDomain.) Instead

and in general, non-public (and non-AppDomain-agile) objects should be used for locking purposes.


The same guidance applies to MethodImplAttribute. The MethodImplAttribute accepts a MethodImplOptions

enumeration value, one of which is Synchronized. When applied to a method, this ensures that only one thread at

a time may access the attributed member:


C#


[MethodImpl(MethodImplOptions.Synchronized)]

void SomeMethod()

{


// … critical region here


}


However, it does so using the equivalent of the explicit locking code shown previously, with a lock on the instance

for instance members and with a lock on the type for static members. As such, this option should be avoided.


R E A D O N L Y S P I N L O C K F I E L D S


The readonly keyword informs the compiler that a field should only be updated by the constructor; any attempts

to modify the field from elsewhere results in a compiler error. As such, you might be tempted to write code like

the following:


C#


private readonly SpinLock _lock; // WARNING!


Don’t do this. Due to the nature of structs and how they interact with the readonly keyword, every access to this

_lock field will return a copy of the SpinLock, rather than the original. As a result, every call to _lock.Enter will

succeed in acquiring the lock, even if another thread thinks it owns the lock.


Patterns of Parallel Programming Page 116


For the same reason, don’t pass try to pass SpinLocks around. In most cases, when you do so, you’ll be making a

copy of the SpinLock. As an example, consider the desire to write an extension method for SpinLock that executes

a user-provided delegate while holding the lock:


C#


// WARNIN ! DON’T DO THIS.


public static void Execute(this SpinLock sl, Action runWhileHoldingLock)


{

bool lockWasTaken = false;

try


{

sl.Enter(ref lockWasTaken);

runWhileHoldingLock();


}


finally


{

if (lockWasTaken) sl.Exit();

}

}


Theoretically, this code should allow you to write code like:


C#


_lock.Execute( () =>

{


… // will be run while holding the lock

});


However, the code is very problematic. The SpinLock being targeted by the method will be passed by value, such

that the method will execute on a copy of the SpinLock rather than the original. To write such a method correctly,

you’d need to pass the SpinLock into the Execute method by reference, and C# doesn’t permit an extension

method to target a value passed by reference. Fortunately, Visual Basic does, and we could write this extension

method correctly as follows:


C#


(This extension method cannot be written in C#.)


Visual Basic


<Extension()>


Public Sub Execute(ByRef sl As SpinLock, ByVal runWhileHoldingLock As Action)

Dim lockWasTaken As Boolean

Try


sl.Enter(lockWasTaken)

runWhileHoldingLock()


Finally

If lockWasTaken Then sl.Exit()

End Try

End Sub


See the blog post at http://blogs.msdn.com/pfxteam/archive/2009/05/07/9592359.aspx for more information

about this dangerous phenomenon.


Patterns of Parallel Programming Page 117


C O N C L U S I O N C O N C L U S I O N

Understanding design and coding patterns as they relate to parallelism will help you to find more areas of your

application that may be parallelized and will help you to do so efficiently. Knowing and understanding patterns of

parallelization will also help you to significantly reduce the number of bugs that manifest in your code. Finally,

using the new parallelization support in the .NET Framework 4 which encapsulate these patterns will not only help

to reduce the bug count further, but it should help you to dramatically decrease the amount of time and code it

takes to get up and running quickly and efficiently.


Now, go forth and parallelize.


Enjoy!


A C K N O W L E D G E M E N T S


The author would like to thank the following people for their feedback on drafts of this paper: Donny Amalo, John

Bristowe, Tina Burden, David Callahan, Chris Dern, Joe Duffy, Ed Essey, Lisa Feigenbaum, Boby George, Scott

Hanselman, Jerry Higgins, Joe Hoag, Luke Hoban, Mike Liddell, Daniela Cristina Manu, Ade Miller, Pooja Nagpal,

Jason Olson, Emad Omara, Igor Ostrovsky, Josh Phillips, Danny Shih, Cindy Song, Mike Stall, Herb Sutter, Don Syme,

Roy Tan, Ling Wo, and Huseyin Yildiz.


A B O U T T H E A U T H O R


Stephen Toub is a Program Manager Lead on the Parallel Computing Platform team at Microsoft, where he spends

his days focusing on the next generation of programming models and runtimes for concurrency. Stephen is also a

Contributing Editor for MSDN® Magazine, for which he writes the .NET Matters column, and is an avid speaker at

conferences such as PDC, TechEd, and DevConnections. Prior to working on the Parallel Computing Platform,

Stephen designed and built enterprise applications for companies such as GE, JetBlue, and BankOne. Stephen

holds degrees in computer science from Harvard University and New York University.


This material is provided for informational purposes only. Microsoft makes no warranties, express or implied.

©2010 Microsoft Corporation.


Patterns of Parallel Programming Page 118


Deploying highly available and secure cloud solutions


Deploying highly available and secure cloud solutions


December 2012


footer left page.jpg Deploying highly available and secure cloud solutions


This document is for informational purposes only. MICROSOFT MAKES NO WARRANTIES, EXPRESS, IMPLIED, OR STATUTORY, AS TO THE INFORMATION IN THIS DOCUMENT.

This document is provided “as-is.” Information and views expressed in this document, including URL and other Internet Web site references, may change without notice. You bear the risk of using it.

Copyright © 2012 Microsoft Corporation. All rights reserved.

The names of actual companies and products mentioned herein may be the trademarks of their respective owners.

Authors and contributors


DAVID BILLS – Microsoft Trustworthy Computing

CHRIS HALLUM – Microsoft Windows

YALE LI – Microsoft IT

MARC LAURICELLA – MicrosoftTrustworthy Computing

ALAN MEEUS – Windows Phone

DARYL PECELJ – Microsoft IT

TIM RAINS – Microsoft Trustworthy Computing

FRANK SIMORJAY – Microsoft Trustworthy Computing

SIAN SUTHERS – Microsoft Trustworthy Computing

TONY URECHE – Microsoft Windows

footer left page.jpg Table of contents Executive summary ……………………………………………………………………………………………………………….. 1 Introduction ………………………………………………………………………………………………………………………….. 3 Measuring reliability and user expectations …………………………………………………………………….. 4 Service-oriented architecture ………………………………………………………………………………………… 4 Separation of function …………………………………………………………………………………………………….. 5 Automatic failover……………………………………………………………………………………………………………. 5 Fault tolerance …………………………………………………………………………………………………………………. 5 Disaster planning …………………………………………………………………………………………………………….. 6 Test and measure …………………………………………………………………………………………………………….. 6 Cloud provider ……………………………………………………………………………………………………………………… 7 Cloud provider expectation and responsibility ……………………………………………………………. 7 Cloud availability ……………………………………………………………………………………………………………… 8 Design for availability ……………………………………………………………………………………………………… 8 Organizational customer of the cloud ……………………………………………………………………………… 11 The organization’s responsibility ………………………………………………………………………………….. 11 Availability of sensitive information stored in the cloud ……………………………………………13 The user and the device used to access the cloud …………………………………………………………15 User expectation and feedback …………………………………………………………………………………….15 Design for test ………………………………………………………………………………………………………………….16 User device availability ……………………………………………………………………………………………………16 Conclusions …………………………………………………………………………………………………………………………..19 Additional reading ……………………………………………………………………………………………………………… 20 Executive summary

Many organizations today are focused on improving the flexibility and performance of cloud applications. Although flexibility and performance are important, cloud applications must also be available to users whenever they want to connect. This paper focuses on key methodologies that technical decision makers can use to ensure that your cloud services, whether public or private, remain available to your users.

At a high level, each cloud session consists of a customer using a computing device to connect to an organization’s cloud-based service that is hosted by an internal or external entity. When planning for a highly available cloud service, it’s important to consider the expectations and responsibilities of each of these parties. Your plan needs to acknowledge the real-world limitations of technology, and that failures can occur. You must then identify how good design can isolate and repair failures with minimal impact on the service’s availability to users.

footer left page.jpg This paper showcases examples for deploying robust cloud solutions to maintain highly available and secure client connections. In addition, it uses real-world examples to discuss scalability issues. The goal of this paper is to demonstrate techniques that mitigate the impact of failures, provide highly available services, and create an optimal overall user experience.

footer left page.jpg Introduction

Customers have high expectations for the reliability of computing infrastructure, and the same expectations apply to cloud services. Uptime, for example, is a commonly used reliability metric. Today, users expect service uptimes from 99.9% (often referred to as three nines) to 99.999% (five nines), which translates to nine hours of downtime per year (at 99.9%) to five minutes of downtime per year (at 99.999%). Service providers frequently distinguish between planned and unplanned outages, but, as IT managers well know, even a planned change can result in unexpected problems. A single unexpected problem can put even a 99.9% service commitment at risk.

Reliability is ultimately about customer satisfaction, which means that managing reliability is a more nuanced challenge than simply measuring uptime. For example, you can imagine a service that never goes down but that is really slow or that is difficult to use. Although maintaining high levels of customer satisfaction is a multifaceted challenge, reliability is the foundation upon which other aspects of customer satisfaction are built. Cloud-based services must be designed from the beginning with reliability in mind. The following principles of cloud service reliability are discussed in this paper:

. Use a service-oriented architecture . Implement separation of function . Design for failure . Automate testing and measurement . Understand service level agreements

footer left page.jpg Measuring reliability and user expectations

In addition to uptime, which was discussed earlier, other reliability metrics exist that should be considered. A common measurement of computer hardware reliability is mean time to failure (MTTF). If a component fails, the service it provides is unavailable for use until the component is repaired. However, MTTF only tells half of the story. To track the time between failure and repair, the industry created the mean time to repair (MTTR) measurement. To calculate an important metric of service reliability, we can use the equation of MTTF/MTTR. This equation shows that reducing the repair time by half will result in a doubling of the measured availability. For example, consider the situation of an online service that has historically demonstrated an MTTF of one year and an MTTR of one hour. In terms of measured availability, halving the MTTR to a half hour is equivalent to doubling the MTTF to two years.

By focusing on MTTR, you can mitigate the potential impact of failure incidents and seek to improve reliability by creating a set of standby servers with a sufficiently redundant design to hasten recovery from such incidents. You should always document these types of mitigations in a service level agreement (SLA) from the cloud provider. By documenting them you are implicitly acknowledging that some amount of failure is expected to occur, and that the best way to minimize the impact from failure is to increase the MTTF and reduce the MTTR.

The following sections detail some of the key architectural requirements of designing highly available cloud-based services.

Service-oriented architecture

Effective cloud technology adoption requires appropriate design patterns. In a service-oriented architecture, each component should have a well-designed

footer left page.jpg interface so that its implementation is independent of every other component and able to be used by new components as they are deployed. Designing architecture in this way helps reduce overall system downtime, because components that call into a failing component can properly handle such an event.

Separation of function

Separation of function, also known as separation of concerns, is a design pattern that states that each component will implement only one or a small set of closely related functions with no overlap and loose coupling to other components. The three-tier architecture shown in Figure 1 later in this paper is a classic example of separation of function. This approach allows functionality to be spread across different geographies and networks so that each function has the best chance to survive failures of specific servers. The figure depicts redundant front-end web servers, message queues, and storage, each of which could be separated geographically.

Automatic failover

If the component interfaces are registered with a uniform resource identifier (URI), failover to alternate service providers can be as simple as a DNS lookup. Using URIs instead of locations for services increases the likelihood that a functioning service can be located.

Fault tolerance

Also known as graceful degradation, fault tolerance depends on aggregating the building blocks of a service without creating unnecessary dependencies. If the user web interface is as simple as possible and decoupled from the business logic or back-end, the communications channel can survive failures of other components and maintain the organization’s link to the user. In addition, the web interface can be used to inform the user of the current status of each piece of the organization’s cloud-based service. This approach not only helps the user understand when to expect full restoration of services, but also improves user satisfaction.

footer left page.jpg Disaster planning

You should expect that services will fail from time to time. Hardware failure, software imperfections, and man-made or natural disasters can cause service failure. You should complete planning for routine problems before deployment to help troubleshooters know what to look for and how to respond. But even huge environmental disruptions, sometimes known as black swan events, will occur periodically; therefore, you need to consider such events during the planning process. The black swan theory posits that these unlikely events collectively play vastly larger roles than regular outages.

Test and measure

Two types of test and measurement of a running service are appropriate. The automated polling of the service by a test server can result in early detection and reporting of failure and thereby reduce the MTTR.

User research should be conducted either immediately before or after a deployment to understand how users react and identify unmet expectations. An easy way to obtain user feedback is to simply ask them for it, not every time you see them but occasionally. You should be able to get useful data, even with a very low response rate, and you will also obtain key performance indicators (KPIs) from users for monthly status reports.

footer left page.jpg Cloud provider

Two concepts from the 1970s have been realized by new technologies in today’s cloud offerings.

. Virtualization of computer hardware is a reality, with virtual computer images and virtual hard drives that can be remotely managed. . Fast scaling and agility are realities, with management tools that can control the power of physical and virtual hardware.

It’s important that IT professionals understand these concepts and their powerful capabilities. As stated in the “Executive summary” section, the concepts in this paper apply to both public and private clouds, each of which has a place in the toolbox of forward-looking IT departments. The focus from the start of any project should be on cloud design and management services that provide minimally disruptive service delivery to users.

Cloud provider expectation and responsibility

A natural shared responsibility exists between any organization and its chosen cloud provider. For custom applications, the cloud provider designs its service for reliability based on the use of certain features, such as failover and monitoring, by the developer. The developer must understand and use these features for reliability to be an achievable goal.

An organization that implements a solution on top of cloud-based infrastructure must ensure that the service is available as much as possible. Users expect these types of services to be as reliable as a telephone. Outages may occur, but they are rare, localized events. The organization’s ability to provide such assurance requires transparent communication with the provider about what to expect from the service and what must be supplied by the service consumer. Without such transparency, finger-pointing about responsibility can occur instead of automated recovery when service failures lead to outages for users.

footer left page.jpg The same consideration applies to private clouds. An IT organization can partition infrastructure responsibility to in-house experts who then create a private cloud. The cloud service is expected to provide a reliable platform on which the rest of the IT team can create innovative solutions to address the business needs of the organization. But just as for an outsourced cloud service, fully transparent operations and documentation of expectations will help avoid failures that result from vague or poorly defined areas of responsibility.

Cloud availability

Typically, public cloud services provide high availability by using a geographically distributed and professionally managed collection of server farms and network devices. Even very large enterprises that have private clouds for specific high-value content can profitably use public cloud services to host their application solutions. And large public clouds have effectively infinite capacity, because they can respond with more servers when demand is greater than anticipated. Offloading the excess server capacity has multiple benefits, the most prominent of which is that, in most public cloud models, excess capacity is not billed until it is used.

Many cloud providers offer built-in capabilities for increased availability and responsiveness, including:

. Round-robin DNS . Content distribution networks . Automated failover . Geographic availability zones

Design for availability

As stated earlier, the most effective way to increase availability is to shorten the MTTR. If geographic and network diversity is available from the cloud, ensure that load balancing automatically routes users away from failed components to working components. Even a relatively simple capability such as network load balancing can be affected by unexpected interaction between the organization

footer left page.jpg and the cloud provider or DNS. Such interactions have the potential to introduce instabilities in the service offering that have not been anticipated.

For example, distributed denial of service (DDoS) attacks are external attacks against availability that all cloud services need to mitigate. However, unless mitigation is carefully implemented, organizations with little security experience can unintentionally cause an application to become unavailable, which can result in as much downtime damage as a DDoS attack. DDoS mitigation is an example of a capability that is most effectively provided at scale—that is, by the cloud provider or the ISP.

Most major cloud vendors are certified for reliability and security, which they report in documents such as those contained in the Cloud Security Alliance (CSA) Security, Trust, and Assurance Registry (STAR).1 Although STAR itself is relatively new, it’s important for IT managers to consider that most in-house systems have not received such third-party vetting. Obtaining such assurance at a shared cost is another potential benefit of public cloud services.

1 Security, Trust and Assurance Registry (STAR), at https://cloudsecurityalliance.org/star/

When evaluating the benefits and challenges of creating a highly available cloud- based solution, it is important to ensure that your design includes a threat analysis of well-known problems such as those defined earlier, as well as any business- disrupting failures that are unique to the solution you want to deploy. Typically, only security attacks are considered in a threat analysis, but a well-designed cloud solution will consider other types of loss of availability and plans for mitigations as well.

The following figure shows a generic three-tier design with redundancy capability. Each request has more than one path to a component that can respond to it. Starting from the left is a user device, such as a laptop computer, from which the request is routed (again, consider the use of round-robin DNS and network load balancing features, if available). In tandem, an automated availability test service is exercising as much of the system as possible to assure that any failure is quickly reported so that necessary repairs can begin quickly.

The cloud service in the figure shows separation of function. This separation helps ensure that the network path to the user has no common components that result

footer left page.jpg in failure of both paths. Within each cloud service site, additional component redundancies are possible. In this scenario, the queue may be provided by the cloud service provider. If a common database needs to be shared between both sites, it is up to the organization’s application architecture to route traffic to the data in a way that will fail over to some other site running a mirrored copy of the database; however, many public cloud offerings have built-in data redundancy capabilities that should also be explored.

In this example solution, load balancing is split between the Internet at the front end, the cloud service in the middle tier, and the organization’s application at the back-end. Tests of disabling each of these components should be undertaken with live loads to assure that fail-over options work as planned.

Figure 1. Designing for availability


If the website front-end component is sufficiently simple and straightforward, users should always be able to see the enterprise brand image and status information, which will help them have confidence in the reliability of the enterprise itself. Simplicity in both components and connections is the key to the reliability and availability of the system as a whole. Complex and tightly interconnected systems are difficult to maintain and debug when something fails.

footer left page.jpg Organizational customer of the cloud

An organization that acquires cloud services from either private or public cloud providers needs to fully understand the responsibilities of the cloud provider as well as the limitations of those responsibilities. Similarly, the cloud provider must understand the availability and security requirements of the solution that it provides to users. A complete cloud solution requires a thoroughly reliable implementation and an ability by the cloud service provider to create a service that integrates its own capabilities with the organization’s requirements. The good news is that this integration is where the most innovation and value-add for the organization is generated.

The organization’s responsibility

When the responsibilities of the cloud provider are specified, well understood, and documented in a service level agreement, any unmitigated threats become the responsibility of the customer—the organization. A best practice for identifying potential unmitigated threats is to conduct a brainstorming session to identify all possible threats and then filter out those that are known to be the responsibility of the cloud provider. Threats that remain are the organization’s responsibility to mitigate. The following list of risks and responsibilities can be used as a guide for types of threats to consider:

. Apply access control locally and in the cloud. Although data loss incidents can occur for a variety of reasons, they most commonly occur when an attacker either spoofs the identity of a valid user or elevates their own privileges to acquire access that has not been authorized. Most organizations compile a directory of employees and partners that can be federated, or have their accounts mirrored, into a cloud environment; however, other users may need to be authenticated using different methods. For future flexibility, adopt

footer left page.jpg cloud services that support federation and accept identities from on-premises directories as well as from external identity providers. The trend is for providers to include access control services as a part of their service offering. A best practice is to avoid duplicating your account database, because doing so increases the attack surface of the information it contains, such as password data. . Protect data in transit. Data loss can occur if the data is not protected in storage or in transit. Protecting data in transit can be accomplished by using Transport Layer Security (TLS) to provide encryption between endpoints. Protecting data in storage is more of a challenge. Encryption can be provided in the cloud, but if the data is to be decrypted by apps that also run in the cloud, the encryption key needs special protections. It’s important to note that providing the cloud with access to the encryption keys as well as to the encrypted data is equivalent to storing the data unencrypted. . Protect trusted roles. Authorization to perform administrative functions or to access high-value data will likely be based on users’ roles within their organizations. Because roles will vary for each user while their identity remains constant, some mapping must exist between each user ID and a list of the ID’s authorized roles. If the cloud provider is trusted to control access, this list must be made available to the cloud and managed accordingly. A best practice is to use claims-based authorization technologies such as Security Assertion Markup Language (SAML). . Protect data on mobile devices. Protection of user credentials and other sensitive data on mobile devices is only feasible if security policy can be enforced. A best practice is to configure Microsoft Exchange ActiveSync mailbox policies. Although not all devices implement all of the ActiveSync policies, the market is responding to this need and organizations should seek to deploy and enforce a endpoint security solutions on all mobile devices. . Develop all code in accordance with SDL. Application code is likely to come from a combination of the cloud provider (for example, in the form of sample code), the cloud tenant organization, and third parties. A threat modeling process such as the one used as part of the Security Development Lifecycle (SDL), the software development security assurance process created by Microsoft, needs to consider this factor. One area in particular that needs to

footer left page.jpg be analyzed is the potential for conflict if more than one component controls related functionality, such as authorization. . Optimize for low MTTR. The threat modeling process also needs to consider and specify different types of expected failures to help ensure low MTTR. For each potential failure, specify the tools and technologies that are available for recovering functionality quickly.

Availability of sensitive information stored in the cloud

The cloud offers some interesting options for securing data within a highly available architecture. Consider the following example cloud solution, in which the functionality for both security and availability is split between the organization and the cloud. Sensitive organizational information is stored in the cloud, but the decryption keys are maintained within the organization so that no attack on the cloud can reveal the sensitive information. One option is to encrypt all data that is stored in the cloud to prevent data leakage. However, it is also possible to differentiate between types of data so that high-value data is protected by encryption and low-value data is protected only by access control. The design principles of separation of function and geographical distribution that were suggested earlier are used here to increase resiliency.

The following figure illustrates how the data protection scenario works. Data is entered and retrieved at a workstation that is attached to an organization’s network. The network uses a firewall to protect it from intrusions. The workstation connects to a service in the network that uses a key to encrypt and decrypt data. The key is obtained from the organization’s central directory, so all distinct local protected networks can access the data that is stored in the cloud.

The user is authenticated by the organization’s directory. Federation and SAML are used to provide centralized control of authentication and authorization, which takes advantage of the available existing account repository (such as Active Directory) in a distributed environment.

footer left page.jpg Figure 2. Data encrypted in the cloud


This example of encrypted data in the cloud can be used as a pattern for a variety of implementations. The protection of the data decryption key removes the threat of data leaks in the cloud and puts control of the plaintext data under the organization’s full control. The distributed architecture helps to ensure the availability of the service.

footer left page.jpg The user and the device used to access the cloud

Users will measure the availability of a cloud service solely in terms of their ability to complete their current task, which means that the cloud service as well as the device that they use to access the cloud must be functional.

User expectation and feedback

Users measure service availability based on their success at achieving their objectives. The following figure shows the typical steps in the process of a user obtaining access to a cloud resource. First, the user’s device must connect to the local network and be authenticated. Next, the device’s security disposition, or health, is checked and some sort of role-based authorization process is used to establish appropriate access for the user. Finally, the cloud resource itself must be available. The failure of any of these components will block the user’s ability to complete their task. Sometimes the blockage is desired for security purposes, but the user will always perceive it to be an impediment.

Figure 3. Availability blockers


When any one of the links shown in the figure fails, it is important to let the user know the nature of the problem and also what needs to be done to restore availability of the solution. Whenever user action is required, instructions need to be clear and concise.

footer left page.jpg Design for test

An automated test program is helpful for detecting solution failures. A best practice is to design the solution for online testing. All customer-facing services and webpages need to enable automated query programs that use near real-time reporting with automated escalation when significant failures occur. Online testing can provide valuable performance indicators of the availability of the solution services.

Some method of communicating users’ perception of availability should be implemented as well. For example:

. If an application provides users with access to the cloud, use it to generate statistics, such as time from login to acquisition of cloud data. . Periodically ask users when their session ends if they would take a short survey. . Send user experience researchers into the field to get user feedback.

User device availability

Devices that are used to access cloud solutions must be trusted not to leak high- value information. Because mobile devices are increasingly being used to access such information, some way to evaluate device security, or health, is required. A good cloud design is able to evaluate device health and verify user identity. This section describes how to provision device health assessment in such a way that the cloud solution can be available to users from anywhere.

This example solution addresses the need to establish secure access to an organization’s network from a user-owned device. This type of scenario is often referred to as bring your own device to work, or BYOD. For many years, IT departments were able to protect enterprise assets by quarantining all resources, including the client computers that accessed those resources, inside a protected perimeter. In BYOD scenarios users have commercially available devices that can access all of their personal data from anywhere, and they want to use those same devices to access the organization’s resources as well. This phenomenon is known as the consumerization of IT.

footer left page.jpg In such a scenario, the cloud service needs to establish the user’s identity, learn their preferences about how their personal information can be used, and obtain the user’s permission if the service (or the organization) wants to store the user’s personal information for future use or share it with others. In addition, the cloud service may have content that should only be released to user devices that are determined to be secure. Many users want to know that their privacy, identity, and assets are protected from malware, although most users are unwilling to be inconvenienced by security mechanisms.

The following figure shows a solution built to assess mobile device health from the cloud. The mobile device authenticates the user through a connection to an identity provider in the cloud. If the web service has highly confidential information, or is trying to obtain a provable indication of the user’s intent, it may elect to verify the security of the mobile device before proceeding. The user’s device will then receive a health attestation that can be sent with the user ID.

Figure 4. Secure mobile clients


Windows 8 devices can be protected from low-level rootkits and bootkits by using low-level hardware technologies such as secure boot and trusted boot.

footer left page.jpg Secure boot is a firmware validation process that helps prevent rootkit attacks; it is part of the Unified Extensible Firmware Interface (UEFI) specification. The intent of UEFI is to define a standard way for the operating system to communicate with modern hardware, which can perform faster, more efficient input/output (I/O) functions than older, software interrupt-driven BIOS systems.

Trusted boot creates a condition in which malware—even if it is able to tamper with the boot process, which is unlikely—can be detected, which prevents a health attestation from being granted. Secure boot also protects the antimalware software itself.

A Remote Attestation Service (RAS) agent can communicate measured boot data that is protected by a Trusted Platform Module (TPM). After the device successfully boots, boot process measurement (for example, measured boot in Windows 8) data is sent to a RAS agent that compares the measurements and conveys the health state of the device—a positive, negative or unknown state—by sending a health claim back to the device.

If the device is healthy, it passes that information to the web service so the organization’s access control policy can be invoked to grant access.

Depending on the requirements of the content provider, device health data can be combined with user identity information in the form of Security Assertion Markup Language (SAML) or open standard for authorization (OAuth) claims. The identity provider, for example Active Directory, may belong to the user’s employer, to the content provider, or to a social network such as Facebook. The data is evaluated by fraud detection services that are already in use at most commercial websites. Access to content is then authorized to the appropriate level of trust for what the health assertions, or claims, merit. These claims protocols are structured to allow additional requests from the content provider to the user’s device as needed by the user’s transaction requests of the provider. For example, if high-value data or funds transfers are requested, additional security state may need to be established by querying the user’s device before the transaction can be completed.


footer left page.jpg Conclusions

The preceding examples illustrate solutions that emphasize a secure, service- oriented architecture with separation of functions. The demonstrated architectural patterns divide the solution into components with loose coupling. This approach allows each component to fail over gracefully, even if other components fail catastrophically. The service as a whole may continue with some or all functionality no matter which individual component fails. The design can use hybrid solutions that include some on-premises functionality while providing other functionality, such as solution scaling, through an off-premises public cloud.

As a best practice, availability needs to be monitored by a service that operates in the same realm as the user. In addition, services should be designed and located in a way that makes them accessible and operable from geographically diverse locations to provide availability when calamities and natural disasters occur.

Cloud service developers and cloud service customers alike need to communicate and cooperate to anticipate, design, and test for failures at every point. Such communication and cooperation will have a direct impact on the success of the solution and the satisfaction of its users.

footer left page.jpg Additional reading

For more information about the scenarios and solutions detailed in this paper, see the following resources. These documents provide additional information to help you make the right design decisions for the availability of your cloud-based solutions.

. The Windows Azure Application Model https://www.windowsazure.com/en– us/develop/nodejs/fundamentals/application-model/ . Microsoft System Center http://microsoft.com/systemcenter (this website is now focused on Release Candidate 2012) . Cloud Computing: Achieving Control in the Hybrid Cloud http://technet.microsoft.com/en-us/magazine/hh389788.aspx . Cloud Security Alliance – Security, Trust & Assurance Registry (STAR) https://cloudsecurityalliance.org/star/ . Security Guidelines for SQL Azure http://social.technet.microsoft.com/wiki/contents/articles/1069.security– guidelines-for-sql-azure.aspx . Service-Oriented Architecture – Design Patterns www.soapatterns.org/masterlist_c.php . Cloud Insecurity: Not Enough Tools, Experience or Transparency www.technewsworld.com/story/74890.html . How the Cloud Looks from the Top: Achieving Competitive Advantage In the Age of Cloud Computing (PDF) http://download.microsoft.com/download/1/4/4/1442E796-00D2-4740-AC2D– 782D47EA3808/16700%20HBR%20Microsoft%20Report%20LONG%20webview.pdf


footer left page.jpg


One Microsoft Way

Redmond, WA 98052-6399

microsoft.com/twcnext

Office 365 Enterprise Preview

Office 365 Enterprise Preview

The efficiency you want, the controls you need

Create professional content more easily than ever, securely connect with customers and partners, and take advantage of powerful tools for more effective management, control and compliance with enterprise-grade security, data loss prevention, and rights management.
.

Top 10 reasons to try Office 365 Enterprise Preview

.

1. Have Office when you need it

When you’re away from your PC, stream a full-featured version of Office on any Internet-connected PC (Windows 7 or later required) with Office on Demand.

2. Work together with Site Mailboxes

Store documents from your PC and project-related email in a Site Mailbox so that your team can access the content no matter where you are. The Site Mailbox syncs with SharePoint, ensuring content is up-to-date.

3. Protect sensitive data

Keep your organization safe with data loss prevention (DLP) capabilities that prevent users from mistakenly sending sensitive information to unauthorized people. The DLP features in Exchange identify, monitor, and protect sensitive data through deep content analysis and provide built-in and extensible DLP policies that are based on regulatory standards such as PII, HIPAA, and PCI.
.
Data Loss Prevention capabilities.

4. Stay compliant with archiving

The ability to retain and discover data across your organization is essential to ensuring internal and regulatory compliance. Compliance officers can use the new eDiscovery Center to identify, hold, and analyze your organization’s data from Exchange, SharePoint, and Lync. The data always remains in place so you don’t need to manage a separate data store.

5. Keep people connected

You can follow documents, sites, and people to track what others are working on. SharePoint even recommends people or documents to follow. With ratings and reputation tools, you can acknowledge co-workers and inspire them to work better.

Stay connected with SharePoint.

6. Gain business insights

Combine large volumes of data from various sources with PowerPivot in Excel and explore data, visualize, and tell a compelling story with Power View. Make better decisions with teammates by sharing Business Intelligence-enriched reports and dashboards on SharePoint.

7. Work across time zones and geographies

Discuss and meet, coauthor documents, find experts, and chat in real-time with improved capabilities that keep everyone connected no matter where they are. Detailed contact cards and presence are integrated across all Office applications, making it easier than ever to connect.

8. Collaborate more securely

New capabilities and data governance/protection policy features in SharePoint let you work confidently with partners and customers. Use Lync to connect with others, while getting the authentication, encryption, and media controls your enterprise needs.

9. Get more out of your meetings

The new Lync Meeting tools let you interact with people through video, audio, and instant messaging, and to share content while meeting. Join a Lync Meeting from an HTML5-based browser using the Lync Web App, and enjoy HD video, voice over IP, instant messaging, and sharing of desktops, applications, and PowerPoint presentations.

Lync Meeting.

10. Manage and control your business more easily

Office 365 continues to improve the ease of management from a web-based portal, provides powerful scripting access via PowerShell, and continues to invest in the infrastructure with data backup, disaster recovery, and globally redundant data centers. In addition, the new service health dashboard provides customizable reports that help you get insights into your service.

Windows 8 and Windows RT Product guide

Windows 8 and

Windows RT


windows.microsoft.com


Product guide


© 2012 Microsoft Corporation. All rights reserved.


Contents


Meet Windows 8 and Windows RT 04


The Start screen is all you 06

Your password in a picture 07

Ready to roll: The apps you need 08

The Windows Store 11

Your Windows, wherever you go 11


In touch and up to date 12


Connect your stuff and your people 14

Work and play on the go 14

Internet Explorer 10: A more beautiful web 15


Natural and intuitive 16


Discover fast and fun ways to get around 21

Search, share, change settings, and more 24

Apps work together 26

Snapping apps 27

Keyboard shortcuts 28


Your PC, your apps, your choice 30


Truly innovative hardware 32

Windows Store: All the apps you want 34

Family Safety 40

Xbox 360 and Windows 8 and Windows RT 40


Reimagined, but familiar 42


A new take on Task Manager 44

More secure 44

File Explorer revamped 44

Restore and reset your PC 45

Multi-monitor support 45


Windows 8: Powerful for work and play 46


Windows and devices 48

Windows 8 Pro: Ready for business 48

Access and protect your data 48


Windows RT: Fast and connected for your life on the go 50


Do more with apps 52

Get one to go 52

Get more done 52

Stay more secure 52

Have it both ways 52


Windows 8 and Windows RT are here 54


Meet Windows 8

and Windows RT


Windows is beautiful, fast, and fluid, bringing together your sites, people, apps, and more—


so everything you care about is right on your Start screen. Windows 8 and Windows RT

provide the platform for great hardware innovation, inspiring a new generation of tablets,


laptops, and all-in-one PCs that take advantage of touch, mouse, and keyboard—all working


together on top of the fastest and most stable foundation to date.


Use Windows to work and play with ease. Sleek and lightweight, with a focus on beautiful

design and innovative materials, Windows-based PCs have reached new heights in

performance and battery life. Entertainment and apps of every kind take center stage. Tap

into your creative side, lose yourself in a game with friends, discover and download video

and songs, and play them on your TV.


The Windows Store is your place for getting apps for Windows 8 and Windows RT. Discover

a variety of great apps, check out the featured apps, or tap or click a category name to

browse all of the apps in the category.


Windows is connected. Built-in mobile broadband features support 3G and 4G. As you


move, your PC automatically finds and uses available Wi Fi hotspots. You can be effortlessly


connected, ready to work, and able to stay in touch from virtually anywhere.


04 windows.microsoft.com windows.microsoft.com 05


All about you


The Start screen is all about you. Vibrant and beautiful, the Start screen is the first thing


you’ll see. Each tile on the Start screen is connected to a person, app, website, playlist, and

everything else that’s important to you. This isn’t the usual wall of static icons. Instead, you


see: status updates, weather forecasts, Tweets, and more—you see live updates before you


ever open a single app. Pin as many tiles to Start as you want, and then group, arrange, and

name them so it’s just the way you want it.


Your password in a picture


Forget having to remember a bunch of letters and numbers to sign in to your PC. Now you

can use a picture for your password. You choose the picture and the way you want to you


draw on it, so the possibilities are infinite—draw a circle around your favorite landscape,

trace a pattern over your dog’s face—it’s easy. You can either draw a picture password

directly on a touchscreen with your finger, or you can use a mouse to draw your shapes.


Switch to password

Locked

Justin Harrison

Justin_Harrison@contoso.com

windows.microsoft.com


windows.microsoft.com


Ready to roll: The apps you need


Windows 8 and Windows RT come with apps for both the basics and a lot more. Apps like

People, Mail, Photos, and Messaging power you through essential tasks and work together

to make everything easier.


People


See the latest info and start conversations

with contacts from your email accounts,

Facebook, LinkedIn, Messenger, Twitter,

and more.


Photos


See your photos and videos in one place,

whether they’re on Facebook, Flickr,

SkyDrive, or another PC.


Messaging


Send messages to a unified list of your


Facebook and Messenger friends and

choose from hundreds of emoticons.


Music


Browse your music collection, create and

edit playlists, and keep up with the hottest

new releases. See artist details with pictures,

bios, and album lists. Sign up for Xbox Music

Pass and get unlimited listening for millions

of songs.


windows.microsoft.com


Maps


View an interactive map with the Bing Maps

app, and get turn-by-turn driving directions.


Find traffic details, road conditions, street


maps, Multimap, satellite photos, and

aerial maps.


SkyDrive


Seamlessly access and work on your files


from your Windows apps, as well as from

your other devices.


Mail


Get email from your accounts—including

Outlook.com, Gmail, and Yahoo!—all in


one place.


Video


Browse and watch movies and shows.

Watch on your PC or play to your TV.1


Weather


See a beautiful preview of current weather

conditions when using the Weather app.


You’ll find the latest conditions and hourly,


daily, and 10-day forecasts.


1 To use Play To, you’ll need a TV that’s certified to be compatible with Windows 8, Windows 7, or DNLA.

Some features aren’t available on Windows 7 and DNLA-certified TVs.


windows.microsoft.com


Games


Discover the hottest new games and

download them to your PC. Depending on

where you live and travel, you can edit your

avatar, see what your friends are up to, and

share your achievements with them.


News

Stay informed. The beautiful, photo-rich

News app, powered by Bing, makes it

easy for you to stay up to date on what’s

happening in the world.


Calendar


Keep track of your schedule in month,


week, or two-day view. Get notified about


appointments at the right time so you’re

always on time.


Finance


Use this app to check key market indices and

stay on top of fast-changing market conditions

right from the Start screen.


Travel

Travel


Explore over 2,000 destinations all over the world through beautiful

photos. The Travel app powered by Bing makes it possible: travel

guides, booking tools, real-time currency conversion, and weather

info provide everything you need to turn your next trip into an

inspired adventure.


The Windows Store


Windows 8 and Windows RT include the Windows Store, where you can discover a new

world of apps for your PC. Just tap or click the Store tile and start exploring. Filter apps

by price, rating, and more. Many apps are free, and others let you try before you buy. So


explore and load up on apps—the more you have, the more you can do.


Your Windows, wherever you go


Sign in with your Microsoft account to any of your PCs running Windows 8 or Windows RT

and immediately see everything that makes it yours: your background, your display, your

settings. And when you get a new Windows-based PC, sign in with your Microsoft account

and watch the People app come to life with info from your social networks. Windows: your


stuff no matter where you are.


windows.microsoft.com


windows.microsoft.com


In touch and

up to date


Windows keeps you in touch. When you sign in, all the latest status updates and info you

care about right on your Start screen tiles: the photo you were just tagged in, today’s


weather, news headlines, and messages from your friends—everything you need to stay up


to date at a glance.


12 windows.microsoft.com windows.microsoft.com 13


Connect your stuff and your people


It’s easy to share between your Windows apps and the services that connect them. You can


quickly send pictures or files right from an app. If you want to send a link to a site or share


an app you love, you can do that right from your browser or the Windows Store. Instantly.

No more having to interrupt what you’re doing to copy what you want to share into an email

message. Just swipe in from the right and tap Share (or point to the upper-right corner with

a mouse, and then click Share).


Work and play on the go


Start a project on one PC and finish it on another. Collaborate freely and always have the

latest version of your files. You—and the people you work with—can use free Office Web


Apps to edit shared documents on SkyDrive and immediately see each other’s changes. You


don’t even need to have Office installed. Share the files you choose with the people you


choose, and make the rest private.


windows.microsoft.com


Internet Explorer 10: A more beautiful web


Internet Explorer 10 is the entirely new browser built to take advantage of the full power of

Windows 8 and Windows RT.


Fast and fluid


Internet Explorer starts and loads sites almost instantly. It brings a fluid responsiveness to


the web that feels totally new. Everything you want to do on the web is a swipe, tap, or

click away.


Perfect for touch


Internet Explorer 10 provides a touch-first and truly full-screen browsing experience.


Navigation controls appear only when you need them and quietly get out of the way when


you don’t. You can flip ahead or back through your websites with the flick of a finger. Tiles


and tabs for frequently visited sites are oversized for easy tapping.


Easy to use


Smooth, intuitive controls work just as you’d expect. One box is both the address and

search bar for speedier navigation. Pin your favorite sites to your Start screen and get to

them as quickly as you can open your apps.


Safer and more private


The industry-leading SmartScreen technology helps keep your PC and your info safer on

the web and helps protect against malware. Privacy tools like Do Not Track are built in and

easily turned on in just one tap or click, so you have more control.


windows.microsoft.com


Natural

and


Windows 8 and Windows RT are perfect for PCs with touchscreens, those that have a mouse

and keyboard, and those with both. No matter which kind of PC you choose, you’ll discover


faster and more fluid ways to switch between apps, move things around, and move smoothly


form one place to another


intuitive


16 windows.microsoft.com windows.microsoft.com 17


Here’s what you need to know about using touch or mouse:


Swipe from the right edge for system commands


Swiping from the right side of the screen reveals the charms with

system commands.


Mouse equivalent: Place the mouse pointer in the lower-right or

upper-right corner of the screen.


Swipe in from the left to switch apps


Swiping in from the left reveals thumbnails of your open apps so

you can switch to them quickly.


Mouse equivalent: Place the mouse pointer in the upper-left and

click to cycle through apps or lower-left corner of the screen to see

the Start screen.


Swipe in and out on the left brings up previously used apps


Swiping in and back out on the left brings up the most recently

used apps and you can select an app from that list.


Mouse equivalent: Place the mouse in the upper left and slide

down the left side of the screen to see the most recently used apps.


Swipe from the bottom or top edge for app commands


App commands are revealed by swiping from the bottom or top

edge. You can swipe from the top to the bottom of the screen to

dock or close the current app.


Mouse equivalent: Right-click the app to see the apps commands.


windows.microsoft.com


Drag an app to close it


You don’t have to close apps. They won’t slow down your PC

and they’ll close on their own if you don’t use them for a while.

If you still want to close an app, drag the app to the bottom of

the screen.


Mouse equivalent: Click the top of the app and drag it to the

bottom of the screen.


Press and hold to learn


You can see details when you press and hold. In some cases,

pressing and holding opens a menu with more options.


Mouse equivalent: Point to an item to see more options.


Tap to perform an action


Tapping something causes an action, such as launching an app or

following a link.


Mouse equivalent: Click an item to perform an action.


Slide to drag


This is mostly used to pan or scroll through lists and pages, but

you can use it for other interactions, too, such as moving an

object or for drawing and writing.


Mouse equivalent: Click, hold, and drag to pan or scroll. Also,

when you use a mouse and keyboard, a scroll bar appears at the

bottom of the screen so you can scroll horizontally.


windows.microsoft.com


Pinch or stretch to zoom


Zooming provides a way to jump to the beginning, end, or a


specific location within a list. You can start zooming by pinching

or stretching two fingers on the screen.


Mouse and keyboard equivalent: Hold down the control key

on the keyboard while using the mouse wheel to expand or

shrink an item or tiles on the screen.


Rotate to turn


Rotating two or more fingers turns an object. You can turn the


whole screen 90 degrees when you rotate your device.


Mouse equivalent: Support for rotating an object depends on


whether the specific app supports it.


Discover fast and fun ways to get around


Pinch and stretch to zoom in and out. Get a global view of everything that’s on your screen,


and slide back and forth to find what you’re looking for. You can easily do all these things


with a mouse, too. Swipe in from the left to switch between recently used apps.


20 windows.microsoft.com windows.microsoft.com 21


Swipe in from the right to get back to Start and to other things you

do often, like searching, sharing, and changing your settings. Swipe

in from the bottom or top to see navigation controls for any app

you’re in.


Search, share, change settings, and more


No matter where you are in Windows 8 or Windows RT—an app, website, or your Start

screen—it’s easy to do the things you do all the time, like search, share links and photos,


connect devices, and change settings.


What you can do changes depending on where you are, so start exploring. Search, Share,

Start, Devices, and Settings are always available on the right side of your screen. With touch,

swipe in from the right edge, and then tap what you want. With a mouse, move your pointer

into the upper-right or lower-right corner, and then move it up or down.


22 windows.microsoft.com windows.microsoft.com 23


Search


Apps work together


Search for anything anywhere. You can search just the app you’re in,


Things that used to take lots of different programs to do now flow together in one simple


for example to find a message in Mail or an app in the Store, search


experience. Use the Photos app to see all your photos from Facebook and Flickr, and then


another app, or search your entire PC for an app, setting, or file.


upload them to your blog or send them to friends via email—all without ever leaving


the app. Get to the controls the same way in every app. Swipe in from the top or bottom

edge, or right click with a mouse, and the app commands pop right up. To search, swipe in

Share from the right and tap Search (or point to the upper-right corner with a mouse, and then


Share files and info with people you know or send info to another click Search) to find things within the app, on your PC, or on the web.


app, all without leaving the app you’re in. You can email photos

to your mom, update your Facebook status, or send a link to your

note-taking app.


Start


Get to your Start screen. Or if you’re already on Start, go back to the

last app you were in.


Devices


Use all of the devices that are connected to your PC, both wired and

wireless. You can print from an app, sync with your phone, or stream

your latest home movie to your TV.


Settings


Change settings for apps and your PC. You’ll find settings, help,


and info for the app you’re in, plus common PC settings, such as


network connection, volume, brightness, notifications, power,


and keyboard.


24 windows.microsoft.com windows.microsoft.com 25


The Windows keyboard speaks your language. On touch-enabled PCs, the keyboard layout


Snapping apps


automatically adjusts to the language you use on your PC. Whether you want to type and


Snap apps side by side2 so you can do two things at once. Chat with a friend while


click, or swipe and tap, you’ll be able to do it in the language of your choice.


arranging a date for coffee, or watch a video while getting some work done. It’s easy to do


two things at once with Windows 8 and Windows RT.


The touch keyboard has two modes, so you can switch between a full-sized keyboard with

large buttons, and a handy thumb keyboard that splits the keys on either side of the screen.

Each touch keyboard makes typing easier, more comfortable, and more natural whether

you’re sitting down or walking around.


2 A 1366 x768 minimum screen resolution is needed to snap apps side by side.


26 windows.microsoft.com windows.microsoft.com 27


Keyboard shortcuts

With Windows 8 and Windows RT, you can use all the keyboard shortcuts you already know,

as well as some new ones for even greater efficiency. For example, the easiest way to search

on the Start screen is to simply start typing. Not on the Start screen? Press the Windows

logo key or button and you can quickly switch between the Start screen and the app

you’re in. Here are some of the new keyboard shortcuts for Windows 8 and Windows RT.

Press this

Windows logo key + start typing

Ctrl+plus (+) or Ctrl+minus (-)

To do this

Search your PC

Zoom in or out of many items, like apps

pinned to the Start screen or in the Store

Windows logo key + O

Windows logo key + Z

Windows logo key + PgUp

Windows logo key + PgDn

Windows logo key + Shift+period (.)

Move the Start screen and apps to the

monitor on the left (apps in the desktop

won’t change monitors)

Move the Start screen and apps to the

monitor on the right (apps in the desktop

won’t change monitors)

Open commands for the app

Snap an app to the left

Lock the screen orientation (portrait

or landscape)

Ctrl+scroll wheel Zoom in or out of many items, like apps

pinned to the Start screen or in the Store Windows logo key + period (.) Snap an app to the right

Windows logo key + C Open the charms

Windows logo key + F Open the Search charm

Windows logo key +H Open the Share charm

Windows logo key +I Open the Settings charm

Windows logo key + K Open the Devices charm


28 windows.microsoft.com windows.microsoft.com 29


Your PC, your apps,

your choice


Touch-enabled HD screens and ultra-responsive performance give you the best Windows 8

and Windows RT experience, and powerful graphics.


30 windows.microsoft.com windows.microsoft.com 31


Truly innovative hardware


Windows 8 and Windows RT are available on a wide range of devices that showcase the

latest innovations. It’s an exciting time to buy a new PC because of the choices you have and

the way hardware has evolved to truly keep pace with your life. Versatile convertibles give

you the style and mobility of a tablet, but can be quickly turned into a laptop so you can use

the keyboard when you need it.


Tablets and convertibles are designed to work as hard as they play. Lightweight tablets are

blazing fast with longer battery life to go where you go, do what you do, and never slow

you down. Windows 8 is designed for faster, more secure startup. Many Windows 8 PCs will

resume and connect to your networks before you even notice.


To keep you connected while on the go, Windows has added support for mobile data


networks, so you’ll be able to find tablets and laptops with built-in support for your favorite


mobile carrier.


Windows provides support for a full range of environmental sensors that make it possible for

Windows-based PCs and apps to react to what you’re doing. You can buy a new Windowsbased

PC with these sensors built in, helping apps tell you where you are, react when you tilt

or rotate the screen, do fun and interesting things when you shake the screen, automatically

change screen brightness based on changes to lighting, and even let you touch two devices

together to share a photo or a webpage.


windows.microsoft.com


Windows 8 and Windows RT also introduce new ways to connect a new generation of

devices, such as USB 3.0, which supports up to 10 times the speed of current USB and


Bluetooth Low Energy (BLE)—a great eco-friendly innovation with much improved

power efficiency.


windows.microsoft.com


Windows Store: All the apps you want


Discover all the great apps in the Windows Store for your Windows 8 or Windows RT

PC. You can browse through games and social media apps, download your favorite

entertainment app, compare photo, music, and video apps, and get apps that other people


have already rated and reviewed. Lifestyle, shopping, travel, finance, productivity, and more.


Our categories cover all the bases.


When you click the Top free and New releases tiles, you’ll see the newest and highest-rated

apps. And if you know what you want, just start typing or use the on-screen keyboard when

you’re in the Store,3 and you’ll instantly see results for apps that match your search.


3 Requires an active Internet connection and 1024 x 768 minimum screen resolution to access the Windows Store

and to download and run apps.


34 windows.microsoft.com windows.microsoft.com 35


Check out the featured apps we’ve highlighted for you in the Spotlight section. In many


countries and regions, we regularly showcase a different set of apps that truly shine on


Windows 8 and Windows RT. We’re always on the lookout for fabulous new apps and

showcase those we think you’ll love.


Here’s a short list of great apps you might find in our Spotlight.4


Larousse


Find exceptional content in French exclusively designed for Windows 8! You get a French

language dictionary, an encyclopedia, a thesaurus, an atlas of 200 maps, chronologies,

idioms, image galleries, and learning games. Larousse is an excellent source of knowledge to

answer all of your questions, so you can learn, fact-check, and have fun!


Cut the Rope


A mysterious package has arrived, and the little monster inside has only one request…

CANDY! Help get the candy to Om Nom, the lovable star of the game, in this highly

innovative and addictive puzzle game. Combining realistic physics with simple, yet accurate


and precise touch control, Cut the Rope is an original and fun-filled game.


eBay


The eBay app for Windows 8 and Windows

RT lets you to tap into the world’s largest

marketplace anywhere you are. It’s a free

app built with eBay users in mind that will

help you get more out of your buying and

selling activity.


Condé Nast Collection


The Condé Nast Collection opens the door


to a treasure trove of artwork that defines


culture, style, and generations that you


won’t find from any other source.


4 Not all apps are available in all markets.


36 windows.microsoft.com windows.microsoft.com 37


Skyscanner


Need a cheap flight, fast? Search millions of routes on over 1,000 airlines and find the

lowest-priced flights in seconds with the free Skyscanner Windows app; save money,


save time. Skyscanner sources the best deals and then connects you to the airline or

travel agent to make your booking directly, so you always get the best deals. It’s simple,


independent, and finds the lowest fares fast.


iCookbook


Award-winning iCookbook is the first


recipe and cooking app for Windows 8 and

Windows RT! iCookbook comes loaded with

more than 2,000 hand-selected and kitchentested

recipes with an easy-to-read Prepare

feature! iCookbook includes the same

number of recipes as more than 20


full-size cookbooks.


windows.microsoft.com


windows.microsoft.com


Family Safety


Family Safety is now an integrated part of Windows 8 and Windows RT, so it’s easier than

ever to keep track of when and how your kids use your PC, and to set limits on exactly

which websites, apps, and games they’re allowed to use. Family safety monitors your kids’

activities and lets you know what they’re doing. By connecting your account, you’ll even be

able to get email reports right in your inbox.


If you’re worried about your kids downloading apps, you can use Family Safety to control


what they can download and see in the Windows Store. Set up a rating level to filter the


apps according to your preferences.


Xbox 360 and Windows 8 and Windows RT


Xbox music and video is the new way to get great entertainment on Windows 8 and Windows

RT. Enjoy the latest movies, TV shows, and music on your tablet or PC. Get access to great


games made especially for Windows—from the latest hits to your favorite classics. Plus,


use Xbox SmartGlass5 on your tablet or PC as a second screen with your Xbox 360 for an


enhanced experience. Even flick your photos, home movies, and music right from your


tablet or PC to your TV.


You can use touch, or mouse and keyboard, to browse and control what’s playing with the

app. And the app shows you detailed info about the movies, TV shows, games, and music

that you’re enjoying.


Entertainment is more amazing with Windows 8 or Windows RT and Xbox. On your PC, when

you sign in with the Microsoft account associated with your gamertag, you’ll be automatically

signed in to any Xbox LIVE app that you open in Windows 8 or Windows RT.


5 Coming end of 2012. Available content and features vary by device. Second screen control is available

with select games and Xbox LIVE content. Additional fees and requirements apply for some content.

See xbox.com/live.


windows.microsoft.com


windows.microsoft.com


Reimagined,

but familiar


Windows 8 and Windows RT are built on the rock-solid foundation of Windows 7, but

they’ve been improved on all fronts and designed to work with great new hardware

and devices. With radically updated designs, touch support, and instant resume, it’s a

new era for PCs.


42 windows.microsoft.com windows.microsoft.com 43


Strong on fundamentals


Blazing fast with incredibly fast start-up times, longer battery life, and responsiveness you


can feel in your fingers, Windows 8 PCs are humming with a new power.


More secure


Bad things can happen to good PCs. From hackers, viruses, worms, spyware, and other types


of malware, your PC has a lot to fight against. Windows 8 and Windows RT help to ensure


that you’re protected at all times.


Windows 8 and Windows RT transform the way you use your PC. They’re beautiful, fast,


and fluid, with Windows productivity when you need it. Go ahead and push the limits. The

features used most often by power users are now even more flexible and efficient.


Restore and reset your PC


Windows 8 and Windows RT come with a number of options to restore your PC. You can

even refresh your PC, which keeps all of your documents, accounts, personal settings, and

Windows Store apps, but returns Windows to its original state.


Multi-monitor support


If you want to get more things done at once, consider using multiple monitors. Read a


report on one while creating a presentation with another, or find apps in the Windows Store


while you skim the latest reviews online. And some apps, like coding and video editing apps,

are faster to work with when they’re spread across two or more monitors. Windows 8 and

Windows RT have been designed to give you new, powerful, multi-monitor options. Use the

four corners of each monitor to open the Start screen, charms, and your recent apps. Open

desktop apps on all monitors, or open apps from the Windows Store on one and desktop


apps on another. The flexibility of the new multi-monitor support will give you an edge


in productivity.


A new take on Task Manager


You can use the updated Task Manager to

quickly see which apps and services are

using resources on your PC. And if you want

to see the nitty-gritty details of what your

network connections and hardware are up

to, or control the apps that run at startup,


it’s all easy to find and control. Color-coded


tiles help you to quickly see what’s going on.


You can keep track of resources efficiently


and immediately with graphs and details on

processes, apps, and history.


File Explorer revamped


Whether you’re a person who puts all your


files into a single folder or has dozens of


folders and never throws anything away,

you can use File Explorer (previously called

Windows Explorer) to get a handle on your


files. The new ribbon in File Explorer makes


it a lot easier to do what you do most often,


such as copy and paste files, show file

extensions, and search for files based on


date, type, or other properties. We’ve even

brought back a long-lost favorite:

the Up button.


windows.microsoft.com


windows.microsoft.com


Windows 8:

Powerful for


Windows 8 has been reimagined to be all about you. Put what matters most right on your

Start screen, and get instant access to your people, apps, sites, and more, so you can spend

less time searching and more time doing. Windows 8 is smooth, intuitive, and designed to

let you do what you want, the way you want.


work and play


46 windows.microsoft.com windows.microsoft.com 47


Windows and devices


Windows 8 supports a wide range of devices, including printers, cameras, media players,

and displays. They’re designed to just work when you plug in your device. A Windows Store

device app is an app that lets you work with your hardware.


For example, you can plug in a scanner and Windows will automatically download the

associated Windows Store device app, when available. This app would allow you to preview,


scan, and configure the scanner ‘s settings. Windows 8 generally works with the same


peripheral devices and apps that work with Windows 7.


Windows 8 Pro: Ready for business


With Windows 8 Pro, you get everything in Windows 8, plus enhanced features that help


you easily connect to company networks, access files on the go, and more.


Access and protect your data


Encrypt your data with BitLocker on Windows 8 PCs to help keep your work safe and


confidential, even if your PC is lost or stolen.


Windows 8 Pro also lets you connect to your company networks using domain join.


For ultimate flexibility and data access, you can set up your work PC to allow remote


connections and access it with Remote Desktop when you’re on the go.


48 windows.microsoft.com windows.microsoft.com 49


Windows RT: Fast

and connected for

your life on the go


50 windows.microsoft.com windows.microsoft.com 51


Do more with apps


Great built-in apps like People, Mail, Photos, and Messaging work together to make things

easier and power you through essential tasks. And you can do more with a world of apps

at the Windows Store. Windows RT works exclusively with apps from the Windows Store, so

you know your software is always compatible.


Get one to go


Extraordinary battery life means you can go longer. And connected standby in Windows RT

keeps your apps in sync, even in sleep mode, so your PC turns on and is ready to go when

you are.


Get more done


Windows RT comes with Office Home & Student 2013 RT Preview6 so you can do more

right out of the box with touch-optimized, new versions of Microsoft Word, Excel, and

PowerPoint.


Stay more secure


Windows Defender, Windows Firewall, and Windows Update are always on in Windows

RT so you’re always more secure with the latest protection7. Windows RT also comes with

Device Encryption so your information is safer, too.


Have it both ways


Windows RT is built for touch so you can work, play, and customize in whole new ways, but

it also works great with mouse and keyboard so you can get to work when you need to.


6 Preview edition installed. Final Office version will be installed via Windows Update when available (free

download; ISP fees apply). Some features and programs unsupported. See http://office.com/officeRT


7 Internet access (with any fees that apply) is required to update. Windows Update and Defender can’t

be disabled.


windows.microsoft.com


windows.microsoft.com


Windows 8

and Windows RT

are here


Whether you’re working or playing, at home, in the office, or on the go, Windows 8 and


Windows RT are designed for you. You decide how you want to sign in, which PCs you want

your apps on, who else can use your PC, and the colors, pictures, and organization style that

works best for you. Get a great set of apps out of the gate, and build on it from the myriad

of apps available in the Store. Get the protection, speed, and reliability you’re used to from

Windows and then some.


With Windows, there are endless possibilities.


54 windows.microsoft.com windows.microsoft.com 55